Persistent memory MCP server. 25 tools, BM25+MMR+OOD retrieval, CFR-21 audit, knowledge graph.
Quick Install
Automated & IDE SetupCopy the AI prompt to install this server into Claude Code, Cursor, or another agent — or use 1-click editor setup below.
Not yet automatically verified
We haven't yet run this listing's install command through our automated sandbox check. This isn't a red flag — we're steadily working through the catalog.
Manual Client & Custom JSON ConfigExpand JSON ▾
Client Config & Setup
Choose your client or environment
Target File:
💡 Paste the JSON block into your client's configuration file under mcpServers, then restart the application.
Documentation Overview
MemoryIndustry
Formerly cuba-memorys. Same daemon, same cuba_* MCP tools, new product name.




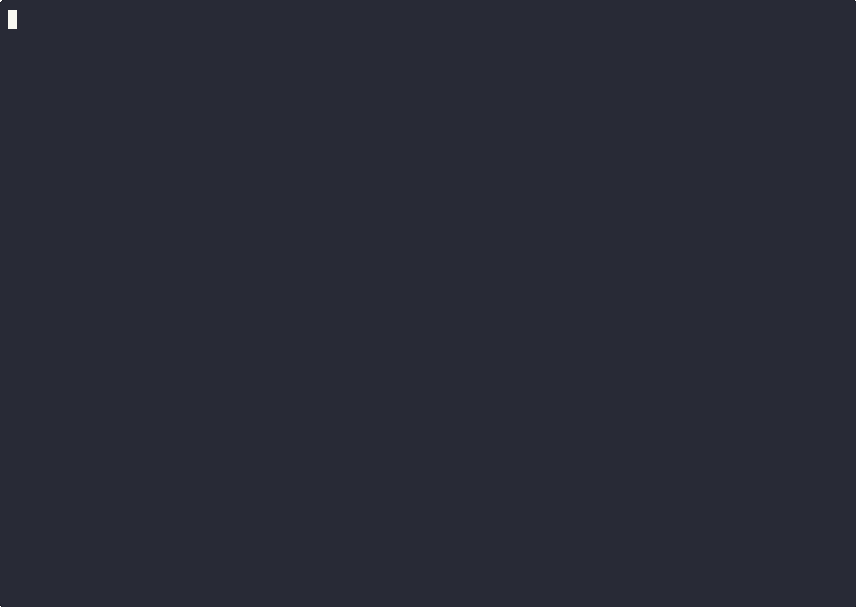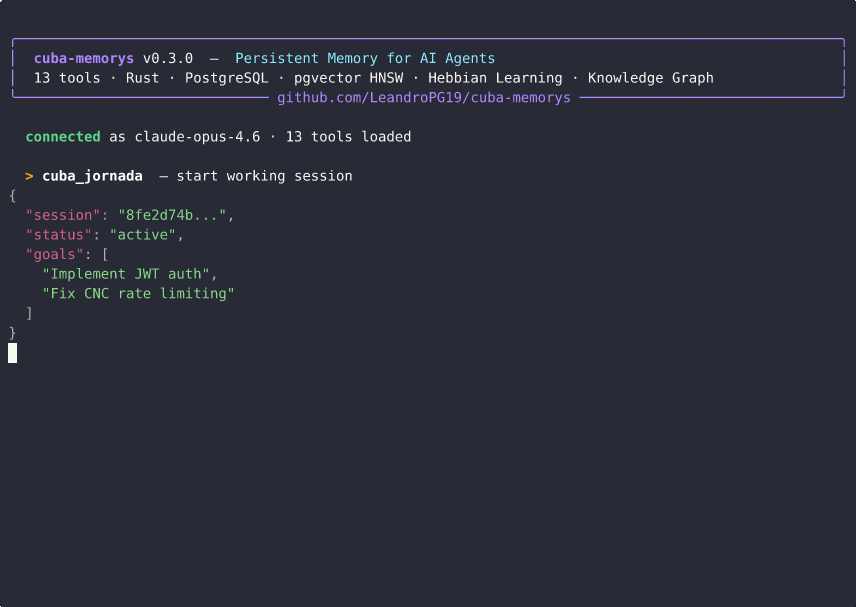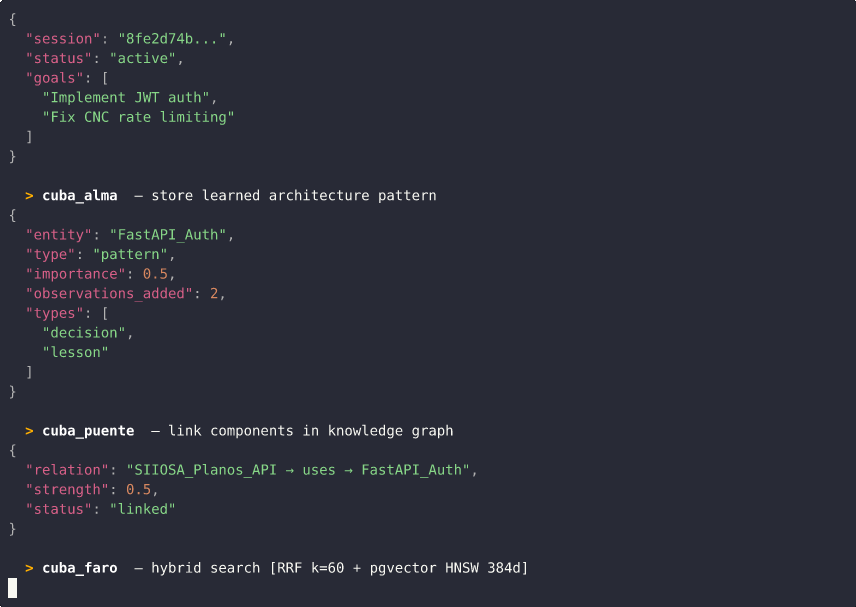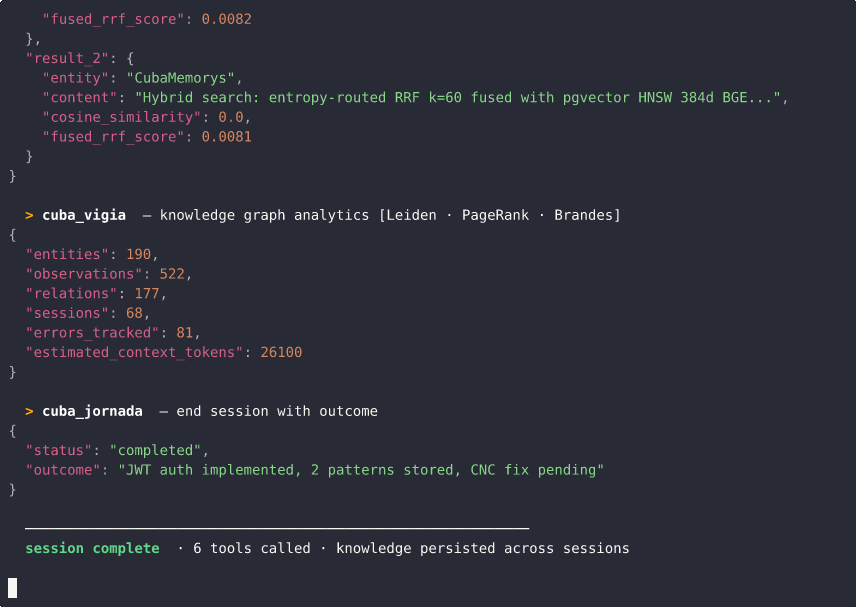
Long-term memory for AI coding agents. An MCP server that gives your agent a knowledge graph it can search, reason over, and be corrected by — so it stops forgetting your codebase between sessions.
Written in Rust. Backed by PostgreSQL + pgvector. 31 MCP tools (32 with CUBA_DOCS=1), 25 CLI commands, and every number below measured on a benchmark that — as of v0.12 — actually measures what it claims to. (The previous one did not. See Measured.)
Install
That is the whole setup. On first run it provisions a PostgreSQL 18 + pgvector container via Docker and initializes the schema. Docker must be running. The cuba-memorys command remains a binary alias.
Cursor / Windsurf / VS Code / Zed
No DATABASE_URL needed. Or run cuba-memorys setup (or memory-industry setup) and it writes the config for every client it finds — then cuba-memorys setup check audits them for disagreement, which is the failure that actually bites (two configs, two embedding dimensions, one silently broken search).
Bring your own PostgreSQL
Needs the vector and pg_trgm extensions. cuba-memorys doctor will tell you if anything is missing.
One shared daemon instead of one process per client
stdio gives every client its own process, and every process loads its own copy of the models — embeddings, reranker and NLI together are several GB. Three editor windows meant three copies, and on a 16 GB laptop that is the whole machine.
serve loads them once and answers every client over loopback HTTP, which is also the shape the 2026-07-28 MCP specification settled on: no session handshake, every request self-describing.
memory-industry serve is the same command. Point every client at it, and give each one its own Mcp-Client-Id so their sessions stay separate — without it jornada start in one window becomes the active session of the next:
GET /health reports uptime, database reachability and how many clients have been seen. status is three-valued — ok, starting, degraded — and the code is always 200: a 503 would take out of rotation a daemon that still serves lexical search and still serves the one endpoint that can explain what is wrong. Alert on status, not on the code.
With CUBA_HTTP_TOKEN in an Authorization: Bearer header the answer also carries runtime: mode, resource_tier, {state, device, reason} for the embedder, reranker and NLI, gpu{build, degraded, placement} and llm{configured, backend, model, base_url} — which is how you find out where the reranker is actually running without reading the source. Without the token none of that is served, and neither is graph_db.last_error, which can name an internal host and port. No key, no DATABASE_URL and no model path is ever printed, with or without a token.
The token is mandatory if you bind anything other than loopback — the daemon serves the entire graph with no authentication by default — and on a routable address it must be at least 32 characters.
The port opens first, then the models load, and only then does the daemon announce itself and start serving. Binding first keeps the cheap diagnosis — a second daemon on the same port fails immediately instead of spending two minutes loading before it finds out — and connections that arrive during the load queue in the kernel backlog, so a client waits and gets a real answer rather than a refused connection. If the load overruns MEMORY_INDUSTRY_WARM_BEFORE_SERVE_SECS (180 s) the daemon serves anyway, /health says starting, and every search asking for reranking comes back marked degraded. Under stdio a client that gives up at 30 s without closing stdin used to leave an abandoned multi-GB process holding every model it had loaded; stdio now exits if no handshake arrives within CUBA_HANDSHAKE_TIMEOUT_SECS (60 s, 0 disables).
That queue only helps a client that can outwait the load: one whose own budget is shorter — a sync peer gives up after CUBA_HANDLER_TIMEOUT_SECS (30 s) — still cuts the call, and cuts it seeing a timeout instead of a refused connection, which is the better diagnosis but is not the real answer the queue was there to buy. /health is what says which of the two states the daemon is in, and it answers two different questions. That it answers at all means the port is served, which is everything a caller needs when what it is about to call does not touch the models — a sync fetch moves rows. That it answers ready: true means the models finished loading as well, which is what to wait for before a search that asks for reranking, or when the first search must not be the one that pays for the load. The first wait is bounded and the second is not: the daemon opens within MEMORY_INDUSTRY_WARM_BEFORE_SERVE_SECS whatever the models are doing, but a warm-up that overruns that ceiling keeps serving everything with ready: false for as long as it takes, so ready: true can fail to arrive on a daemon that is answering perfectly. Wait on it without a ceiling of your own and you hang on a healthy machine.
Semantic embeddings & models (recommended)
Without a model, embeddings are hash-based: deterministic, and semantically meaningless. Search still works through the lexical and BM25 branches, but nothing understands meaning.
One command installs the models and the ONNX runtime, on any OS — no shell scripts, no manual ORT_DYLIB_PATH:
Everything lands in ~/.cache/cuba-memorys/ and is found automatically. models downloads only when you run it — nothing is fetched behind your back.
bge-m3 (1024-d) is better than e5-small for Spanish, though the size of the gap is no longer claimed (the old +21 nDCG figure came from a broken benchmark). It needs a dimension migration (scripts/migrate-embedding-dim.sh 1024) and CUBA_EMBED_MODEL=bge-m3 CUBA_POOLING=cls.
Modes: local · red · completo
CUBA_MODE is a preset that sets the database, the models, and outbound network together, so you pick one name instead of lining up a dozen env vars:
CUBA_MODE | Database | Capabilities | Network out |
|---|---|---|---|
local (default) | Docker on this machine | embeddings + NLI as installed | none |
red | shared managed Postgres (set DATABASE_URL with sslmode=require) | + provenance per node, real-time sync between machines | none |
completo | whatever DATABASE_URL implies | + reranker (GPU if present) + cuba_docs | cuba_docs |
Two machines, one memory. Point both at the same managed Postgres (Neon or Supabase free tier both have pgvector and fit the 36 MB corpus many times over), give each a name with CUBA_NODE_NAME, and CUBA_MODE=red. What one writes, the other reads; every memory records which machine it came from (origin_node). Without a shared database, cuba_sync does the same job through a git repository — see Sync between machines. Do not expose your own Postgres port to the internet — use a managed provider's TLS, or a private network like Tailscale.
Related MCP Servers
Adoption & maintenance
Factual signals from GitHub, npm, and our automated checks — not a rating.
GitHub stars
29
Stargazers on the source repository.
npm downloads
1.6k
Package downloads in the last 30 days.
Last commit
1mo ago
Most recent push to the default branch.
Directory activity
2 views
Config copies, upvotes, and views on AllMCPs.
Reviews
No reviews yet — be the first to share how this listing worked for you.
Frequently Asked Questions about Cuba Memorys
AllMCPs Directory Badge
Showcase your server listing on GitHub or your project documentation. Embed this dynamic SVG badge to highlight official listing status and live engagement.
Badge Style:
Live Dynamic SVG Preview
Markdown (GitHub README)
[](https://allmcps.com/mcp/cuba-memorys)HTML Embed
<a href="https://allmcps.com/mcp/cuba-memorys"><img src="https://allmcps.com/api/badge/cuba-memorys?style=directory" alt="Cuba Memorys on AllMCPs" /></a>Technical Specs & Signals
CategoryKnowledge & Memory
4/5 checks healthy over the last 46d
45Quality signal: Fair · 45/100How this signal is calculated ▾
Server availabilityNot measured
Not scored for repo-hosted servers — we can't reach the running server, only its GitHub page. Hosted MCP endpoints are health-checked live.
Verified ownership10/20
Documentation & tools16/30
Adoption & activity8/15
Community engagement0/10
A guidance signal from public completeness & health data — not a user rating. New listings start lower and rise as they add docs, get verified, and grow adoption. Signals we can't observe for a listing are skipped, not counted against it.
Supply-chain signal
No high-severity advisories surfaced by our automated scan.
Critical 0High 0Medium 0Low 0
Scanned 2d ago via OSV.dev · memory-industry (PyPI)
Own this project?
This directory is pre-filled from public sources. Claim via GitHub README, site badge, or DNS TXT to unlock edit access and the Official badge — proof is checked automatically, then reviewed by our team.
Free dofollow backlink: add your website and place the AllMCPs badge on it — no claim needed. We detect it automatically and keep it verified as long as the badge stays live.
Claim & get free dofollowShare & Embed
Add our SVG badge (dark/light directory styles) or embeddable widget to your site.