 Treering
English | 한국어
Treering draws a map of your codebase and keeps a copy of it for every commit, so you can see how the structure changed: which types started depending on each other last week, or when a class began to collect callers. It runs entirely on your machine and sends nothing over the network. It doesn't use an LLM, so the same code always produces the same graph.
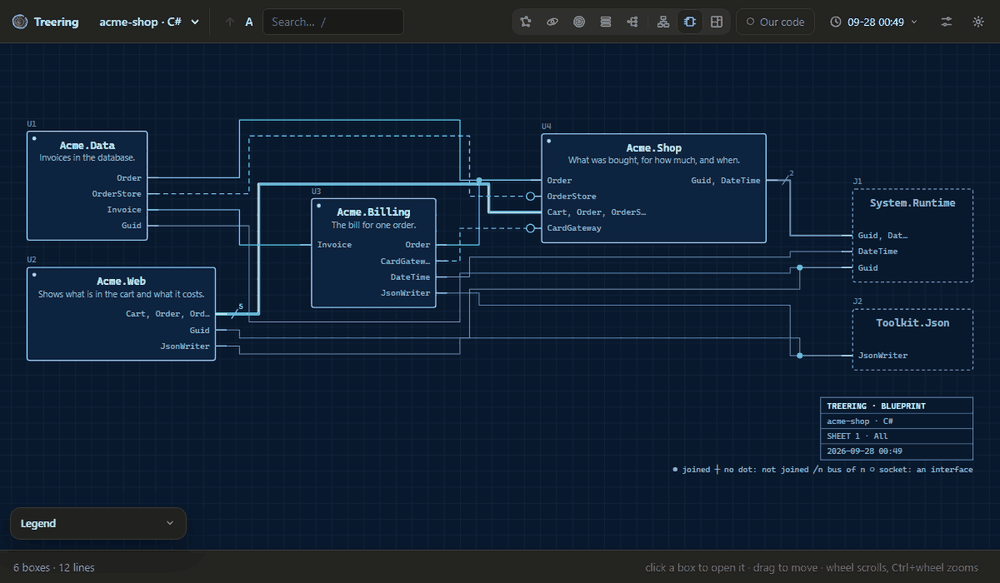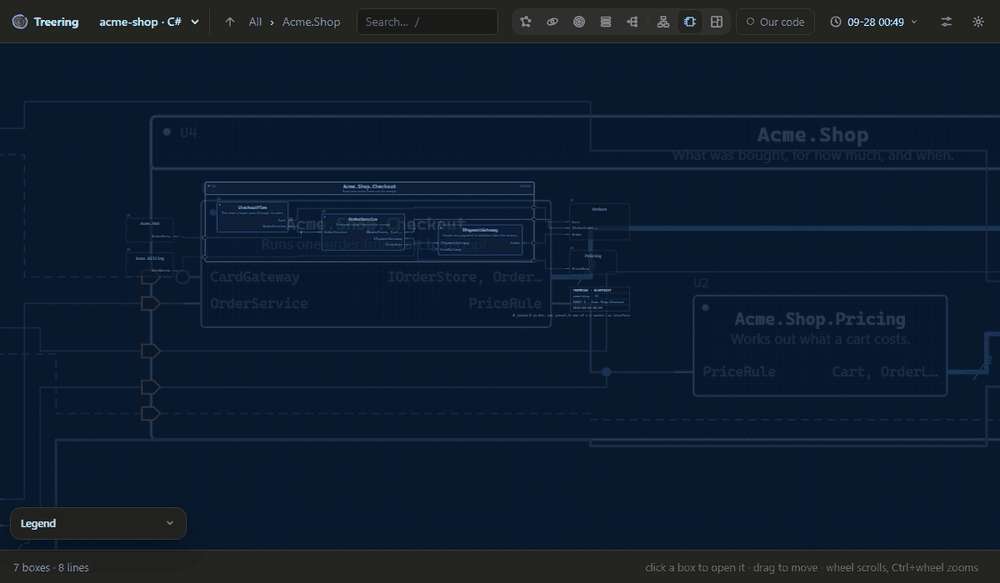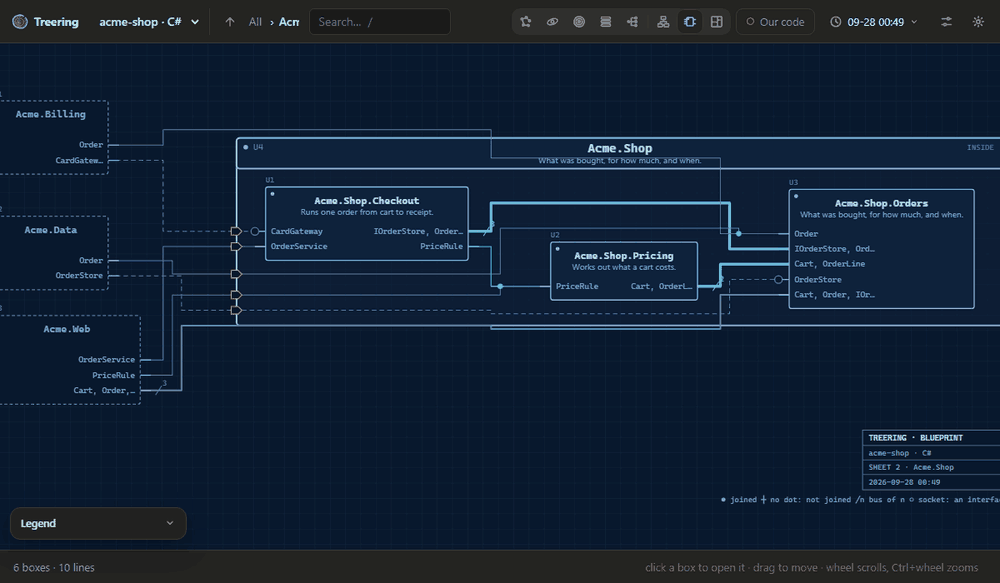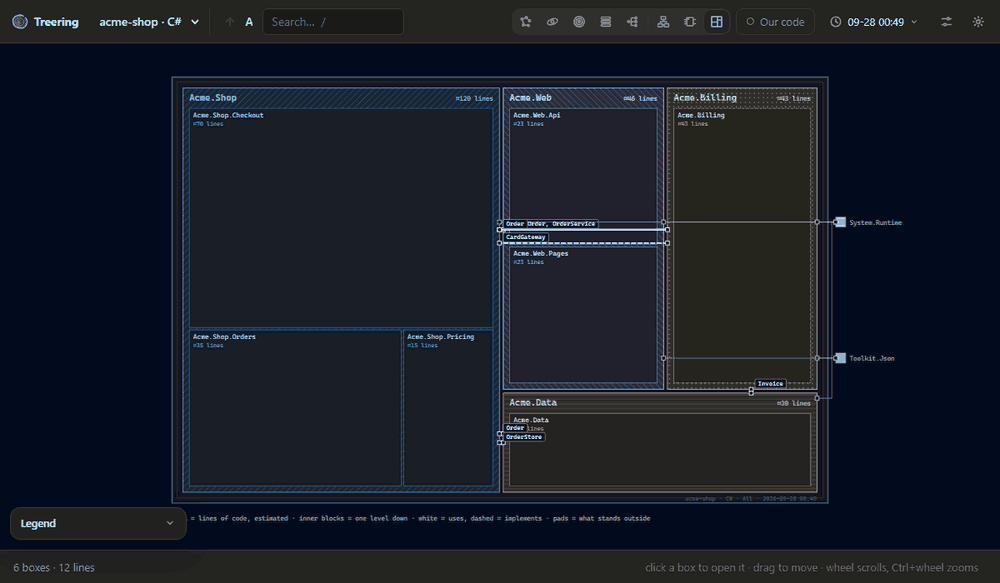
Click a box to go inside it; the part you opened frames what it holds. Then back out, and the same sheet as a chip.
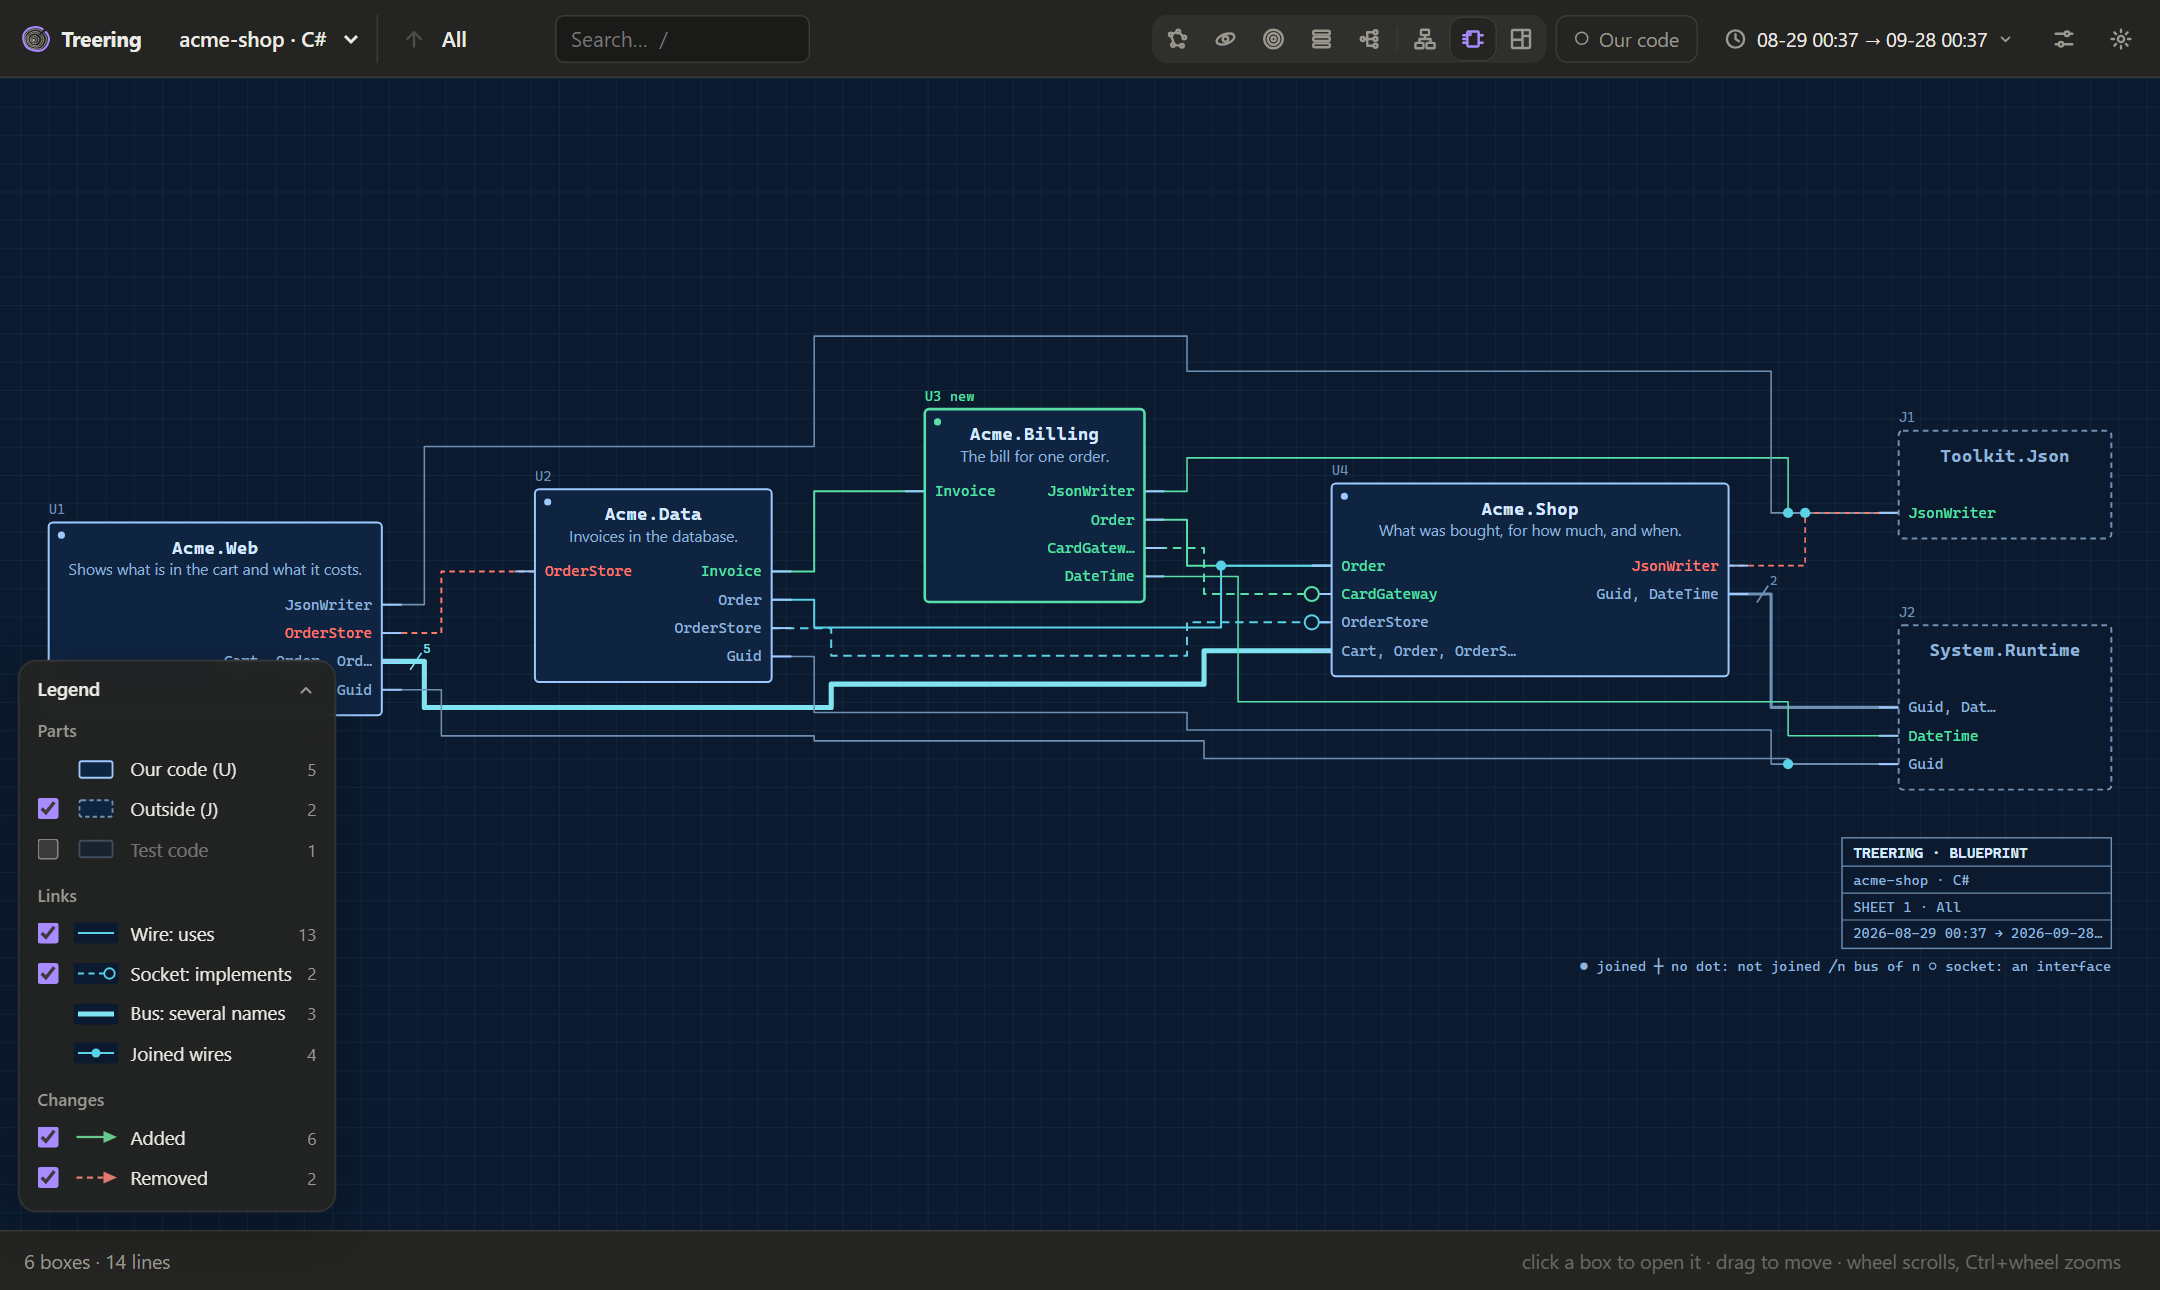
The sample project's modules as a schematic, compared with a month earlier. Green is new: a Billing module now implements the payment interface. Red dashed is gone: the web pages used to call the database directly.
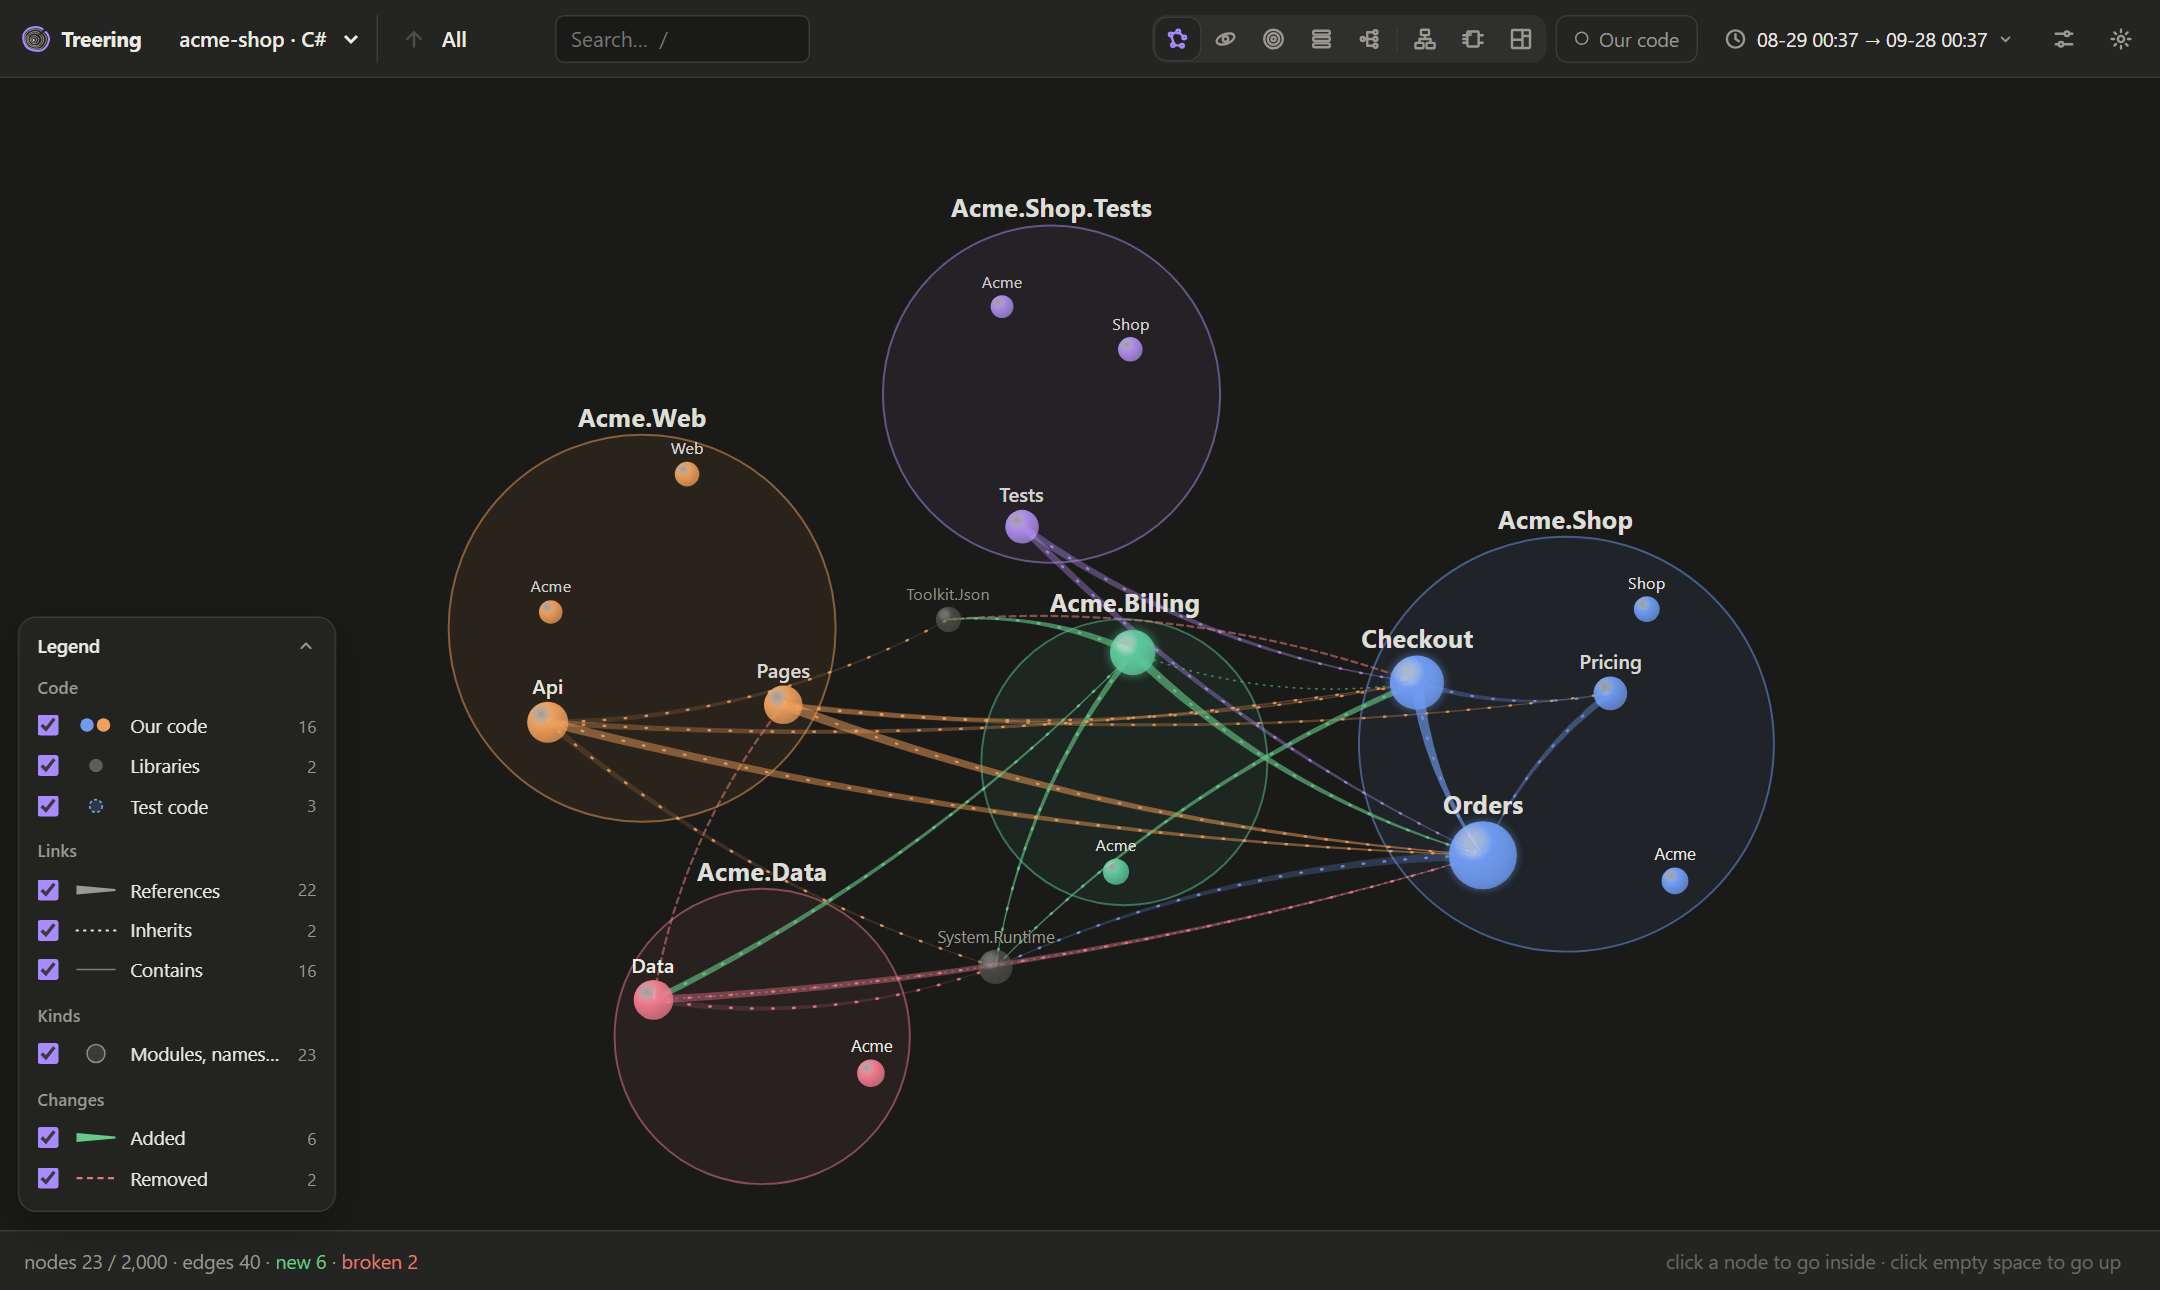 | 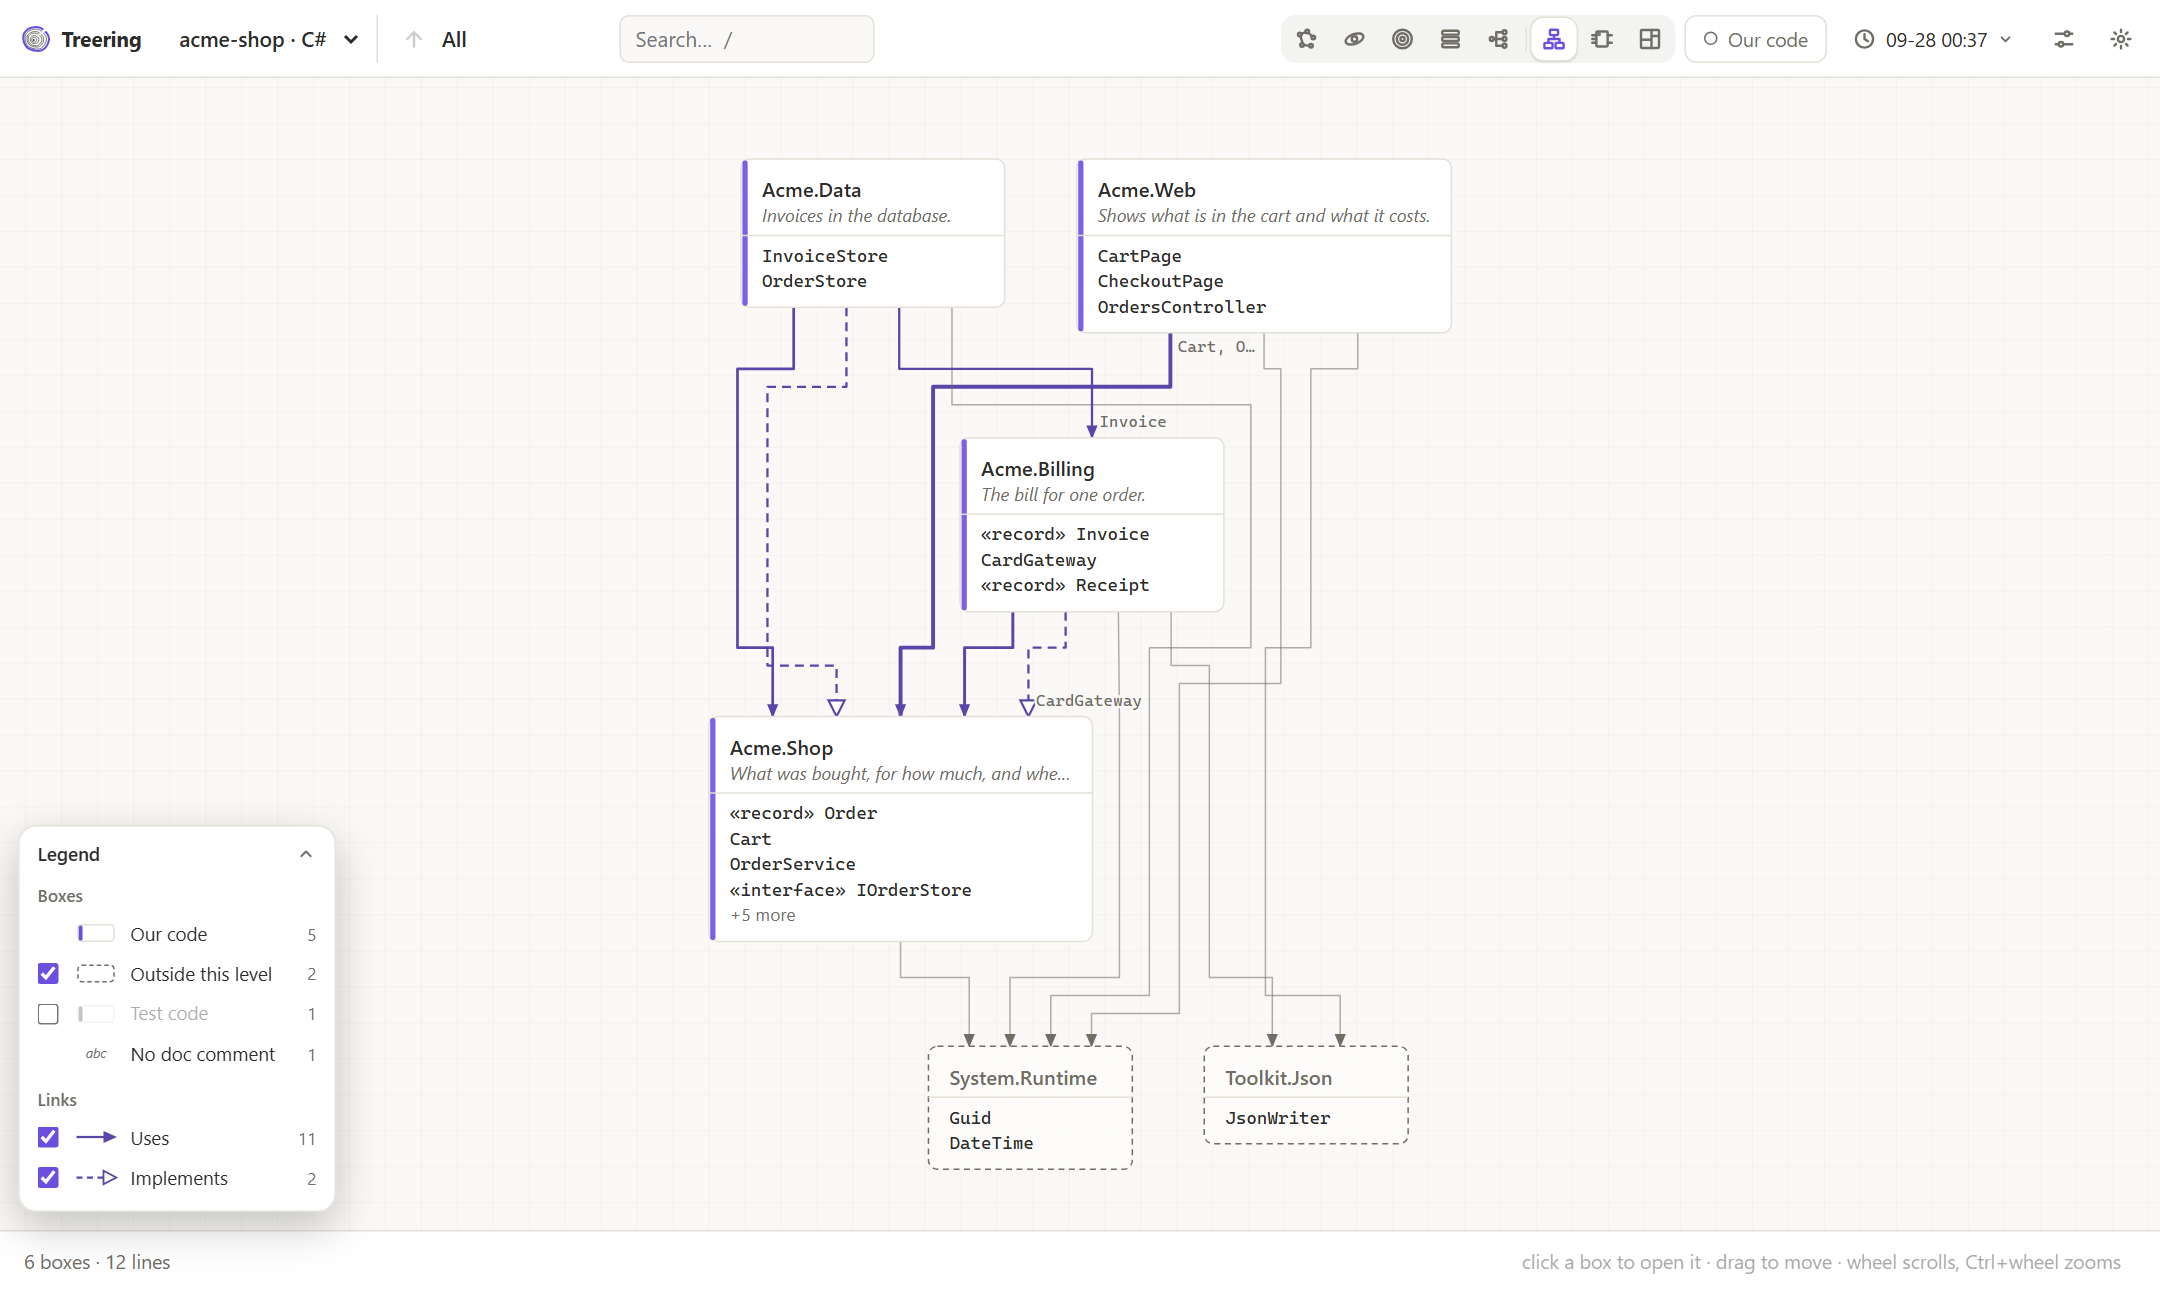 |
| Map. Modules as bubbles and the calls between them. New lines are green, broken ones red. | Blueprint. One level as boxes in tiers, each with its role and what the others use it for. |
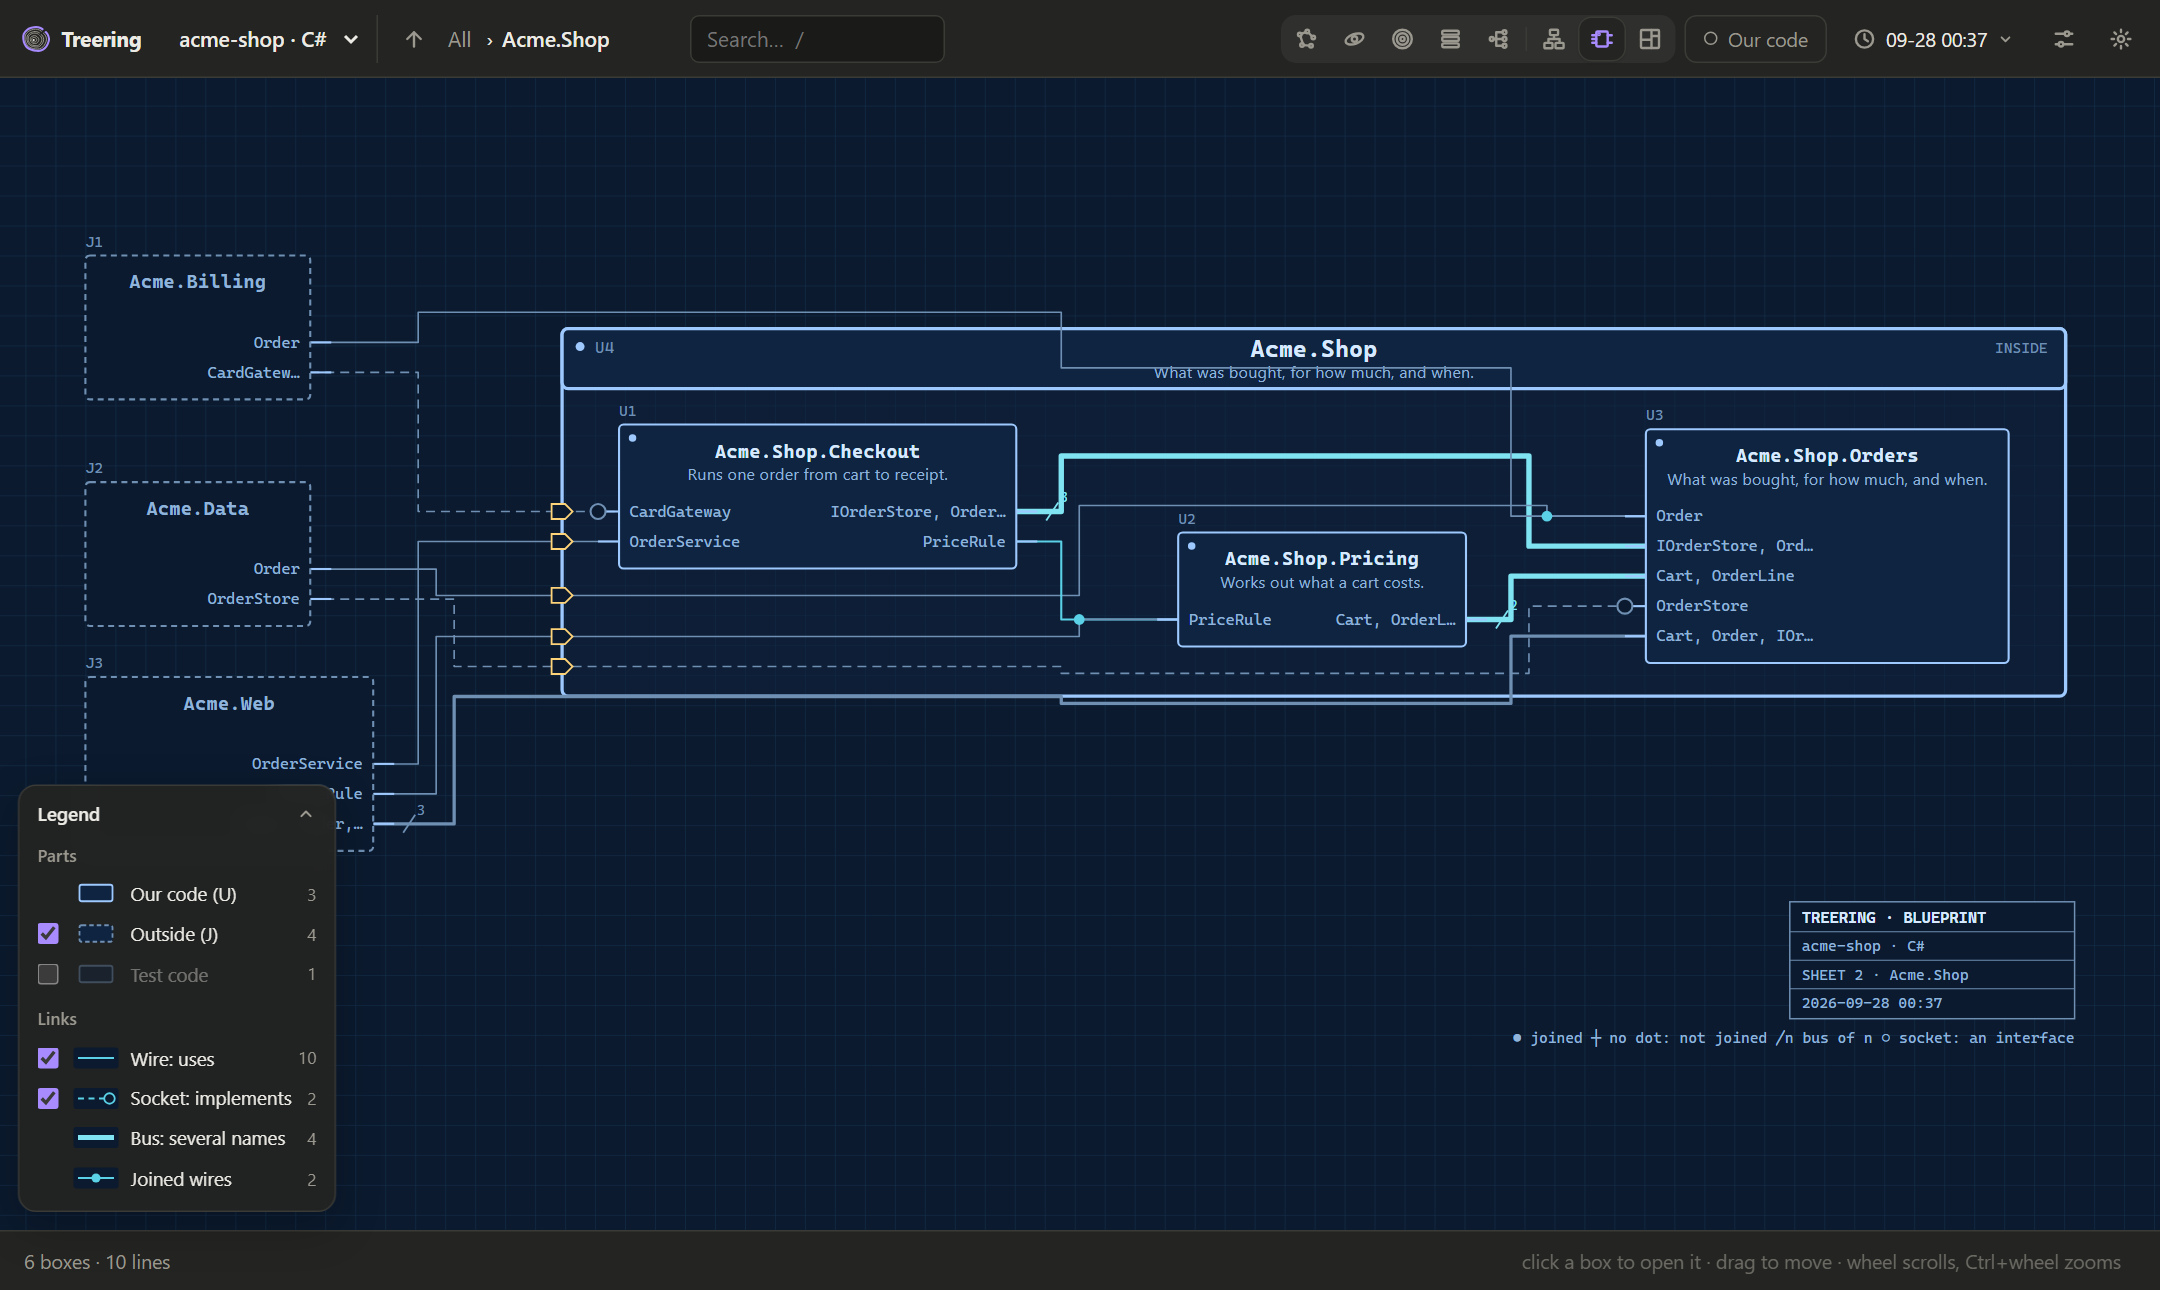 | 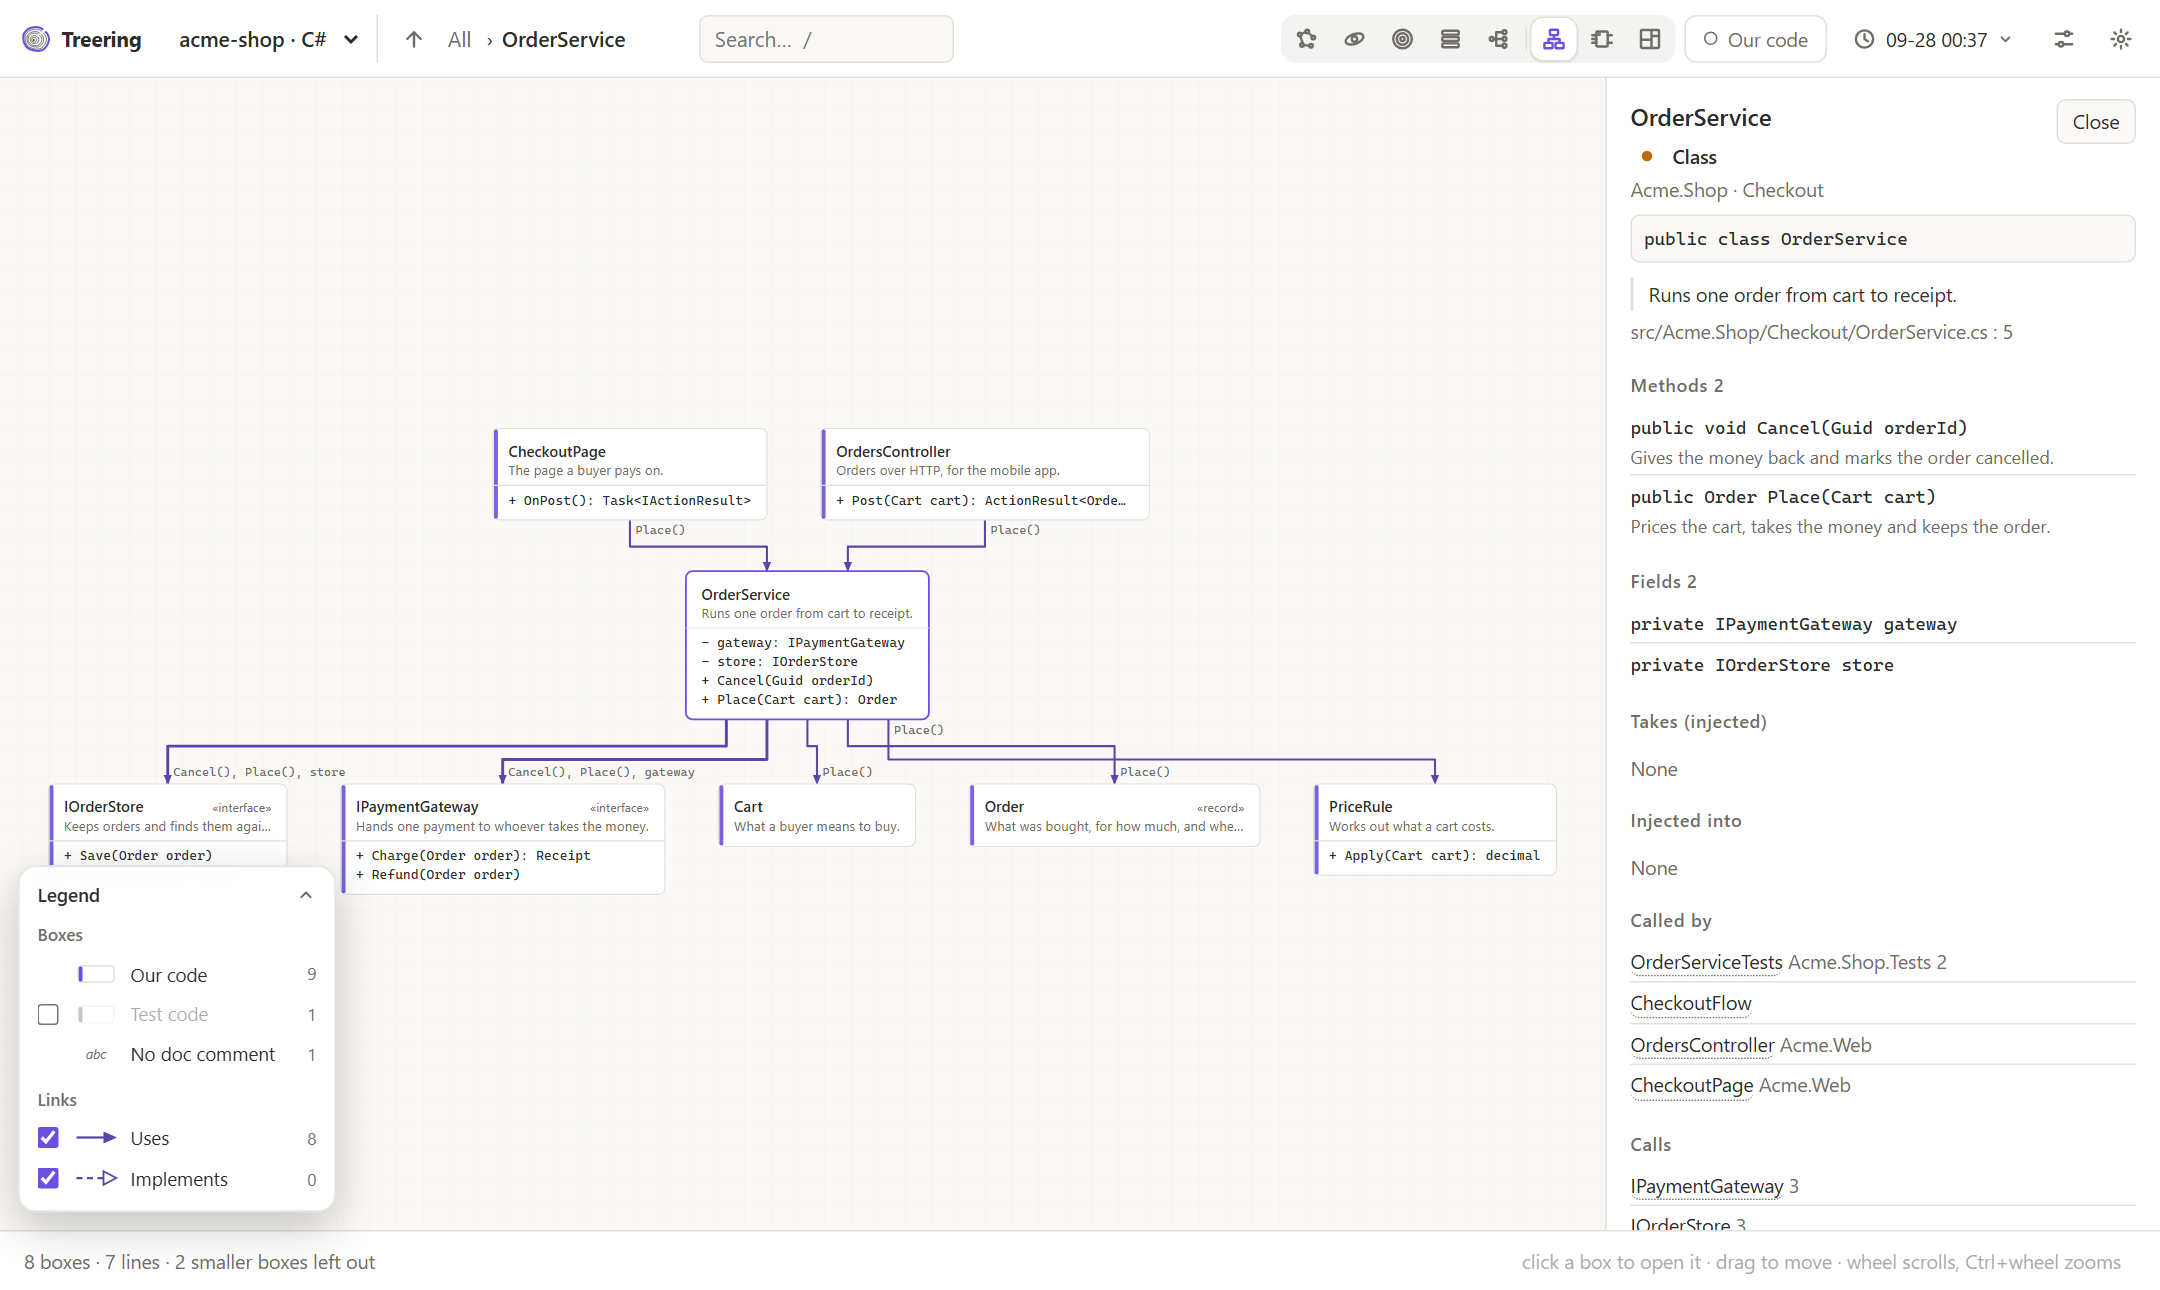 |
| Inside a module. The module you opened frames what it holds; wires cross its edge at sheet ports. | One class. Its fields and methods, the types it works with, and which member ties them. |
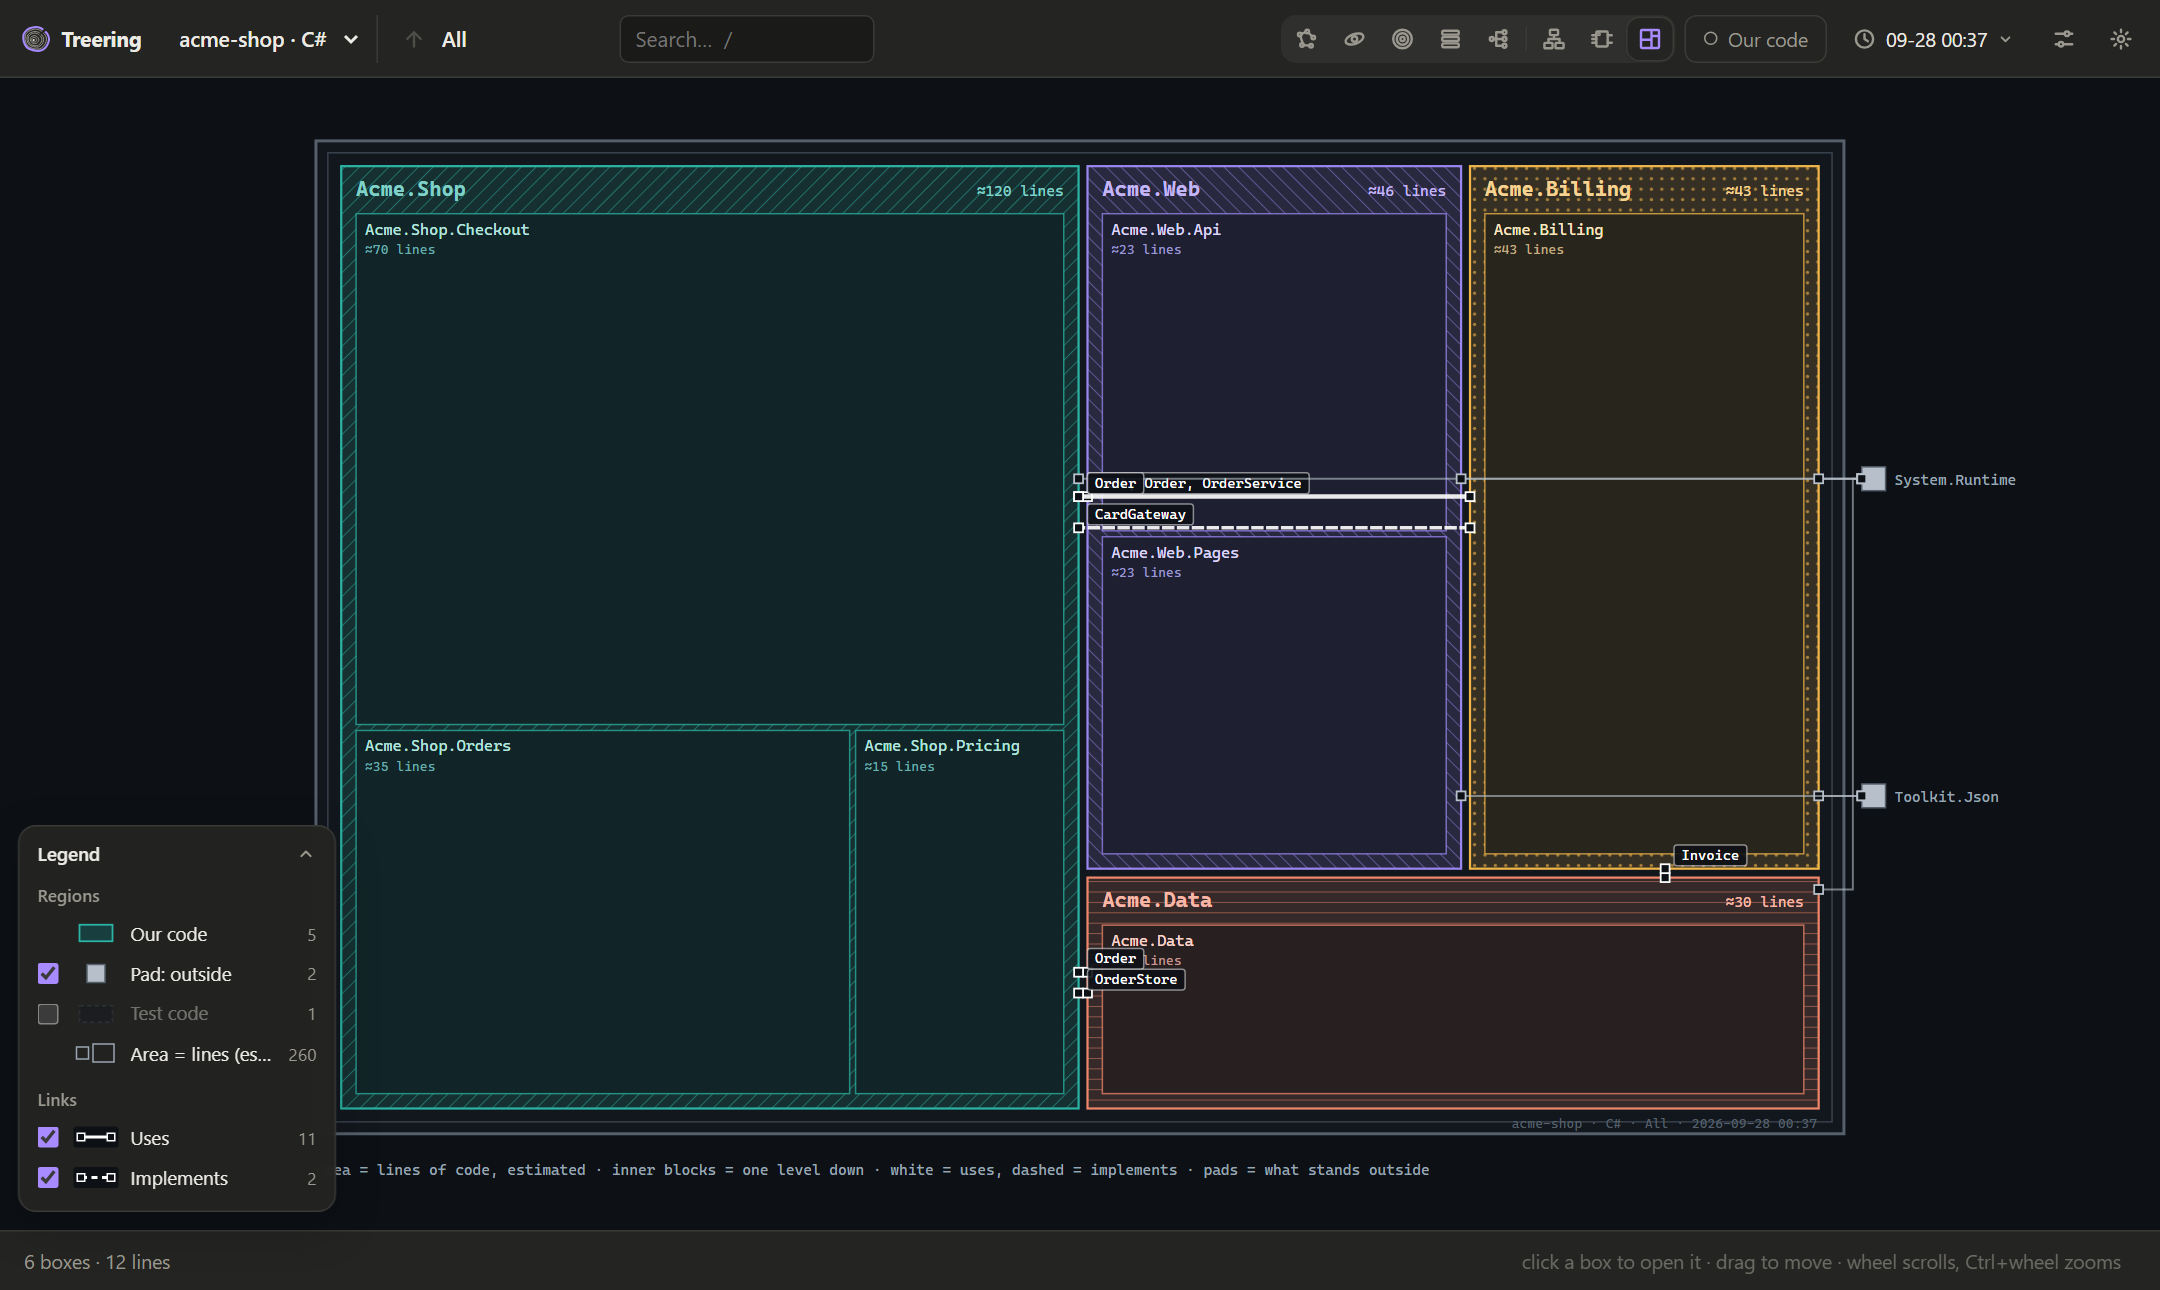 | |
| Chip. Where the weight is: each region as big as its code, libraries as pads on the edge. |
All of these are the sample project that comes with Treering (treering sample), a small made-up shop.
Treering is still in development, and the database format may change between releases. The design notes are in treering-plan.md (in Korean).
Install
Windows (PowerShell):
Linux (x86-64):
Each script downloads the latest build from Releases, checks it against the published checksum, and puts treering on your PATH. On Windows it also adds Treering to the Start menu. Neither needs administrator rights, and running a script again updates Treering. If you'd rather not run a script, download the zip or tarball from Releases and unpack it anywhere.
Then run treering, or open it from the Start menu. It starts the server and opens http://127.0.0.1:7377 in your browser. If Treering is already running, it only opens the browser.
To look around before importing anything, choose Or look around a sample project first on the first screen. It adds acme-shop, a small made-up online shop with a month of history. treering sample adds it from the command line.
Install the indexers
Treering doesn't parse source code itself. It reads SCIP indexes, which each language's indexer produces. Install the indexers for the languages you use:
Import a repository
import looks at which languages the repository contains and runs each indexer with the flags it needs. For C# it indexes the solution at the root, or each project if there's no solution. For TypeScript it indexes each topmost package.json, and for Python each pyproject.toml. The graph is stored in your user folder, never inside the repository, and treering projects lists what you've imported.
treering serve opens the map at http://127.0.0.1:7377. Without a database argument it serves every imported project, and you can switch between them in the menu at the top of the page.
You can also import from the page. Open the project menu, choose Import…, then Choose a folder…. The server opens your system's folder picker (Explorer on Windows, the standard dialog on macOS, zenity or kdialog on Linux), because a browser won't give a page the full path of a folder. You can type the path instead. The import starts when you pick a folder, and the dialog shows each indexer as it runs. If one fails, it tells you why and what to try.
The import and folder endpoints only accept JSON requests sent by the page itself, so another site open in your browser can't start an import or open a window.
Read the map
The map shows modules, namespaces and types as nodes, and the references between them as edges.
- Click a node to go inside it. The node you entered stays on screen as a ring around its contents. Click empty space, right-click the ring, or press Esc to go back up, and the map marks the node you just left.
- Colour shows whose code it is: each of your own modules has a colour, and libraries are grey. Size shows how much a node is used.
- The Shape menu lays out the same graph five ways: Constellation, Orbit, Ring, Layers and Tree. Layers stacks dependencies from top to bottom and keeps cycles together. Tree shows what contains what, one branch at a time.
- The side panel describes what you're inside, or the type you clicked: its members, what it injects and where it's injected, what it implements, its callers and what it calls. Each name in the panel links to that node.
- Press
/orCtrl+Kto search. Picking a result takes you to where it lives. - At and Compare show the graph at one snapshot, or the edges added and removed between two.
- Scope switches between everything and Our code. A symbol counts as yours when the index contains its definition, so libraries drop out without guessing from names. On Acme.Shop this cuts 38 modules to 4 and 829 types to 401.
- Theme offers Light, Dark, Slate, Skyfall and Obsidian, and Language switches between English and Korean.
- If your system is set to reduce motion, the decorative animation stops.
Keep it up to date
update re-indexes only the projects whose files changed. Each changed file goes to its nearest project (.csproj, package.json, or pyproject.toml and setup.py) and that language's indexer, so a repository with several languages updates each part with its own tool. If an indexer is missing, Treering prints the command that installs it.
watch runs update on a timer and adds a snapshot only when something changed, so the history fills in while you work. It starts from the commit recorded in the last snapshot, so you can stop and restart it without losing anything, and it counts uncommitted changes as well as commits.
You usually don't need to run watch yourself: treering serve does the same for every imported project while it runs. Every 10 minutes it re-indexes what changed and adds a snapshot, and if you're looking at the latest snapshot the page moves to the new one by itself. A re-index that leaves the graph as it was adds no snapshot. Turn it off with --no-watch or under Settings on the page, change the period with --watch-minutes N, and pick another port with --port N.
Work with indexes directly
You can run an indexer yourself and load its output. For C#:
Always pass --allow-global-symbol-definitions to scip-dotnet. Without it, symbols don't carry their package name, and once you index projects separately or add snapshots, one symbol turns into several. In one test that recorded 6,784 symbols as added and 6,790 as removed.
To compare over time, load more snapshots:
diff lists the dependencies added and removed between two snapshots, and growth shows when a type's callers increased.
Use it from an agent
This runs a Model Context Protocol (MCP) server over stdio for the projects you've imported. It has six tools: list_projects, find_symbol, callers_of, subgraph, changed_since and snapshots. Each tool takes a project (a name or id from list_projects); left empty, it asks the most recently imported one. They run the same queries as the page, with the same size limits. When a result would be too large, the response says what was left out so the agent can narrow the question and ask again. treering mcp graph.db answers about that one database only.
To add it to Claude Code:
In other hosts, the command is treering with the argument mcp. Each release also carries MCP bundles (treering-win-x64.mcpb, treering-linux-x64.mcpb) for hosts that install MCPB in one step, and is published to the MCP Registry as io.github.RedholeTechnologies/treering.
Performance
On Acme.Shop (4 projects, 632 .cs files):
| Step | Result |
|---|---|
| Indexing (scip-dotnet) | 89s |
| Loading into the graph | 2.6s, 53 MB peak memory |
| Database size | 5.9 MB, from an 8.2 MB index.scip |
| Cost of a second snapshot | 27% more (5.9 MB to 7.5 MB) |
| Whole-map query | 29 ms by module, 30 ms by namespace, 48 ms for every type |
| Drill-down query | 182 ms (384 types, 2,933 edges) |
| Incremental update | 17s, of which 16.6s is indexing |
On a large C# repository (11,385 .cs files):
| Step | Result |
|---|---|
| Indexing | 3 min 28s, 34.5 MB index |
| Symbols and edges | 43,932 and 185,266 |
| Memory while scanning | 41.6 MB, the same as for the 8.2 MB index |
| Loading | 11 to 15s, 103 MB, 40.3 MB database |
| Whole-map query | 26 ms for 115 modules, 48 ms for 406 namespaces, 210 ms for every type (capped at 2,000) |
Scanning memory doesn't grow with the size of the index, and every whole-map view stays under 300 ms at this size. That's because edges are summarised per module, namespace and type once, when the index is loaded, instead of on every query. The module map went from 327 ms to 26 ms with that change.
Languages
C#, TypeScript and Python work end to end. Because the input is SCIP, adding a language mostly means adding its indexer: TypeScript needed no changes to Treering, and the module level became npm packages and namespaces became folders on their own. Constructor injection is recognised from .ctor, <constructor>, __init__ and <init>. update and watch handle TypeScript too; on ShopWeb, 19 changed files in one package took 52s.
scip-python 0.6.6 doesn't start on Windows: it builds a regular expression from the path separator, and \ isn't a valid pattern on its own. Treering loads a small script ahead of scip-python that escapes that one pattern. It also finds pip for scip-python, looking in the repository's .venv first and then at any Python the py launcher knows. If there's no pip, it indexes with an empty package list, which only loses the names of third-party packages. On python-sample this produced 1,800 symbols and 6,564 edges in 51.6s.
Each language has its own quirks. TypeScript produces few inheritance edges, because with structural typing the indexer rarely emits implements. And 14.8% of TypeScript references can't be attributed to a definition, compared with 1.4% for C#, because imports and module-level code come before any definition in the file.
Known limitations
SCIP records where a reference is, but not which symbol it sits inside (enclosing_symbol is empty). Treering assigns each reference to the nearest definition before it. That's reliable at the type level, where a file's references belong to the types it defines. At the method level it goes wrong around nested types, lambdas, local functions, property accessors and field initializers, so the page and the MCP tools mark these edges as inferred.
C# top-level statements, the usual Program.cs today, have no definition before them at all. scip-dotnet still writes args as a parameter of the compiler-generated Program.<Main>$, so Treering files those calls under the project's Program. That is how a service's startup registrations show up on the map. If the statements never use args, their calls are left out.
An update can't take less than about 10 seconds, and the indexer accounts for nearly all of it. The smallest C# project spends 16.6s in scip-dotnet, and scip-typescript takes 50s over ShopWeb's one package. Treering's own part, comparing and loading, takes under half a second.
Out of scope
Treering won't include:
- its own language parsers, since the SCIP indexers do that
- LLMs, embeddings or vector search, since the graph has to be reproducible
- cloud sync, accounts or telemetry
- code editing
Build
This produces a single executable of about 52 MB. The web page is embedded in it, so nothing else needs to be installed to run it, not even Node. Without IncludeNativeLibrariesForSelfExtract, e_sqlite3.dll is placed next to the executable.
NativeAOT doesn't work yet, because JSON serialization uses reflection and the MCP SDK scans assemblies.
Why "Treering"
A tree ring is one year of growth laid down around the years before it, so cutting a trunk shows its whole history at once. Treering does the same for code. It keeps a snapshot of the structure for every update, and lets you read back how the modules, types and their dependencies grew. The name says in one word what sets it apart from other code maps: time. It also nods to the trees code is already made of, from syntax trees to the tree of modules, namespaces and types.
The logo is the end of a sawn log: uneven rings around an off-centre pith, a drying crack running in from the bark, and the outermost ring, which is now, in the accent colour.
License
Apache-2.0. The components bundled into a published executable, and their licences, are listed in THIRD-PARTY-NOTICES.md.