Sluicer README
The full upstream README, mirrored here for reference. Install config, tool schemas, adoption signals, and an original overview live on the Sluicer listing page.

Web scrapers that fail loudly when a site's layout changes,
instead of quietly returning empty values.
No model, no API key, no bill.





Documentation · Getting started · In your agent · Scoreboards · FAQ · Changelog
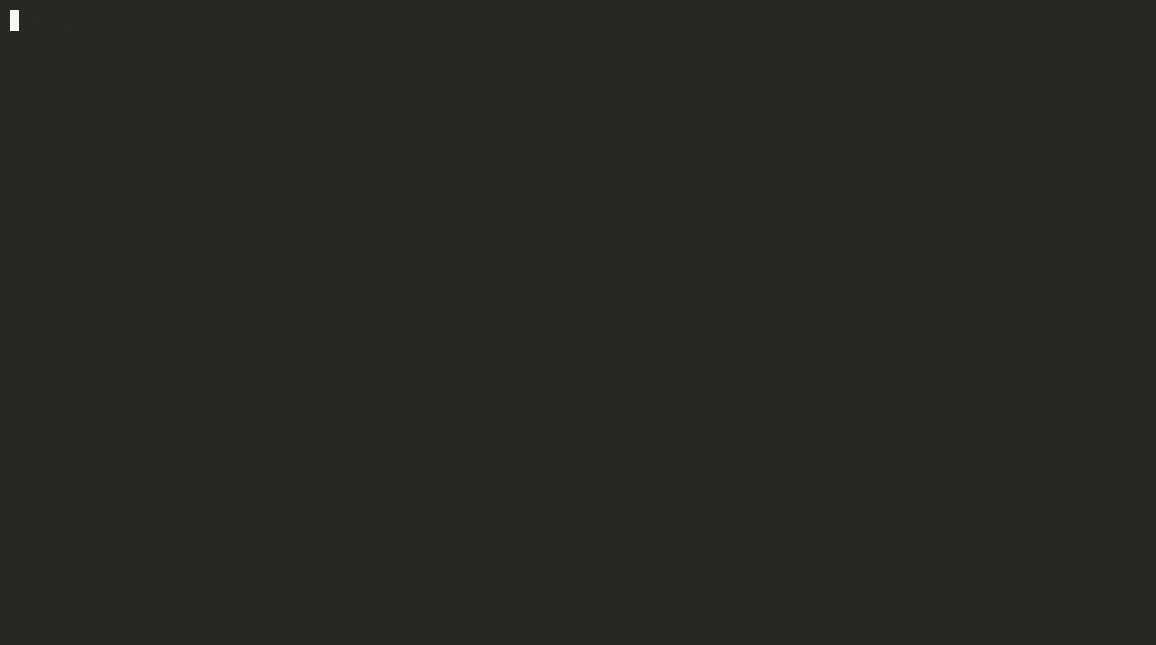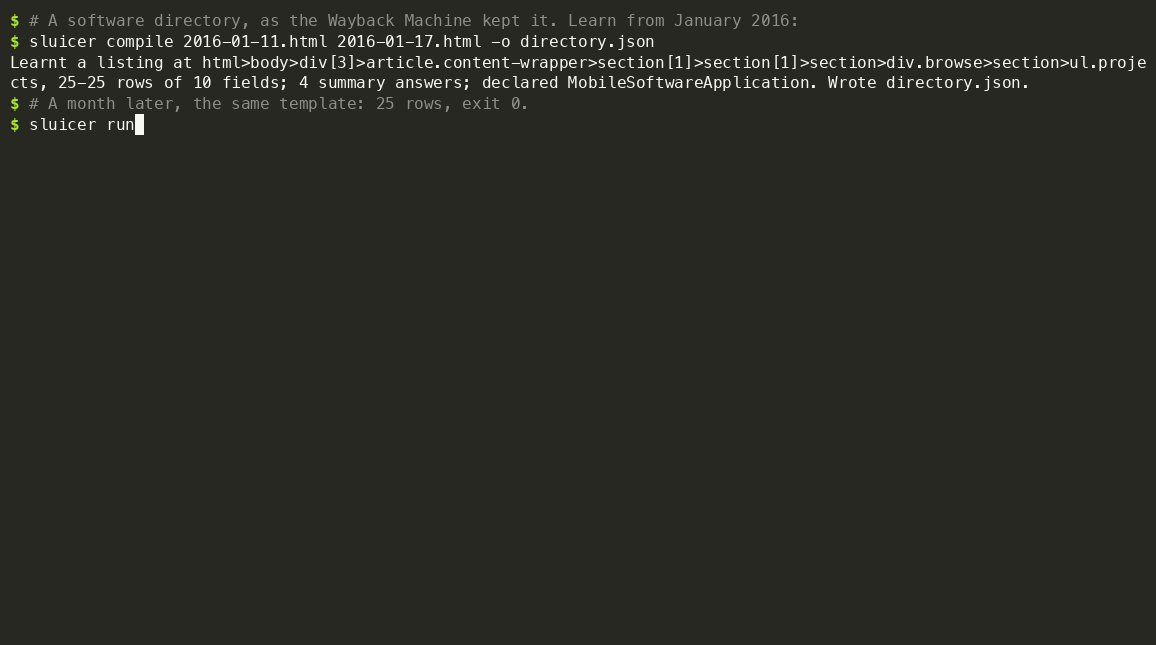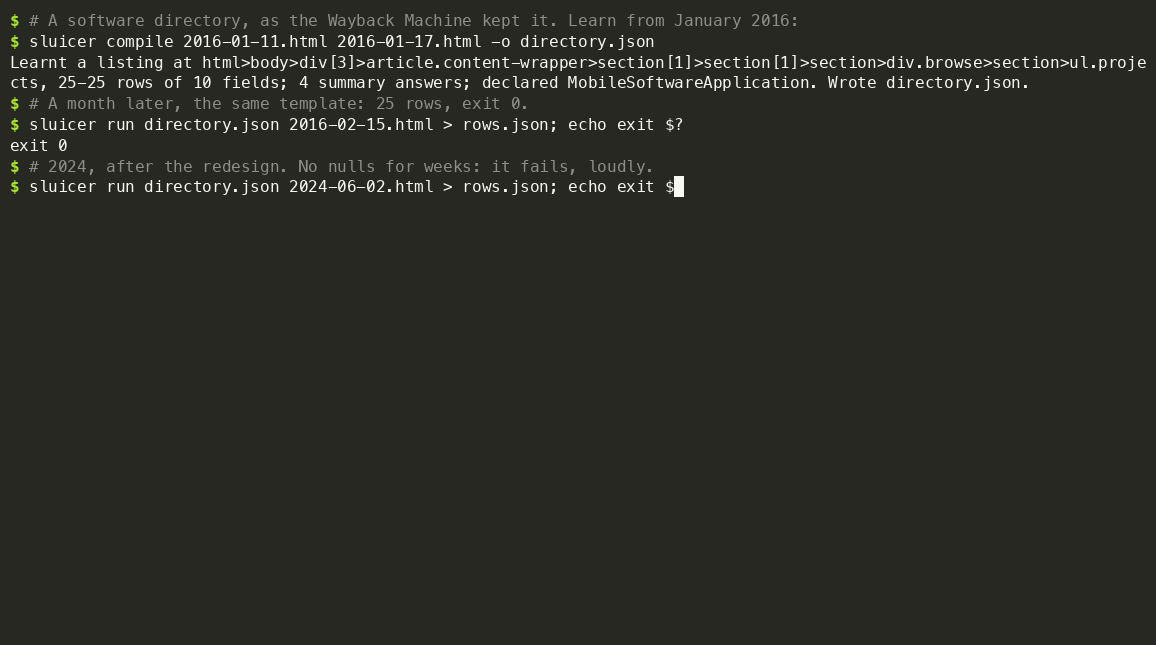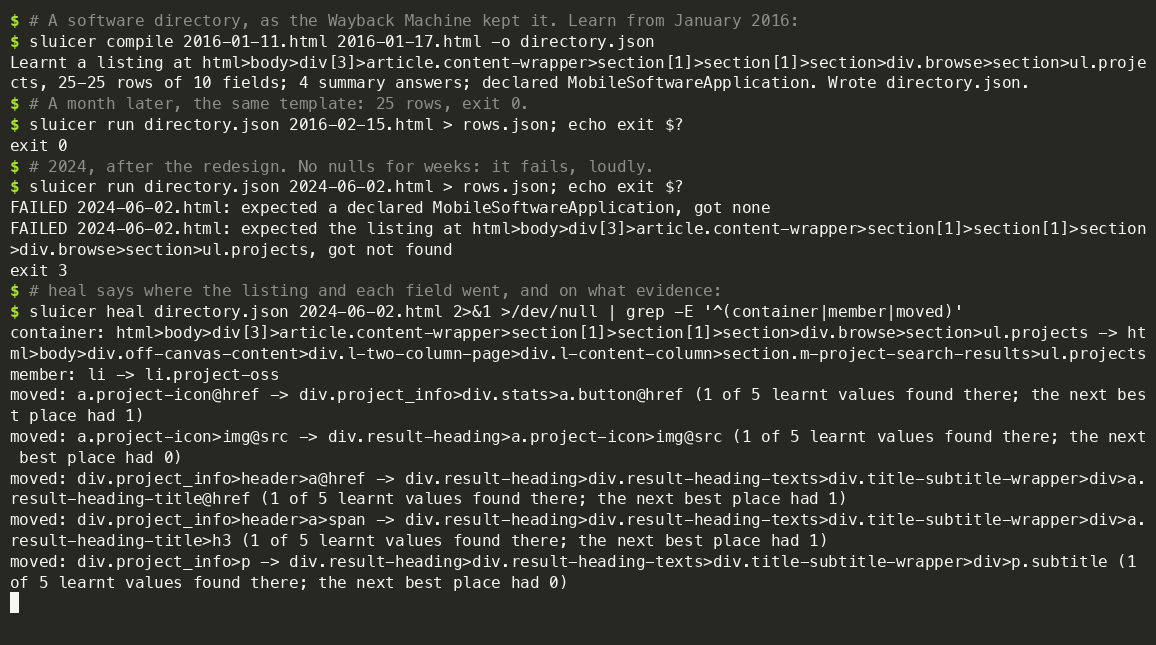
A real site, as the Wayback Machine kept it. The extractor learnt in January
2016 still fits in February. After the 2024 redesign it stops with exit code
3. heal then proposes new places for the listing and five of its
ten fields, each move resting on one of five learnt values: moves to check,
not a repair.
Most scrapers break without a sound. The site changes its markup, and the scraper keeps running and returns nulls, or the wrong column, for weeks before anyone notices.
Sluicer works the other way round. Show it a value on a few pages of a site
(a price, a title, a date) and it learns where that value lives. On every
page it reads after that, it checks the page against what it learnt. If the
layout has changed, the run fails with exit code 3 and names the check that
broke. sluicer heal then proposes where each field went, when the new page
still shows values the extractor was learnt from.
It also reads everything a page already declares about itself: JSON-LD, microdata, RDFa, OpenGraph and four more vocabularies, merged into one record per thing, with every value pointing to the exact place on the page it came from. No model reads any page, so the same page always gives the same answer.
Quick start
books.toscrape.com and quotes.toscrape.com are public sandboxes made for
trying scrapers on. The last command prints FAILED https://quotes.toscrape.com/: expected the listing at html>body>…>ol.row, got not found, its path shortened
here, and exits 3.
After a redesign, sluicer heal looks on the new page for the values the
extractor was learnt from, and proposes a new place for each field it finds
them in. In a clone of this repository, examples/shop/ holds a made-up shop
before and after a redesign that renamed every class:
Each move says how many of the field's learnt values were found in its new
place, and how many the next best place held. heal proposes; it does not
repair. It can only move a field whose old values the new page still shows, so
run it on a page you learnt from, or one listing the same items. On the
drift benchmark's
21 real redesigns, 18 of the new pages shared no item with the old ones, and
heal was fully right on none and partly right on 2. When a field or the listing
is lost, it exits 3 and writes nothing unless given --force.
Exit codes follow grep: 0 found -- a record or a summary answer, a <title>
alone included -- 1 found nothing, 2 could not read the page, and 3 when a page
broke its extractor's checks, a heal lost a field or left a move undecided, or
an audit found a documented rule broken. diff exits 1 when something changed.
The checks are about structure, not truth: a run fails when a field is no longer where it was learnt, no longer reads the way it did, or no longer has its shape. A change that keeps all three, such as a different number in the price's place, passes. On SWDE, the checks flagged 18% of the extractors' wrong answers; the other 82% passed.
Reading what a page declares needs no example at all. The product page read
here is
examples/brake-pads.html,
in a clone of this repository; without one, fetch it first with
mkdir -p examples && curl -o examples/brake-pads.html https://raw.githubusercontent.com/Gi0tto/sluicer/main/examples/brake-pads.html.
The library is imported from the Python you ran pip install sluicer in:
The page states one price in its JSON-LD and another in its OpenGraph tags;
Sluicer reports the conflict instead of picking one in silence. sluicer inspect page.html shows the same reading laid out for a person.
Install
That is the whole install for every command but one kind of page: it reads
HTML you have, fetches and crawls over plain HTTP, audits, learns extractors
and turns a page into markdown. For the sluicer command in an environment of
its own, uv tool install sluicer or pipx install sluicer; to run it once,
installing nothing, uvx sluicer --version; in a uv project, uv add sluicer.
A page a script draws, which plain HTTP brings back as an empty shell, needs a
browser: add the browser extra, then let Sluicer download Playwright's
Chromium once.
sluicer doctor says what is installed, what each missing piece is for, and
the command that adds it for the way you installed Sluicer (pip, uv tool, pipx
or uvx); a command that needs a missing extra names the same command.
What each extra adds
| extra | adds |
|---|---|
browser | a browser, Playwright's Chromium, for a page plain HTTP brings back as an empty shell; download Chromium with sluicer install browser |
mcp | the MCP server; add browser for pages that need one |
api | the HTTP API, with mcp |
microformats | microformats2, which is off by default |
all | every extra above |
stealth | the stealth rung, by scrapling: one page, only when asked with --stealth, never in a crawl; never in all |
markdown | nothing more since 0.10, when trafilatura joined the base install; kept so an older install line still works |
fetch | deprecated since 0.8: browser and stealth together, what it installed before |
The base install is lxml, click, cssselect (CSS selectors), protego
(robots.txt) and trafilatura (markdown), and tomli on Python 3.10 to read a
configuration file: the
HTTP client is Python's own.
What you can give it
| you have | run | and get |
|---|---|---|
| a page, as HTML or a URL | sluicer extract page.html | every record it declares, a summary that answers 25 questions, its conflicts, each value with where it came from |
| many pages of one template | sluicer compile ... --want price=41.90, then sluicer run | the fields you gave an example of, from every page, checked |
| the selectors you already know | sluicer compile --select price='span.price::text' ..., then sluicer run | the fields you named, held to the same checks: a selector a redesign broke fails the run |
| a page that declares nothing | sluicer extract page.html --induce | the rows its markup repeats: a listing's cards, a table's lines |
| a whole site | sluicer map URL, sluicer crawl URL -o site.jsonl | its addresses from its sitemaps, or every page it links to, read politely |
| a list of URLs, a web archive | sluicer batch urls.txt, sluicer warc crawl.warc.gz | one JSON line per page |
| a feed | sluicer feed URL | its items, as one JSON document |
| an article | sluicer markdown URL | its main text as Markdown |
Every request names Sluicer, and robots.txt and Crawl-delay are obeyed; a
crawl waits when a site asks it to. Only a command that reads single pages or
learns an extractor can be told otherwise, with --stealth or --no-robots;
map, crawl and batch cannot. sluicer --help lists every command, and
the command line reference
explains each one.
In your agent
The MCP server has twelve read-only tools, among them extract_declared,
select_values, compile_extractor, run_extractor and heal_extractor. Every answer carries
ok, true only when it can be used as it is. The server does not fetch
localhost, private networks or cloud metadata addresses unless it is started
with SLUICER_ALLOW_PRIVATE=1.
In your agent
covers Cursor, VS Code, Gemini CLI, Claude Desktop, Zed, LangChain, the OpenAI
Agents SDK and Pydantic AI. For any other language, sluicer serve offers the
same tools over HTTP (HTTP API),
and at /mcp the MCP server itself over streamable HTTP, for n8n, Dify and any
client that does not start servers over stdio
(Over HTTP).
Measured, losses included

Every number below comes from a public test set, and every scoreboard gives the command that produces it again. Where another tool does better on what a row measures, the row shows it.
| scoreboard | what is measured | Sluicer | beside it |
|---|---|---|---|
| SWDE, 80 sites | extractors learnt from three pages, run on the other 124,051 | F1 0.850, 11,156 wrong answers | Scrapling 0.671, 56,058 wrong |
| Drift, 44 before/after pairs on 25 sites | a change noticed: 21 changed, 23 did not | 0 failed silently, 0 false alarms | -- |
| Products, 140 pages | price, availability (F1) | 0.750, 0.907 | Zyte's paid API 0.918, 0.957 |
| WCXB, 511 pages | title, author, date found; dates invented | 0.727, 0.532, 0.581; 8 invented | trafilatura 0.745, 0.750, 0.838; 216 invented |
| As served, 360 pages | dates found; right when it answers | 0.780; 0.734 | trafilatura 0.855; 0.393 |
| News, 21 languages | title, author, date found | 0.871, 0.829, 0.970 | trafilatura 0.852, 0.879, 0.970 |
| trafilatura's set, 851 annotated pages | title, author, date found | 0.776, 0.472, 0.588 | trafilatura 0.738, 0.669, 0.865 |
Sluicer reads only what a page states in its markup, so on titles, authors and
dates it answers less often than tools that also read the visible text, and it
invents far fewer dates. Its rules were written while reading the pages of these
scoreboards, so the numbers show how it does on pages it was tuned on. The one
held-out test is the half of SWDE's sites whose pages and errors were not read
while making the rules; its numbers were read at each release and a few times
besides, each listed there, once to decide whether to keep a rule. There it scores 0.845, including five camera sites that
were read before the split and so are not a clean test.
bench/PREREG.md
records which pages each rule was made on.
When not to use Sluicer
- You need authors or dates that pages do not declare. trafilatura reads
them from the visible text and finds more of them. Sluicer guesses them too,
by default since 0.10, in a
visiblefield of its own that never enters the summary (--no-visibleorvisible=Falseturns it off): on the scoreboards it finds more of them and invents some, and on two of them its dates are right less often when it answers. - You need an article's full text.
sluicer markdownuses trafilatura for it; if you need trafilatura's options or other output formats, use it directly. - The site blocks bots. Sluicer is not built to get past bot protection:
every request names it, unless a single-page command is given
--stealth.
Why Sluicer compares it with extruct, trafilatura, Scrapling, Crawl4AI and Firecrawl, and says when each is the better choice.
Learn more
- Getting started, a ten-minute tour, and Extractors, how learning, checking and healing work.
- FAQ, Known limits and What is stable before 1.0.
- Moving from extruct:
from sluicer.compat import extructanswers extruct's own calls. - The full documentation is at https://gi0tto.github.io/sluicer/.
Community
Questions, ideas and what you built go to Discussions. A page Sluicer read wrong is an issue: attach the page, so the fix comes with a test. Report a vulnerability privately, as SECURITY.md explains, and see CONTRIBUTING.md to set up a checkout.
Sluicer is built and maintained by one person. If it saves you time or money, sponsoring it pays for keeping the scoreboards measured and the extractors working as the web changes.
Licence
MIT, except two data files under their own licences: schema.org's type names
(CC BY-SA 3.0) and CLDR's month and weekday names (Unicode License v3); the
package's licence expression is MIT AND CC-BY-SA-3.0 AND Unicode-3.0. The base
install needs lxml, click, cssselect and protego, all BSD-3-Clause,
trafilatura, Apache-2.0, and on Python 3.10 tomli, MIT. The tree under
trafilatura and the extras is not all permissive: tld is MPL-1.1,
GPL-2.0-only or LGPL-2.1-or-later, and certifi is MPL-2.0, both brought by
trafilatura, and orjson, from an extra, is MPL-2.0 alongside Apache-2.0 or
MIT. CI lists every licence in that tree and fails on one
nobody has read; NOTICE
says more.