Sem README
The full upstream README, mirrored here for reference. Install config, tool schemas, adoption signals, and an original overview live on the Sem listing page.
Part of the Ataraxy Labs stack: agent-native infrastructure for software development. See also: weave (entity-level git merge driver) · inspect (semantic code review) · opensessions (tmux sidebar for coding agents).
Read the manifesto: https://ataraxy-labs.com/#thesis · Essays: https://ataraxy-labs.com/blogs · LLMs: https://ataraxy-labs.com/llms.txt

Semantic version control built on Git.
Instead of lines changed, sem tells you what entities changed: functions, methods, classes.
Why sem? · Install · Commands · Agents (MCP) · Cloud consent · Releases




sem is a semantic version control tool that works on top of Git. It parses your code with tree-sitter, extracts every function, class, and method as an entity, and diffs at the entity level instead of lines. This means you see "function blahh was modified" instead of "lines x-y changed."
It works in any Git repo with no setup.
Cloud-backed queries are opt-in per repo: logging in does not upload a repo or send a query. See the cloud consent flow for the public/private repo states, preview screen, local audit log, and forget controls.

Install
Or via Homebrew:
Or via winget on Windows:
Or via Scoop on Windows:
Or install the npm wrapper into node_modules:
With Bun, trust the package so its postinstall script can download the binary:
Once installed, update to the latest release any time:
Or via cargo, from crates.io:
Or build the latest main from source (requires Rust):
Or grab a binary from GitHub Releases.
Or run via Docker:
Name conflict with GNU Parallel
GNU Parallel ships a sem binary (/usr/bin/sem) as a symlink to parallel. If you have both installed, they'll collide. Run sem --version to check which one you're using. (#77)
Quick fixes:
If you installed via npm/bun, the binary lives in node_modules/.bin/sem and is invoked through npx sem or bunx sem, which avoids the conflict entirely.
Commands
Works in any Git repo. No setup required. Also works outside Git for arbitrary file comparison.
sem stores its SQLite entity cache outside the repository, under the OS cache directory by default. Set SEM_CACHE_DIR=/path/to/cache to override the cache root; repo-local overrides are ignored so cache files do not dirty the working tree.
sem diff
Entity-level diff with rename detection, structural hashing, and word-level inline highlights.
sem impact
Cross-file dependency graph shows what breaks if an entity changes.
sem blame
Entity-level blame showing who last modified each function, class, or method.
sem log
Track how a single entity evolved through git history.
With no entity, sem log analyzes recent repo history at the entity level:
hotspots (most-changed functions/classes, with author counts) and
co-change pairs (entities that repeatedly change in the same commits:
"if you touch one, don't forget the other"):
sem entities
List all entities under a file or directory path. No path is the same as ..
sem context
Token-budgeted context for LLMs: the entity, its dependencies, and its dependents, fitted to a strict content token budget.
When the target signature itself does not fit, JSON output reports target_omitted: true.
sem find / callers / refs / grep
Cold-start lookups backed by an on-disk, mmap-able query index (index.sem, stored next to the SQLite entity cache). The first call in a repo builds the index; every call after that reads it directly, no daemon or background process involved:
Measured on this repo (crates/) with time: the first sem find (index not built yet) took 185ms; the second call against the same repo, once the index existed, took 7ms. Run it yourself; the exact numbers will depend on your machine and repo size. The point is the cold-vs-warm gap: no daemon needs to stay alive for the warm number to hold.
sem graph
Prints the full entity dependency graph for the current repo, or --json for the underlying edge list (the same graph sem impact and sem context are built on top of):
sem stats
Local, cumulative counters: how many diffs sem has run in this environment and how much of that was noise filtered out. Nothing here leaves your machine (see Telemetry):
Use as default Git diff
Replace git diff output with entity-level diffs. Agents and humans get sem output automatically without changing any commands.
Now git diff shows entity-level changes instead of line-level. No prompts, no agent configuration needed. Everything that calls git diff gets sem output automatically. Also installs a pre-commit hook that shows entity-level blast radius of staged changes.
On macOS and Linux, sem setup also registers a Claude Code UserPromptSubmit hook (sem hook prompt-submit) for prompt-time context injection. It edits ~/.claude/settings.json idempotently, backs it up first, and leaves any hooks you already have untouched.
To disable and go back to normal git diff (also removes the session hooks):
Entity-level diffs on every pull request
Add the GitHub Action and every PR gets one sticky comment showing which functions, classes, and methods changed. It updates in place on each push and calls out cosmetic-only PRs (formatting/comments) explicitly:
No config, no API keys, never fails your build. See action/ for details.
Cloud acceleration (for scale and teams)
Local is always free and always fast: the on-disk index answers day-to-day queries in single-digit milliseconds even from a cold process, so there's nothing to keep warm and no login required. You do not pay to make your laptop fast.
Cloud is for what a laptop can't do. On a very large monorepo the first local graph build can take a few seconds; a shared team graph shouldn't be rebuilt per developer; and CI wants the graph without checking anything out. sem login connects those cases to sem cloud, which keeps a warm, pre-built graph for your registered repos and serves the heavy queries from it instead of rebuilding locally.
It is fully optional and transparent:
- Not logged in, or the cloud is unreachable? sem computes locally and prints the exact same output. No failures, no difference in results.
SEM_LOCAL=1forces local computation even when logged in.- Small repos see no change, local is already fast. The win is for large codebases where rebuilding the graph each time is the bottleneck.
Related commands, all cloud-account scoped:
sem cloud --help lists every subcommand (list, preview, log, never included); each one is read-only or requires explicit confirmation before it sends anything.
If your team runs code review through sem cloud, sem review listen <diff-id-or-url> execs a coding agent pre-configured to join that review as a live listener that answers reviewer questions anchored to specific lines of the diff.
What it parses
32 programming languages with full entity extraction via tree-sitter:
| Language | Extensions | Entities |
|---|---|---|
| TypeScript | .ts .tsx .mts .cts | functions, classes, interfaces, types, enums, exports |
| JavaScript | .js .jsx .mjs .cjs .es6 | functions, classes, variables, exports |
| Python | .py .pyi | functions, classes, decorated definitions |
| Go | .go | functions, methods, types, vars, consts |
| Rust | .rs | functions, structs, enums, impls, traits, mods, consts |
| Java | .java | classes, methods, interfaces, enums, fields, constructors |
| C | .c .h | functions, structs, enums, unions, typedefs |
| C++ | .cpp .cc .cxx .hpp .hh .hxx | functions, classes, structs, enums, namespaces, templates |
| C# | .cs | classes, methods, interfaces, enums, structs, properties |
| Ruby | .rb | methods, classes, modules |
| PHP | .php .inc .phtml .module | functions, classes, methods, interfaces, traits, enums |
| Swift | .swift | functions, classes, protocols, structs, enums, properties |
| Elixir | .ex .exs | modules, functions, macros, guards, protocols |
| Bash | .sh | functions |
| Fish | .fish | functions |
| Lua | .lua | functions (global, local, table, and method forms) |
| HCL/Terraform | .hcl .tf .tfvars | blocks, attributes (qualified names for nested blocks) |
| Kotlin | .kt .kts | classes, interfaces, objects, functions, properties, companion objects |
| Fortran | .f90 .f95 .f03 .f08 .f .for | functions, subroutines, modules, programs |
| Vue | .vue | template/script/style blocks + inner TS/JS entities |
| XML | .xml .plist .svg .csproj + 9 more MSBuild/resource extensions | elements (nested, tag-name identity) |
| ERB | .erb .html.erb | blocks, expressions, code tags |
| Svelte | .svelte .svelte.js .svelte.ts (+ .test/.spec variants) | component blocks + rune JS/TS modules |
| Perl | .pl .pm .t | subroutines, packages |
| Dart | .dart | classes, mixins, extensions, enums, type aliases, functions |
| OCaml | .ml .mli | values, modules, types, classes, externals |
| Scala | .scala .sc .sbt .kojo .mill | classes, objects, traits, enums, functions, vals, extensions |
| Nix | .nix | bindings, inherit declarations |
| Haskell | .hs | functions, signatures, data types, newtypes, classes, instances, type synonyms |
| Elm | .elm | value declarations, type aliases, type declarations, port annotations, infix declarations |
| Clojure | .clj .cljs .cljc | vars, functions, macros, multimethods, protocols, records, types |
| D | .d .di | modules, functions, classes, structs, interfaces, unions, enums, templates, aliases, unittests |
| Zig | .zig | functions, tests, variables |
| SQL | .sql .psql .pgsql .ddl | tables, views, functions, indexes, types, schemas, triggers, sequences |
Plus structured data formats:
| Format | Extensions | Entities |
|---|---|---|
| JSON | .json | properties, objects (RFC 6901 paths) |
| YAML | .yml .yaml | sections, properties (dot paths) |
| TOML | .toml | sections, properties |
| EDN | .edn | top-level map entries (keyword keys) |
| CSV | .csv .tsv | rows (first column as identity) |
| Markdown | .md .mdx | heading-based sections |
| LaTeX | .tex .latex .cls .sty | sections (part/chapter/section/…), plus theorem/lemma/proof/figure/table/algorithm and other tracked environments |
Everything else falls back to chunk-based diffing.
Custom extensions and extensionless files
For files with non-standard extensions, create a .semrc in your project root:
sem also reads .gitattributes patterns (diff= and linguist-language=) if you already have those set up. .semrc takes priority when both define the same extension.
For files with no extension at all, sem detects the language automatically from content (shebang lines, vim modelines, and structural heuristics like package/import/use statements). This covers 30+ languages with no config needed.
How matching works
Three-phase entity matching:
- Exact ID match: same entity in before/after = modified or unchanged
- Structural hash match: same AST structure, different name = renamed or moved (ignores whitespace/comments)
- Fuzzy similarity: >80% token overlap = probable rename
This means sem detects renames and moves, not just additions and deletions. Structural hashing also distinguishes cosmetic changes (whitespace, formatting) from real logic changes.
Use with AI agents (MCP)
On macOS and Linux, clients in the same checkout share a warm repository daemon.
Run sem mcp --status to check it. See the shared runtime contract and reproducible benchmark
for session isolation, fallback behavior, and current platform limits.
sem mcp starts a Model Context Protocol server over stdin/stdout. It's not a command you run and read yourself: it's a server your coding agent launches in the background so it can ask sem questions while it works. That's the reason mcp lives alongside the normal commands. The agent gets 8 entity-level tools mirroring the CLI: sem_entities, sem_diff, sem_blame, sem_impact, sem_log, sem_context, sem_find, sem_grep. (If you're also using sem cloud for code review, four more tools let an agent attach to a review and answer reviewer questions in a loop: join_review, wait_for_branch, reply_to_branch, list_open_branches.)
Why an agent wants these: instead of reading whole files and burning tokens, it can ask "what breaks if I change submitOrder" (sem_impact) or "give me just the context to refactor this function" (sem_context, which returns the function's source plus its callers and callees) and get a precise, deterministic answer from the dependency graph instead of a grep result that might miss a caller.
Add it once, then talk to your agent normally. It calls the tools on its own.
Claude Code:
Or one command that also installs the skill, so the agent knows when to reach for sem:
Cursor, Claude Desktop, or any client with an mcpServers config:
If sem isn't on the agent's PATH, use the absolute path to the binary. No separate install is needed: sem mcp ships in the same binary as every other command.
JSON output
Real output, from a one-line logic change to a Python function:
The named change-type buckets (added, modified, deleted, moved, renamed, reordered) always sum to total. orphan is a cross-cutting metadata count for module-level changes, and those changes are already included in the named change-type buckets. beforeContent/afterContent carry the entity's full source on either side of the change; structuralChange is false when the diff is cosmetic only (whitespace, comments).
As a library
sem-core can be used as a Rust library dependency, from crates.io:
Used by weave (semantic merge driver) and inspect (entity-level code review).
Architecture
- tree-sitter for code parsing (native Rust, not WASM)
- git2 for Git operations
- rayon for parallel file processing
- xxhash for structural hashing
- A per-repo cache directory (SQLite entity cache + an mmap-able query index) backs
find/callers/refs/grepwith cold-process lookups and no background daemon - Plugin system for adding new languages and formats (see CONTRIBUTING.md)
Telemetry
Local by default: sem counts command names (e.g. diff, impact) on your own machine only, and in that mode nothing is ever uploaded. No code, file paths, repo names, or user identity is recorded, and no network call is made.
SEM_NO_TELEMETRY=1 or DO_NOT_TRACK=1 force the record-nothing behavior regardless of mode. Development builds (anything run out of a cargo build target/ directory) never record, so working on sem itself doesn't pollute the numbers.
Contributing
Want to add a new language? See CONTRIBUTING.md for a step-by-step guide.
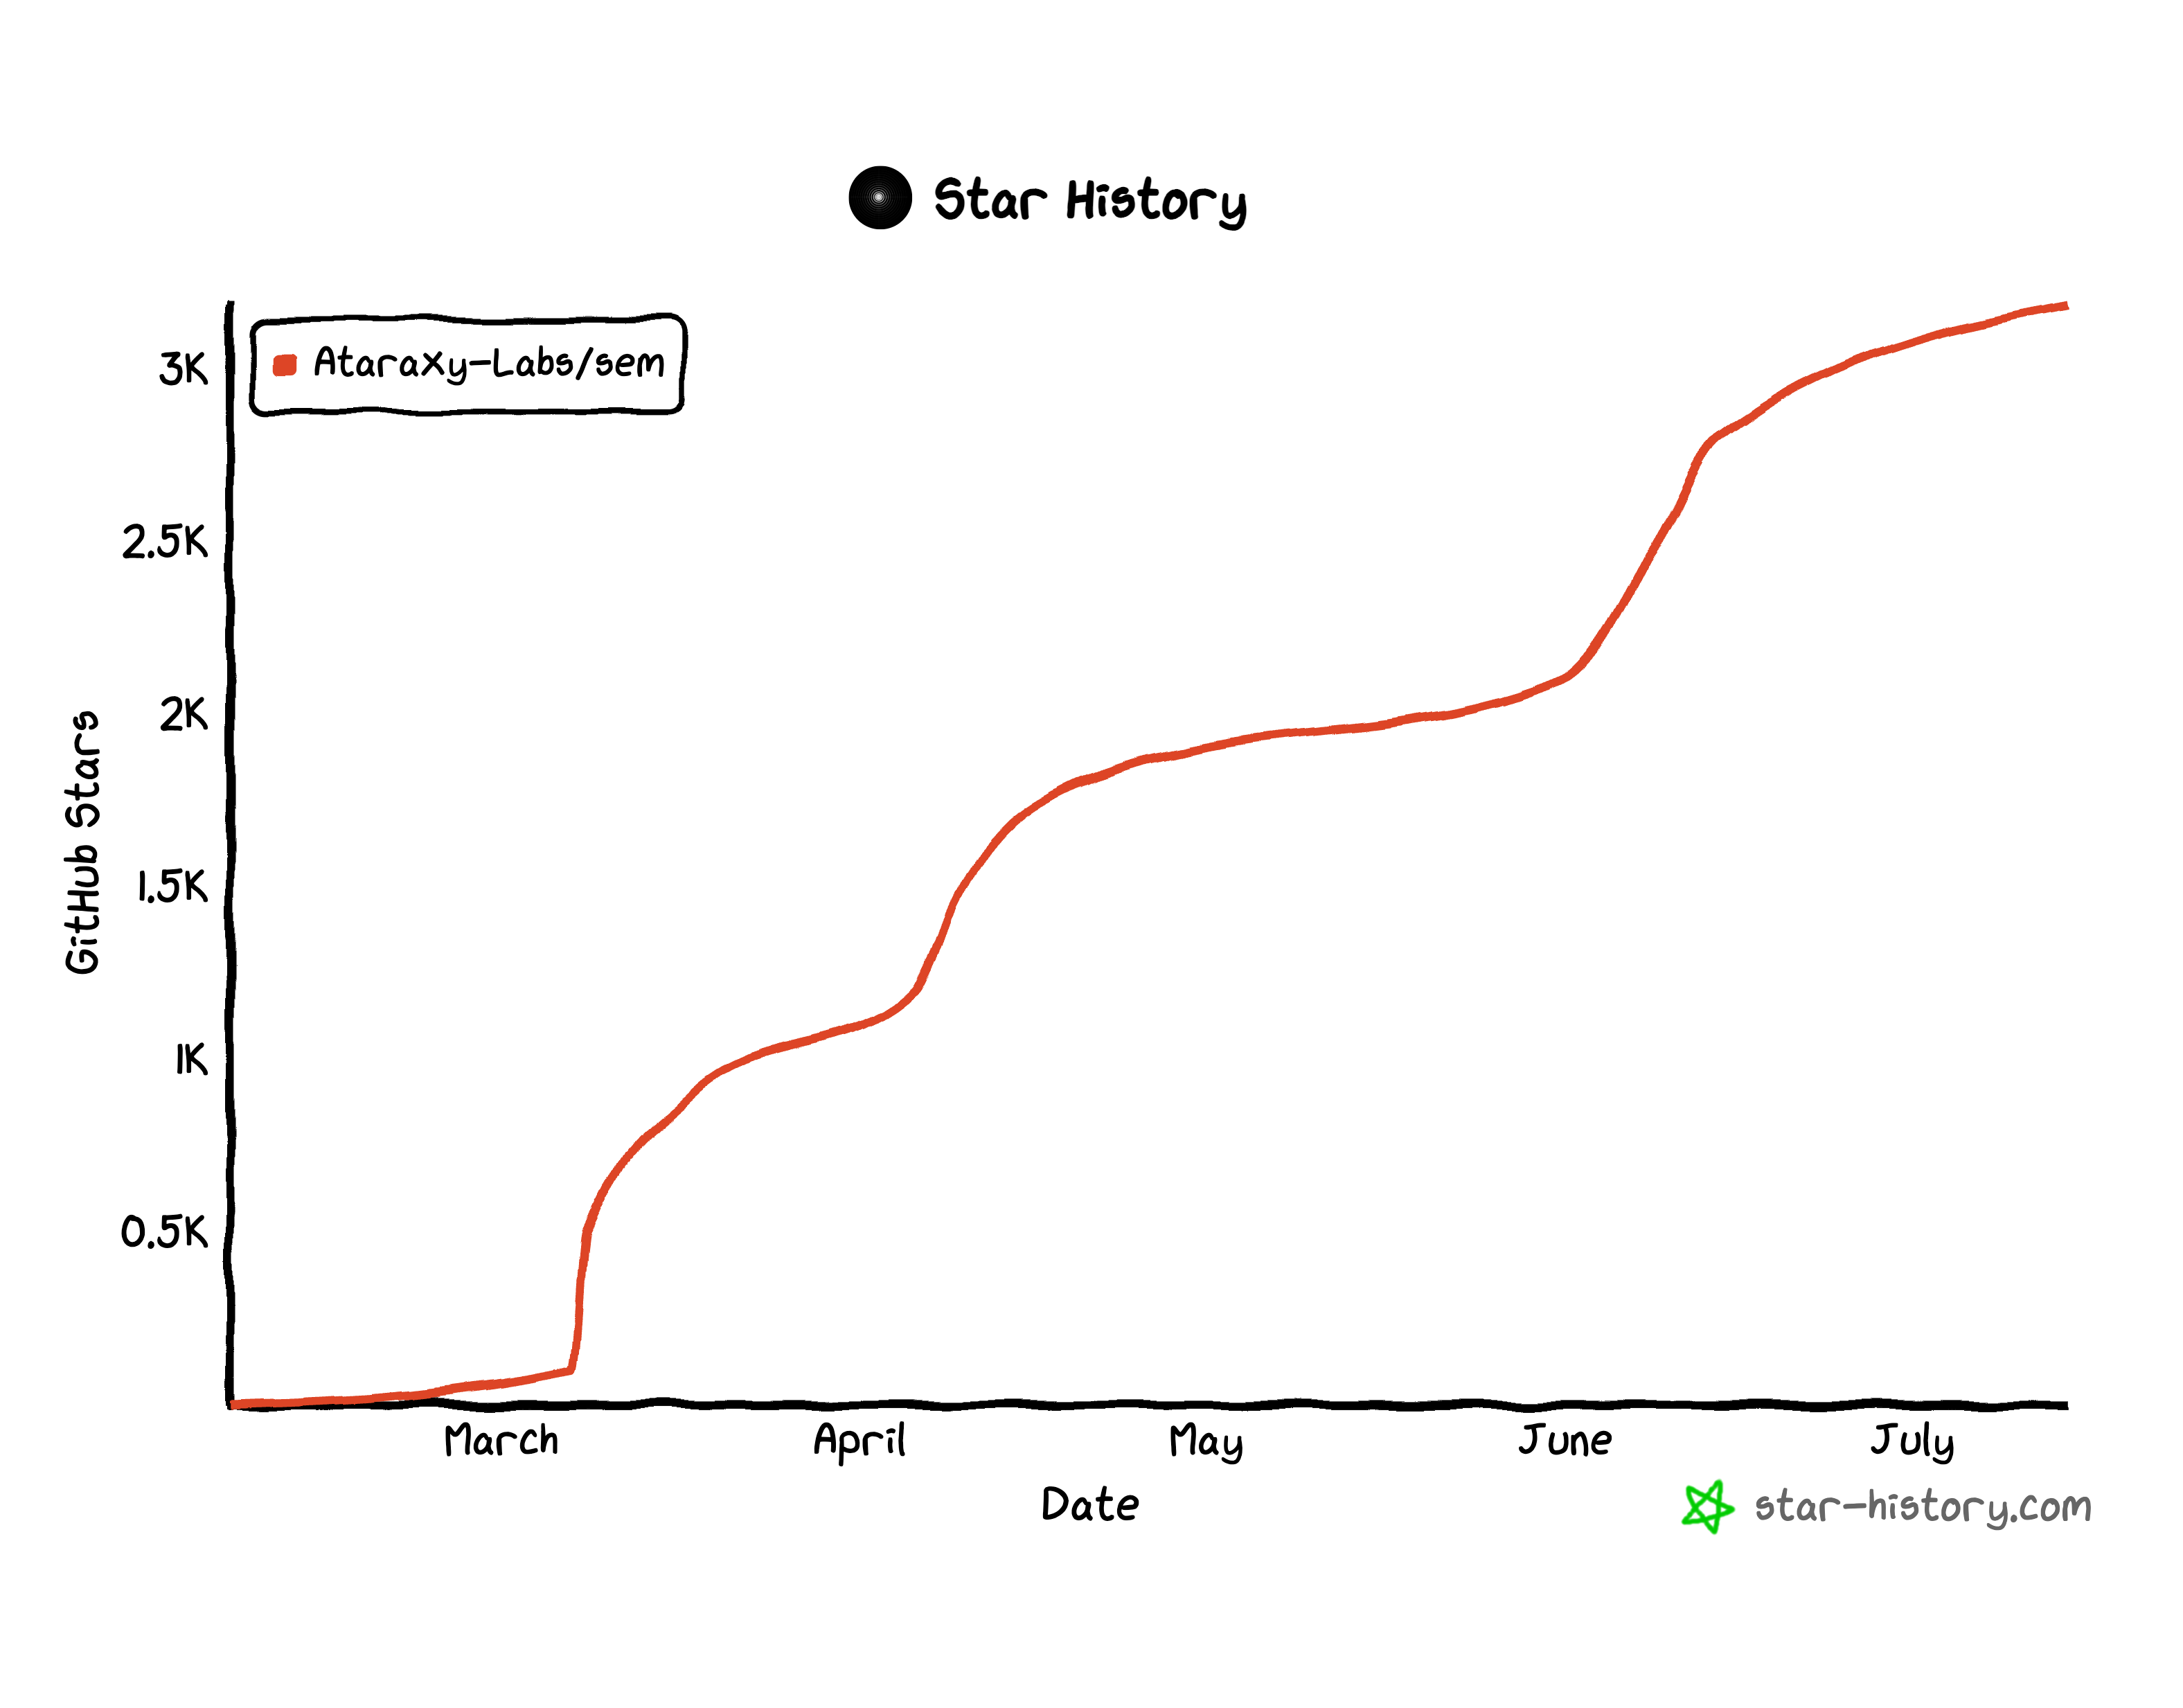
Star History
License
MIT OR Apache-2.0