M
Mirobody
Turn scattered health data into answers you can trace. Self-hosted AI health data engine for lab reports, wearables and genetics, with a built-in MCP server. Run it with Docker and one LLM key, or keep every model local on llama.cpp.
Install Mirobody
Pick your client, then add it in one click or paste the config.
No confirmed install command yet
We only publish a config when the install details come from the project itself — its README, its docs, or a verified owner. We haven’t found those for mirobody, and we’d rather show nothing than a guess you’d paste into your client.
Open setup steps on GitHubOverview
From the project README

Mirobody
Turn scattered health data into answers you can trace.
A self-hosted AI health data engine that brings lab reports, wearables and genetic files into one standardized record.
Standardize health data with one command. Try the full app in Codespaces with your own model key, or run the app, the data and the models 100% on your own machine.
English · 中文
▶ Live demo · Try one command · Open in Codespaces · 100% local
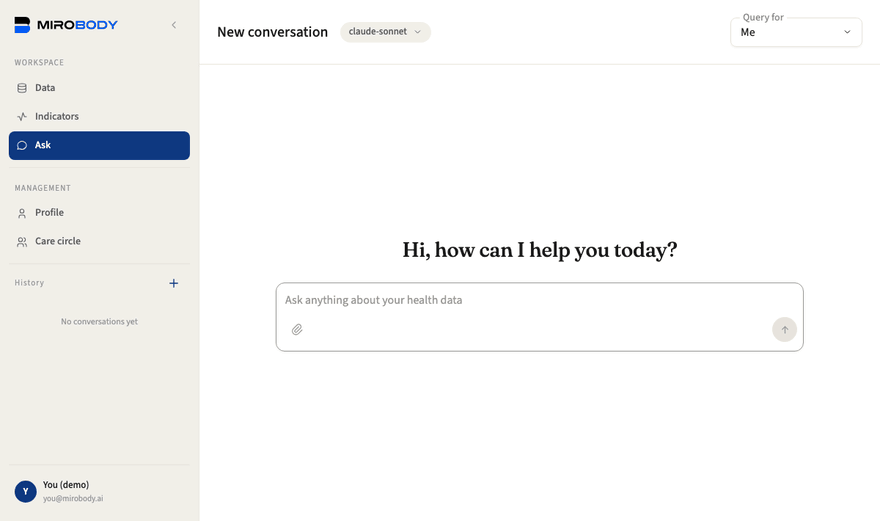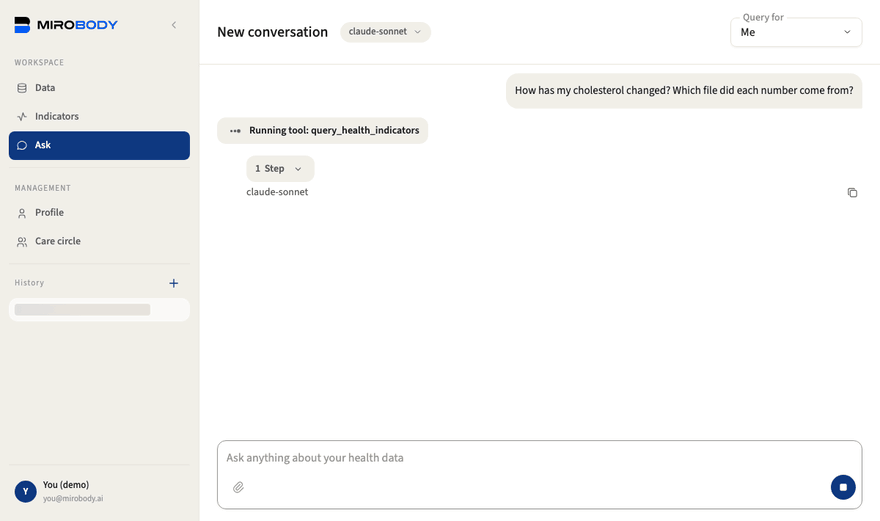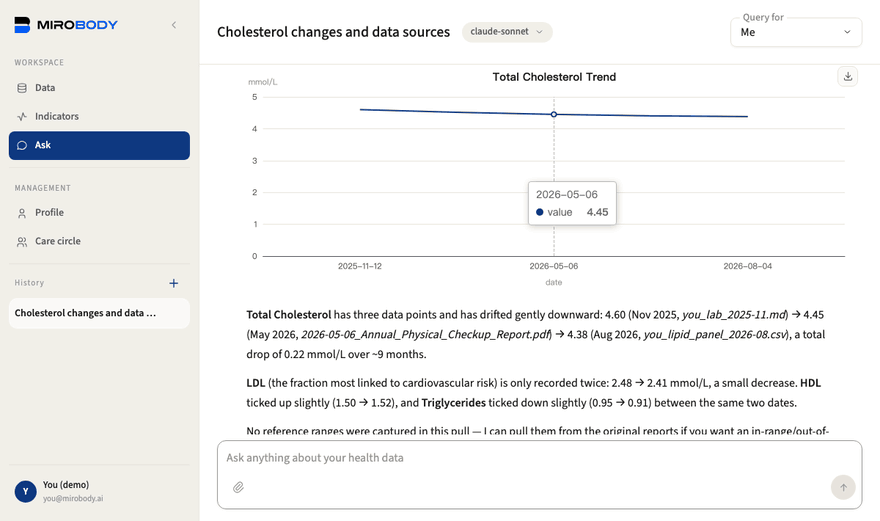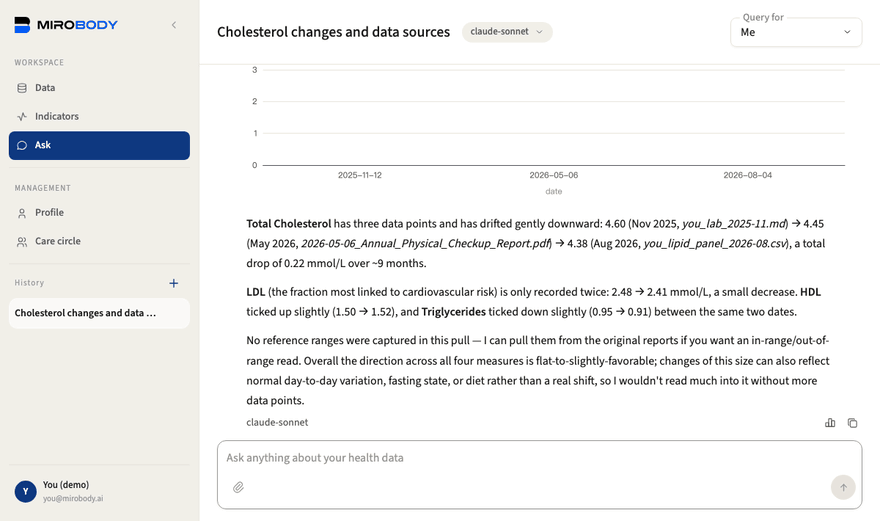
Three reports, three names for the same test. One trend, with the file behind every number.
Choose where to start
| You want to | Start here | What you need |
|---|---|---|
| Standardize names and units | One command | uv; no model or API key |
| Try the full app in your browser | GitHub Codespaces | A GitHub account and your own model API key |
| Keep the app, models and records on your machine | 100% local with Docker | Docker with Compose; 16 GB memory; no API key |
| Keep the app and records on your machine, without Docker | No Docker | Debian or Ubuntu; PostgreSQL 16; Python 3.12; your own model API key |
Try the engine with one command
With uv installed, paste this into your terminal:
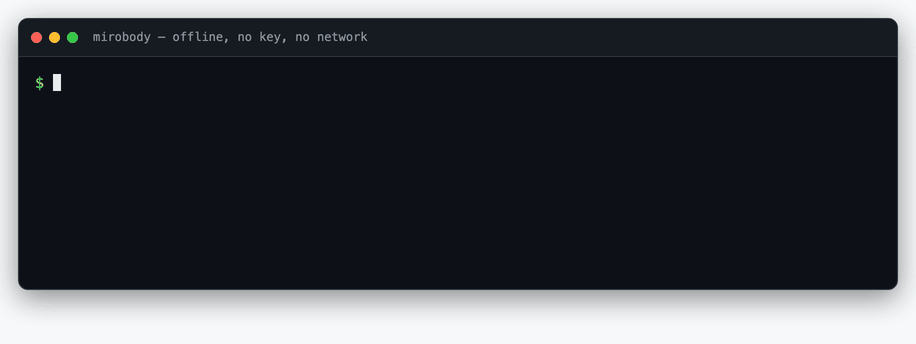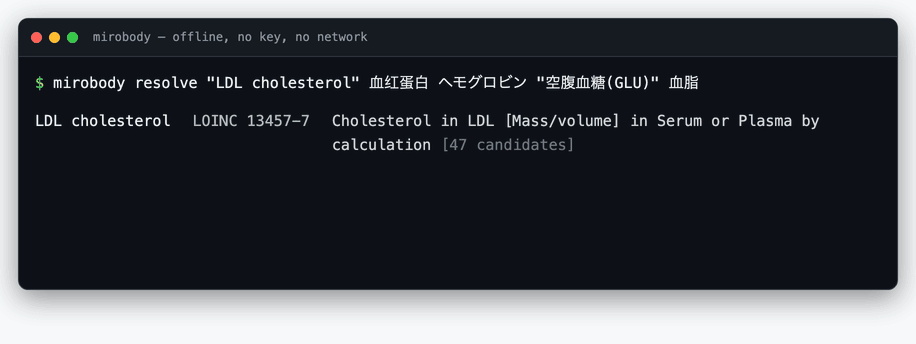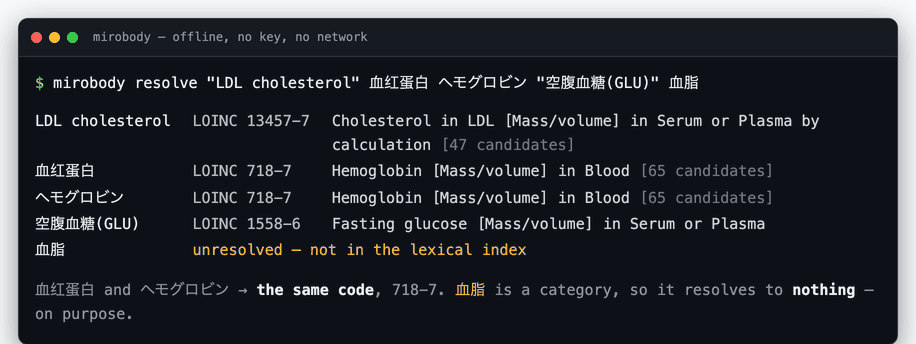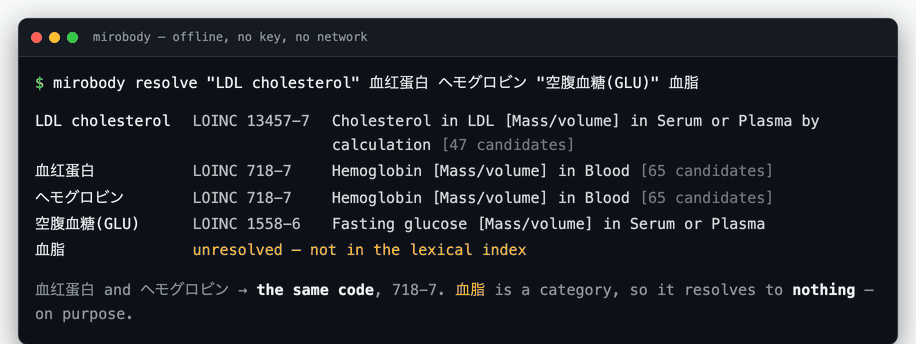
uvx --python 3.12 mirobody resolve "LDL cholesterol" 血红蛋白 ヘモグロビン "Total Kolesterol" 血脂
No repository clone, Docker, model or API key. uv prepares Python and the package for you; the first run needs a network connection to download them. The resolver then works offline from the bundled vocabulary.
血红蛋白 and ヘモグロビン both resolve to 718-7. 血脂 stays unresolved: it names a category, not one test. The same engine standardizes names and units across the full app.
→ Use the engine from Python or MCP
Try the full app in Codespaces
Run the web app in your browser with your own model API key. GitHub prepares the environment; you do not need to install Docker or Python on your computer.

- Create the codespace and wait for the automatic setup to finish in its terminal. It starts the app, Postgres, the worker and the synthetic demo data.
- Open the setup link printed in the terminal and enter your own model API key: OpenRouter, OpenAI, Gemini, Anthropic, DeepSeek, DashScope, or any OpenAI-compatible gateway. The key is saved only after a real request succeeds. The forwarded app port is private by default.
- Sign in as
you@mirobody.ai, code111111, on the Email code tab. Ask "How has my cholesterol changed?" The demo holds 2,019 readings across your record andmom@mirobody.ai's, shared with you view-only. - Upload a synthetic sample from
demo/upload/on the Data page to see a new report join the record, or switch to mom's record and ask again.
The app and its records run in GitHub's cloud; the model service receives the documents and questions it processes. Use the included synthetic data to explore. Codespaces has usage limits and billing; model usage is billed by your model provider. Stop the codespace when you finish. For complete control on your own machine, use the local route below.
Run everything 100% locally
The app, records and models all run on your own machine. No model API key needed. Docker with Compose starts the stack and llama.cpp, with a small answering model and a document reader:
git clone --depth 1 https://github.com/thetahealth/mirobody.git && cd mirobody
COMPOSE_PROFILES=local-cpu ./deploy.sh
Allow 16 GB of memory, at least 8 GB of it for Docker. No GPU is required; on Windows, run the commands in a WSL 2 terminal. The first start needs a network connection to download container images and model weights. If the registry is not reachable from your network, deploy.sh says so and retries through a mirror; DOCKER_MIRROR in .env names your own. After those downloads, document reading, standardization and answers run locally. CPU answers can take minutes; Mac, NVIDIA and Windows options explain how to use your GPU.
Open the app link the script prints. The local models are already selected; sign in with the same demo account above, ask a question or upload a sample. Which model to choose compares the local options.
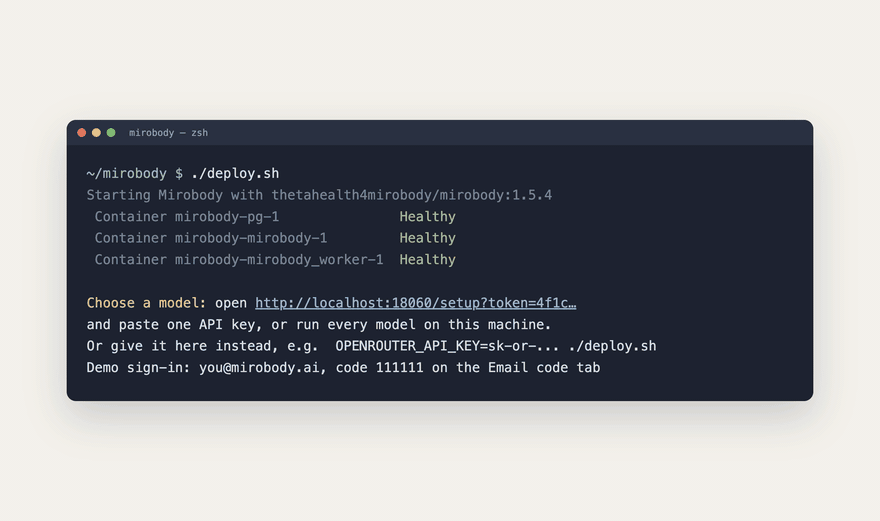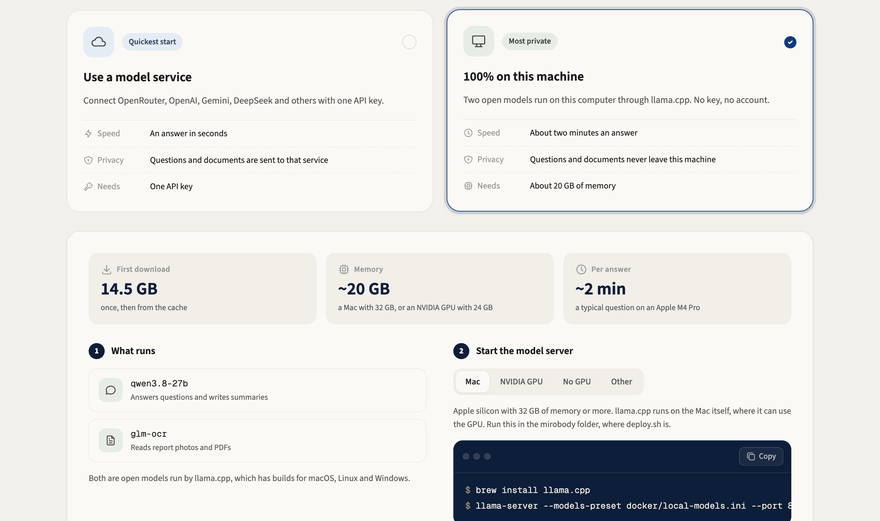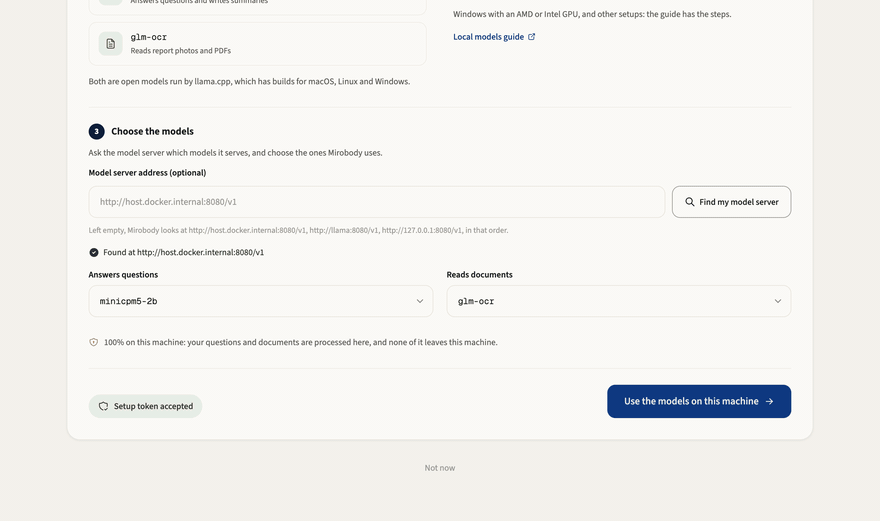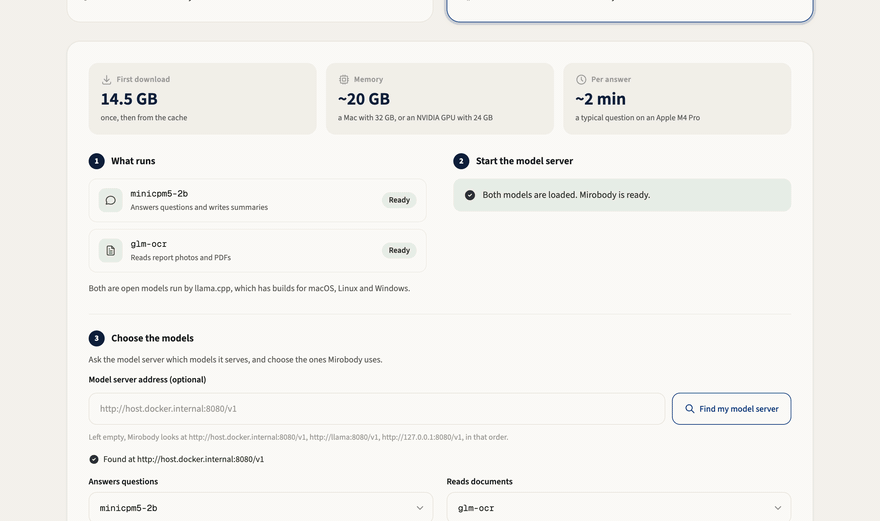
Prefer Docker with a cloud model? Run ./deploy.sh without a local model profile, then paste your own model key into the printed setup link. The app and records stay on your host; the model service processes your documents and questions.
→ Self-host guide · Walkthrough · Deploy on a server
Run without Docker
No container, and nothing pulled from a registry. On Debian or Ubuntu, PostgreSQL 16 with pgvector comes from the distribution's own packages and the app runs straight from the checkout. It is the same install the Codespaces path performs:
git clone --depth 1 https://github.com/thetahealth/mirobody.git && cd mirobody
scripts/install_native.sh   # PostgreSQL, pgvector, the Python package, a .env
scripts/start_native.sh     # the worker and the app on port 18060
Open the link it prints and sign in as you@mirobody.ai, code 111111: the demo record is seeded already. A model key from the printed setup link adds document extraction and answers. install_native.sh installs system packages with sudo and writes one sudoers rule for the postgres account, and says so as it runs.
The local models belong to the Docker path, so this one answers through a model service. Everything else matches the row above it in what stays on your machine: the records live in the PostgreSQL you just installed, and a name to a code never leaves the machine.
What you can do
- Compare reports across labs. PDFs, phone photos and spreadsheets, 23 file types in all, land in one history. Every reading links to the page it was read from.
- Bring in everyday data. Import an Apple Health export, or connect Garmin, Oura and Whoop.
- Look after your family. Invite someone who shares their own record, or keep one for a parent who never signs in.
- Write a health journal.
headache since last night, BP 150/95, no feverbecomes a coded complaint and two coded readings; "no fever" is not logged as a fever. - Explore genetic data. Upload a 23andMe, AncestryDNA or WeGene export, or a VCF, and ask by rsID, gene or region. Drug questions get CPIC coverage, never a change of medication.
- Use your own agent. Connect Claude Code, Codex or Cursor over MCP, or embed the offline engine in Python.
Collect · Translate · Agent

| Stage | What it does | Where |
|---|---|---|
| ① Collect | Files, devices and journal entries come in; the source is kept, so every reading points back to it. | collect/ |
| ② Translate | A1c, HbA1c and Glycated Hemoglobin resolve to one code, units to one standard, offline. A name it cannot place stays unresolved. | engine/ · translate/ |
| ③ Agent | Ask over the coded record: trends, comparisons across labs and devices, a chart, and the file behind every number. | agent/ |
The model reads documents and reasons; the codes and units come from vocabularies bundled with the package, never from the model. How a reading moves through the pipeline.
Care for your family
Security & health
What it can reach and how reliably it runs — from our own checks, not the maintainer’s claims.
Not checked yetNo health check has run yet.
We have not completed a health check for this listing yet.
Reviews
No reviews yet — be the first to share how it worked for you.
Frequently Asked Questions about Mirobody
We don't have a confirmed install command for mirobody yet, so we don't publish a generated one — a guessed package name would point at the wrong package or none at all. Follow the project's own README or setup instructions (https://github.com/thetahealth/mirobody) for the current steps.
Turn scattered health data into answers you can trace. Self-hosted AI health data engine for lab reports, wearables and genetics, with a built-in MCP server. Run it with Docker and one LLM key, or keep every model local on llama.cpp.
We don't have confirmed pricing for mirobody. Listing it on AllMCPs is free, but that says nothing about what the server itself costs — check the project's own site for current pricing.
Related MCP servers
Add a badge to your READMEShow it’s listed — live SVG, Markdown or HTML.
AllMCPs Directory Badge
Showcase your server listing on GitHub or your project documentation. Embed this dynamic SVG badge to highlight official listing status and live engagement.
Badge Style:
Live Dynamic SVG Preview
Markdown (GitHub README)
[](https://allmcps.com/mcp/mirobody)HTML Embed
<a href="https://allmcps.com/mcp/mirobody"><img src="https://allmcps.com/api/badge/mirobody?style=directory" alt="Mirobody on AllMCPs" /></a>