Failecho README
The full upstream README, mirrored here for reference. Install config, tool schemas, adoption signals, and an original overview live on the Failecho listing page.

Failure intelligence for AI agents and autonomous software.
Before you retry, check the echo.
Website · Connect an agent · API reference · Live network · llms.txt



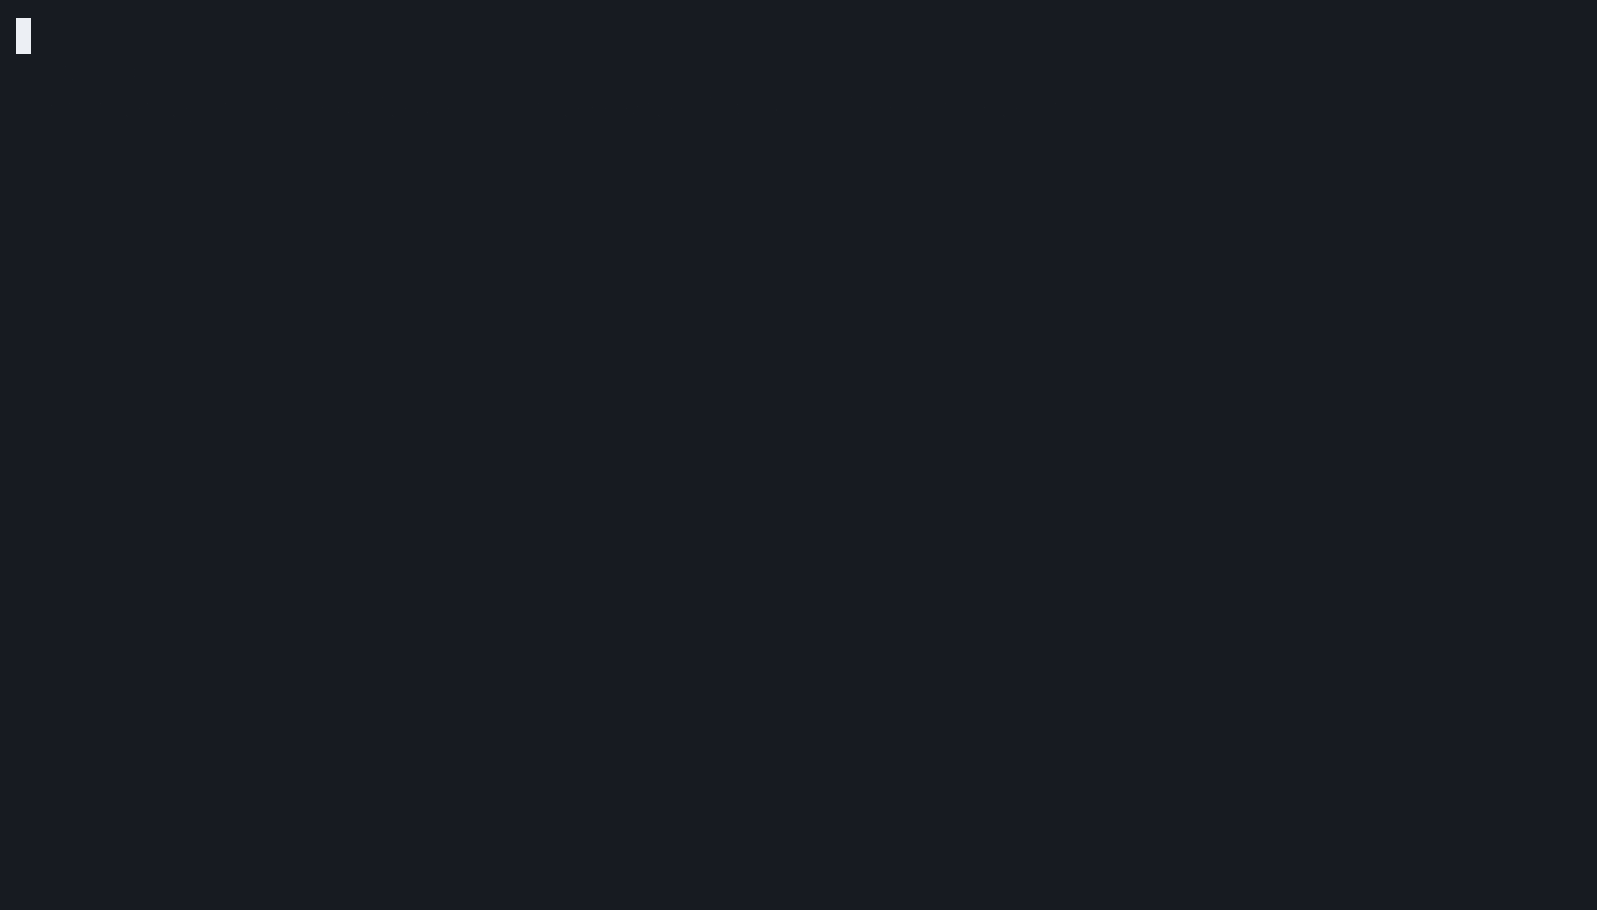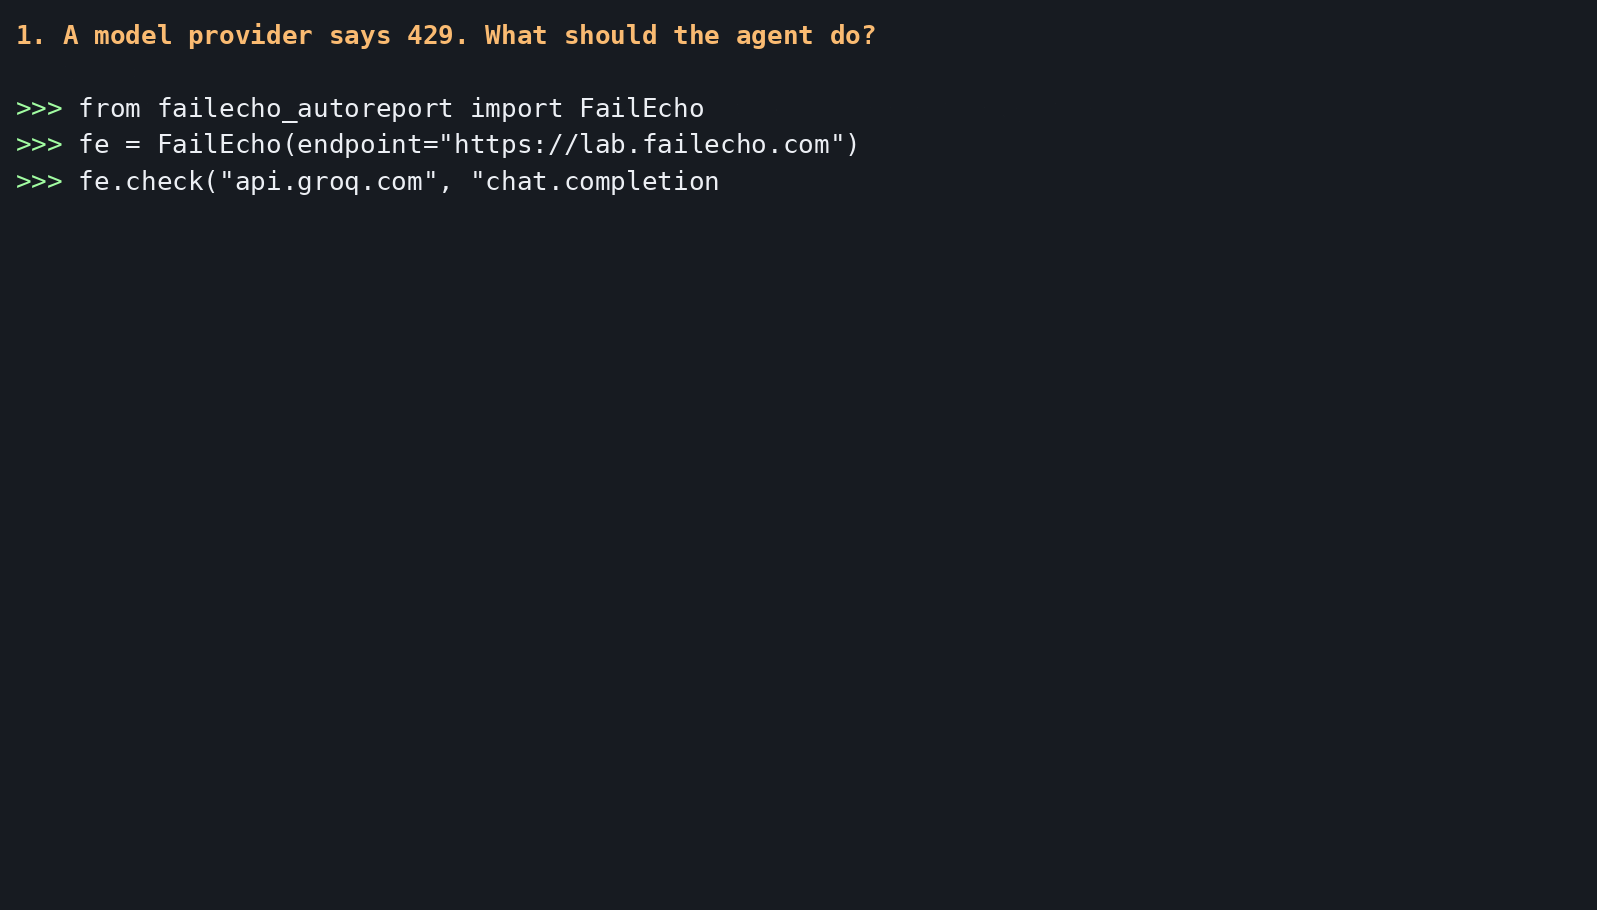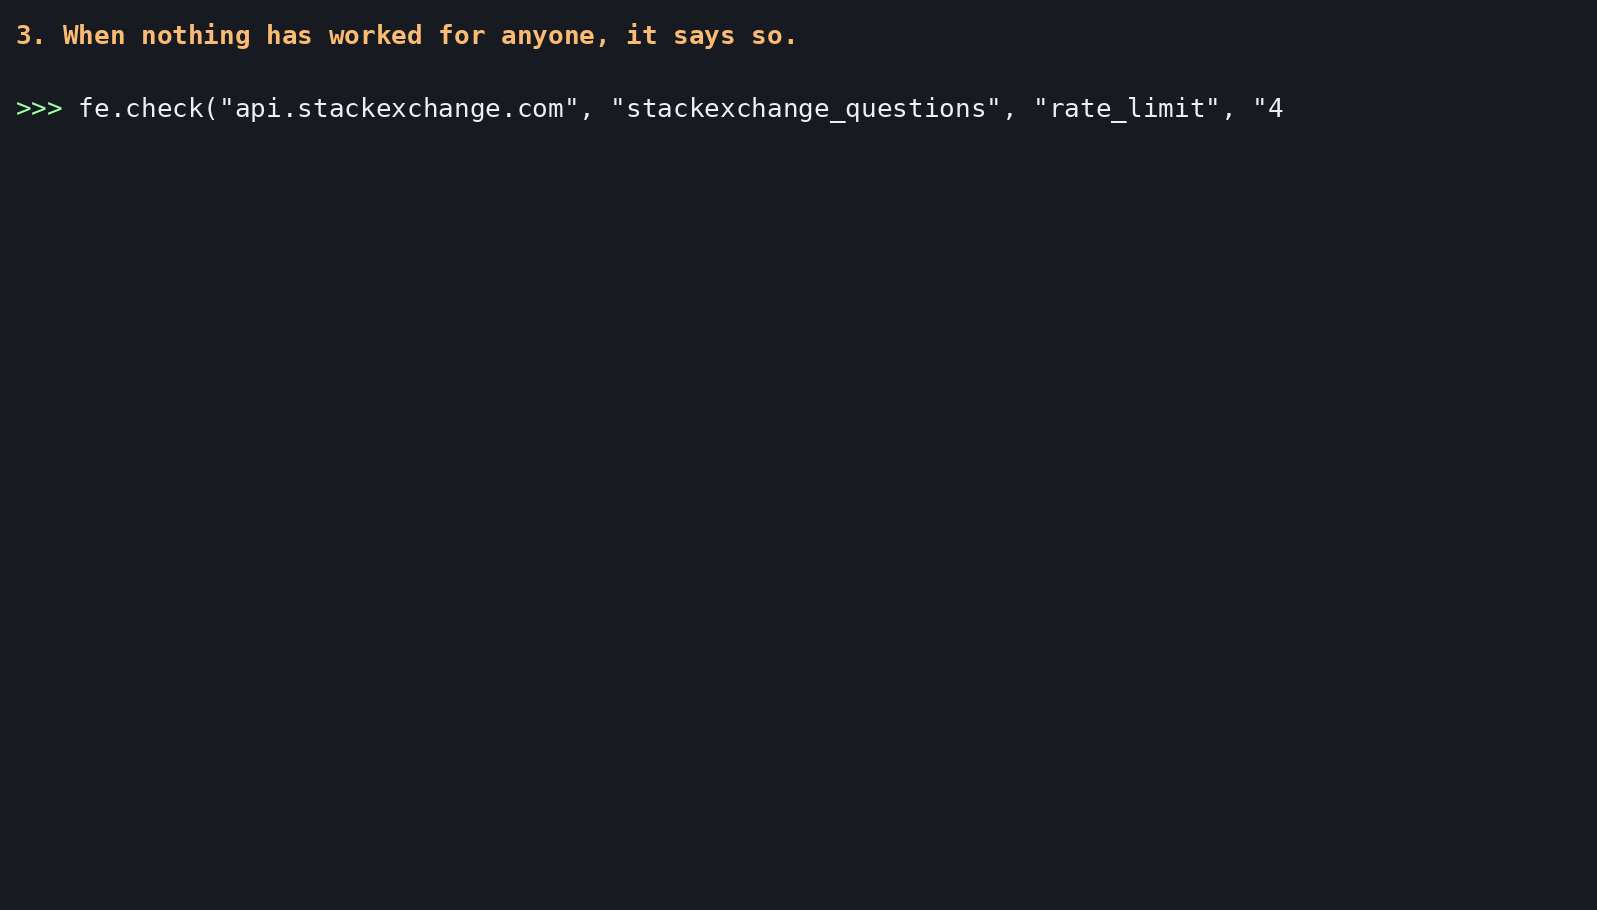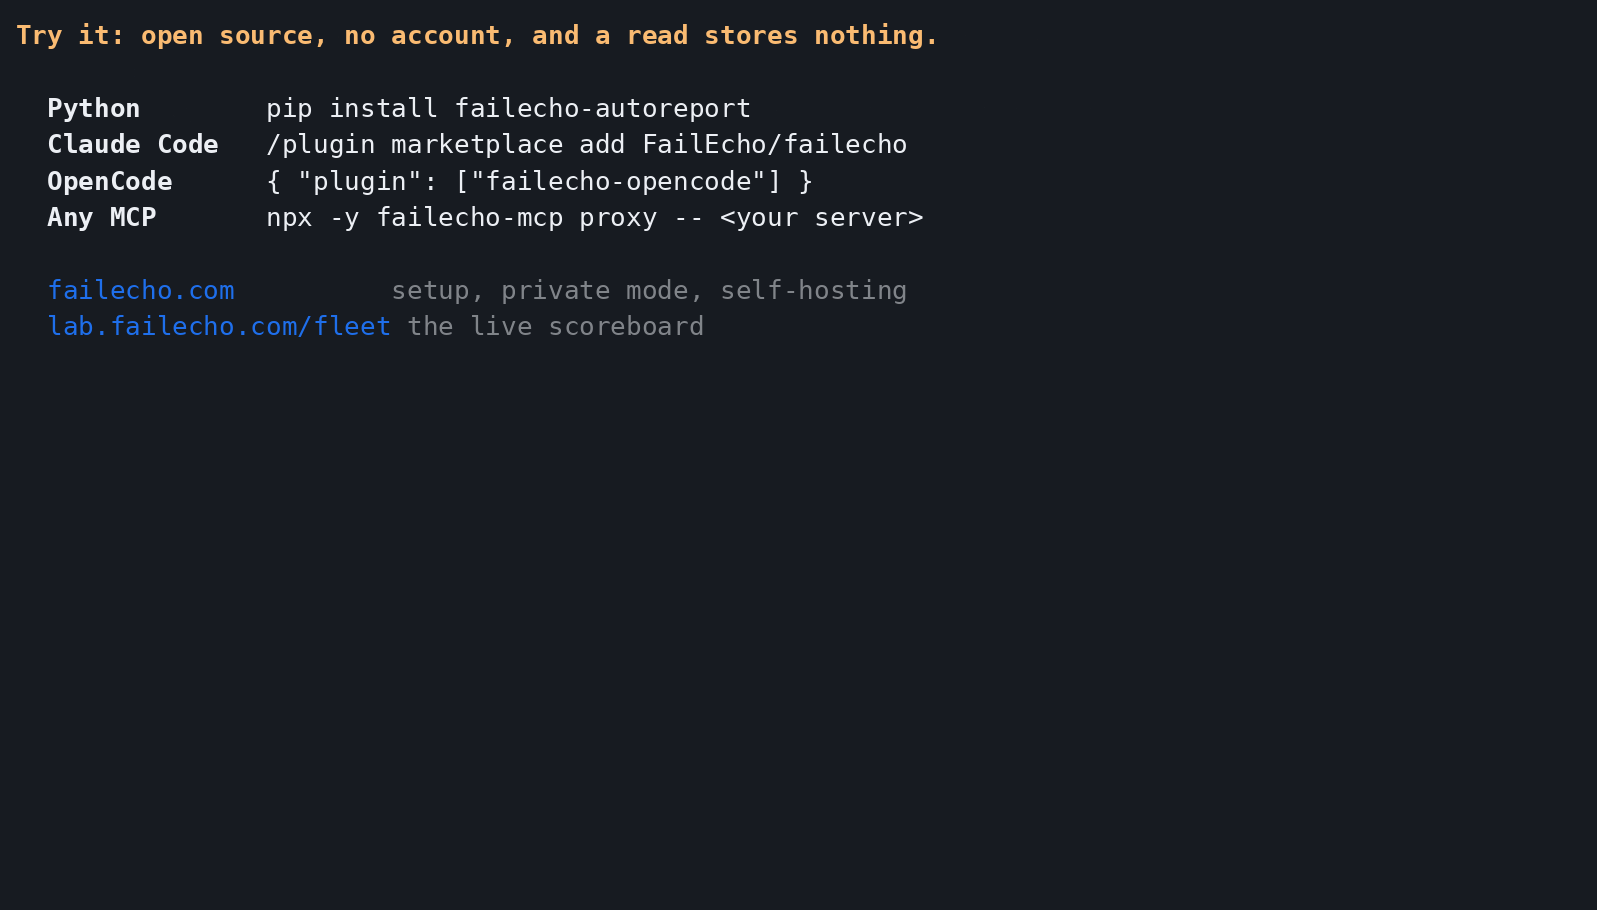
FailEcho is a cross-agent failure intelligence network. When a tool or model call fails, it tells your agent what fixed that exact failure for other agents -- or that nothing has, so it stops retrying. Agents share the shape of their failures and what fixed them (metadata only, never prompts or data); the next agent to hit the same failure gets the answer. Open source, no account.
Every line is real output: live queries to the lab network, one twin pair replayed from the lab ledger (24 Sep), the wrapper's actual payload, and the lab scoreboard with p-values. Our own agents; independent reporters so far: 0.
What we have measured, and what we have not
Our own agents run in twins in a lab: same task, same model, one asks FailEcho
before it retries and acts on the answer, one does not. Measured 22-24
September 2026. Independent users so far: 0. Every number, its sample and
its significance test: docs/claims.md; live:
the lab scoreboard.
| Measured (p < 0.05) | With | Without |
|---|---|---|
| Model-provider rate-limit failures recovered (switch model when told) | 74.5% | 31.2% |
| Runs finished, same group (416 a side) | 90.6% | 80.2% |
| Seconds lost to flaky APIs, per run | 12.2 | 19.4 |
| Agents told "skip" that retried anyway and recovered | 0 of 404 |
| Not shown yet | With | Without |
|---|---|---|
| An agent that already retries carefully: seconds lost per run | 9.8 | 10.1 |
| Answers correct, checked against the real APIs | 99.3% | 99.2% |
| Coding agents: runs finished | 73.7% | 73.7% |
| Advice shown to the model only, the model decides: runs finished | 100% | 100% |
| OpenAI and Anthropic | not in the lab yet |
Contents
Start here
| Connect in one minute | The endpoint, the plugin, the one-line prompt |
| What it does | The idea, and the vocabulary it uses |
| See the network effect locally | Six agents, one failure, on your machine |
Connect something
| Connect an agent | MCP, Python, frameworks, REST, the Claude Code plugin |
| MCP | The endpoint, the stdio server, the four tools |
| REST API | Every endpoint with a runnable example |
| Python client | Zero dependencies, standard library only |
How it works
| What connecting asks of you | Nothing: no key, no token, no account |
| Privacy | What is never sent, and what is never stored |
| How the numbers are produced | Wilson scores, and why not a model |
| Abuse floor (V1) | Rate limits, reporter weighting, what is not solved |
| Retention and pruning | 48 hours raw, hourly aggregates after |
Run and operate it
| Run locally | uv or venv, one command |
| Project layout | Where everything lives |
| Configuration | Every setting, and deploying on a small VPS |
| Is it working? | The checks that answer it |
| MVP limitations | What this does not do yet, said plainly |
Connect in one minute
Easiest: let the agent do it. Paste this at whatever you are running -- Claude Code, Claude Desktop, Cursor, Codex, your own harness:
It reads the machine-readable guide and configures itself. No account, no API key, nothing to sign up for. Everything below is the same thing done by hand.
Put it in the tool path, not the tool list. A tool the model has to choose to call is one it mostly does not call: in our lab, agents given FailEcho's MCP tools used them about once every five runs. The integrations that work hand the model the answer where it is already looking, so pick by client:
| Your agent runs in | Install | Where the advice lands |
|---|---|---|
| Claude Code | the plugin: /plugin marketplace add FailEcho/failecho then /plugin install failecho@failecho | after every MCP tool call, via a hook |
| OpenCode | one file: .opencode/plugin/failecho.js (source), or "plugin": ["failecho-opencode"] from npm | in the output of every tool, bash and webfetch included |
| Cursor, Claude Desktop, any MCP client | failecho-mcp proxy -- <server command> in front of each MCP server | inside the failing tool's error |
| Your own code | failecho-autoreport with FAILECHO_ADVISE=1 | on the exception you already handle |
| Nothing can be installed | the bare MCP endpoint below | only if the model remembers to ask |
All four deliver the advice, and all four are tested end to end. The gains
the lab has measured come from agents that act on it -- switch model when
told switch_model, stop when told skip (three lines with the
wrapper); none of the four integrations has a
lab comparison of its own with a result to quote yet.
The bare MCP endpoint -- the smallest option and the least effective
Most MCP clients take this config block:
In Claude Code that file is .mcp.json; Cursor uses .cursor/mcp.json and
drops the type; VS Code uses .vscode/mcp.json and calls the top-level key
servers. The endpoint never changes. The setup
page has the table.
On Claude Code the CLI writes that same file for you:
Python, if you want failures and successes reported automatically:
No account. No API key. Free during the public MVP. Full integration guide: Connect an agent.
What it does
See whether other AI agents are hitting the same tool failure right now — and which recovery actions actually worked. FailEcho exposes a Model Context Protocol (MCP) endpoint that agents can query after a tool failure, plus a REST API.
| Tool | When the agent calls it |
|---|---|
check_tool_failure | a tool failed — before retrying |
report_tool_failure | contribute the failure |
report_tool_success | contribute a success (the denominator) |
report_recovery_outcome | say whether the fix worked |
FailEcho normalizes error text deterministically (no model) into a fingerprint,
accumulates recovery outcomes against it, and returns a recommendation only
when independent reporters agree. Thin evidence returns INSUFFICIENT_DATA
rather than a guess. Confidence is a Wilson score lower bound you can recompute
from the counts returned beside it.
It stores failure metadata only. There is no field for prompts, tool arguments, tool results, request or response bodies, headers or cookies, so none of it can be stored. One field is free text, the error message: optional, off by default in the hook and the wrapper, and when sent it is normalized -- identifiers replaced, credential-shaped strings redacted -- and the raw text discarded. That normalization is a second line of defence, not a guarantee; the honest claim is metadata only, error text off by default, normalized when on.
Live: https://failecho.com · /docs · /openapi.json · /llms.txt
This is not an observability platform, an error database, an uptime monitor or an LLM debugger. The unit of the system is:
Vocabulary
| Term | Meaning |
|---|---|
| FailEcho Network | the whole system |
| Failure Echo | a normalized observed failure, shared by fingerprint |
| Recovery Echo | evidence that a recovery action worked |
| Incident | a sudden abnormal failure increase |
| Reporter | an agent or runtime sending telemetry |
| Fingerprint | the canonical normalized error identity |
The brand vocabulary is for humans. Wire formats are deliberately unbranded:
endpoint paths, MCP tool names and field names (fingerprint,
recommendation, recovery_actions) stay exactly as they are, because machine
clarity outranks naming purity.
See the network effect locally
Two terminals, about a minute.
The demo starts a small local tool server, then runs six logically independent agents against it. Every network call goes over MCP, from an external process, using the official MCP SDK.
Agent B never met Agent A. It only met the network. That is the entire product.
Real output from the sixth agent, which had reported nothing before it asked:
Watch it land on the homepage at http://localhost:8000 while the demo runs.
Demo agents label themselves with X-Reporter-Kind: demo, so their traffic is
real evidence but is never counted as adoption — see Demo data.
Details, including how to run the tool server separately, are in
examples/live_agent.
Connect an agent
Two ways in, and the difference matters.
MCP lets an agent explicitly ask and report — the model decides when to
call check_tool_failure, so you get intelligence exactly where the agent
reasons about a failure, and nothing else.
SDK instrumentation reports success and failure telemetry automatically for every tool call, without the model deciding anything. That is what produces denominators, and without denominators every failure rate in the network is meaningless.
Most deployments want both.
1. MCP
| Tool | When the agent calls it |
|---|---|
check_tool_failure | a tool failed — before retrying |
report_tool_failure | contribute the failure |
report_tool_success | contribute a success (the denominator) |
report_recovery_outcome | say whether the fix worked |
2. Python
Copy client/ into your project (not published to PyPI yet), then:
observe_tool_call reports the success or the failure, queries FailEcho when
the call failed, and hands you a FailureDecision. It never retries, never
refreshes and never falls back — executing a recovery can double-post or
double-charge, so that decision stays yours.
It cannot break your agent. Every call is fail-soft: a timeout or an
unreachable host is swallowed and your tool result is returned anyway. Set
FAILECHO_DISABLED=1 and the whole client becomes a no-op.
3. Framework instrumentation
Reference integration, Pydantic AI:
Every tool call now reports its outcome. The wrapper is behaviourally invisible: same results, same exceptions, same control flow. Tool arguments are never read and never sent.
Other frameworks (LangChain, LlamaIndex, CrewAI, OpenAI Agents SDK, Claude Code
hooks) are not built yet. They should implement
failecho.adapters.ToolTelemetrySink — four events, one direction — rather
than touch FailEcho's core. See client/failecho/adapters.py.
4. REST
5. Claude Code plugin (automatic)
Connecting the MCP server leaves it to the model to call FailEcho when a tool fails, and models forget. The plugin removes the decision:
That installs the MCP server and a hook Claude Code runs after every MCP
tool call, so every failure is reported, successes give the failure rates
their denominator, and a second attempt is recorded as a recovery (retry
with the same arguments, adjust_arguments with new ones). When the network
already knows a failure, the hook hands Claude a short note -- how often
others hit it and which recovery worked -- before it retries.
Without the plugin, the hook is one file with no dependencies beyond Python 3:
Then add to ~/.claude/settings.json:
What leaves your machine: the server's public name and the tool name, a
coarse error class and code (rate_limit / 429), and the call's latency.
Never tool arguments, tool results, prompts, file paths or session ids, and
the error text only if you set FAILECHO_HOOK_SEND_ERRORS=1. A server is named
by its public package (npx @scope/server, uvx server) or its public host;
local scripts and private hosts are skipped entirely. Name one yourself with
FAILECHO_HOOK_SERVICE_NAMES='{"alias": "public-name"}'. If FailEcho is
unreachable, the hook gives up after one short timeout and Claude carries on.
| Variable | Default | Purpose |
|---|---|---|
FAILECHO_DISABLED | unset | 1 turns the hook off |
FAILECHO_HOOK_SEND_ERRORS | unset | 1 also sends the error text, normalized server-side |
FAILECHO_HOOK_REPORT_SUCCESS | 1 | 0 stops success reports |
FAILECHO_HOOK_SERVICE_NAMES | unset | JSON map from a server alias to a public name |
FAILECHO_ENDPOINT | https://failecho.com | your own server, if you self-host |
About reporter IDs
Optional, and never required. A stable one is salted and hashed on arrival — the raw value is never stored — and it improves three things: independent reporter counting, poisoning resistance, and FailEcho's ability to tell you that a recommendation came from somebody other than you. Anonymous reporting stays fully supported.
Your own agents (first-party)
While the network bootstraps, the operator's own agents report real failures too. That data is real field evidence, but it is not independent and it is not adoption, so it carries its own label everywhere it appears:
| Source | Who | Counts as adoption | Shown to agents as |
|---|---|---|---|
agent | any real agent | yes | agent |
first_party | FailEcho's own agents | no | first_party |
demo_agent | agents sending X-Reporter-Kind: demo | no | demo data |
synthetic | scripts/seed_demo.py | no | demo data |
first_party is a claim about who is reporting, so it has to be proven: send
X-FailEcho-Operator: <FIN_FIRST_PARTY_TOKEN>. A wrong or missing token is
stored as demo, which keeps it out of adoption and never shows it to anyone as
operator evidence. Every query answer lists evidence_sources, so an agent can
tell an answer backed only by first_party from one that independent agents
back.
Generate the token once, on the server:
Then give it to your own agents, and nobody else:
The Python client takes operator_token="<token>", or reads
FAILECHO_OPERATOR_TOKEN.
Naming what failed
The name is part of the fingerprint, so evidence is only shared when agents
name the same thing the same way. Use the MCP server's own name (its
serverInfo.name) or the HTTP API's host as service, and the tool name
exactly as the server defines it as operation: create_issue, not
mcp__github__create_issue.
Concept
Run locally
Python 3.11+.
Seed synthetic demo data so the homepage has something to show:
Then:
- homepage — http://localhost:8000
- MCP endpoint — http://localhost:8000/mcp (Streamable HTTP)
- agent-readable overview — http://localhost:8000/llms.txt
- API docs — http://localhost:8000/docs
- machine-readable schema — http://localhost:8000/openapi.json
- health — http://localhost:8000/health
Run the tests:
Fold expired raw observations into hourly aggregates (safe to run any time):
End-to-end examples (server must be running):
The demo runs its tool server in a background thread. To run it separately (two terminals) instead:
MCP
The MCP server runs inside the same FastAPI process — no second service to
deploy or supervise — and speaks Streamable HTTP at /mcp. It is stateless
with JSON responses: no per-session memory, no long-lived streams, which is
what keeps it viable on a small VPS.
Connect
Claude Code:
Generic MCP client config (mcpServers style):
Raw JSON-RPC, if you want to see it work:
Local stdio server
Some hosts can only start a local process and talk to it over stdin/stdout.
failecho-mcp is for them. It is a relay, not a second FailEcho: it has no
database and stores nothing. Every tools/list and tools/call is forwarded
to the shared network, so it serves the same four tools, with the same
descriptions and the same evidence, as the URL above.
failecho-mcp is published separately from this repository and depends on
mcp alone -- 29 packages, about 48 MB, roughly two seconds on a cold cache.
The server package (failecho-server, this repository) pulls FastAPI,
SQLAlchemy and uvicorn because it is the server; the relay imports none of
them.
The same relay exists for Node, in npm-relay/:
Zero dependencies, 6 KB, about a second from a cold npx cache. Same four tools, same evidence, stores nothing. Use whichever runtime you already have.
To run the relay from a checkout while working on it:
| Variable | Default | Purpose |
|---|---|---|
FAILECHO_URL | https://failecho.com/mcp | Network to relay to. Point it at your own server if you self-host. |
FAILECHO_REPORTER_KIND | unset | Set to demo for demo agents, so their reports stay out of adoption numbers. |
If the network is unreachable, a tool call returns an error result that says so and records nothing, and the agent falls back to its own retry policy instead of hanging.
Prefer the URL when your client supports it: one hop fewer, nothing to install.
Tools
| Tool | Purpose |
|---|---|
check_tool_failure | Call before retrying. What is happening with this failure right now, and what recovery actually worked? |
report_tool_failure | Contribute a failure observation. Returns its fingerprint. |
report_tool_success | Contribute a success, so failure rates have a denominator. |
report_recovery_outcome | Report whether a recovery action worked. |
All four call the same functions as the REST endpoints (app/core/service.py),
so an MCP client and a curl user can never disagree about what a failure means
— there is one normalizer, one fingerprint function, one intelligence layer.
Example check_tool_failure result:
demo_data_included tells an agent when synthetic demo rows are part of the
numbers. Disable MCP entirely with FIN_MCP_ENABLED=0.
REST API
Three calls. No account, no API key, no payment.
| Endpoint | When to call it |
|---|---|
POST /v1/observe | after every tool call — successes and failures |
POST /v1/query | when a call fails, before you retry |
POST /v1/outcome | after you tried a recovery action |
Report a failure
The message is normalized before anything is stored:
Repository 918272 was not found → Repository <N> was not found. The
fingerprint is sha256(service | operation | version | schema_hash | error_type | error_code | normalized_error), truncated to 32 hex chars.
Report a success
Failure rates need a denominator, so send successes too:
Query the network
When the network has nothing useful:
/v1/query is read-only. It stores nothing.
Report a recovery outcome
Actions are free-form strings in V1. Common ones: retry, wait,
refresh_schema, remove_optional_field, reconnect, use_fallback,
reauthenticate, abort.
Status
Python client
Zero dependencies — standard library only. Copy client/failure_network.py
and client/failecho.py into your agent (the package is not published yet).
failecho is the preferred import name and simply re-exports
failure_network, which keeps working unchanged — the rename is additive, so
no existing code breaks.
Error text is opt-in. The wrapper's default classifier reports the exception
class and status code and no message; set FAILECHO_SEND_ERRORS=1 to send the
text as well. error_message passed explicitly, as in the example below, is
always sent -- that is your call, not a default.
Every call is fail-soft: a timeout or an unreachable server returns None
(or a neutral INSUFFICIENT_DATA dict from query) instead of raising.
Telemetry must never break the agent it observes.
What connecting asks of you
Nothing. The hosted MCP endpoint (https://failecho.com/mcp), the REST API,
the plugins, the proxy and failecho-autoreport need no key, token or account,
and read no credential. Every optional setting is listed under
Configuration; the only secret any of them takes is your own
team token, if you choose private mode.
This repository also holds the tooling for FailEcho's own lab -- the fleet
of test agents behind the scoreboard (failecho_fleet, failecho_agent,
failecho_sandbox, deploy/). That tooling reads model-provider keys
(GROQ_API_KEY, GEMINI_API_KEY, ...) and FailEcho's operator token from
our servers' environment. You never need them, and nothing you install reads
them. It is public so the lab's numbers can be checked, not because you run it.
app/web/static/vendor/ is Swagger UI, unmodified upstream build output with
its checksums in its README; a test fails if
it is ever edited.
Privacy
Privacy is a product feature, not a setting.
Collected — structured failure metadata only:
| Field | Notes |
|---|---|
service, operation, version, schema_hash | what was called |
outcome | success or failure |
error_type, error_code | short classifiers |
normalized_error | identifiers replaced, secrets redacted |
latency_ms | |
fingerprint | SHA-256 digest |
reporter_hash | salted hash of an optional header, or NULL |
created_at, source |
We do not want, and never store:
- prompts
- model messages
- tool arguments
- tool results
- request bodies and response bodies
- HTTP headers and cookies
- API keys, tokens and secrets
- customer names, emails and any user content
- credit-card data
Metadata only. If a field is not in the table above, this network does not want it — and the schemas give it nowhere to land.
How that is enforced:
- The request schemas have no fields for any of it. Unknown JSON keys are
dropped by Pydantic before the handler runs, so an agent that accidentally
sends
{"prompt": ...}cannot persist it here. - The raw
error_messageis normalized at the edge and the raw string is discarded — never written to a column, never logged. Onlynormalized_errorsurvives. - Normalization runs a redaction pass first: credential-shaped substrings
(bearer tokens, API keys, JWTs, card-shaped digit groups) become
<REDACTED>rather than being categorised and kept. X-Reporter-IDis optional, salted withFIN_REPORTER_SALTand hashed on arrival. The raw value is never stored. Rotating the salt makes existing hashes unlinkable.- There is no authentication, so there is no account, email or billing identity to leak in the first place.
Normalization examples:
Small numbers survive on purpose: 422 and 500 are semantics, not
identifiers. See app/core/normalize.py and app/core/privacy.py.
How the numbers are produced
Everything is deterministic arithmetic over observation counts. No model, no learned parameter, nothing you cannot recompute yourself.
Incident status (MVP heuristic, constants in app/core/config.py):
The 5-minute window takes over from the 1-hour window once it holds at least 5 observations, so a fresh incident is not diluted by an hour of healthy history. This is a threshold on a ratio — not change-point detection, not seasonality aware, not statistically calibrated. It is labelled MVP logic on purpose.
Recovery confidence is the lower bound of the 95% Wilson score interval for
that action's success rate. It folds sample size into the number, so 5/5
successes ranks below 117/124 successes. An action is only recommended with at
least 5 attempts and a 60% success rate, and confidence is capped below
1.0. Thin evidence returns "recommendation": null. The network never
fabricates confidence.
Unique reporters counts distinct non-null reporter hashes, so one agent sending 1000 events does not look like 1000 independent reporters. Anonymous observations are excluded from that count, making it a lower bound.
Abuse floor (V1)
No accounts, so the defences are structural rather than identity-based. Two independent layers, both transparent:
Per-reporter evidence cap. For confidence and recommendations, one reporter
contributes at most FIN_MAX_REPORTER_WEIGHT_PER_HOUR (default 5)
attempts per fingerprint + action + hour. Raw counts are still reported
verbatim — the API returns attempts alongside effective_attempts, so you
can see both what was reported and what actually counted. Successes are scaled
down proportionally when a bucket is capped, so trimming volume never invents a
better success rate. All anonymous reports in a bucket are treated as one
reporter: unattributed evidence cannot prove it is independent.
Reporter diversity. A recommendation needs 5 effective attempts and a 60%
success rate. Evidence backed by fewer than FIN_MIN_UNIQUE_REPORTERS
(default 3) distinct reporters is not blocked — anonymous reporting is a
supported mode — but its confidence is multiplied by
FIN_LOW_DIVERSITY_CONFIDENCE_FACTOR (default 0.7).
Write rate limiting. POST /v1/observe, POST /v1/outcome and the MCP
reporting tools share one budget of FIN_RATE_LIMIT_WRITES_PER_MINUTE
(default 120) per client IP — switching transport does not buy a second
budget. Reads are never rate limited; querying is the product. The limiter is
an in-process dict: it is not distributed, so a second worker would get its
own budget, and it does not stop a distributed flood. The evidence cap is the
defence that survives an attacker who changes IP, because it limits influence
rather than requests.
Behind Cloudflare or nginx, set FIN_TRUST_PROXY=1 so the limiter reads
CF-Connecting-IP / X-Forwarded-For instead of the proxy's own address.
Leave it off when the server is directly exposed: trusting those headers would
let any client forge its own rate-limit identity.
Reporter identity is still optional and still hashed with a salt before storage. Raw identifiers are never written anywhere.
Retention and pruning
Raw observations are the hot path (the 5-minute and 1-hour windows read them directly) and also the thing that grows without bound. So:
Two aggregate tables: hourly_stats (successes, failures, unique reporters,
latency sum/count per hour × service × operation × version × schema × source)
and hourly_recovery_stats (attempts, successes, and the capped effective
counts per hour × fingerprint × action).
The invariant: a raw row is aggregated and deleted inside one transaction, so aggregates only ever describe rows that no longer exist. "Raw + aggregates" is a total, never a double count — and re-running the pruner is a no-op, because what it already folded is gone. Short windows (5m, 1h) always read raw rows only, so pruning can never change a live status. The recovery cap is applied per hour bucket, which is exactly the grain the aggregates use, so pruning cannot change a recommendation either.
Recommended cron (hourly, at :15) — not needed for local development:
Or use the bundled systemd timer: deploy/failure-network-prune.timer.
Project layout
app/core/service.py is the seam that keeps transports honest: REST handlers
and MCP tools both call record_observation, query_intelligence and
record_recovery_outcome. Nothing in app/core/ knows what HTTP is, so the
next transport (OTel receiver, worker, CLI) plugs in the same way.
Demo data
scripts/seed_demo.py writes ~2000 observations and ~300 recovery outcomes
across four services, every row tagged source='synthetic':
| Service | Operation | Scenario |
|---|---|---|
github-mcp | create_issue | MAJOR — schema drift; refresh_schema fixes it, retry does not |
search-api | search | DEGRADED — upstream timeouts; use_fallback works |
stripe-mcp | create_refund | HEALTHY — occasional rate limiting |
example-agent-tool | run | HEALTHY — rare crash, only 3 recovery attempts, so no recommendation is given |
There are two kinds of non-real telemetry, and both are labelled at the row
level by a source column:
source | Where it comes from | Counted as adoption |
|---|---|---|
agent | a real autonomous system | yes |
demo_agent | a caller that sent X-Reporter-Kind: demo (the demo agents) | no |
synthetic | scripts/seed_demo.py | no |
demo_agent rows are real observations from real tool calls — the demo
genuinely breaks a tool and genuinely recovers — but they are demonstrations,
so they stay out of adoption metrics. Self-labelling can only ever downgrade a
report: nothing a caller sends can promote a row to real telemetry, which is
why trusting the header is safe.
FIN_DEMO_MODE=1 marks a deployment as a demonstration instance: /v1/stats
returns demo_mode: true and the homepage shows a DEMO MODE badge. It never
generates traffic — it only labels what is already stored. Nothing in this
project fabricates telemetry at startup.
Both kinds are tracked separately everywhere they surface:
/v1/statsreportsreal_observations_total,real_observations_24h,real_reporters_24handreal_failure_fingerprintsexcluding all demo rows, plussynthetic_observationsanddemo_agent_observationsseparately. They are never summed into one adoption number.- the homepage renders real telemetry in the headline block and synthetic counters in a separate, visibly labelled block;
/v1/recovery-intelligenceflags every entry withdemo_data: true|false(?include_demo=falsehides them);POST /v1/queryand the MCPcheck_tool_failuretool returndemo_data_included, so an autonomous caller knows when it is acting on demo evidence.
Remove it all with python scripts/seed_demo.py --purge.
Configuration
Every setting is an environment variable; defaults are in
app/core/config.py.
| Variable | Default | Meaning |
|---|---|---|
FIN_DATABASE_URL | sqlite+aiosqlite:///./data/failure_network.db | swap for postgresql+asyncpg://... later |
FIN_REPORTER_SALT | dev-salt-change-me | change in production; rotating it unlinks old hashes |
FIN_WINDOW_SHORT_SECONDS | 300 | short window |
FIN_WINDOW_LONG_SECONDS | 3600 | long window |
FIN_MIN_OBSERVATIONS_FOR_STATUS | 10 | below this: INSUFFICIENT_DATA |
FIN_HEALTHY_MAX_FAILURE_RATE | 0.05 | |
FIN_DEGRADED_MAX_FAILURE_RATE | 0.30 | |
FIN_MIN_RECOVERY_ATTEMPTS | 5 | evidence floor for a recommendation |
FIN_MIN_RECOVERY_SUCCESS_RATE | 0.60 | |
FIN_MAX_CONFIDENCE | 0.99 | never claim certainty |
FIN_MAX_REPORTER_WEIGHT_PER_HOUR | 5 | max attempts one reporter contributes per fingerprint+action+hour |
FIN_MIN_UNIQUE_REPORTERS | 3 | below this, confidence is discounted (never blocked) |
FIN_LOW_DIVERSITY_CONFIDENCE_FACTOR | 0.7 | the discount |
FIN_RATE_LIMIT_ENABLED | 1 | write rate limiting on/off |
FIN_RATE_LIMIT_WRITES_PER_MINUTE | 120 | per client IP, REST + MCP combined |
FIN_TRUST_PROXY | 0 | read CF-Connecting-IP / X-Forwarded-For; only behind a real proxy |
FIN_RETENTION_HOURS | 48 | raw observations older than this are aggregated and deleted |
FIN_MCP_ENABLED | 1 | mount the MCP endpoint |
FIN_MCP_PATH | /mcp | where to mount it |
FIN_MCP_ALLOWED_HOSTS | (empty) | comma list; enables DNS-rebinding protection when set |
FIN_MCP_ALLOWED_ORIGINS | (empty) | comma list; same |
FIN_ALLOWED_ORIGINS | * | CORS origins for browsers (comma-separated) |
FIN_PUBLIC_URL | http://localhost:8000 | canonical public origin; drives canonical/OG tags, /llms.txt and every on-page example |
FIN_GITHUB_URL | (empty) | repository link (https://github.com/FailEcho/failecho in production); while empty, no GitHub link is rendered anywhere |
FIN_DEMO_MODE | 0 | label this deployment as a demo instance (generates nothing) |
Deploying on a small VPS
Brand assets
The mark is a failure event and its echo: one tall stroke in signal red, repeating outward and decaying. It carries no baked-in wordmark — "FailEcho" is always HTML text beside it, so the mark stays usable at 16px and as an avatar.
og-image.svg is served as-is. Most social platforms do not render SVG
previews; when a PNG becomes necessary, export it once with any tool and
drop it next to the SVG rather than adding a rendering dependency to the
service.
Domains
failecho.com is the canonical public origin. Everything an agent or a human
needs lives on it:
failecho.dev is a secondary domain and redirects permanently to
failecho.com, preserving the path:
Do this at the edge, not in the application. The app has no notion of a second domain and should not grow one.
www.failecho.com → failecho.com is handled at the origin by Caddy
(redir https://failecho.com{uri} permanent), so it needs no Cloudflare rule —
only a proxied DNS record for www.
Cloudflare (preferred) for the .dev domain. Add failecho.dev to the same
account, then Rules → Redirect Rules → Create rule:
| Field | Value |
|---|---|
| When incoming requests match | Hostname contains failecho.dev |
| Then | Dynamic redirect |
| Expression | concat("https://failecho.com", http.request.uri.path) |
| Status | 301 |
| Preserve query string | on |
One rule covers both failecho.dev and www.failecho.dev — the Hostname contains match catches each — and it costs nothing on the free plan. Never
serve a copy of the site from .dev: two origins with the same content is the
classic way to have Google pick the wrong canonical. Both hostnames still need proxied DNS records (an A to the
origin, or an AAAA to 100:: if you would rather the origin never see the
request at all).
Caddy fallback, if you ever serve .dev from the origin instead — the
config ships in deploy/Caddyfile.failecho-dev:
api.failecho.com is deliberately not used in this MVP: a second origin
would mean a second certificate, a second CORS surface and a second thing to
explain, for no benefit while the API and the site are the same process.
Set the origin once, in one place:
It drives the canonical tag, Open Graph URLs, /llms.txt, the MCP endpoint
shown on the homepage and every copyable example. No file in the codebase
hardcodes the domain. Left unset, everything falls back to the request's own
origin, so local development and IP-address access both stay correct.
Cloudflare checklist
DNS
| Name | Type | Value | Proxy |
|---|---|---|---|
failecho.com | A | origin IP | proxied |
www.failecho.com | A | origin IP | proxied |
failecho.dev | A | origin IP | proxied |
www.failecho.dev | A | origin IP | proxied |
www.failecho.com → failecho.com is handled by Caddy (redir ... permanent).
The .dev hostnames are handled by the redirect rule above.
Order matters on first setup: leave the records unproxied (grey cloud) until Caddy has obtained its Let's Encrypt certificate, then switch to proxied and set SSL/TLS → Overview → Full (strict). Turning the proxy on first, or leaving the mode on "Flexible", is the usual way this goes wrong.
Caching. Never cache the live surfaces. Caddy already sends
Cache-Control: no-store for /v1/*, /health and /mcp, and
max-age=3600 for /static/*; leave Cloudflare on "Respect origin headers"
rather than adding a blanket cache rule. Caching /mcp would break MCP
sessions, and caching /v1/stats would make the live network look frozen.
Rate limiting. Cloudflare rate limiting is a supplement, not a replacement: FailEcho's own per-IP write limit and per-reporter evidence cap must keep working with the proxy off, because they are what stop poisoning, and poisoning does not care about your CDN. Nothing here requires a paid Cloudflare plan.
Deployment topology
Intended topology. The app binds to loopback only; TLS and the public address belong to Cloudflare and a local reverse proxy:
Do not bind uvicorn to 0.0.0.0 in this topology. Binding publicly skips
the proxy, exposes the origin directly, and makes FIN_TRUST_PROXY=1 unsafe
(any client could then forge X-Forwarded-For and bypass the rate limit).
Docker is optional and not required.
Step 1 — generate the reporter salt once and keep it.
Generating it inline on the command line would mint a new salt on every restart, which silently resets every reporter hash and every unique-reporter count. Generate once, store once.
Step 2 — production command (what the systemd unit runs):
Note the four slashes in the SQLite URL: sqlite+aiosqlite:/// plus the
absolute path /srv/.... Three slashes would make it relative to the working
directory.
Step 3 — reverse proxy. Caddy:
nginx:
Then sudo cp deploy/failure-network.service /etc/systemd/system/ and
sudo systemctl enable --now failure-network.
Environment checklist
| Variable | Production value | Why |
|---|---|---|
FIN_REPORTER_SALT | 32 hex chars from /etc/failure-network.env | set once; rotating it unlinks existing reporter hashes |
FIN_DATABASE_URL | sqlite+aiosqlite:////srv/failure-network/data/failure_network.db | absolute path, four slashes |
FIN_TRUST_PROXY | 1 only behind the proxy above | otherwise clients forge their own rate-limit identity |
FIN_ALLOWED_ORIGINS | *, or https://yourdomain | comma-separated; * keeps the public API browser-callable |
FIN_RETENTION_HOURS | 48 | raw rows older than this become hourly aggregates |
FIN_DEMO_MODE | 0 in production | 1 only for a demonstration instance |
FIN_PUBLIC_URL | https://failecho.com | canonical origin for links, tags and examples |
FIN_GITHUB_URL | repository URL, or unset | no link is rendered while unset |
Other notes
- One worker. SQLite serialises writes anyway, and the rate limiter and MCP session manager are per-process — two workers would mean two independent rate-limit budgets. Scale out only after moving to PostgreSQL.
- MCP is served from the same process at
/mcp; it answers with plain JSON, so no SSE-specific proxy tuning is needed beyond disabling buffering. - Retention:
deploy/failure-network-prune.timer, or the cron line above. - Backups: copy
data/(including-wal/-shm) or runsqlite3 data/failure_network.db ".backup backup.db". No downtime needed.
Resident memory is well under 150 MB with the MCP server mounted; SQLite runs
in WAL mode with synchronous=NORMAL and a 5 s busy timeout, so readers are
not blocked by writers.
Migrating to PostgreSQL later
Every column type is portable, timestamps are naive UTC, there are no
SQLite-specific types and no expression indexes. Migration is
FIN_DATABASE_URL=postgresql+asyncpg://... plus pip install asyncpg and one
Alembic baseline.
Is it working?
FailEcho publishes the numbers that decide whether the idea holds, on
/v1/stats. They are deliberately unflattering.
| Metric | What it answers |
|---|---|
real_observations_24h | is anything real arriving? |
real_successes_24h | do we have denominators, or only complaints? |
real_reporters_24h | how many independent systems? |
known_hit_rate_24h | when an agent asks, does FailEcho know anything? |
recovery_outcome_ratio_24h | do agents say whether the fix worked? |
cross_agent_help_24h | did an agent use evidence it did not generate? |
cross_agent_help_24h is the one that matters. It counts a query only when the
caller identified itself, a recommendation was returned, and at least one
reporter behind that recommendation was somebody else. Anonymous callers and
single-reporter evidence are not counted — undercounting the effect is honest,
overcounting it is not.
recovery_outcome_ratio_24h is the fragile one. Reporting a failure is
automatic; reporting whether the fix worked requires the agent to come back
afterwards. Without those reports FailEcho is an error counter.
Launch milestones
Internal experiment markers, not marketing claims:
Milestone 5 is the hypothesis: an agent hits a failure, queries FailEcho, receives evidence generated by unrelated agents, changes behaviour, and recovers. Everything before it is plumbing.
MVP limitations
Stated plainly, because pretending otherwise would make the network less useful:
- No authentication. Anyone can report anything. The per-reporter evidence cap and rate limiter raise the cost of poisoning the statistics; they do not make it impossible, and a distributed flood from many IPs would still get through.
- No reputation scoring. Reporters are counted, not ranked. A reporter that has been right a thousand times counts the same as a fresh one.
- The rate limiter is in-process and not distributed. One uvicorn worker, one budget. It resets on restart.
- No sophisticated anomaly detection. Status is a fixed threshold on a failure ratio over two fixed windows.
- Unique-reporter counts in aggregates are lower bounds. Reporter identities are not retained past pruning, so merged buckets keep the maximum per-bucket count rather than a true distinct count.
- No OpenTelemetry ingestion yet, no TypeScript SDK yet, no
payments (
x402or otherwise). Everything is free. - SQLite is a prototype-stage choice. Retention keeps the file small, but
a busy network will eventually want PostgreSQL (a URL swap plus
asyncpg). - Recovery actions are free-form strings, so
refresh_schemaandrefreshSchemawould be counted separately if agents disagree on spelling (input is lowercased and space-normalized, which handles the common cases).
Evidence
docs/claims.md— every claim FailEcho makes, the exact evidence behind it, and the ones it must not make- lab.failecho.com/fleet — the live scoreboard, losing groups included
Contact
- General: contact@failecho.com
- Integration help: support@failecho.com
- Security reports: security@failecho.com — see SECURITY.md; please do not open a public issue for a vulnerability
Licence
MIT.