Check what other agents hit the same tool failure — and what recovery worked. Ask before retrying.
Quick Install
Automated & IDE SetupCopy the AI prompt to install this server into Claude Code, Cursor, or another agent — or use 1-click editor setup below.
One-click editor setup isn’t available for this listing yet — we don’t have a confirmed install command, and we’d rather show nothing than point your editor at the wrong package or host. Follow the project’s own setup instructions, linked above.
Manual Client & Custom JSON ConfigExpand JSON ▾
No confirmed setup config for this listing yet. We only publish a config block when the install details come from the project itself — its README, its docs, or a verified owner. We haven’t found those for failecho, and we’d rather show nothing than a guess you’d paste into your client. Follow the project’s own setup instructions for the current steps.
Documentation Overview

Failure intelligence for AI agents and autonomous software.
Before you retry, check the echo.
Website · Connect an agent · API reference · Live network · llms.txt



FailEcho is a cross-agent failure intelligence network. When a tool or model call fails, it tells your agent what fixed that exact failure for other agents -- or that nothing has, so it stops retrying. Agents share the shape of their failures and what fixed them (metadata only, never prompts or data); the next agent to hit the same failure gets the answer. Open source, no account.
Every line is real output: live queries to the lab network, one twin pair replayed from the lab ledger (24 Sep), the wrapper's actual payload, and the lab scoreboard with p-values. Our own agents; independent reporters so far: 0.
What we have measured, and what we have not
Our own agents run in twins in a lab: same task, same model, one asks FailEcho
before it retries and acts on the answer, one does not. Measured 22-24
September 2026. Independent users so far: 0. Every number, its sample and
its significance test: docs/claims.md; live:
the lab scoreboard.
| Measured (p < 0.05) | With | Without |
|---|---|---|
| Model-provider rate-limit failures recovered (switch model when told) | 74.5% | 31.2% |
| Runs finished, same group (416 a side) | 90.6% | 80.2% |
| Seconds lost to flaky APIs, per run | 12.2 | 19.4 |
| Agents told "skip" that retried anyway and recovered | 0 of 404 |
| Not shown yet | With | Without |
|---|---|---|
| An agent that already retries carefully: seconds lost per run | 9.8 | 10.1 |
| Answers correct, checked against the real APIs | 99.3% | 99.2% |
| Coding agents: runs finished | 73.7% | 73.7% |
| Advice shown to the model only, the model decides: runs finished | 100% | 100% |
| OpenAI and Anthropic | not in the lab yet |
Contents
Start here
| Connect in one minute | The endpoint, the plugin, the one-line prompt |
| What it does | The idea, and the vocabulary it uses |
| See the network effect locally | Six agents, one failure, on your machine |
Connect something
| Connect an agent | MCP, Python, frameworks, REST, the Claude Code plugin |
| MCP | The endpoint, the stdio server, the four tools |
| REST API | Every endpoint with a runnable example |
| Python client | Zero dependencies, standard library only |
How it works
| What connecting asks of you | Nothing: no key, no token, no account |
| Privacy | What is never sent, and what is never stored |
| How the numbers are produced | Wilson scores, and why not a model |
| Abuse floor (V1) | Rate limits, reporter weighting, what is not solved |
| Retention and pruning | 48 hours raw, hourly aggregates after |
Run and operate it
| Run locally | uv or venv, one command |
| Project layout | Where everything lives |
| Configuration | Every setting, and deploying on a small VPS |
| Is it working? | The checks that answer it |
| MVP limitations | What this does not do yet, said plainly |
Connect in one minute
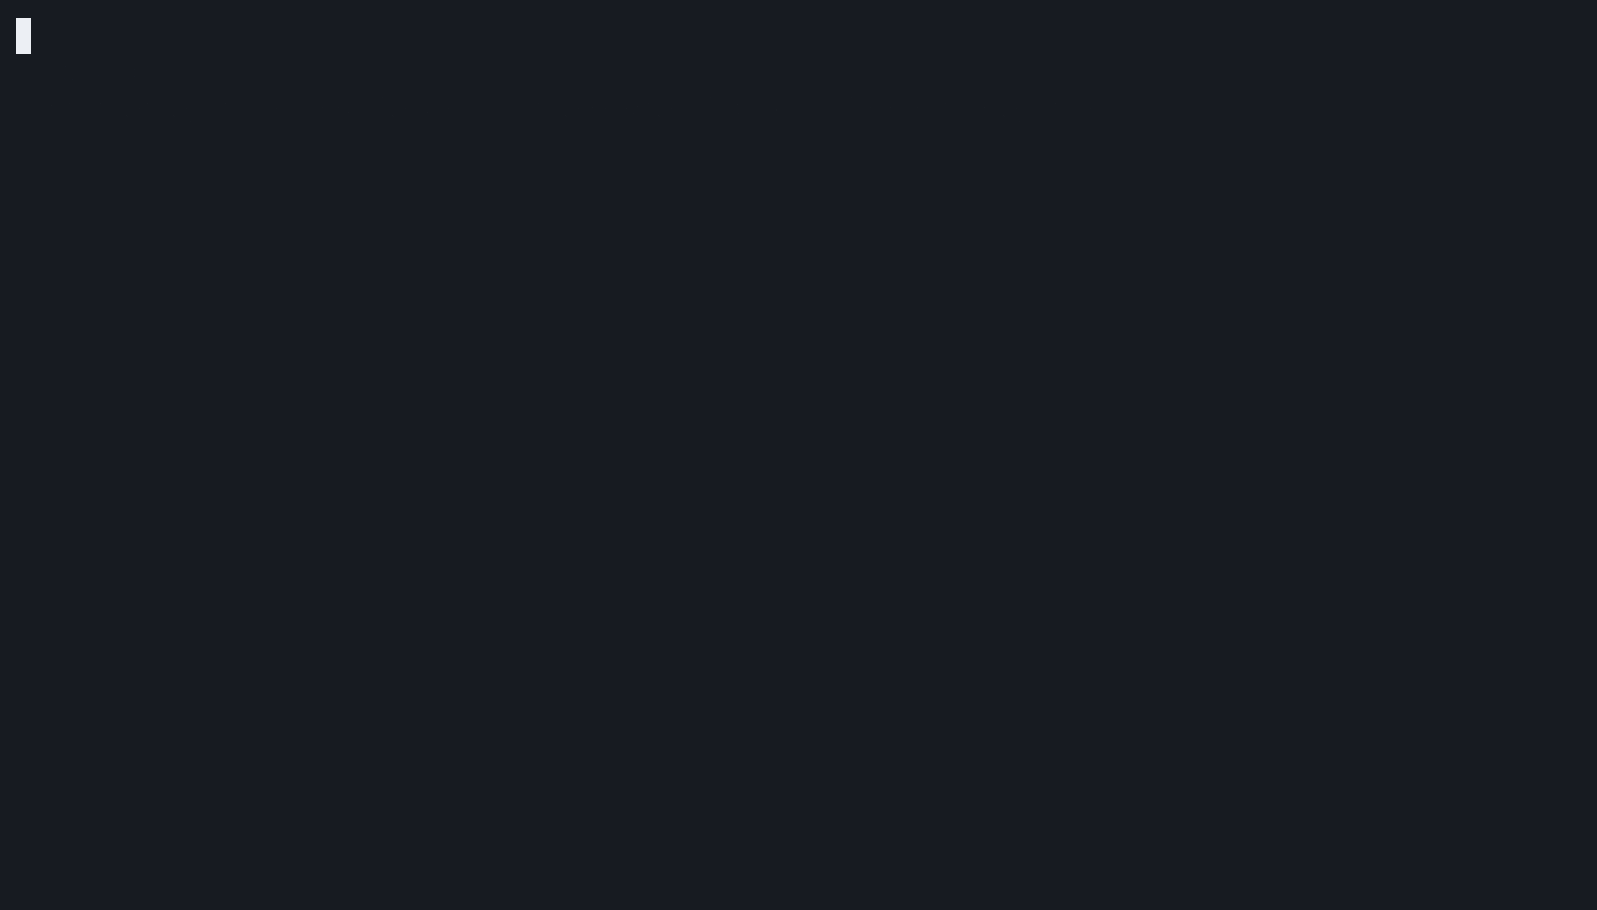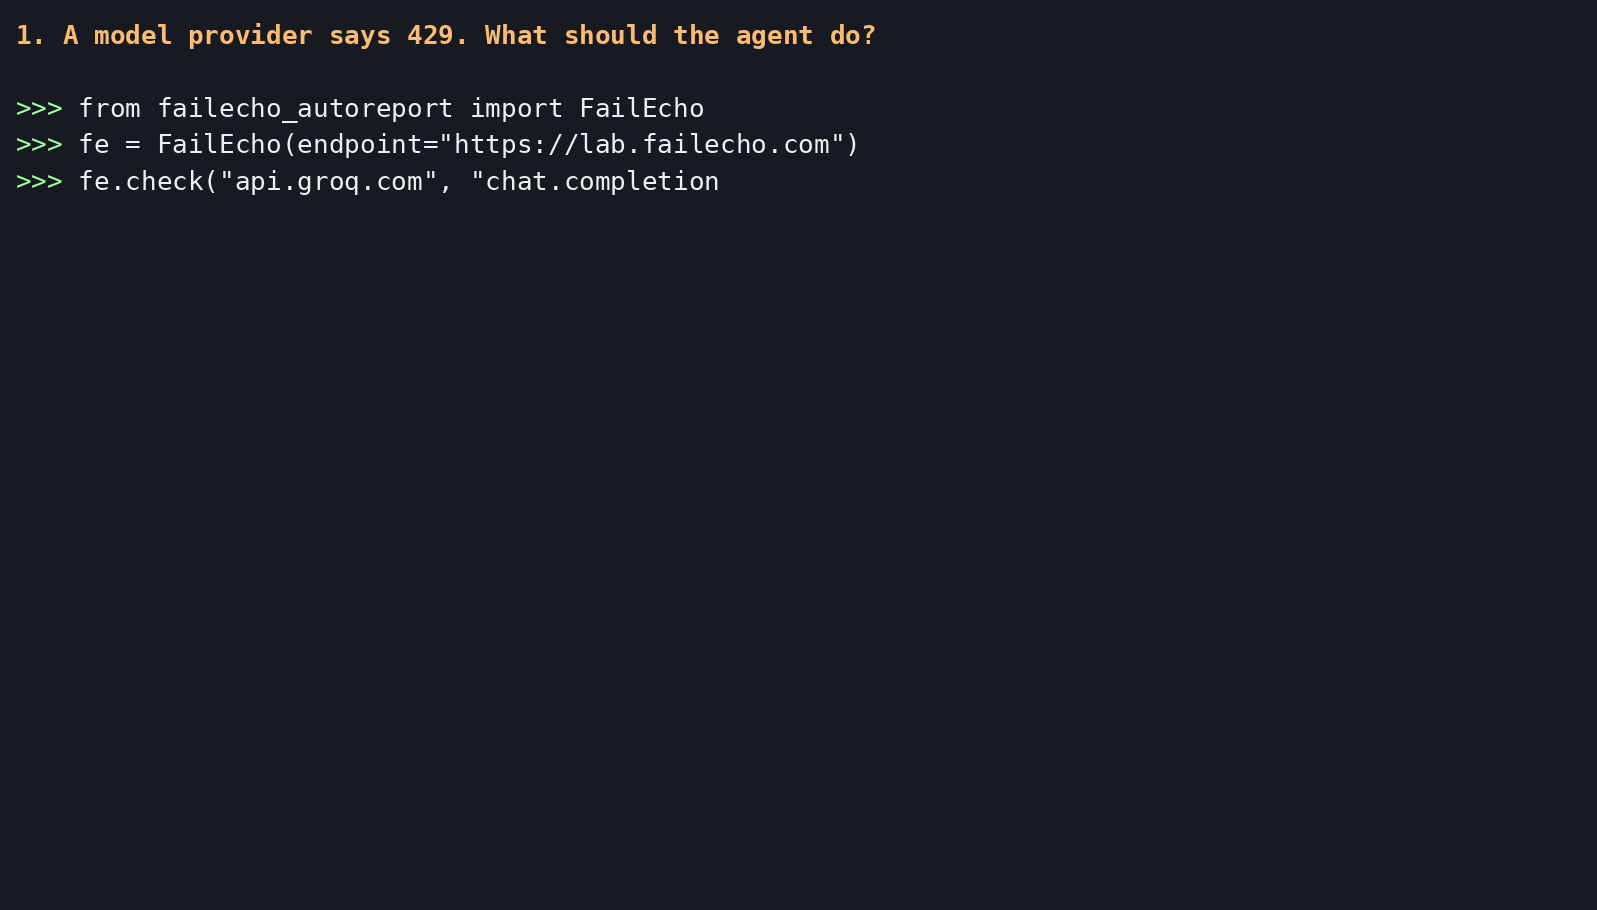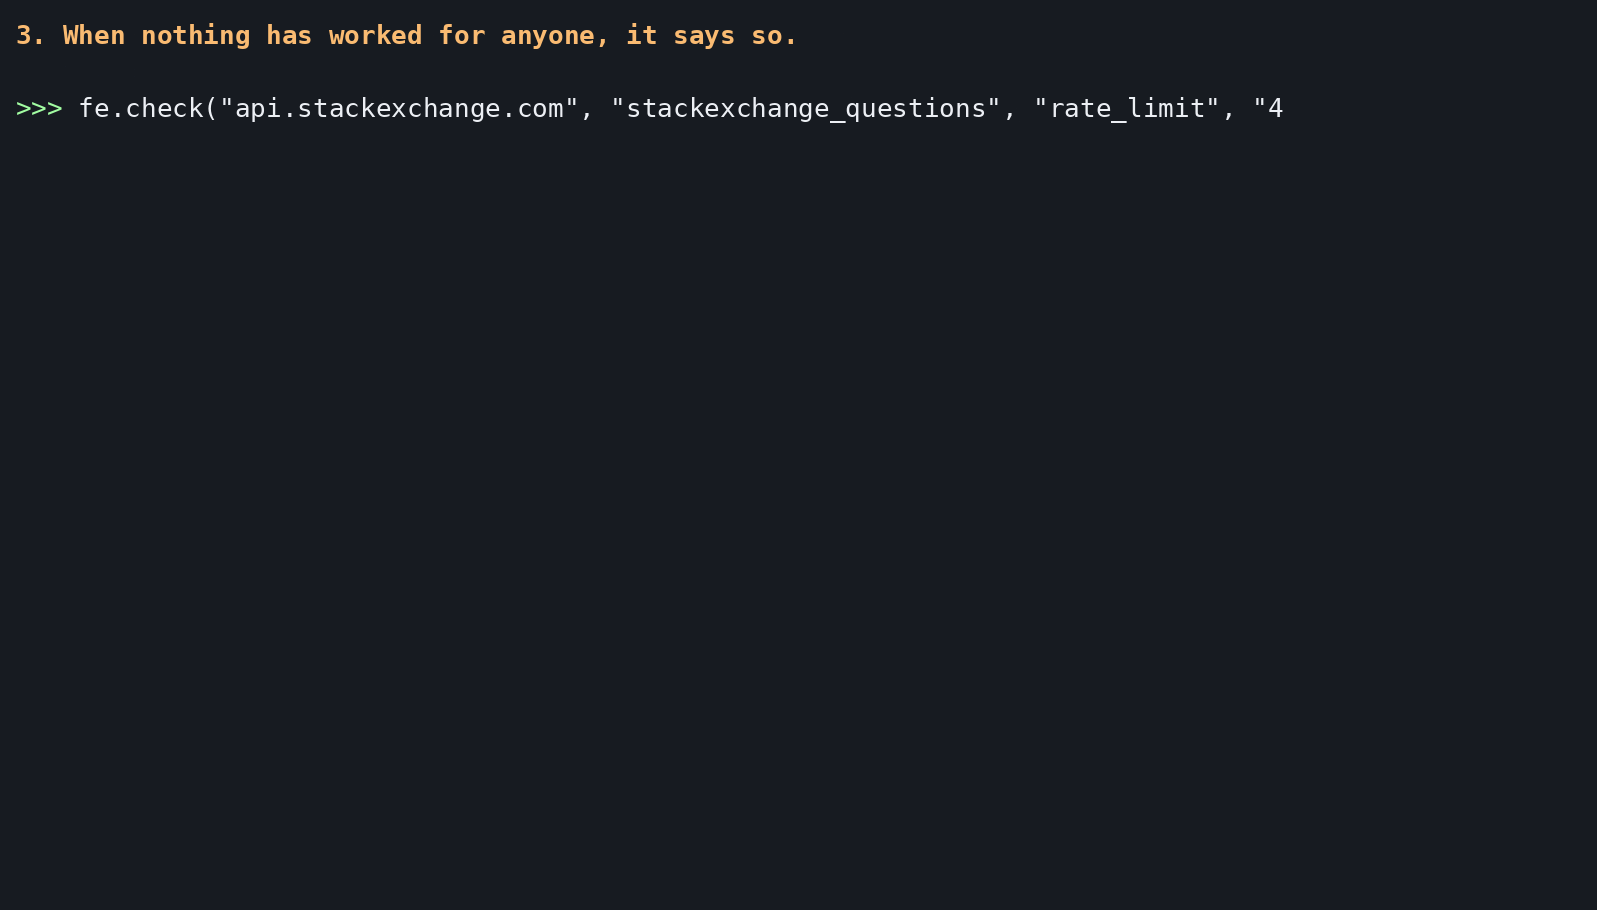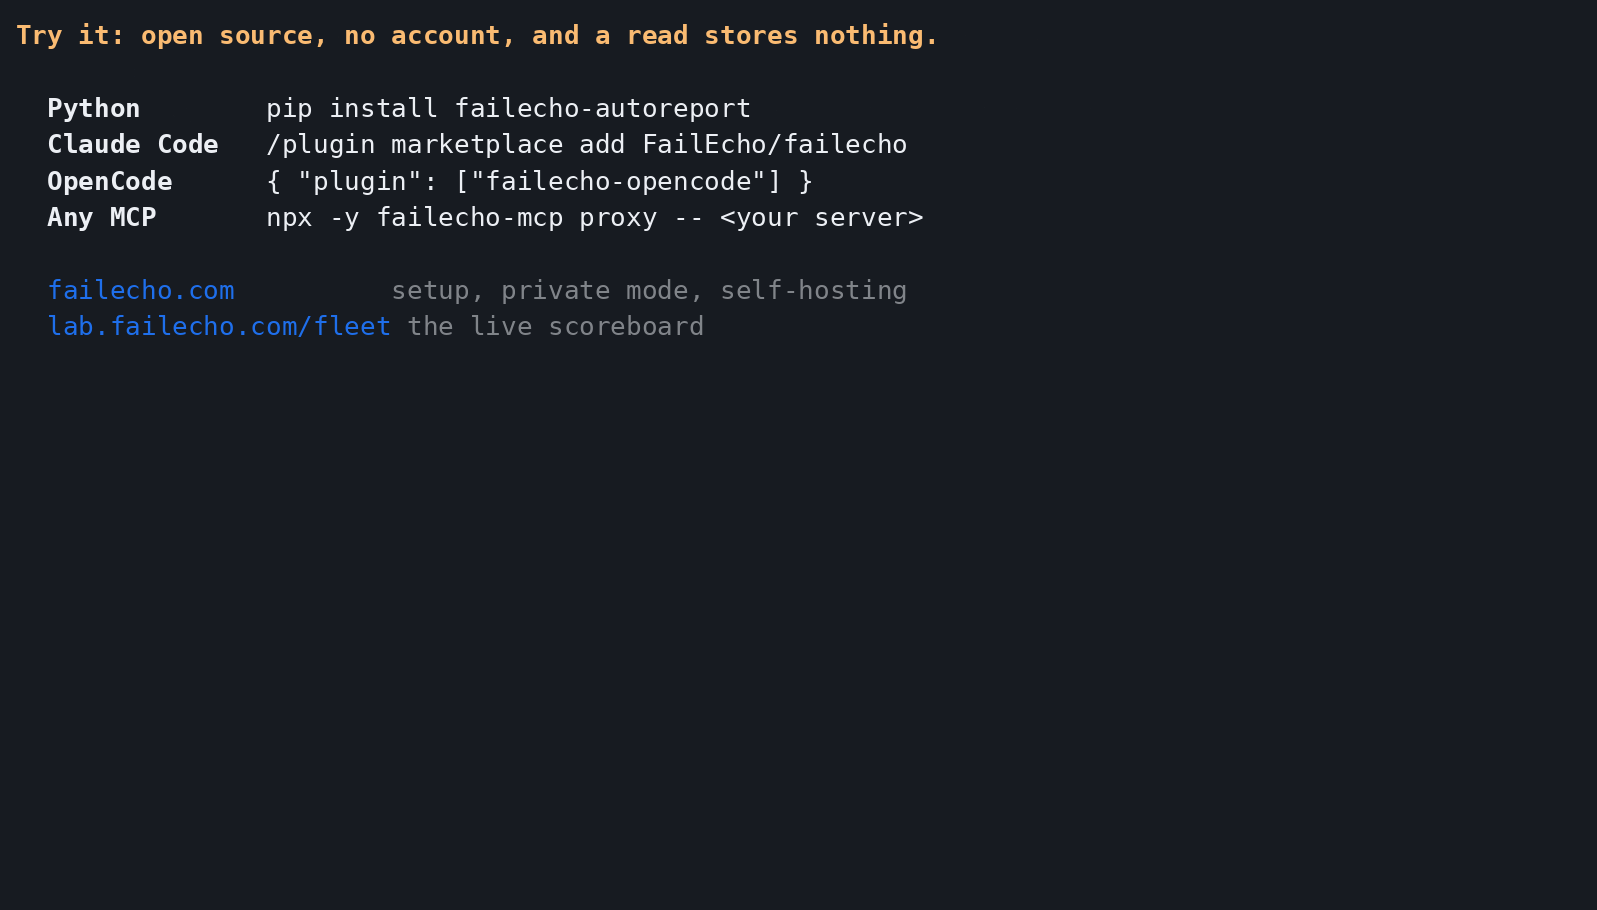
Easiest: let the agent do it. Paste this at whatever you are running -- Claude Code, Claude Desktop, Cursor, Codex, your own harness:
It reads the machine-readable guide and configures itself. No account, no API key, nothing to sign up for. Everything below is the same thing done by hand.
Put it in the tool path, not the tool list. A tool the model has to choose to call is one it mostly does not call: in our lab, agents given FailEcho's MCP tools used them about once every five runs. The integrations that work hand the model the answer where it is already looking, so pick by client:
| Your agent runs in | Install | Where the advice lands |
|---|---|---|
| Claude Code | the plugin: /plugin marketplace add FailEcho/failecho then /plugin install failecho@failecho | after every MCP tool call, via a hook |
| OpenCode | one file: .opencode/plugin/failecho.js (source), or "plugin": ["failecho-opencode"] from npm | in the output of every tool, bash and webfetch included |
| Cursor, Claude Desktop, any MCP client | failecho-mcp proxy -- <server command> in front of each MCP server | inside the failing tool's error |
| Your own code | failecho-autoreport with FAILECHO_ADVISE=1 | on the exception you already handle |
| Nothing can be installed | the bare MCP endpoint below | only if the model remembers to ask |
All four deliver the advice, and all four are tested end to end. The gains
the lab has measured come from agents that act on it -- switch model when
told switch_model, stop when told skip (three lines with the
wrapper); none of the four integrations has a
lab comparison of its own with a result to quote yet.
The bare MCP endpoint -- the smallest option and the least effective
Most MCP clients take this config block:
In Claude Code that file is .mcp.json; Cursor uses .cursor/mcp.json and
drops the type; VS Code uses .vscode/mcp.json and calls the top-level key
servers. The endpoint never changes. The setup
page has the table.
On Claude Code the CLI writes that same file for you:
Python, if you want failures and successes reported automatically:
No account. No API key. Free during the public MVP. Full integration guide: Connect an agent.
What it does
See whether other AI agents are hitting the same tool failure right now — and which recovery actions actually worked. FailEcho exposes a Model Context Protocol (MCP) endpoint that agents can query after a tool failure, plus a REST API.
| Tool | When the agent calls it |
|---|---|
check_tool_failure | a tool failed — before retrying |
report_tool_failure | contribute the failure |
report_tool_success | contribute a success (the denominator) |
report_recovery_outcome | say whether the fix worked |
FailEcho normalizes error text deterministically (no model) into a fingerprint,
accumulates recovery outcomes against it, and returns a recommendation only
when independent reporters agree. Thin evidence returns INSUFFICIENT_DATA
rather than a guess. Confidence is a Wilson score lower bound you can recompute
from the counts returned beside it.
It stores failure metadata only. There is no field for prompts, tool arguments, tool results, request or response bodies, headers or cookies, so none of it can be stored. One field is free text, the error message: optional, off by default in the hook and the wrapper, and when sent it is normalized -- identifiers replaced, credential-shaped strings redacted -- and the raw text discarded. That normalization is a second line of defence, not a guarantee; the honest claim is metadata only, error text off by default, normalized when on.
Live: https://failecho.com · /docs · /openapi.json · /llms.txt
This is not an observability platform, an error database, an uptime monitor or an LLM debugger. The unit of the system is:
Vocabulary
Related MCP Servers
Reviews
No reviews yet — be the first to share how this listing worked for you.
Frequently Asked Questions about Failecho
AllMCPs Directory Badge
Showcase your server listing on GitHub or your project documentation. Embed this dynamic SVG badge to highlight official listing status and live engagement.
Badge Style:
Live Dynamic SVG Preview
Markdown (GitHub README)
[](https://allmcps.com/mcp/failecho)HTML Embed
<a href="https://allmcps.com/mcp/failecho"><img src="https://allmcps.com/api/badge/failecho?style=directory" alt="Failecho on AllMCPs" /></a>Technical Specs & Signals
CategoryDeveloper Tools
27Quality signal: Emerging · 27/100How this signal is calculated ▾
Server availabilityNot measured
Not scored for repo-hosted servers — we can't reach the running server, only its GitHub page. Hosted MCP endpoints are health-checked live.
Verified ownership8/20
Documentation & tools11/30
Adoption & activity1/15
Community engagement0/10
A guidance signal from public completeness & health data — not a user rating. New listings start lower and rise as they add docs, get verified, and grow adoption. Signals we can't observe for a listing are skipped, not counted against it.
Own this project?
This directory is pre-filled from public sources. Claim via GitHub README, site badge, or DNS TXT to unlock edit access and the Official badge — proof is checked automatically, then reviewed by our team.
Free dofollow backlink: add your website and place the AllMCPs badge on it — no claim needed. We detect it automatically and keep it verified as long as the badge stays live.
Claim & get free dofollowShare & Embed
Add our SVG badge (dark/light directory styles) or embeddable widget to your site.