Ask Fable README
The full upstream README, mirrored here for reference. Install config, tool schemas, adoption signals, and an original overview live on the Ask Fable listing page.
ask-fable: Multi-Model Reasoning MCP Server
ask-fable is a portable, installable MCP (Model Context Protocol) server for AI coding agents. It works in Claude Code, OpenCode, Kimi Code, Grok, Cursor, Codex, and any other harness that can spawn a local MCP server.
It gives those agents guarded code and architecture reasoning from Anthropic's Claude Fable (the newest claude-fable-*), Claude Opus 5 (claude-opus-5), MiniMax (MiniMax-M3), Gemini, Codex, GLM, DeepSeek, Grok, Kimi, Ollama Cloud models, and any model on your own LM Studio server. It can query one backend, synthesize a parallel council, run an ordered refinement chain, or stage a structured adversarial debate.
Fable and Opus 5 use Claude Code's existing OAuth session (through the Agent SDK,
with the claude CLI as a fallback). MiniMax, Gemini, Codex, Grok, and local Ollama
similarly reuse authenticated local CLIs. LM Studio is a LAN backend that needs no
key: ask_model(provider="lmstudio") loads a model on demand with a real context window and does not
evict a resident model. GLM, DeepSeek, and Atlas Cloud are
optional HTTP backends that need server-side API keys.
Start here
| If you need to… | Use |
|---|---|
| Ask one trusted coding model, with follow-up memory | ask (Fable; add oracle="opus" for Claude Opus) |
| Ask a cheap, fast Anthropic model (high-volume, single-turn) | ask_model(provider="sonnet") (Claude Sonnet 5) |
| Compare independent answers in parallel | ask_council |
| Draft, critique, then decide in order | ask_chain |
| Stress-test a high-impact decision | ask_debate |
| Check an answer you already have | ask_verify |
| Grind a claim down to what survives evidence | ask_falsify |
| Brainstorm an open question, models arguing to divergence | ask_conference |
| Select a task-matched Atlas Cloud model | list_models(provider="atlas") → ask_model(provider="atlas") |
| Atlas council with GPT-5.6 Sol adjudicating | ask_council(provider="atlas") |
| Ask a model on your LAN LM Studio server | ask_model(provider="lmstudio") (one model) / ask_council(provider="lmstudio") (local panel, Fable synthesizes) |
| Check the GPU or free a local model | host_status / unload_lms_model |
| Reuse large code context without pasting it again | context(op="write", …) + context_ref |
| Investigate a request after it ran | trace_list + trace_get |
Start with ask for one hard question. Escalate to a council, chain, or
debate only when the decision warrants the extra latency and cost.
What it gives you
ask-fable gives an MCP client six ways to reason:
| Mode | What happens | Best for |
|---|---|---|
| Ask | One model answers directly; Fable can remember a session | Everyday debugging and design questions |
| Council | Several models answer in parallel; Fable reconciles them | Comparing independent opinions |
| Chain | Models work in order: draft → critique → decide | Deliberate refinement and cost-tiered escalation |
| Debate | A proposer and opponent test claims; Fable adjudicates | Contentious, hard-to-reverse decisions |
| Falsify | Claims are asserted, attacked, and resolved by a code clerk; the ledger persists across calls | Grinding a checkable claim down to what receipts actually support |
| Conference | Models argue together over rounds; a rapporteur maps the disagreement | Open-ended ideation |
The same guard, context bus, cache, audit trail, and tracing layer wrap every mode. Backends are optional: use Fable alone, call a specific provider, or mix Fable, Opus 5, MiniMax, Gemini, Codex, Grok, GLM, DeepSeek, Kimi, Ollama, LM Studio, Atlas Cloud, and OpenRouter. Unavailable council members are reported and skipped instead of failing the whole request.
A real example — ask_debate, lazy token bucket vs. background refill task
for a per-user rate limiter (resolution: adjudicated):
Use the lazy token bucket. Do not build the background refill task — the timer only approximates at tick granularity what the lazy design computes exactly.
The debate surfaced traps neither side opened with (a 100 req/min bucket permits ~199 requests in a worst-case rolling minute; TTL eviction alone doesn't bound memory) and closed with four ship-it fixes. More real calls, one per mode: docs/EXAMPLES.md.
The cheapest real second opinion is the twin token — the twin flames.
It expands to both Anthropic reasoners at once, Fable + Claude Opus 5, and
both ride the same OAuth session as ask, so a two-model cross-check costs you
no provider keys and no extra setup:
Five features make the result useful to an agent, not just readable by a human:
-
Structured sidecar — every answer carries a machine-readable
sidecar({recommendation: apply|investigate|reject|needs_more_context, confidence, needs_context}) next to the prose, so an agent acts on it directly. When the model needs more, afollowuptells it exactly what to paste, and a per-session terminator stops an unbounded re-ask loop (status:"context_exhausted"). -
Context bus —
context(op="write", …)a big codebase context ONCE under a key, then passcontext_refon any ask tool (or council) to pull it in instead of re-pasting. Shared by every agent on the server;context_read()lists what's stored andcontext_read(key=…)fetches a blob, whilecontext'spack/deleteops round it out. -
Council consensus — councils return a
consensussignal (strong|partial|divergent|unknown) +material_disagreementcomputed from the panel's recommendations, eachsourcesentry shows that model'srecommendation, and the synthesis is anonymized (Expert A/B, Fable last) to blunt self-preference bias. The signal counts labs, not models: a panel that agreed but spans one training lineage (e.g. several Anthropic models) is downgraded fromstrong, andindependent_labsreports how many distinct labs answered — same-lab models don't fail independently, so their agreement isn't independent evidence. -
Correlated traces — every call includes a
trace_id; inspect the ordered request timeline without storing raw prompts in the default safe mode. -
Session hub — successful turns from local MCP instances are mirrored into a shared, visibility-only dashboard. Agents can use the same label to coordinate work without that shared history ever becoming model context.
How it works
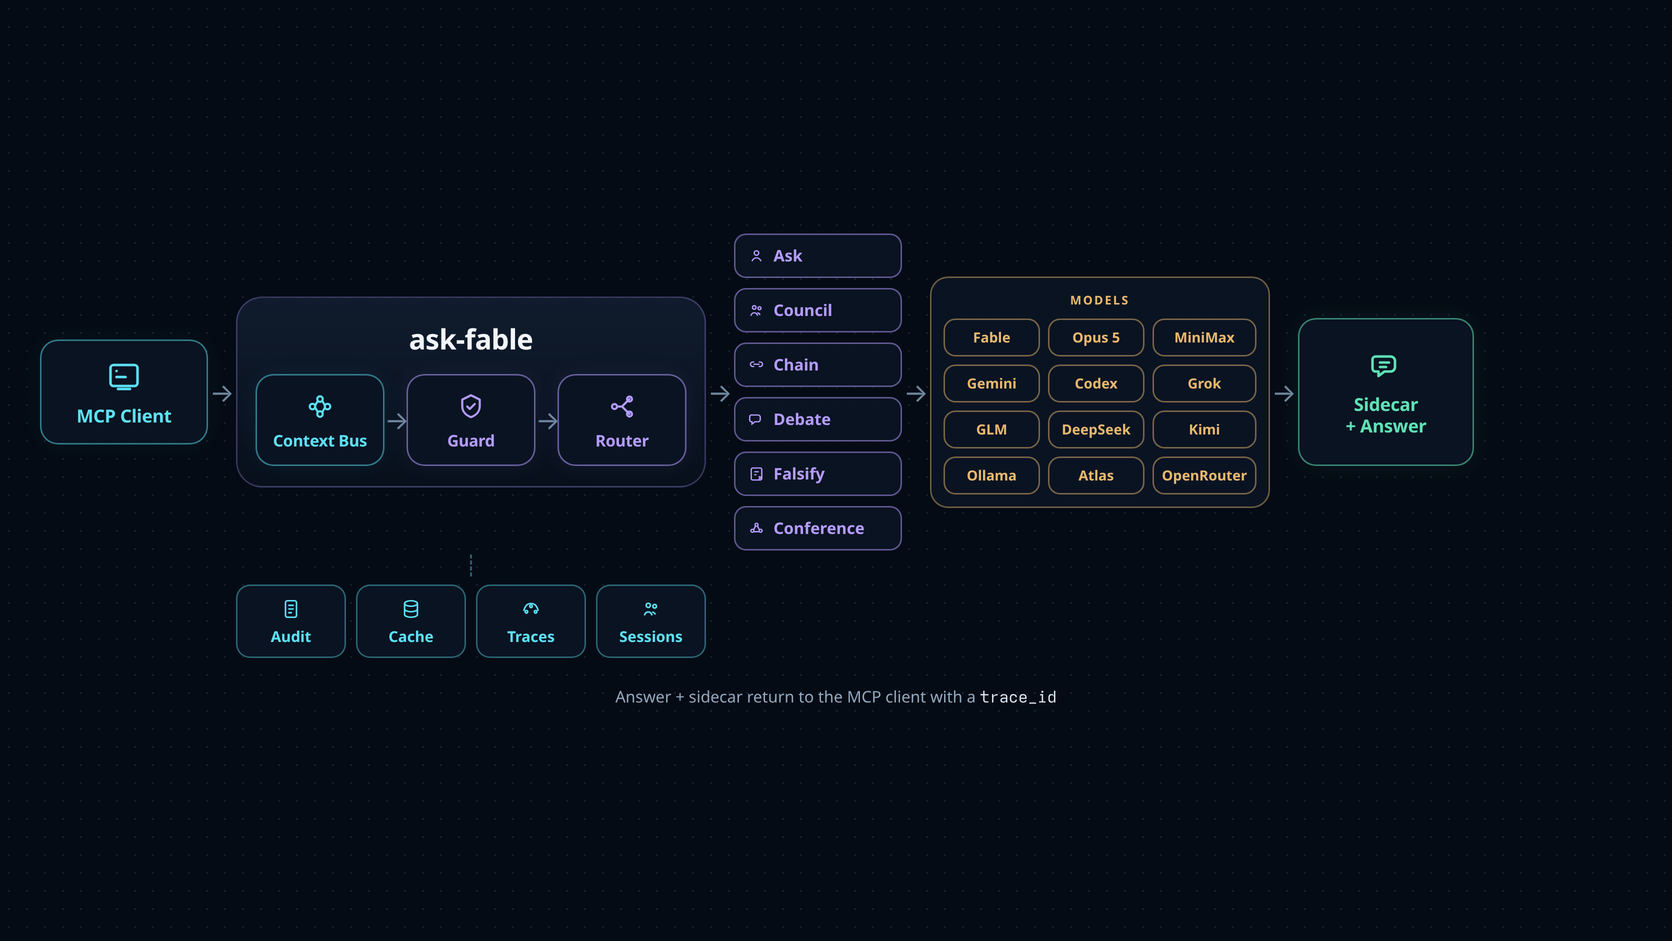
A request enters through MCP, resolves any reusable context_ref, passes the
guard, and is routed to the chosen reasoning mode. The result is normalized into
an answer plus a machine-readable sidecar, persisted to the configured
observability stores, and returned with a trace ID.
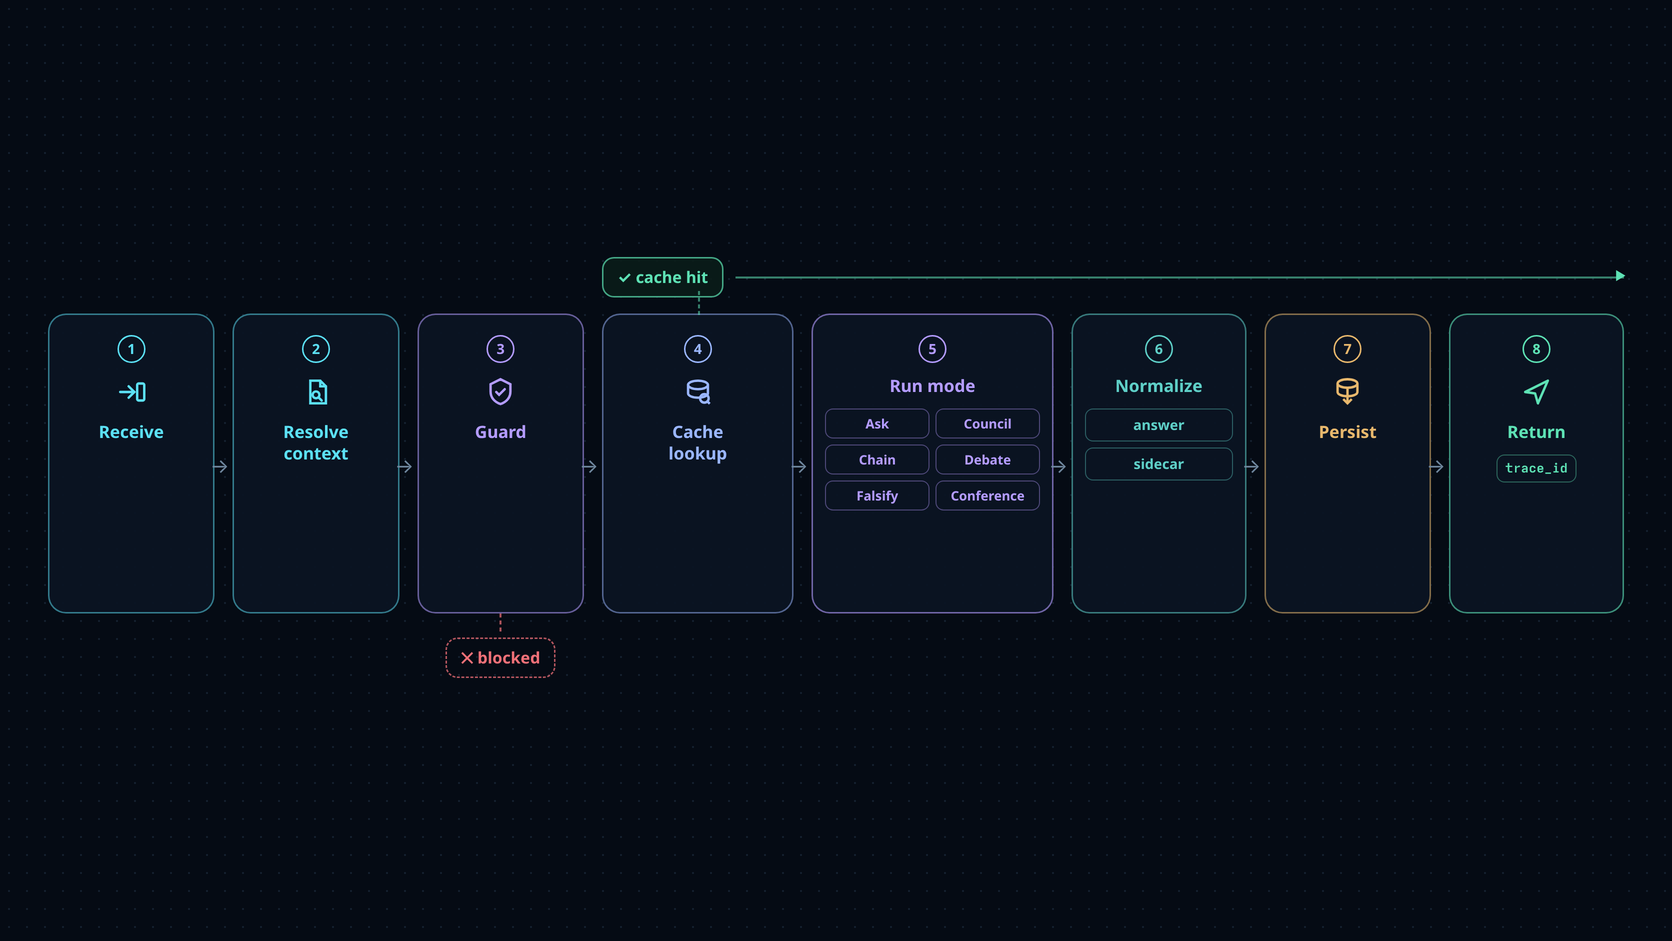
The project ships its own two-layer request gate: a size/sanity floor followed by a prohibited-use denylist. Fable's model prompt adds the final semantic scope contract. See The guard for the exact behavior.
The guard
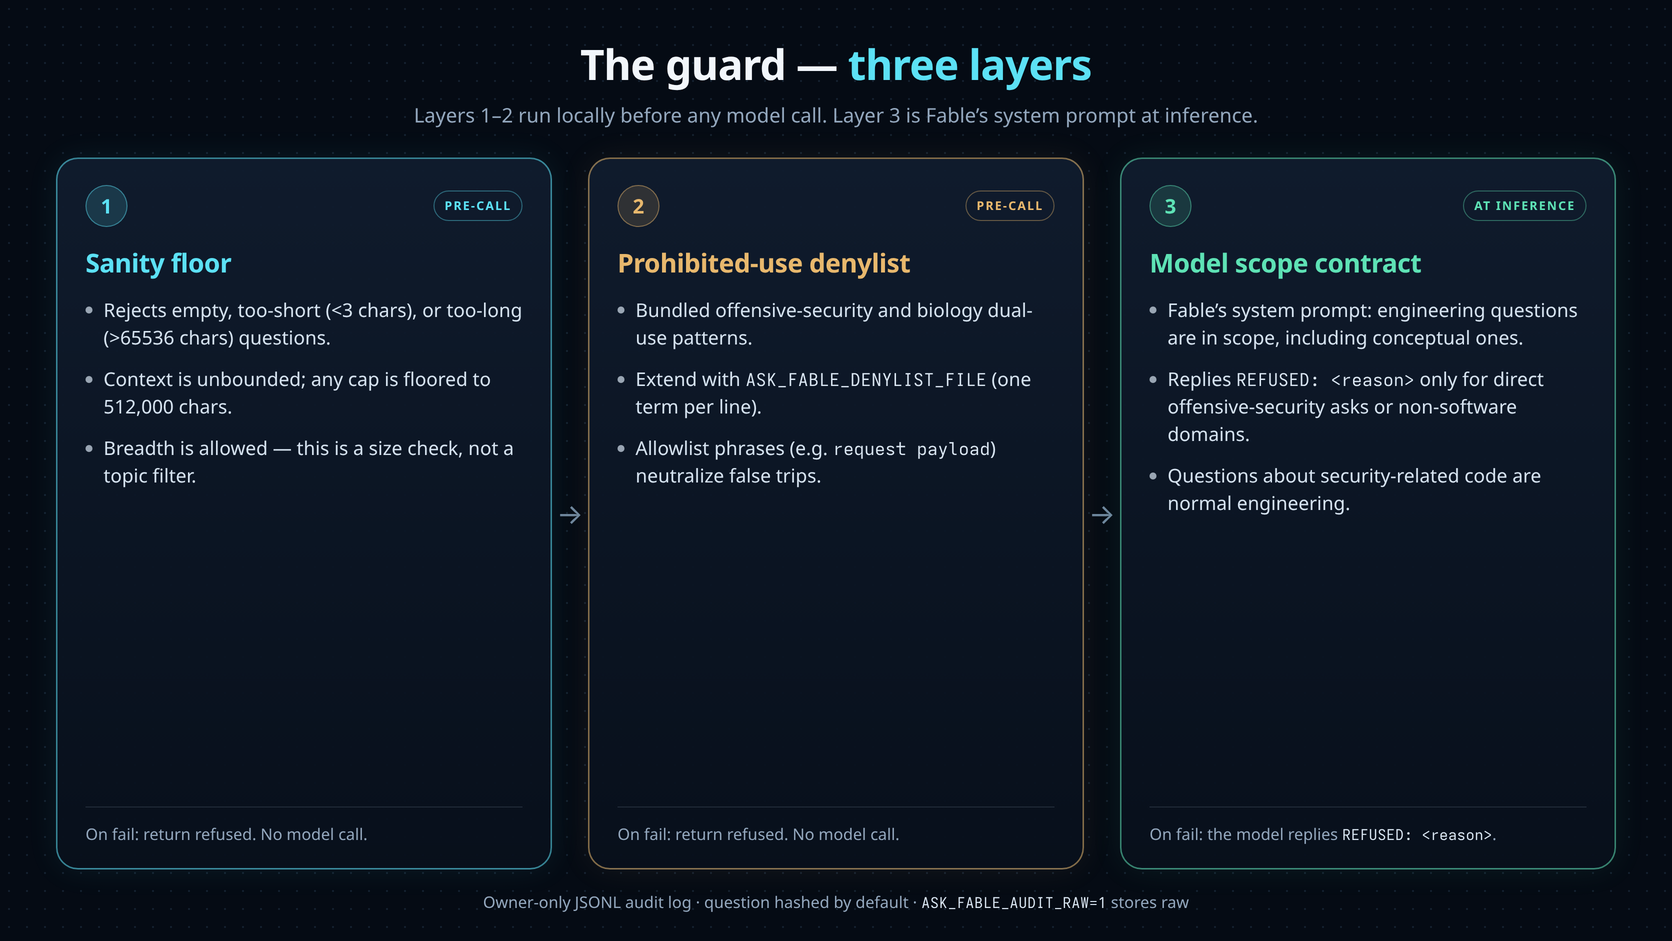
Every question is checked before any model call:
- Sanity floor — rejects only empty / too-short (
<3chars) / too-long (>65536chars) questions. Context is unbounded by default (any cap you set is floored to 512,000 chars). Breadth is allowed. - Prohibited-use denylist — ask-fable's bundled offensive-security and
biology dual-use patterns. It scans the question and
context(the context scan is on by default;ASK_FABLE_GUARD_SCAN_CONTEXT=0restricts it to the question) — the provider's own safeguard reads the whole payload, so a block is caught locally and deterministically instead of upstream. Extend it viaASK_FABLE_DENYLIST_FILE(one term per line). Benign multi-word phrases (e.g.request payload) are neutralized before matching so an ambiguous word likepayloadused in an ordinary engineering sense doesn't false-trip; add your own viaASK_FABLE_ALLOWLIST_FILE(one phrase per line). This only rescues the exact benign phrase — a bare prohibited term still rejects. Legitimate security-engineering work passestrusted=true(operator-authorized viaASK_FABLE_ALLOW_TRUSTED) to run the denylist log-only. - Model scope contract — Fable answers engineering questions, including
conceptual/brainstorming ones with no code context (breadth is fine), and
replies
REFUSED: <reason>only when the question itself directly asks for offensive-security work (exploit development, attack tooling) or non-software domain knowledge (e.g. biology). Questions about security-related code are normal engineering.
Every decision is appended to an owner-only JSONL audit log (question hashed by
default; ASK_FABLE_AUDIT_RAW=1 to store raw).
Quick start
1. Install
New here? The setup & usage guide walks through install, registering in Claude Code (OpenCode, Kimi Code, Grok, and other MCP clients use the same server — see below), setting up every backend (API keys, Ollama Cloud, MiniMax/Gemini CLIs),
/mcpverification, and how to use every tool.Want the big picture? The visual architecture map charts the whole server end to end — the request pipeline, the oracle bridges, council/chain orchestration, and on-disk state.
Requires the Claude Code CLI to be installed and logged in (that's the OAuth session Fable is reached through).
2. Register in your coding harness
ask-fable is a local stdio MCP server (ask-fable on PATH). Point any
MCP-capable coding harness at it; only the config-file shape changes. Restart
the harness after editing — most load MCP servers once at startup. All 40
ask_fable tools then become available. They are grouped into reasoning modes,
direct provider calls, context management, configuration, and observability;
see the tool guide for the short chooser or CLAUDE.md
for the complete one-line inventory.
Claude Code — ~/.claude/.claude.json
Add to ~/.claude/.claude.json (root-owned — edit as the owner, e.g. via
sudo):
(or "command": "python3", "args": ["-m", "ask_fable"]).
OpenCode — ~/.config/opencode/opencode.json
The docs/OPENCODE.md guide covers the full setup — the
exact schema-valid MCP block, optional API keys, the restart-to-load behavior,
and troubleshooting. Minimal registration:
Kimi Code — ~/.kimi-code/mcp.json
Kimi Code's default MCP request timeout is ~60s; oracle calls often run longer.
toolTimeoutMs keeps the host from aborting a still-running call. A
Request timed out error from the client is that transport timeout, not a
refusal — check trace_list before re-asking.
Grok — ~/.grok/config.toml
Cursor, Codex, and other MCP clients take the same ask-fable command; only
the config file shape differs.
3. Ask a question
In your MCP client, call ask with a focused question and the relevant code or
error. Reuse the same session key for follow-ups:
Tool guide
The server exposes 28 MCP tools, but you only need seven entry points —
ask, ask_council, ask_chain, ask_debate, ask_verify, ask_falsify, and
ask_conference. Everything
else selects a specific backend, manages reusable context, or inspects what ran.
| Goal | Start with | Escalate when |
|---|---|---|
| Solve or debug one problem | ask (Fable; oracle="opus" for Claude Opus 5 — ~half the price, faster) | use context_ref for large reusable context |
| Get one alternate opinion | ask_model(provider=…) — minimax/deepseek/glm (cheap direct APIs first), gemini/codex/grok/kimi (local CLIs), ollama/atlas/ali/openrouter (gateways, pass model), lmstudio (LAN LM Studio) | use a council when you need comparison |
| Research a live-web / OSINT question | ask_websearch (opt-in — the one tool that browses; model=grok default, or gemini / a Claude model) | set ASK_FABLE_ALLOW_WEBSEARCH=1 to enable it |
| Pick an Atlas model for a task | list_models(provider="atlas", task="…") | call ask_model(provider="atlas", …) with the accepted selection or rendered picker |
| Cross-check with a second strong model | ask_council(models=["twin"]) — Fable + Opus 5 on one OAuth session, no keys | add a third voice with models=["twin","m3"] |
| Compare several views | ask_council | use ask_chain when order matters |
| Cross-check Atlas models, GPT adjudicating | ask_council(provider="atlas") | pin the panel with configure_council(provider="atlas") |
| Cross-check your local LM Studio models | ask_council(provider="lmstudio") | pin the panel with lmstudio_council / ASK_FABLE_LMSTUDIO_COUNCIL |
| Make a contentious decision | ask_debate | keep the scope narrow; it is the most expensive mode |
| Check a draft answer before acting on it | ask_verify | pass the draft as answer and its source material as context; read verify.prevented, not the prose |
| Prove a claim before acting on it | ask_falsify | pack the corpus it must cite; reuse the same session to compound evidence |
| Brainstorm an open question | ask_conference | raise rounds (default 3, up to 10) when a dilemma needs more back-and-forth |
| Inspect what happened | trace_list then trace_get | enable full mode only when redacted content is needed |
Full reference: docs/TOOLS.md — every tool, its arguments, and
when to reach for it. A one-line inventory of all 27 lives in CLAUDE.md.
Observability & response shape
Every answer carries a machine-readable sidecar ({recommendation, confidence, needs_context}) and a trace_id; councils add a consensus signal and debates a
deterministic resolution. Results are cached, progress streams to the console, and
all persisted state lives under a per-user state dir with owner-only permissions.
Details: docs/OBSERVABILITY.md — the full response contract, caching, console progress, and backend setup.
Configuration
Everything is optional environment variables set in the server's env block, with
sensible defaults.
Reference: docs/CONFIGURATION.md — every setting grouped by backend, guard, storage, and observability.
Recommended agent instructions
The server injects a short standing instruction so agents reach for these tools
unprompted. But weak local models under-attend to system prompts, so for the best
results also drop a decision ladder into your project's CLAUDE.md /
AGENTS.md / opencode.md (agents re-read those). Copy this block:
Companion skills
skills/ ships four skills that drive these tools from Claude Code, OpenCode,
Grok, Kimi Code, and other skill-capable harnesses (copy or symlink into
~/.claude/skills/, ~/.agents/skills/, or the harness equivalent):
ubercode— treat Fable (and, viaask_council, MiniMax-M3) as a smarter reasoning partner for the hard 5%: oracle escalation when you're stuck, and cross-checked adversarial review before a high-consequence diff.uberplan— fan out N diverse candidate plans locally, use Fable as a comparative judge (optionally cross-checked withask_council), then synthesize one final plan.uberarch— open-ended architectural ideation: fan abstract ideas out to the oracles (ask_council/ask_chain) for multi-model trade-off analysis before any code exists.uberbrainstorm— design-first, approval-gated brainstorming for the fuzzy front end ("what should we build and why"), with the council red-teaming the chosen design; hands off touberplan.
Development
salient-core (a richer prohibited-use denylist) is unpublished and therefore
not declared as an extra; the guard picks it up automatically at runtime if it
is installed in the environment.
Documentation
- Setup & usage guide — install, register, backends, verification
- Real examples — actual calls per mode, with verdicts
- Tool guide — every tool and when to use it
- Configuration reference — all environment variables
- Observability & response shape — sidecar, traces, caching
- Decision-flow diagrams — per-mode orchestration charts
- Context bus — local SQLite store and LAN design
- Remote context bus — share context across machines
- OpenCode setup · Visual architecture map
License
MIT