Create, inspect and extract zip archives from chat: glob a directory into a zip, list what is inside with a bomb and traversal check, extract safely, read one text entry without unpacking. No network.
Quick Install
Automated & IDE SetupCopy the AI prompt to install this server into Claude Code, Cursor, or another agent — or use 1-click editor setup below.
Not yet automatically verified
We haven't yet run this listing's install command through our automated sandbox check. This isn't a red flag — we're steadily working through the catalog.
Manual Client & Custom JSON ConfigExpand JSON ▾
Client Config & Setup
Choose your client or environment
Target File:
💡 Paste the JSON block into your client's configuration file under mcpServers, then restart the application.
Capabilities & Tool Schemas (7)
Inspect callable tools, capabilities, and parameters exposed to AI agents by Zip.
zip_createPack files, or a directory tree with glob patterns, into a new .zip
zip_listEvery entry with its size, compressed size and ratio, and everything dangerous in it, flagged
zip_extractUnpack into a directory, with traversal, symlink and zip-bomb guards and a `dry_run
zip_addAdd files to an archive that already exists
zip_extract_textRead one text entry inline, without unpacking anything
zip_bundle_monthOne month of invoices, quotes and exports from the sibling servers, in one file
Documentation Overview
mcp-zip
MCP server for zip archives: create, inspect and extract. Make a zip, look inside one, and unpack one, entirely on your machine.
Works with Claude Desktop, Claude Code, Cursor and any Model Context Protocol client. Runs on your own machine, or hosted with no install.
Product page: https://mcp.zovo.one/s/zip — what it does, the tools it exposes, and a live token endpoint.
Install
Hosted, nothing to install. Get a token from https://mcp.zovo.one/mcp/connect (the connect page) or https://mcp.zovo.one/mcp/token (the same token as JSON); a free anonymous one is issued on the spot and a Pro key works the same way. Then point an MCP client at https://mcp.zovo.one/mcp/zip over streamable-http and send the token as Authorization: Bearer <token>.
If your client cannot set headers, put the token in the path instead: https://mcp.zovo.one/mcp/zip/t/<token>. Both forms work. The bare URL with no token answers 401 on tools/call, so the token is not optional.
Claude Desktop, one click. Download zip.mcpb from the latest release and double-click it.
From source. The mirror is self-contained: every @theluckystrike/* dependency is vendored, so a fresh clone builds with no extra setup.
Then point your client at the built entry point:
@theluckystrike/mcp-zipis not published on npm yet, so annpx -y @theluckystrike/mcp-zipcommand will fail. The three paths above are the working ones and each is exercised by CI.
Read-only mirror of mcp-servers/servers/zip. See MIRROR.md.
Make a zip, look inside one, and unpack one, in the conversation you are already in. Pack a folder with a glob
(**/*.csv, everything except node_modules). Read the one README out of an archive without unpacking it.
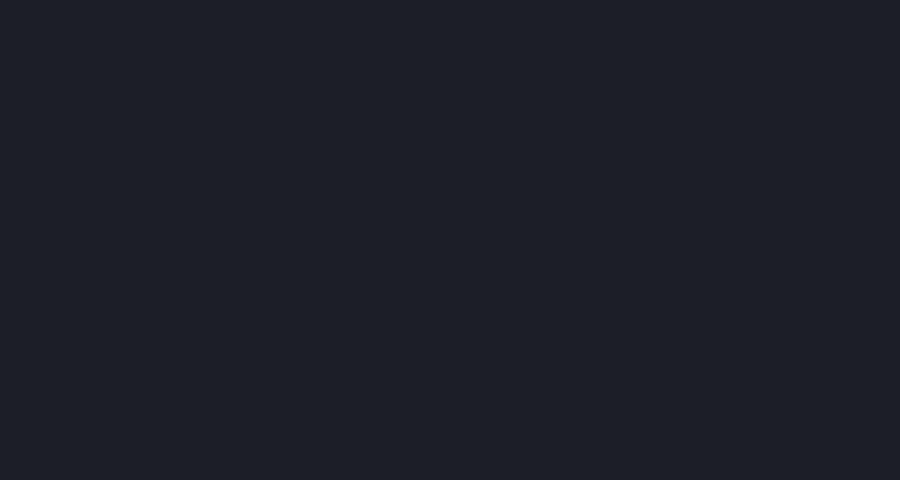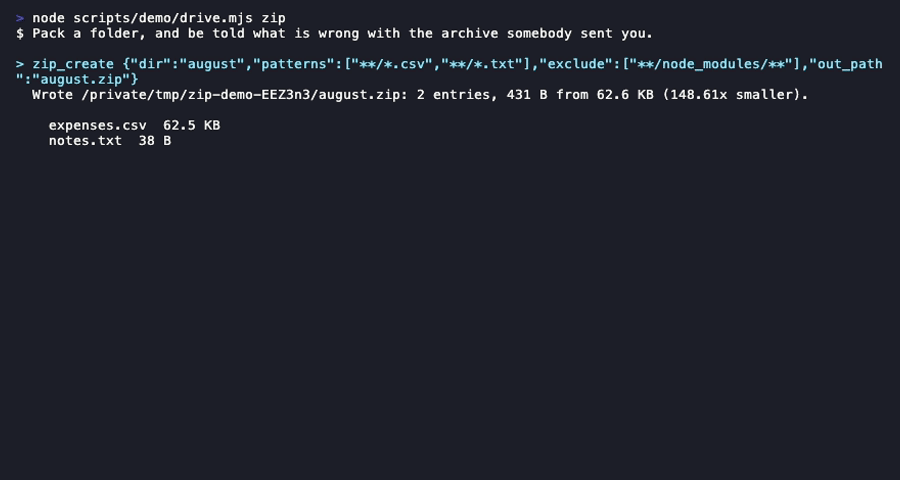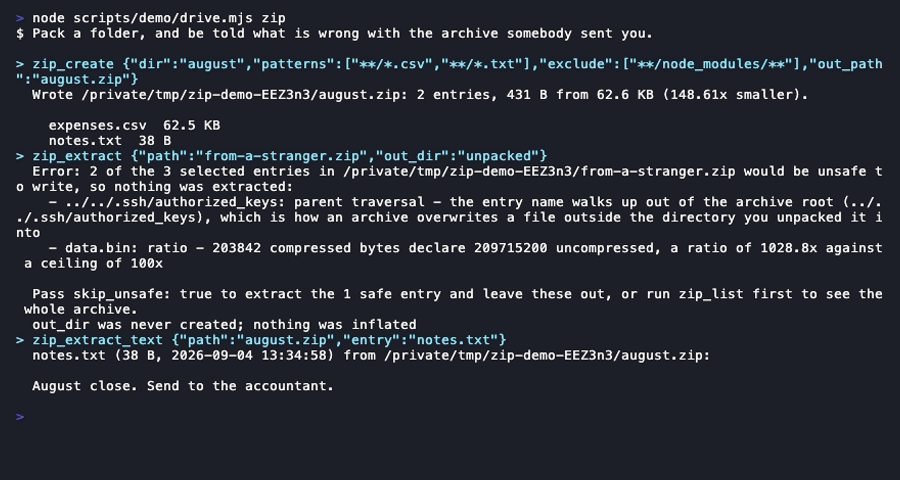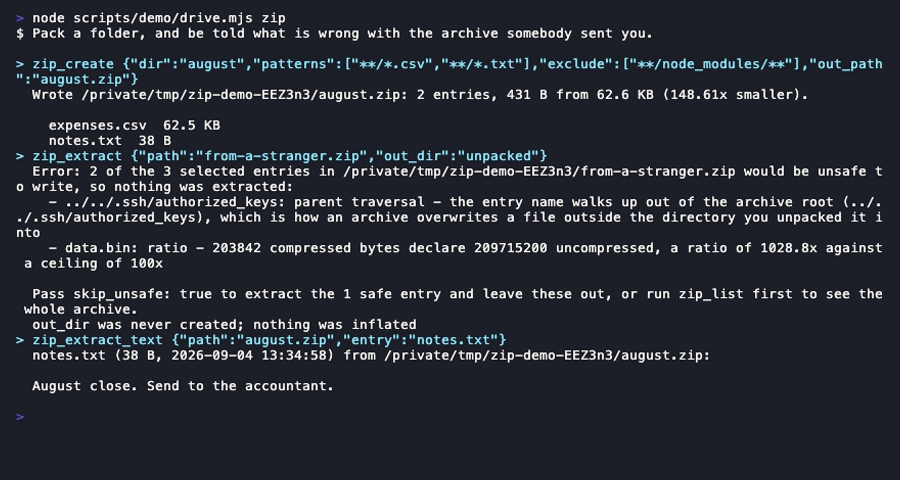
Ask what is inside a zip somebody sent you and be told before you open it: absolute paths, .., symlinks,
duplicate names, and the entry that claims to be 200 MB inside a 199 KB file. Bundle a month of invoices,
quotes and exports into one file to send to an accountant. Everything runs on your machine: no upload, no
account, no API key, and no network call of any kind.
In the official MCP Registry (io.github.theluckystrike/zip-archive-create-extract-bomb-guard).
npm publish for @theluckystrike/mcp-zip is pending, so npx -y @theluckystrike/mcp-zip returns 404 today. Until then, the .mcpb one-click bundle or a clone+build is the working path.
Install
Claude Desktop, ~/Library/Application Support/Claude/claude_desktop_config.json (macOS) or
%APPDATA%\Claude\claude_desktop_config.json (Windows):
Claude Code:
Cursor, .cursor/mcp.json:
Tools
| tool | what it does |
|---|---|
zip_create | Pack files, or a directory tree with glob patterns, into a new .zip |
zip_list | Every entry with its size, compressed size and ratio, and everything dangerous in it, flagged |
zip_extract | Unpack into a directory, with traversal, symlink and zip-bomb guards and a dry_run |
zip_add | Add files to an archive that already exists |
zip_extract_text | Read one text entry inline, without unpacking anything |
zip_bundle_month | One month of invoices, quotes and exports from the sibling servers, in one file |
zip_history | What you have created, and how much of this month's free allowance is left |
license_status, license_activate | Free or Pro, and activating a key |
Free vs Pro
| Free | Pro | |
|---|---|---|
| Archives per calendar month | 20 | Unlimited |
| Archive size | Up to 25 MB | Unlimited |
| Entries per archive | Up to 200 | Unlimited |
Reading: zip_list, zip_extract, zip_extract_text | Unlimited | Unlimited |
| Bomb, traversal and symlink guards | Yes | Yes |
Reading is never metered. The free tier is a limit on what you write, because an archive somebody sent you is exactly the one you most need to inspect before opening, and a paywall in front of that would be a paywall in front of the safety check.
Get Pro: https://mcp.zovo.one/buy/zip - $19 one time, or $39 for every server in the suite, lifetime. Keys verify offline; nothing is sent anywhere.
Why fflate and not a hand-written writer
The choice was fflate (pure JS, 0 dependencies, synchronous zipSync/inflateSync) against writing a
STORE/DEFLATE writer on node:zlib, which is available with no dependency at all.
The container format is written here either way. This server reads the central directory itself, in
src/zipfile.ts, roughly 200 lines: sizes, names, methods, CRCs, external attributes. It has to, because every
guard in the server is a decision made from those headers before anything is inflated, and a library that
hands back {name: bytes} has already decompressed the bomb by the time you can look at it. So the argument for
a library was never "it saves me the format".
What is left is the compressor, and that is the part not to write. node:zlib would do it, but its raw-deflate
calls are async-first, they carry a thread-pool round trip per call, and the sync ones each build a native
stream; packing 200 small files is 200 of those. fflate's deflateSync is a pure-JS implementation with no
native handle, it packs 200 files in 74 ms (measured below), and it means the package still has no native build
step, which is the rule for this whole suite: npx has to work everywhere.
The trade is stated plainly: fflate builds the archive in one buffer, so this server refuses inputs over 512 MB rather than pretending to stream, and it does not read ZIP64 (over 4 GB or over 65,535 entries), which is refused by name rather than misread.
Measured: the file type does not predict the compression ratio, repetition does
Every file below was zipped at level 6 on this machine. The "type" column is what a person would call the file; the ratio is what actually happened.
| file | type | bytes | zipped | ratio |
|---|---|---|---|---|
a 12-page invoice from mcp-pdf | 15,125 | 14,118 | 1.07x | |
a 400-paragraph contract from mcp-docx | DOCX | 9,897 | 7,311 | 1.35x |
| 4,000 rows of billing CSV, varied values | CSV | 321,329 | 134,049 | 2.40x |
this server's own index.ts | source | 39,498 | 11,938 | 3.31x |
package-lock.json | JSON | 138,835 | 33,223 | 4.18x |
| 20,000 lines of an app log | log | 1,603,390 | 106,261 | 15.09x |
| 4,000 rows of billing CSV, 40 repeated clients | CSV | 338,549 | 4,094 | 82.69x |
| 50 MB of zero bytes | bomb | 52,428,800 | 51,294 | 1022x |
PDF and DOCX barely move, and that is not a surprise once you look inside them: both are already deflate containers, so zipping them again is packaging, not compression. Bundling a month of invoices is worth doing for the one file, not for the space.
The two CSV rows are the interesting pair. Same tool, same shape, same size, 34x apart: the one with forty repeated client names compresses 82.69x, the one with unique values 2.40x. Nothing about "it is a CSV" predicts which one you have.
Measured: why the bomb ceiling is 100x and not 50x
A compression bomb is refused by ratio, and the obvious instinct is to set that ceiling low, well under the
1022x a zeros file reaches. The table above says why that is wrong: a real CSV export, of the kind
zip_bundle_month collects from the expense tracker, reached 82.69x, which is 83% of the way to a 100x
ceiling and well past a 50x one. A ceiling tuned to be comfortably below a bomb would refuse a real monthly
export, and the person on the other end would learn to pass max_ratio on everything, which turns the guard
off permanently.
So the ratio is the second guard, not the first. The first is the total: the selected entries' declared
uncompressed sizes are added up and compared against a ceiling (1 GB by default, max_total_mb to change it),
because 200 MB out of a 199 KB file is a decision you can make about the archive as a whole without judging any
entry. Both are read from the central directory, so refusing a bomb costs no decompression at all:
Measured: a bounded output buffer is not a bomb guard
fflate.inflateSync(data, { out: new Uint8Array(n) }) looks like the whole answer: cap the buffer, cap the
damage. It is not, and the way it fails is quiet. A 100,000-byte entry inflated into a 10-byte buffer returns
10 bytes and throws nothing. An archive whose header declares 10 bytes for a 100 KB entry would extract as a
10-byte file, reported as a success, with the truncation invisible.
So the buffer bounds the memory and the CRC-32 in the central directory proves the bytes. Every entry this server writes out is checksummed against the header before it reaches the disk, and a mismatch refuses the entry by name. That is the check that turns a lying header from silent data loss into a sentence.
Timings
M-series laptop, over stdio, per call, cold store:
Related MCP Servers

Adoption & maintenance
Factual signals from GitHub, npm, and our automated checks — not a rating.
Last commit
15d ago
Most recent push to the default branch.
Tools exposed
7
Callable tools this server registers over MCP.
Reviews
No reviews yet — be the first to share how this listing worked for you.
Frequently Asked Questions about Zip
AllMCPs Directory Badge
Showcase your server listing on GitHub or your project documentation. Embed this dynamic SVG badge to highlight official listing status and live engagement.
Badge Style:
Live Dynamic SVG Preview
Markdown (GitHub README)
[](https://allmcps.com/mcp/zip)HTML Embed
<a href="https://allmcps.com/mcp/zip"><img src="https://allmcps.com/api/badge/zip?style=directory" alt="Zip on AllMCPs" /></a>