Super Log README
The full upstream README, mirrored here for reference. Install config, tool schemas, adoption signals, and an original overview live on the Super Log listing page.
 # super-log


One hub for every log stream you have — devices, servers, containers, browsers, chains and apps.
This project is a consolidation of a patchwork of tools I have used, in one form or another, over the last fifteen years — the log mergers, port watchers, build wrappers, ad-hoc proxies and one-off scripts every long-running bench accumulates — rebuilt here as one coherent thing, on one wire protocol, with one screen.
Free and self-hosted, forever. It collects and consolidates; analysis is a separate, cleaner concern — hand the consolidated stream to super-log.com for real-time LLM analysis and team features, or to your own store. See Collection is not analysis.
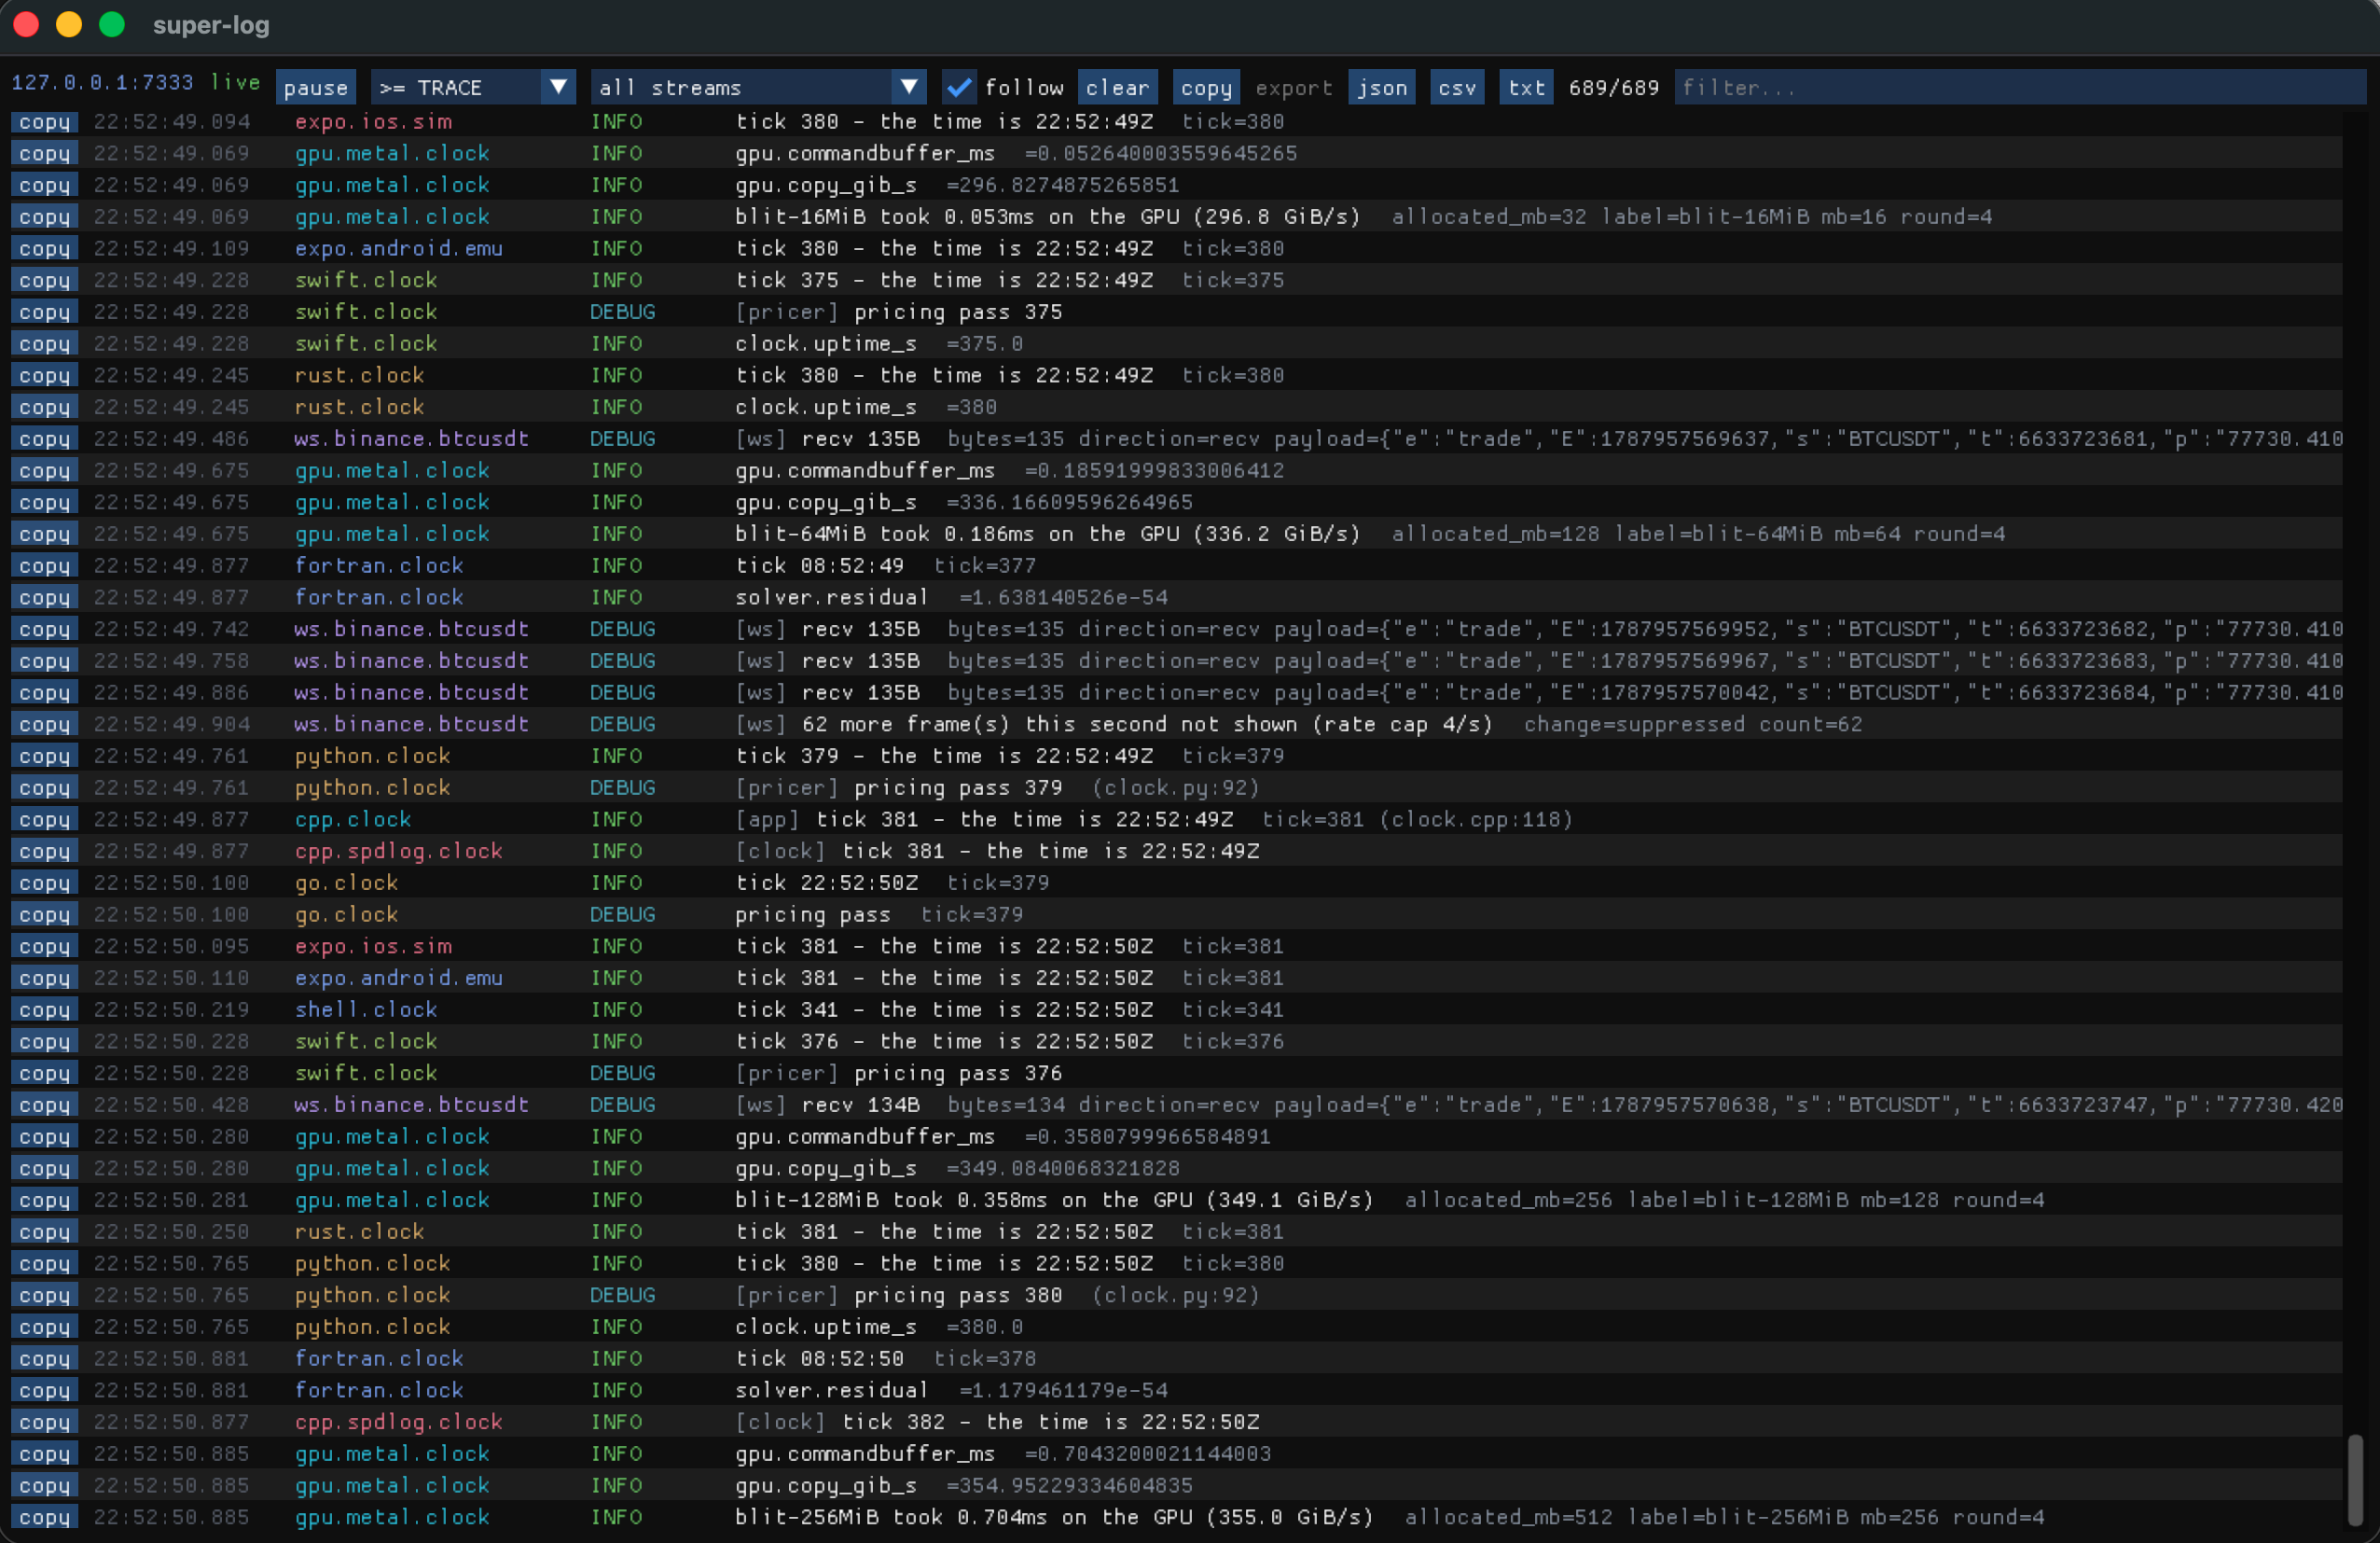
Twelve producers on one screen, interleaved by arrival: C++ through both SN_LOG and spdlog, Rust, Go, Python, Swift, Fortran, a POSIX shell script, two React Native devices, Metal GPU work reporting real bandwidth, and a live Binance WebSocket. The last of those is running at hundreds of frames a second — so it is rate-capped, and says so rather than silently dropping them.
If you build across devices, you know the ritual: a Metro console for the
iOS simulator, another for the Android emulator, adb logcat for the phone
on your desk, a terminal for the C++ engine, another for the Rust service,
browser devtools for the web build, and an ssh session to the box in the
cloud. Six places to look, none agreeing on timestamps, and the bug is
always in the interleaving.
super-log converges all of it on one process and one screen:
| Group | What is in it |
|---|---|
| apps | C++ (spdlog sink and nativeSN_LOG), plain C (one header), C# / .NET (BCL only — console, ASP.NET, Unity profiles, Xbox Dev Mode), Rust (tracing), Python (logging), Go (log/slog), Java, Kotlin and Scala (a drop-in SLF4J backend — swap your logging backend, no code change — plus Log4j 2 and Logback appenders, and java.util.logging), Swift, Fortran, OCaml, Haskell, Lean 4, Ruby and Rails (a drop-in ::Logger), Perl (core modules only), Lua (5.1+, PUC or LuaJIT), Zig (@cImport of the C header), COBOL (riding the C SDK, yes really), POSIX sh, and JS for Node, the browser and React Native — where console, fetch and WebGL are captured too. Anything else with a C FFI links one object: cc -DSUPERLOG_API= -c impl.c |
| OpenTelemetry | already instrumented with OTel? Join the bench withno new SDK — point any exporter at 127.0.0.1:4318 (OTEL_EXPORTER_OTLP_ENDPOINT, the standard port, zero config). Logs, metrics and traces over OTLP/JSON and OTLP/protobuf; severityNumber maps to levels, each service.name becomes an otlp.<service> topic, and an OTel span's trace_id becomes the bench's trace — one /recent?trace= returns the OTel spans and the bench's own lines as a single story. And the reverse: superlog-otlp-export feeds any OTLP backend or collector from the bench (OTLP/JSON logs + gauge metrics), so the bench is a two-way OTLP member, not a walled garden |
| GPU and graphics | Metal and CUDA kernel timings, WebGL context loss and shader failures, and the card itself throughnvidia-smi, rocm-smi or ioreg |
| devices and boards | iOS and Android over USB, serial consoles reading ESP-IDF, Zephyr and bracketed formats, ROS 2/rosout, and drones over MAVLink (ArduPilot/PX4 — battery, GPS fix, mode/arm, failsafes and the flight controller's own STATUSTEXT, from a UDP stream or a .tlog) |
| machines, services | OS logs on macOS, Linux and Windows; ~20 known services (postgres, nginx, redis, kafka…); Unity and Unreal Engine editor logs, level-parsed (Blender and AutoCAD by recipe); Docker containers; any remote host over ssh; power draw, thermals and top energy consumers (macOS); crash reports, kernel panics, shutdown causes, volume and sleep/wake events (macOS); filesystem changes down to the changed LINES, diffed in real time; big downloads — a Hugging Face model, shard by shard — with stall alarms; other hubs, bridged whole; andevery version under the bench — OS, compilers, runtimes, databases and every package the package manager knows — diffed, so "it worked yesterday" finally has an answer |
| network and DNS | an HTTP/S logging proxy, WebSocket frames, a syslog and raw TCP/UDP inlet, DNS records with TLS expiry, listening ports with their processes — and the network's ownstate, watched for change: gateway, Wi-Fi, VPN, resolvers, ARP (a gateway MAC change is ERROR — that is how a MITM starts), ping targets with RTT/loss readings and a traceroute attached to every degradation alarm, plus origin-AS watching of your domains' prefixes (what a BGP hijack looks like from outside); the LAN rendered as a tree with any route kept under watch, and the outbound connections this box holds — a socket stuck in SYN-SENT is the filtered/down port a dev loses an afternoon to |
| builds and repos | cmake, clang, gcc, rustc, swiftc, npm, xcodebuild, Vivado and Quartus — plus sanitizer and valgrind findings captured whole, local git, and GitHub Actions |
| blockchain | watched addresses on any EVM chain, with transfers decoded and token decimals read per contract; operational key balances with edge-triggered fund-now alarms - EVM (gas or ERC-20),Solana (SOL or SPL), Tron (TRX or TRC-20, USDT included), and Bitcoin (any Esplora API, your own node included) |
| trading, FIX | FIX session logs (QuickFIX, FIX8, or any engine that writes the standard message log): every message decoded from the SOH-delimitedtag=value wire and levelled so the quiet failures shout — a Reject or a rejected fill is ERROR with its reason, a Logout or sequence gap is WARN (the session that stopped filling mid-day), a Heartbeat is DEBUG — with ClOrdID, Symbol, Side, OrderQty, Price and OrdStatus riding as fields; one fix.<begin>-<sender>-<target> topic per session, derived from the message itself, never the filename |
| anything that prints | your-command 2>&1 | superlog tee — a drop-in tee |
| alarms, webhooks | rules over the bench (level, rate, silence, combos) plus a tunnelled public webhook for production — deduped by key, repeat-counted, heartbeat dead-man — landing in both viewers' sparse alarm blotters, delivered through one channel registry (desktop, webhook; Telegram/Twilio/email config-gated); public endpoints provisioned one per click or many per manifest file, each with its own ping clock and health light, every route round-trip-tested by the test button, the live URLs written toendpoints.env; webhook testing built in — capture Stripe/GitHub deliveries as wh.* events, verify Stripe signatures on arrival, or relay each delivery to your local handler with its real response returned (stripe listen, with a record) |
Every producer speaks one small wire protocol (docs/PROTOCOL.md: one JSON event per line, batched over plain HTTP POST), the hub fans out to any number of readers with replay-on-connect, and everything is interleaved by hub sequence — not by device clocks, which drift.
Quick start
macOS — Homebrew:
Ubuntu (incl. Ubuntu Server on a Pi) — the PPA, every architecture, auto-updating:
Debian / Raspberry Pi OS — the .deb directly (PPAs are Ubuntu-only; don't
use add-apt-repository here). Pick your arch:
Then see it work in two lines — the hub is already running on :7333:
Fedora/RHEL, npm, vcpkg, building from source, and the web + native viewers are in Install below.
The superlog CLI
One command reads the bench, manages the tailers, and pipes streams onto the hub:
Full reference: docs/CLI.md. Or superlog help.
What it does for you
One screen, everything on it. Streams colour-coded by source and level, filtered by stream, minimum level or substring. Pause freezes the display while collection continues; copy a row or the whole filtered view; export JSON, CSV or plain text.
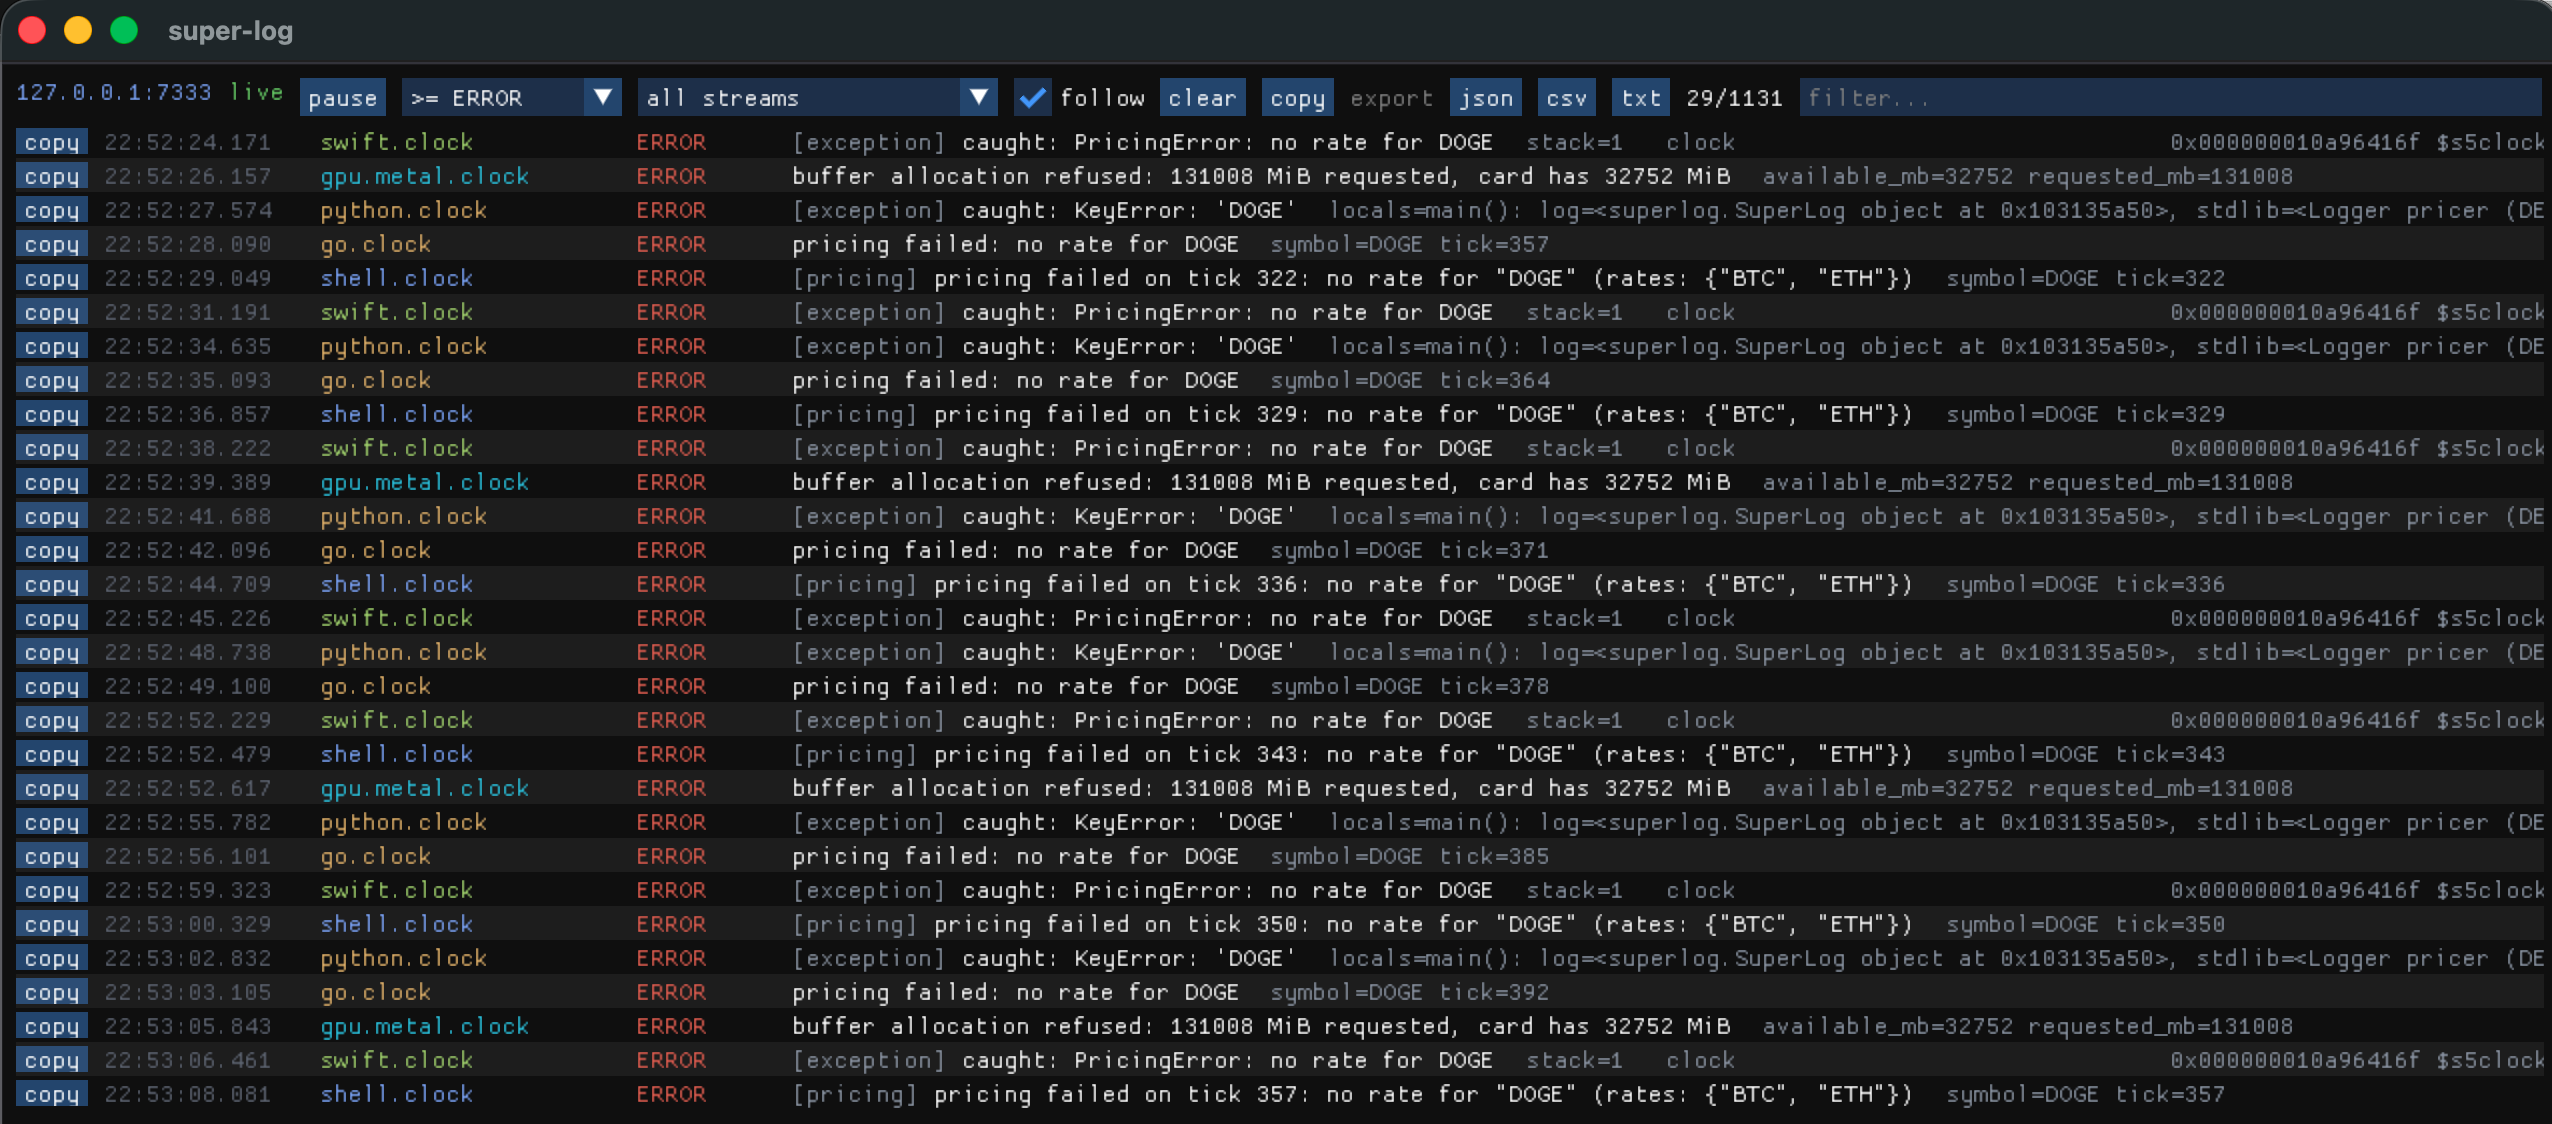
The minimum level set to ERROR: 29 rows out of 1131. The same pricing
failure surfaces from Swift, Python, Go and a shell script side by side —
each in its own language's idiom, a PricingError, a KeyError, a returned
error, a shell test — plus the GPU refusing an allocation four times the size
of the card. Python's row carries the local variables from the failing frame,
which is the part you would otherwise be adding a print statement to find.
Your apps need almost nothing. Fourteen dependency-free SDKs: header-only
C++ (both a spdlog sink and a native snicholls::log one), plain C in
one stb-style header — zero-alloc, and a production build provably contains
no logging at all — a Rust
crate with an optional tracing layer, Python plugging into stdlib
logging, Go with a log/slog handler, Java with a java.util.logging
bridge (Kotlin and Scala ride it, one import, zero glue), Swift, Fortran
over raw POSIX sockets, OCaml over the same raw sockets, Haskell needing
only GHC's boot libraries and curl, Lean 4 for the proof jobs that run
all night (core IO plus curl — Lean grew a kernel before it grew
sockets), Perl from core modules alone (HTTP::Tiny has shipped with
Perl since 5.14), Lua making the same curl bargain as the shell SDK
(Lua never grew sockets at all), C# from the BCL alone — everywhere .NET
goes, including Unity profiles and Xbox Dev Mode — Zig through @cImport
of the C header itself, COBOL through a 20-line C shim onto the
header-only C SDK, Ruby from the stdlib — with a
drop-in ::Logger adapter, which makes the whole Rails story one
config.logger assignment — a sh one-liner for scripts, and one JS
client for React Native, the browser and Node — patchConsole: true and
every console.log is on the bench.
Six of them hook the logging framework the language already has — the
spdlog sink, logging.Handler, slog.Handler, java.util.logging.Handler,
Ruby's ::Logger adapter and patchConsole — so everything a program
already logs reaches the bench without a single call site changing.
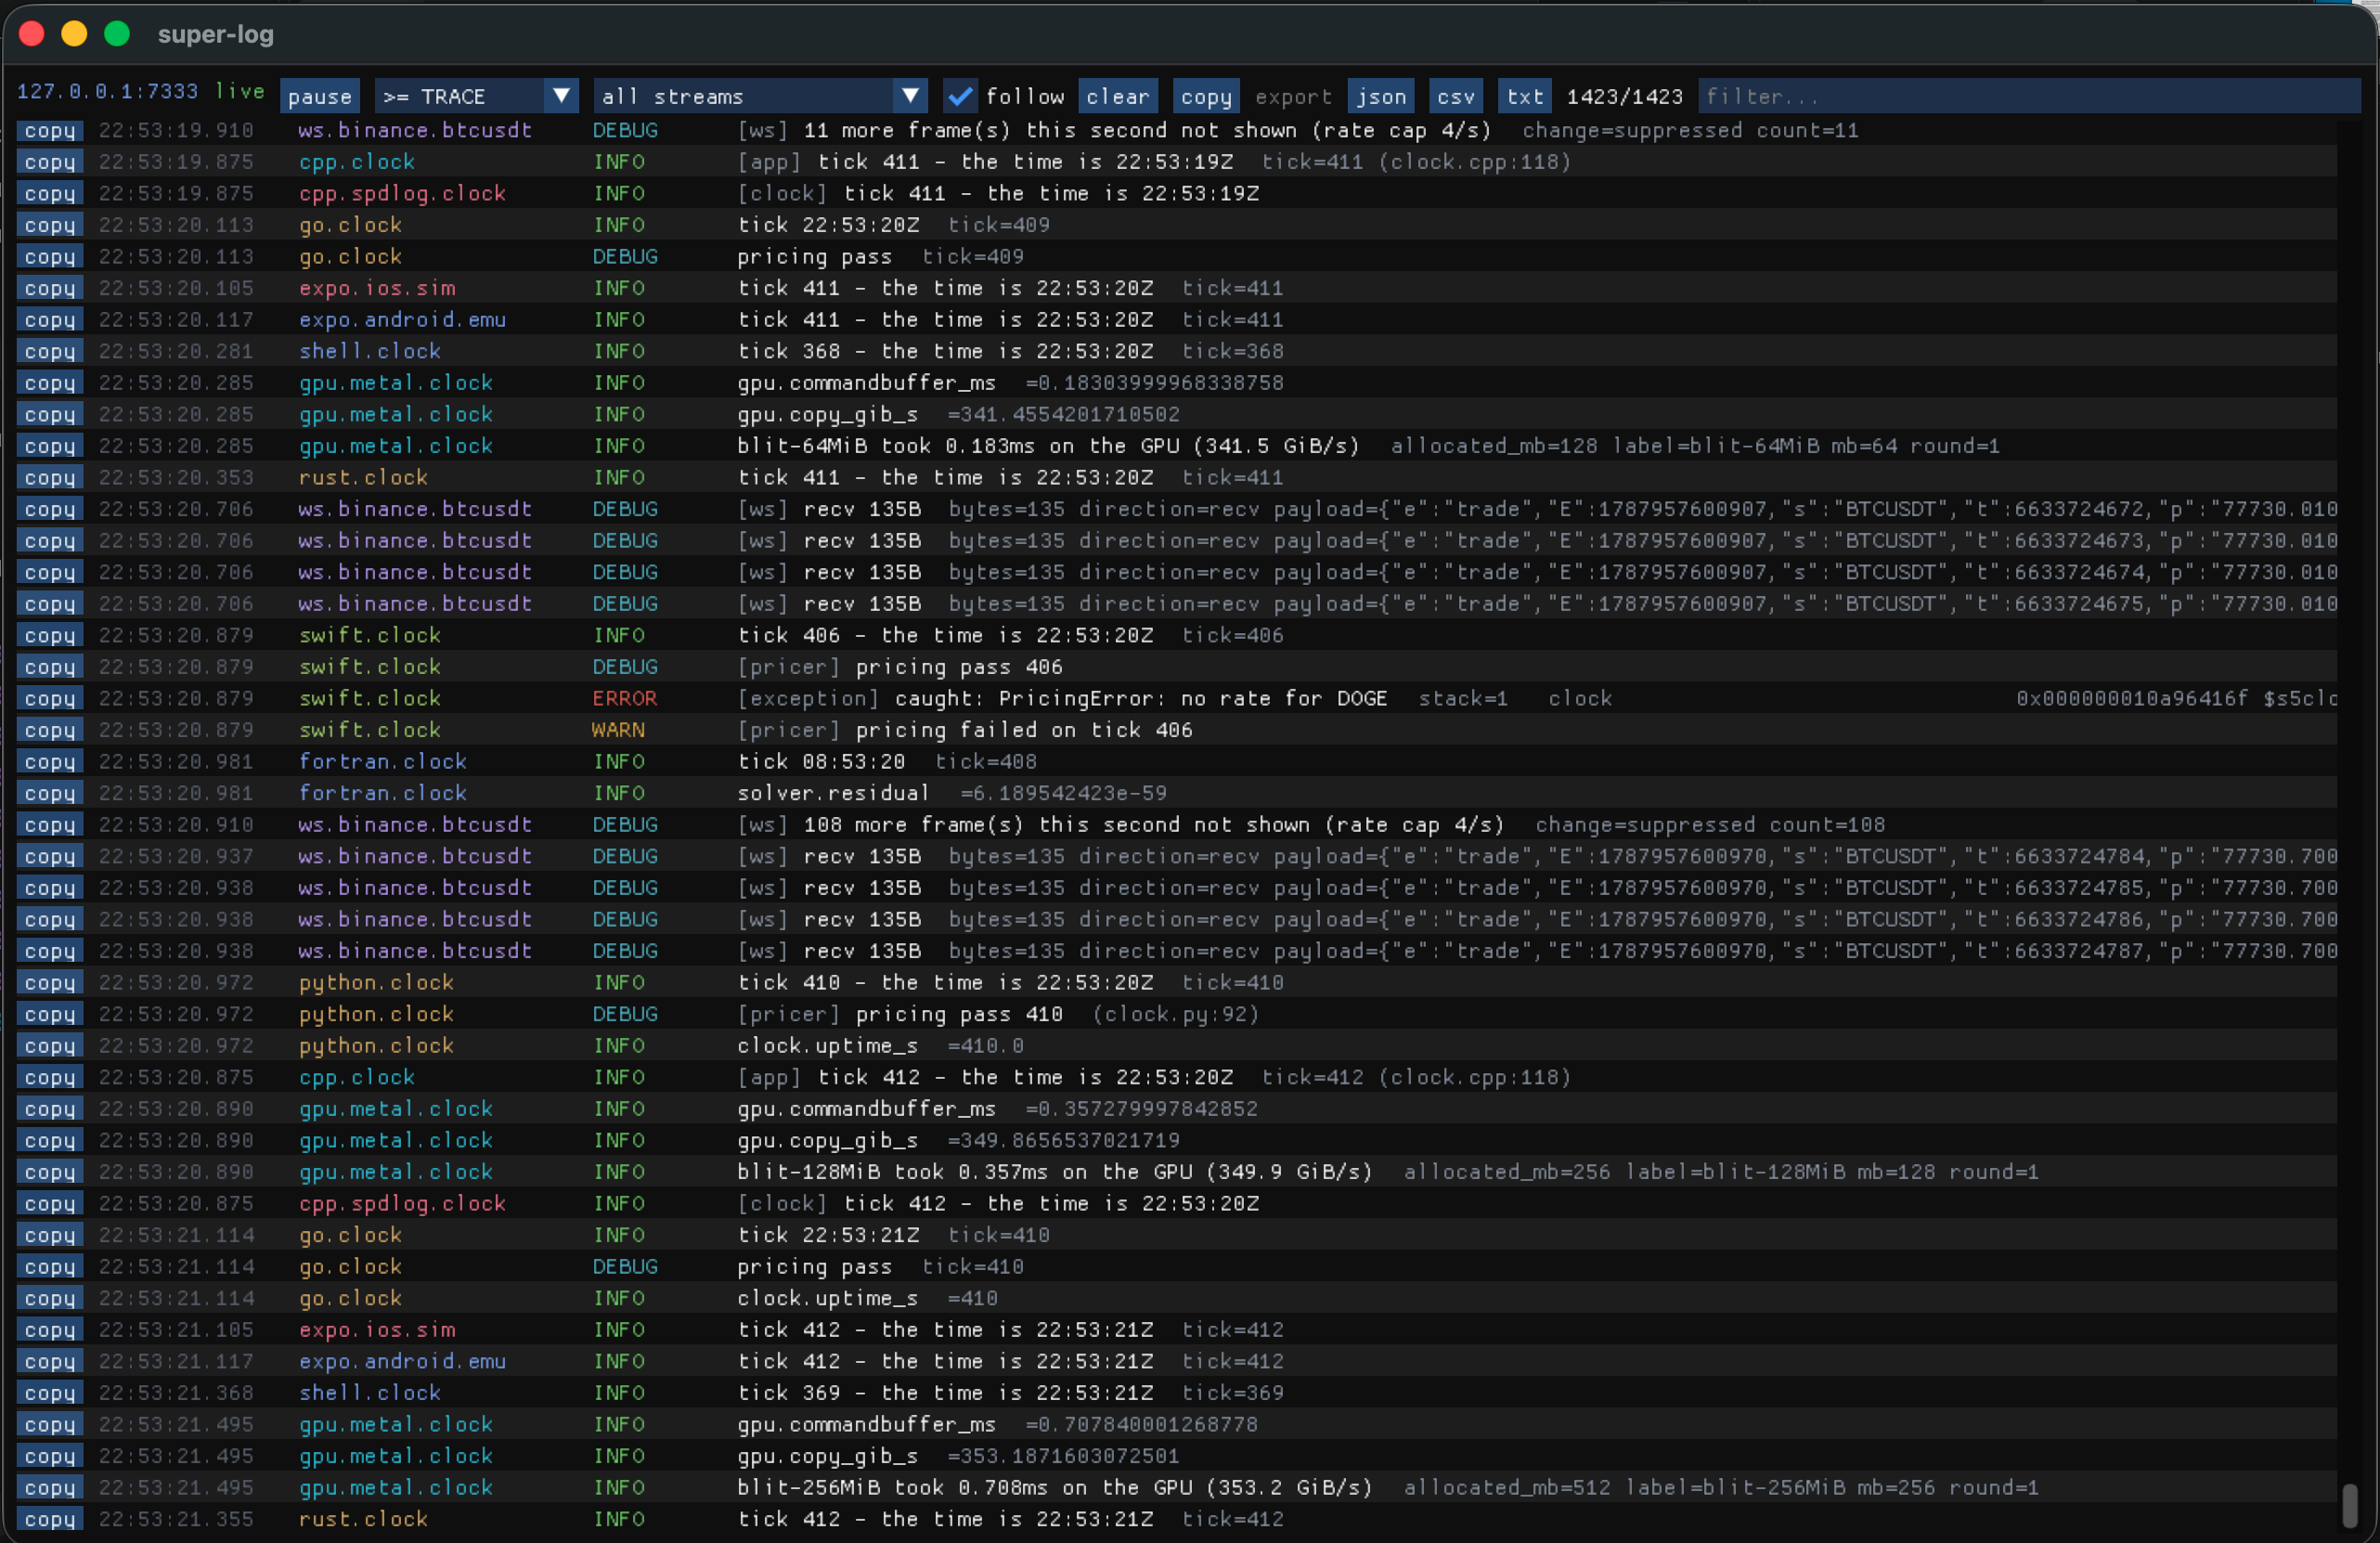
Why the interleaving is the point. In the middle, one Swift tick unfolds in order — the tick at INFO, a DEBUG pricing pass, the ERROR its exception raised, and the WARN that followed — while eleven other producers keep writing around it. Reconstructing that sequence from separate terminals is the ritual this replaces.
Follow one action across every tier. A tap becomes a request, a database
write and a chain call on four streams. withTrace() mints a correlation
id, carries it across awaits, and puts it on outbound HTTP automatically;
a server adopts it and logs under the same id. Then one query — a ⇢ in the
viewer, GET /recent?trace=…, or an agent tool — returns the whole story in
order.
Every error, including the ones nobody logged. Uncaught exceptions and
unhandled rejections are captured by default in every SDK, with whole
stacks — not clipped to the throw site, because a deep React Native render
error runs 100+ frames through the bridge and that path is the thing you
actually need to paste. Capture chains to whatever was already installed, so
React Native still shows its red box, Node still exits 1, and C++ still aborts.
C++ traces are demangled (pricer::Engine::quote(int)) with no boost
dependency. For the hardest class — an exception a library throws and a
component boundary catches and displays, so it never reaches the global
handler — wrap the tree in SuperLogErrorBoundary (or forward your own
boundary's componentDidCatch to log.exception): that lands the component
stack too, the one thing a JS stack never contains — it names the component
that threw. Plus an opt-in breadcrumb on every Error construction.
Zero-app-change fallbacks. Host-side tailers scrape what already exists:
adb logcat (scoped to one app, because an OEM handset emits ~600 lines a
second), the iOS simulator's log stream, the macOS unified log, journald,
Docker containers, and any log file. A catalog knows where ~20 common
services log on macOS and Linux — postgres, mysql, mongodb, redis, nginx,
apache, kafka, elasticsearch, rocksdb — including both Homebrew prefixes.
The catalog also knows the engines and content tools: Unity's
Editor.log (the C# compiler's error CS1234 becomes ERROR, a thrown
exception too, while a folder named "Exceptions" stays INFO) and Unreal
Engine's per-project editor logs (LogNet: Warning: maps by Unreal's own
verbosity words, category kept). Blender logs to stdout — that is what the
tee is for — and AutoCAD's LOGFILEMODE file tails like any other.
Whole fleets, pulled over ssh. One config file brings up every stream on every server: OS logs, service logs, container logs. Nothing is installed remotely, no port is opened, and the servers never need to reach the hub — so the hub can stay loopback-bound while still watching production.
HTTP calls, request and response. Front a service with the logging proxy
and every call is one event (method, path, status, latency, size), or turn
on patchNetwork in the app and see the calls it makes. HTTPS targets need
no certificate work. Bodies are opt-in; credentials are always redacted.
Blockchain addresses, beside the code that touched them. Watch any EVM address and its transfers, contract events and native balance moves land on the same screen, in hub order, next to the app code that sent them.
Operational keys that never silently run dry. A keeper or oracle out of
gas stops a production system as surely as a crashed server, and it fails
politely — it just stops, and nothing says why. superlog-gas polls the
balances you name (native coin or ERC-20, per chain, per key, from a
gitignored config — a labelled key list is a map for an attacker) and
applies the bench's discipline: readings are metric events for the chart,
crossing your fund-now line is CRITICAL said once, your low line WARN
once, and refunding is announced. One JSON-RPC batch per chain per poll,
because a public RPC's rate limit is part of the design surface.
Infrastructure that only speaks when something changes. DNS records and TLS expiry, listening ports and the processes that own them — all watched by diffing snapshots, so the stream is silent until it matters: an NS record you did not change, a certificate three weeks out, a new public listener on a production box, a service that restarted without saying so.
Builds as events, not walls of text. Wrap any build — cmake, clang, gcc,
cargo, npm, xcodebuild, local or over ssh — and compiler diagnostics become
WARN/ERROR rows with file:line, with one summary event carrying exit
status, duration and counts. Linking included: GNU ld's undefined reference and multiple definition carry no severity word and would
otherwise scroll past as INFO; they, Apple's Undefined symbols and
duplicate symbol, lld, collect2, and the driver's own
clang: error: linker command failed all land as ERROR. Debuggers ride the
same rails: pipe a batch session through the tee —
gdb --batch -ex run -ex bt ./app 2>&1 | superlog tee --topic dbg.app --classify
(lldb likewise) — or tail gdb's set logging file like any other.
Massive downloads, watched. A 70B model from Hugging Face is fifteen
shards and half a day of \r-rewritten progress bars that exist only on the
terminal that started them — and tqdm, curl and wget all mute or reshape
those bars the moment their output is a pipe, so tee sees nothing. Wrap
the fetch in superlog-dl and percent, bytes and rate become metric events;
or point --watch at the destination directory and progress is measured at
the filesystem, which no tool can mute and which is the only honest
aggregate when every shard resets its own bar. The event that matters most
is the stall: no bytes for 30 seconds is a WARN on the bench — hours
before the fetch's own patience runs out at 97% of 140GB.
Watts, thermals, and who is drawing them. On macOS every bench run
samples CPU package power, die temperatures, fan RPM, aggregate CPU as one
number, and the top energy consumers — because a runaway process announces
itself through the fans long after a chart would have caught it (see the
power row below for the incident that earned this).
The machine's own life events. Crash reports and kernel panics parsed
out of DiagnosticReports — process, exception, signal — the moment they
land (and from the recent past at startup, because a crash writes its
report before the reboot that restarts the watcher); the previous
shutdown cause once per boot, translated (cause -128: uncontrolled power loss) and ERROR when unclean; volume mounts, unmounts and renames — a
rename moves every path on the volume, which is how long writes die with
nothing recording why; and sleep/wake, which explains every gap in every
other stream. This bench crashed four times with all of that evidence
sitting unread; the first live run surfaced an unclean shutdown and 38
crashes from the preceding three days. The demo starts it unconditionally
on macOS, beside power.
Files, and the lines that changed. A generated header, a lock file a
tool rewrote, a config a script overwrote — superlog-watch puts the
change in the same ordered stream as the build that then failed, and with
--diff it says which lines: one event per hunk, removed and added
together, every hunk of a save sharing a trace with its modified event
so one query returns the whole edit. Idempotent by content hash — a
rewrite that changes no bytes publishes nothing, which an mtime watcher
cannot promise.
History, not just the last few minutes. The journal writes every frame
verbatim to disk; search reads it back with the same filters as the live
feed (including --trace), and replay re-publishes it at original pace.
A 1 GB / 4.8M-event journal searches in ~2.3 s.
Readable by scripts and agents. GET /recent?since=<cursor>&level=ERROR
answers "what happened since I last looked", with a cursor that never misses
or repeats an event.
An MCP server, so a coding agent can read the bench. Seven tools, and
the shape of them matters: an agent's context is small and a firehose is
not, so every tool filters first, caps its output, and returns one compact
line per event. The documentation is queryable too: stream_guide explains
any capability in detail — what power.*'s metrics mean, why a dl.*
stall escalates, why a diff can be silent — from
guide.json, and the same file's playbooks
(triage, follow-a-trace, silent-stream…) are served as native MCP prompts.
Every logging capability ships with an entry there, so an agent never has
to guess what a topic means.
| Tool | For |
|---|---|
hub_status | Is the bench even up — "hub is down" vs "the app logged nothing" |
list_streams | Orientation: which topics are live, their level mix, which have errors |
tail_logs | Recent events by topic/level/text, with a cursor so repeat calls only return what is new |
search_logs | Find by text when you know the message but not the stream |
search_history | The on-disk journal — hours or days, for "what happened at 3am" |
wait_for | Block until a matching event arrives, instead of sleeping and hoping |
list_webhooks | The alarm gateway's routes with public URLs and health — the URL to hand a webhook sender, without asking a human |
agent_report | Put yourself on theagents blotter: which LLM you run on, status, task, percent, and the cadence you promise — the one write this server performs, agent.* only |
stream_guide | The bench's own manual: detailed per-capability docs and playbooks, fetched on demand |
Registered once per machine, not per project: one hub serves every project
and agents narrow by topic prefix. Read-only by construction — with one
deliberate, narrow exception: agent telemetry, which can land only on
agent.* status topics (see the agents blotter below) — and
dependency-free — MCP over stdio is newline-delimited JSON-RPC 2.0.
Not just Claude — any MCP client. The same server drops into every
MCP-capable tool; the config is always npx -y @super-log/mcp:
Three ways to add it:
- MCP Registry — listed as
com.super-log/super-log, discoverable in-app and installable by name (claude mcp add com.super-log/super-log); it propagates to the Cursor / VS Code / Glama / PulseMCP catalogs on its own. - Claude Code plugin —
/plugin marketplace add saxonnicholls/super-logthen/plugin install super-log@super-log(adds the server and a/super-log:stream-guideskill). - Claude Desktop — double-click the
.mcpbfrom the release, no CLI.
Per-client setup for Cursor, VS Code, Cline, Windsurf, Zed, Continue, LibreChat and Gemini CLI — plus the OpenAI Agents SDK / Google ADK recipes — is in docs/CONNECT.md.
Already on OpenTelemetry? Join with one exporter stanza, no new SDK.
superlog-otlp is an OTLP/HTTP server on the standard 127.0.0.1:4318,
so pointing an existing exporter at it needs zero endpoint config:
OTEL_EXPORTER_OTLP_ENDPOINT=http://127.0.0.1:4318. It speaks both
OTLP/JSON and OTLP/protobuf (a hand-rolled bounded decoder, because most
SDKs default to protobuf), maps severityNumber to bench levels, and
turns each resource's service.name into an otlp.<service> topic. The
detail that makes it more than a gateway: an OTel span's trace_id
becomes the event's trace, so it lines up with withTrace()'s own ids
— one /recent?trace= returns the OTel spans and the bench's lines as a
single story. Metrics arrive as metric readings (histograms summarized
to count and sum, never invented percentiles); spans as trace-carrying
DEBUG events, because this is an inlet, not a span store.
And the reverse: feed your existing OpenTelemetry backend from the
bench. superlog-otlp-export reads the hub and POSTs OTLP/JSON to any
collector or vendor — superlog-otlp-export --endpoint https://otlp.example.com --header 'authorization: Bearer …'. Every event becomes an OTLP LogRecord
(the severity band inverted, service.name from origin.app, fields as
attributes, a 32-hex trace as traceId); a bench metric event becomes an
OTLP gauge point. JSON only, on purpose — it is what every collector accepts;
a backend that demands gRPC/protobuf is one OTel Collector hop away (see
docs/OTLP.md). The bench has no spans of its own, so traces are
not exported. Together the inlet and outlet make super-log a two-way OTLP
member of a bench, not a walled garden.
Something reaches you when nobody is watching. Rules over the live feed
fire through one channel registry — console, desktop, webhook, command
today; Telegram, Twilio SMS / WhatsApp and email are config-gated entries
in the same registry (superlog-alert --channels prints the roster and
exactly what each missing channel needs) — and back onto the bench as
alert.*. Four rule shapes, because production breaks in four ways:
something bad was logged, too much of it was logged, something
stopped being logged (a quiet server and a dead server look identical
until you check), and several things happened together — a combo
rule fires when all its conditions land inside one window, the correlation
("a deploy happened AND errors spiked") no single filter can say.
Production can raise the alarm, without logging a thing. Every SDK's
PRODUCTION mode ships nothing by design — but an ALARM is not logging, it
is a rare deliberate act, and superlog-alarm is its door: a token-guarded
public webhook through a Cloudflare tunnel — a quick tunnel with zero
config, or a stable named tunnel auto-provisioned via the API given a
token. Cloudflare is the verified, daily-driven path: quick tunnels, the
named tunnel, DNS provisioning and the endpoint factory all run against it
on a real bench. --tunnel ngrok and --tunnel zrok exist as code paths
but have not been driven the same way yet — see Future directions. One
curl from any language fires
alert.inbound.<name>; the same key re-firing is one alarm with a
repeat count, not 113 pages; recovery closes the loop; and every checker
can POST a heartbeat so the gateway itself raises monitor_dead:<name>
when a watcher goes silent — the alarm the dead watcher cannot send. Both
viewers carry an alarm blotter — a sparse panel, deliberately unlike
the firehose, one row per key — with a test-alarm button that proves
the whole path step by step: hub, tunnel, a real round-trip from the
internet back through the public URL, the notification channels (including
the diagnosis when your own router's DNS filters the tunnel's name while
production's resolves it fine), and then every route on the books, each
with its own verdict — a capture endpoint passes only when a probe posted
through its public URL lands back on the hub as a wh.<name> event, a
forwarded port that answers 502 is reported as "tunnel up, your service is
not", and a watch-only URL passes on any HTTP answer, because any answer
proves the wire.
And straight from code: SN_ALARM. The gateway is the door for a
production system across a network; for an alarm the running program itself
wants to raise — an assertion that should wake someone, a dependency gone dark —
every SDK has a first-class primitive that skips the log and lands in the
blotter directly:
The same call is in every language super-log speaks — sn_alarm(),
sn_alarm!, .alarm() and their kin — because an alarm you can only raise from
one language is a gap an incident finds. It emits on alert.native.<key>, which
the rules engine ignores by design (so it never trips a rule), keyed and
edge-triggered so a hot loop is one alarm and not a flood; CRITICAL fires it, an
INFO RECOVERED closes it. It posts straight to the hub — immediate and local;
the gateway's cross-process dedup and repeat-counting are for alarms that cross
a network. And it is deliberately not gated by PRODUCTION mode: an alarm you
asked for is the one thing that must not go quiet in production
(SUPER_LOG_ALARMS=0 mutes it if you must). Every demo client fires one so you
can watch it land.
The gateway is also an endpoint factory, and the viewers split its two
audiences: alarms (production) — the sparse blotter plus the alarm
path's own routes — and webhooks (development) — the endpoint grid and
a live feed of every captured delivery with its payload, signature verdict
and relay status. Both are toggled from a menu bar that the ImGui and
React viewers render from the same declarative
viewer/menu.json — alongside an agents blotter
(View → Agents): every agent working the bench, one row each — name,
which LLM it runs on, latest status, last seen. MCP consumers appear
the moment they connect (the server announces its own initialize
handshakes) and their tool calls show as requesting events; anything can
report via the agent_report MCP tool or one POST to agent.<name>,
declaring its LLM, task, percent, and the cadence it promises — every 15
minutes by default, plus on events, which is how an 8-hour job stays
visible. The freshness light is held to each agent's own promise:
green inside 2×, late, then silent — an agent that broke its own word
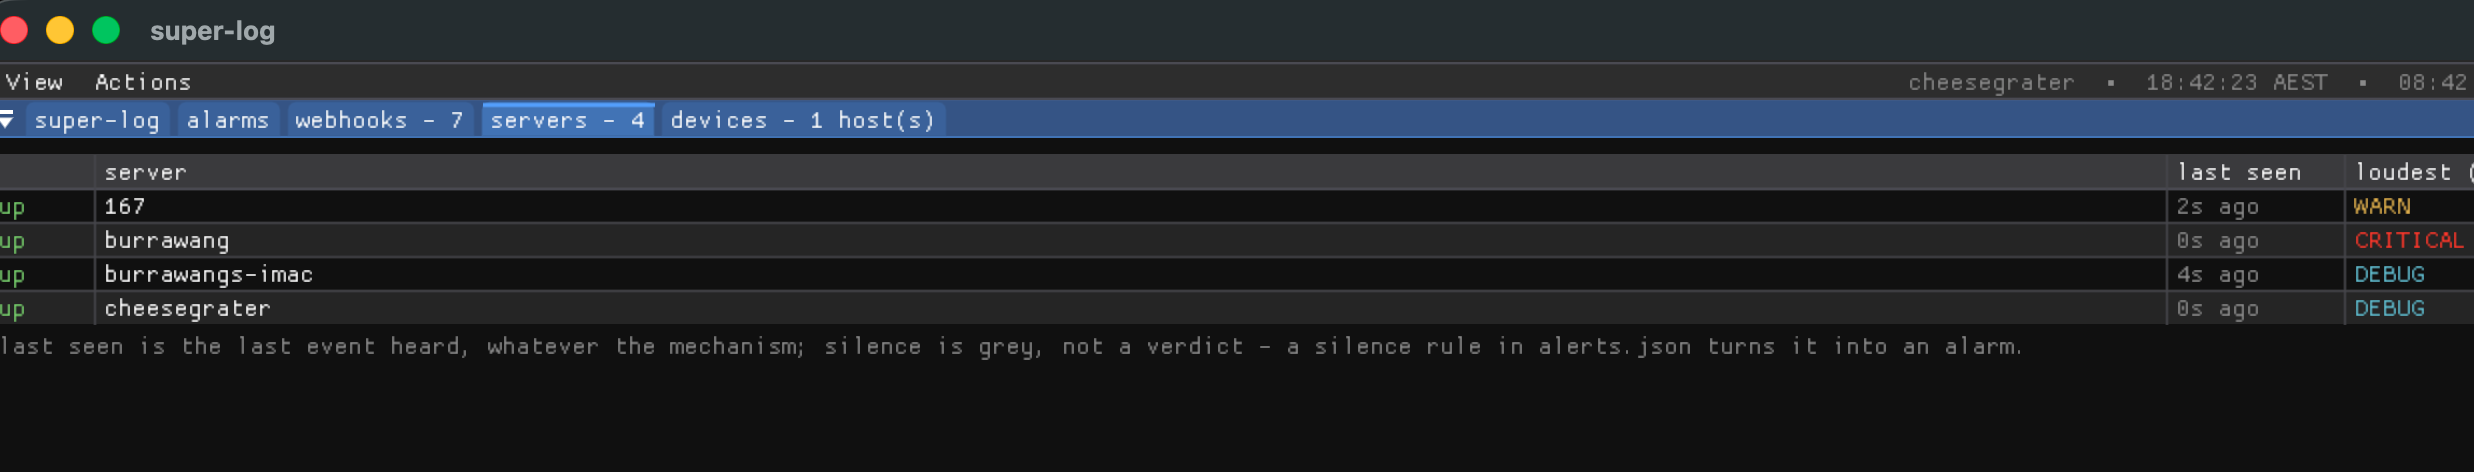
looks like it. And a servers board:
every event carries origin.device, so the hub's traffic is the server
list — one row per machine with a recency light (up / quiet /
silent), last seen, and the loudest level of the last minute,
whatever the mechanism that produced the events (a vitals reading, a ping
metric, an app's own SDK). "Is the build box fine" becomes one glance;
when the answer is grey, the detailed logs are one topic filter away in
the firehose — and a silence rule in alerts.json is what turns grey
into an alarm. Every route is a grid row —
status : route : url : seen : ping — expandable into full diagnostics,
with ping (measure this route now, on the same watchdog books),
copy (the full public URL) and delete buttons, each route pinged on
its own configurable clock (two consecutive failures raises
tunnel_down:<name>, recovery clears it). + endpoint provisions in
one click — a name alone captures deliveries as wh.<name> events (paste
the URL into a Stripe or GitHub webhook form and watch them arrive), a
name plus port forwards a local service. Many endpoints live better in a
file: npm run alarm -- --provision endpoints.json applies a declarative
manifest ({"name":"stripe"} capture, {"name":"webapp","port":5173}
forward, {"name":"partner","url":"https://…"} watch-only, each with
optional interval_s) and keeps it applied as the file changes — new names
appear, removed names are torn down, though only names the file created.
endpoints.json.example shows every shape; the
real file is gitignored because names, ports and signing secrets describe
the bench. Every URL the gateway currently owns is rewritten to
endpoints.env (gitignored) on every change, so scripts and agents
can simply source it — and agents can also just ask: the MCP server's
list_webhooks returns the roster with public URLs and health.
Webhook testing, done properly — Stripe as the worked example. A
capture endpoint alone is already a webhook inspector: paste its URL into
the Stripe dashboard (or stripe trigger payment_intent.succeeded at it),
and every delivery lands as a wh.stripe event with method, headers
(stripe-signature kept) and up to 32KB of body — a real invoice event
runs 5–15KB and arrives whole. Two additions make it a development tool
rather than a peephole. Give the endpoint your signing secret
("secret":"whsec_..." in the manifest, or STRIPE_WEBHOOK_SECRET) and
the gateway verifies the Stripe signature scheme on arrival: each
event carries sig: verified or sig: FAILED (WARN), with stale
timestamps flagged as possible replays — and no secret means the field
stays absent, never a fake verdict. Give it a relay
({"name":"stripe","relay":5000} or a full URL like
http://127.0.0.1:5000/webhook) and each delivery is also handed to your
local handler, whose real response goes back to Stripe — stripe listen --forward-to, except every delivery, signature verdict and your
handler's status code are on the bench, in order, beside your app's own
logs. A handler that is down shows up as relay unreachable at WARN — the
exact finding a webhook test exists to produce. (local: true skips the
tunnel entirely when the bench only needs to test against itself.)
GitHub's scheme (x-hub-signature-256) verifies beside Stripe's against
the same secret; other providers are one clause each.
The webhooks panel's deliveries feed is built for reading the results: filter by endpoint and by level exactly like the main log (WARN isolates the failed signatures and unreachable relays), expand any delivery's payload in place, and copy — one button per delivery, one for the whole filtered set — hands you paste-able evidence: the feed line, the signature and relay verdicts, then the payload verbatim. The whole loop is exercised end-to-end with the Stripe CLI:
Producers never block. Every SDK uses a bounded queue that drops oldest under burst — counted, never hidden. A logger that can stall the app it observes is worse than no logger.
Off in production, by construction. Every SDK requires you to declare DEVELOPMENT or PRODUCTION (neither or both refuses to build), and each mode ships only what its policy allows. Production defaults to nothing.
What this is, and what it is not
It is a development tool. The bench you sit at: everything your machine and your devices are saying, on one screen, in the order it happened, while you are working. It is optimised for the ten seconds after something breaks — one hub, no schema to declare, no agent to install, a stream added by typing one command, and nothing to configure before the first line appears.
It is not an observability suite, and should not be used as one. The distinction is not modesty, it is design: several things that make it good at the first job make it unfit for the second.
| super-log | Prometheus / Grafana / Loki / Datadog | |
|---|---|---|
| Lives | on your machine, while you work | in production, permanently |
| Retention | a ring in memory, plus a journal you turn on | months, indexed, queryable |
| Auth | none — loopback by default | tenants, RBAC, audit |
| Scale | one bench, a handful of servers | thousands of hosts |
| Alerting | rules for "tell me while I am here" | on-call, escalation, SLOs |
| Cost of adding a stream | one command | a pipeline change |
Concretely, do not point this at production and walk away. The hub has
no authentication: anyone who can reach the port can read every stream and
publish to any topic. It keeps 2000 events per topic in memory and forgets
the rest unless the journal is running. Throughput, though, is not the
limit that stops you: on one developer machine a single hub ingested a
250-machine fleet's burst — 500,000 events in 2.3 seconds (~217,000
events/second, 67 MB/s), none dropped — and a level-filtered /recent
still answered in 16 ms while it arrived
(bench/loadtest.mjs — reproduce it yourself against a
throwaway hub). What makes it unfit for production is the two sentences above,
no auth and an in-memory ring, not the ingest path.
What it is fair to do in production is pull: the ssh tailer and the fleet runner read remote logs onto your bench over ssh, so production never needs to reach the hub and the hub never needs to be exposed. That is how the fleet support is meant to be used.
When you outgrow it, you have not wasted anything — the wire format is NDJSON on plain HTTP (see docs/PROTOCOL.md), so a forwarder into Loki, Elasticsearch or an OTLP collector is a small script that subscribes to the firehose and re-posts. The two tools answer different questions and it is reasonable to run both: this one for "what is happening right now while I am looking", that one for "what happened last Tuesday at three in the morning".
Collection is not analysis — and that is the whole design
super-log does one thing: it collects and consolidates. Every stream a bench produces, on one wire, in one order, on one screen. It deliberately does not analyse — no query language, no dashboards to build, no rules engine you must program before the first insight. That separation is not a missing feature; it is the point. Collection should be dumb, fast, and trustworthy; analysis is a different job with different tools, and coupling the two is how logging stacks become the thing you have to operate instead of the thing that helps you operate.
This is the opposite of the log4j lesson. The Java logging world put a large, powerful, evaluating framework inside every application — and in 2021 the world learned what that costs, when a string in a log message became remote code execution (log4shell) across half the internet. The framework that was supposed to observe the app could compromise it. super-log inverts every part of that:
- Logging lives outside the app. A super-log producer is a thin, zero-dependency SDK — often just one file, or no code at all: point an existing OpenTelemetry exporter at it, or tail a file. There is no heavy framework in your process to be a liability.
- Content is data, never code. Every parser on the collection side is bounded and treats input as bytes to be stored, never expressions to be evaluated — the log4shell class of bug is structurally impossible here.
- Production ships nothing by default. Every SDK is DEVELOPMENT-xor-
PRODUCTION, and PRODUCTION is an inert shell that sends nothing until you
opt a level in — the compiled languages compile the wire code out
entirely, provably (
stringsfinds no endpoint in the binary).
So the app stays simple and safe, the bench stays a bench, and what you do with the consolidated stream is a clean, separate choice — eyeball it, forward it to your long-term store, or hand it to something that reasons about it.
super-log.com — analysis and AI, for teams
The open-source bench is the collection and consolidation layer, free and self-hosted, forever. super-log.com is the analysis layer built on top of it — the commercial service for when a consolidated stream is more than one person can watch:
- Real-time LLM analysis of the consolidated log. An AI reads the whole interleaved firehose as it happens — every service, device and chain at once — and tells you what changed, what correlates, and what is about to break, in the plain-language a teammate would use. The thing a human does in the ten seconds after something breaks, done continuously across streams no human can watch all of.
- Built for teams. One consolidated view of everyone's benches and services, shared context, history that outlives a laptop, and alerting that reaches the person who can fix it. The servers, agents and PR boards in the open-source viewers hint at the shape; the hosted service makes them a shared, durable, analysed surface.
- Same clean boundary. super-log.com consumes the exact same NDJSON wire the open-source hub speaks — nothing new to instrument. Your collection stays yours and self-hosted; you choose to send a stream up for analysis, and you can stop at any time. Collection and analysis stay separate all the way through.
The open-source project is complete and useful on its own — the commercial service is analysis you would otherwise build, not a paywall around the bench.
Install
The fastest way onto the bench — Homebrew — and a runnable example in the same breath:
Other channels, each landing the hub and the tailers:
Pick the .deb for your architecture (dpkg --print-architecture). On a
systemd host the hub starts on install; in a container without systemd, run
superlogd yourself.
On install the hub binds loopback (127.0.0.1) — right for a dev box, but
if this machine is the collector other devices ship logs to over the LAN (a
common Raspberry Pi role), they cannot reach it until you bind the network: set
SUPER_LOG_LAN=1 (or SUPER_LOG_BIND=0.0.0.0) in the service environment and
restart superlogd. The failure is silent at both ends — the device shows
"never reported" and the hub logs nothing — so if you are standing one up as a
LAN sink, see docs/DEVICES.md for the "loopback trap" and how
to make the LAN binding persist across restarts.
The MCP server also runs straight from npx, no install:
claude mcp add super-log -- npx -y @super-log/mcp. The viewers (native
and web) come with a clone — see Quick start below. Packaging sources and
the maintainer publish steps live in packaging/.
Quick start (from a clone)
The demo binds to loopback. Real phones need the hub on the LAN:
SUPER_LOG_LAN=1 ./demo/run.sh — read the security section first. The
viewer finds the hub from the host that served the page, so opening it from
another machine needs no configuration.
Configuration files
Most streams need no config — you just run them. A handful that carry
secrets (API keys, RPC URLs with keys, wallet addresses, tokens) read
a file that is gitignored, so your credentials never reach a commit.
Every one ships a .example twin beside it: copy, then edit. That's the
whole ritual — cp <name>.example <name>, fill in your values, run.
| Copy this → to this | For | What goes in it |
|---|---|---|
.env.example → .env | the hub, chains, alarms, and every API-keyed tailer | Hub URL/bind, chain RPC endpoints, Cloudflare/Stripe/Twilio/Telegram creds, PR logins, Starlink dish, notification channels — each block is commented, and anything left blank is simply not watched. |
rpc.json.example → rpc.json | npm run rpc — RPC node health | Per chain,per provider, a {chain, provider, url, kind?}. Two providers per chain (a QuickNode and an Alchemy) is the point — the board shows which one died. The URL shapes are pre-filled; paste your key. |
gas.json.example → gas.json | npm run gas — key balance / fund-now alarms | Per chain, the operational keys to watch withcrit/warn thresholds. EVM, Solana, Tron, Bitcoin (kind). A labelled key list is a map for an attacker even when the addresses are public — hence gitignored. |
alerts.json.example → alerts.json | npm run alert — rules over the bench | Rules: something bad logged, too much logged, a stream went silent, or a combo of conditions in one window — plus the notification channels to fire. |
endpoints.json.example → endpoints.json | npm run alarm — the webhook endpoint factory | The public endpoints to provision declaratively: capture, relay, forward, or watch-only — Stripe/GitHub webhook testing included. |
fleet.json.example → fleet.json | npm run fleet — many machines at once | Describe a fleet of hosts (ssh, OS logs, docker, files) once; one supervisor starts every stream and restarts any that die. |
Config-free by design — nothing to create: the servers, devices
(USB), agents and PRs boards derive from the hub's own traffic or
a gh/env setting, and the OS/app/network tailers take command-line flags.
If a tailer needs a file it can't find, it tells you the exact cp line
and stops — it never runs half-configured.
Installing it in a project
Clone it once, use it from every project. super-log is not a dependency you add to a repo — it is a tool you install on a machine, like a debugger. The hub is machine-wide and shared: one per bench, every project on it. Two hubs would be two ports competing and two viewers each showing a third of the picture.
That also keeps your repo clean, and it avoids a real cost — a Cargo git dependency on this repo clones all five submodules and 36 MB of C++ that the Rust crate never touches.
Then, per project:
That writes exactly two files into your project and touches nothing else:
| File | What |
|---|---|
superlog.conf | what this project logs — the only file you edit |
logging.sh | a self-contained POSIX-sh launcher, ~250 lines |
.superlog/ (pids and logs) is added to your .gitignore. The project type
is detected, so the config arrives pre-filled rather than blank — a
package.json gets npm run build, a CMakeLists.txt gets
cmake --build build -j, and so on.
Booting it with your build and run is the point of the last two commands. They start the logging first if it is not already up, so wiring them into what you already type is all it takes:
build runs through the build wrapper, so warnings and errors arrive as
WARN/ERROR with file:line, and sanitizer or valgrind findings arrive
whole. run runs through superlog-tee, so stdout reaches your terminal
byte for byte and the bench at the same time. Either is a drop-in for the
command it wraps — alias b='./logging.sh build', or setup.sh --wire to
add npm run log / log:stop / log:status to a Node project.
Sharing one bench between projects works the way you would hope. The
second project's start finds the hub and viewer already up and only adds
its own streams; each project's topics carry its own prefix, so they stay
separable in the viewer; and stopping one project leaves the others running.
If you would rather wire an SDK into your code directly instead of watching from outside, that is the next section — but you do not have to, and for most projects the launcher is enough to see everything.
Putting your own apps on the bench
React Native / browser / Node (@super-log/client, zero dependencies):
React trees can wrap once with @super-log/react:
<SuperLogProvider> owns the client and an error boundary that logs the
component stack — which a global handler can never see, because React
swallows render errors.
C++ (header-only; compile with -DSUPERLOG_DEVELOPMENT or
-DSUPERLOG_PRODUCTION):
Plain C (one header, stb-style; the same two macros, and PRODUCTION
compiles every call to nothing — strings the binary for /ingest/ to
prove the logger absent, rather than trusting a flag):
Python (standard library only; development= / production=, exactly one):
Python gets two things the other SDKs cannot. logging.Handler means every
line the program already logs reaches the bench with no call-site changes.
And capture_locals attaches the local variables of the failing frames, so
an exception says symbol='DOGE', n=7 rather than only where it happened —
secret-looking names are redacted and values truncated.
Go (a log/slog handler, so existing calls need no changes):
Trace lives in context.Context rather than a goroutine-local, because Go
deliberately has none — so the id travels exactly where the context does.
Recover logs the panic and re-panics: a logger that swallows a crash has
changed the program it was meant to observe.
Java and Kotlin (java.util.logging bridge; InheritableThreadLocal
trace, so a pooled task inherits its submitter's id):
Swift (@TaskLocal trace, inherited by child tasks):
There is deliberately no setTrace(): a TaskLocal binds to a scope and
nothing else, which makes the usual leak — one request's id surviving into
the next — impossible to express rather than merely discouraged.
Fortran (raw POSIX sockets through ISO_C_BINDING, no libcurl):
A solver is the hardest program on the bench to observe: hours long, often
somewhere you cannot attach, and the evidence is a slurm file nobody reads
until the allocation is spent. DEVELOPMENT xor PRODUCTION is a
preprocessor error like the C++ SDK, and SIGPIPE is ignored at init so a
hub that goes away cannot kill a run twelve hours in.
Shell (any script, one line):
Rust (build with --features development or --features production):
Ruby, and therefore Rails (stdlib only; mode from SUPERLOG_MODE):
Scala (no SDK, on purpose — the Java client, one import, zero glue, exactly as Kotlin uses it):
OCaml (the unix library and nothing else; mode from SUPERLOG_MODE):
Haskell (GHC's boot libraries plus curl; the mode is compiled in —
-DDEVELOPMENT or -DPRODUCTION, neither or both refuses to build):
Lean 4 (core IO plus curl; mode from SUPERLOG_MODE — proof search
runs all night, and a metric per thousand goals beats a silent terminal.
superlog-build -- lake build covers the build itself, with lake's
[n/m] progress as a chartable build.progress_pct):
C# (BCL only — HttpClient and System.Text.Json ship with .NET;
mode from SUPERLOG_MODE). One file into any project: a console app,
ASP.NET, a Unity project on a .NET profile, an Xbox Dev Mode build:
Perl (core modules only — HTTP::Tiny and JSON::PP ship with Perl;
mode from SUPERLOG_MODE), for the glue scripts and cron jobs that run
half the world:
Lua (any Lua 5.1+, PUC or LuaJIT; no sockets in Lua's stdlib, so it makes the same honest curl bargain the shell SDK makes):
COBOL (yes, really — GnuCOBOL CALLs the header-only C SDK through
demo/cobol/shim.c, ~20 lines, so the oldest business
language on the bench inherits the C SDK whole, provably-compiled-out
production included):
Zig needs even less: @cImport reads sdk/c/superlog.h directly
(see demo/zig/clock.zig), with the header compiled
once for the linker — cc -DSUPERLOG_API= -c impl.c — which is the same
one-object route any language with a C FFI can take.
Machines, services, containers, chains (no app changes at all):
Infrastructure watches
dns, ports and netstate diff a snapshot rather than streaming, so
the first poll is a silent baseline and only changes are reported — a
watcher that announces everything it sees teaches you to ignore it. The rest publish
readings as DEBUG metric events and raise their voice only on
edge-triggered crossings.
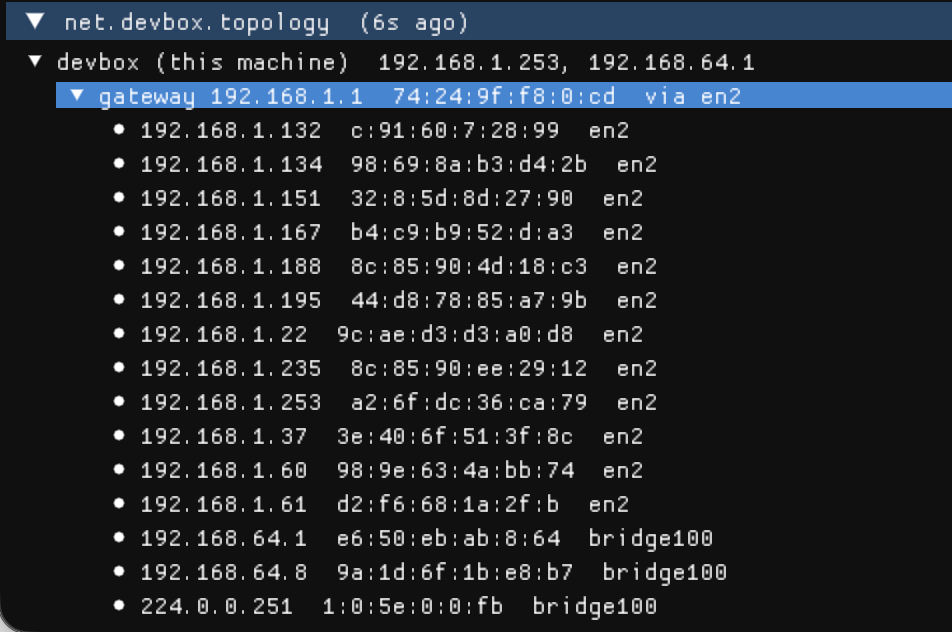
superlog-topology renders the LAN as a tree — this host and its addresses,
the gateway, and every device under it — in its own window in both viewers.
--discover sweeps the subnet so devices the machine hasn't talked to still
appear; --to <target> adds a watched route with per-hop RTT and AS/owner.
| Watch | Publishes | Notable levels |
|---|---|---|
dns | dns.<domain> — A, AAAA, NS, MX, TXT, CAA and the TLS certificate; with --asn, which AS originates each domain's prefix (via RIPEstat) | NS/CAA change is WARN (you probably did not do it; it is how a domain gets taken), a record type vanishing is ERROR, certs go WARN at 3 weeks → ERROR at 1 → CRITICAL once expired. TXT changes are named by kind, so it says "SPF/DMARC record changed" rather than making you diff two long strings. The origin AS changing or the prefix vanishing is CRITICAL — a bench has no BGP view, but RIPEstat does, and from outside that is what a hijack looks like. |
ports | net.<host>.listeners — listening sockets, owning process, pid, and firewall rules | Anew listener on a public address is WARN, the same on loopback is INFO; a listener disappearing is WARN; a pid change is reported as a restart rather than as one service vanishing and another appearing; a watched process going missing is ERROR. |
connections | net.<host>.connections — the outbound complement of ports: which local process holds a connection to which remote endpoint, as a process → endpoint tree (from ss on Linux, lsof on macOS), a periodic DEBUG structural reading. --ssh watches a remote box. | A socketstuck in SYN-SENT across two polls is WARN — the SYN went out and nothing came back, so the port is filtered/dropped or the service is down, the exact hang a dev burns an afternoon on (a refused port RSTs instantly and never hangs; the filtered one is what is pollable). Reaching it recovers (INFO); first contact with a remote host is one INFO — the "is my app pointed at dev or prod" answer. |
vitals | host.<name>.vitals — disk, memory, CPU and load, macOS/Linux/Windows | Readings are DEBUGmetric events (always there for a chart, out of a default INFO view); threshold crossings are edge-triggered WARN/ERROR, so 85% says so once rather than every poll, and recovery says so too. Read-only filesystems are skipped: a macOS simulator runtime is 98% full by design, and alerting on it produced 25 false ERRORs before this rule existed. |
build | build.<host>.<label> — one event per diagnostic, one verdict | Compiler errors are ERROR withfile:line; a build that exits 0 while reporting errors is WARN, not success, because that usually means a ; where && was meant — and a build that reports errors and calls itself fine is how a broken artefact ships. |
watch | fs.<host>.<dir> — files created (INFO), modified (INFO), deleted (WARN); bursts collapse to one summary; with --diff, the changed lines as one event per hunk | Hunks carry the removed and added lines together, and every hunk of one save shares atrace with its "modified" anchor — /recent?trace= returns the whole edit as one story. Idempotent by content hash: an editor's mtime touch or an atomic re-save of identical bytes publishes nothing at all. The diff anchors on lines unique to both sides, so a moved brace does not smear a one-line config edit across the file; binaries and files over --diff-max are tracked by hash alone and say so (undiffable), never pretended about. |
power | power.<host> — CPU package watts, thermal pressure, fan RPM, CPU/GPU die temperatures, aggregate CPU as one number, and the top energy consumers attached to every sample; macOS | Exists because this machine sat at1258% aggregate CPU — eleven saturated cores, one VS Code extension — unnoticed until the fans got loud and kernel_task began throttling, and has crashed under runaway draw. "Too much" is machine-relative, so three detectors: absolute watt caps if you set them, sustained draw above the machine's own learned baseline, and the machine's own verdict (thermal pressure / CPU speed limit), which needs no tuning at all. Watts require root — sudo scripts/install-power-tailer.sh grants exactly one pinned powermetrics invocation, nothing else — and without root it still publishes thermals, aggregate CPU and top processes, each reading marked power_unavailable: not root. The demo starts it unconditionally on macOS. |
dl | dl.<host>.<label> — a download in flight: percent, bytes and rate as metric events, plus one verdict when it ends | |
otlp | otlp.<service> — the OpenTelemetry inlet: anything OTel-instrumented joins the bench with no new SDK, just one exporter stanza. An OTLP/HTTP server on 127.0.0.1:4318 (the standard port, so exporters need zero endpoint config) takes /v1/logs, /v1/metrics and /v1/traces in both OTLP/JSON and OTLP/protobuf (a hand-rolled bounded decoder — most SDKs default to protobuf). severityNumber maps to bench levels, service.name becomes the topic, and trace_id becomes the event's trace — so an OTel span and a withTrace() line share one id and /recent?trace= returns both. Metrics land as metric readings (histograms summarized, never invented percentiles); spans as trace-carrying DEBUG events. | The bridge for a team already on OpenTelemetry: their existing instrumentation shows up on the bench beside everything else, and its trace ids line up with the bench's own — no second SDK, no re-instrumenting. |
starlink | starlink.dishy — the dish itself, over its LAN gRPC API (grpcurl + server reflection carry the wire): pop latency, drop rate, up/down throughput, obstruction fraction and GPS sats as metric readings; every alert flag (thermal throttle, motors stuck…), obstruction, firmware updates, reboots and unreachability as edge-triggered events with recovery. | Paired withnetstate's gateway watch, three failures that look identical from a spinning browser separate cleanly: the dish is down, the router is down, or the path is merely degraded. A missing reading stays absent — a dish that reports no drop rate did not report zero drops. |
rpc | rpc.<chain> — RPC node endpoint health: block height and latency per provider as metric readings, and the two failures that kill a chain integration quietly — DOWN (no answer, ERROR after two misses) and STALLED (still answering, but the block froze — WARN, the failure a naive health check misses). Four dialects — EVM, Solana, Tron, Bitcoin (Esplora). | You run more than one provider per chain (a QuickNodeand an Alchemy) so one can die without taking you with it — but only if you can see which one died. Both viewers carry an RPC board: chain, provider, url, block, latency, last-seen, health, one row per endpoint. |
prs | pr.<owner>.<repo> — pull requests, watched for the one state that quietly kills them: waiting on us. Every open PR by your configured GitHub logins anywhere (your PR in someone else's repo included), plus open PRs on repos you tend, plus your recently closed ones. Whose move it is comes from the record — the last non-bot word — with days_waiting as a chartable metric. Crossing --warn-days (default 3) is one WARN, 3× is one ERROR, a reply is a recovery — and each crossing fires the alarm gateway (dedup key pr:<repo>#<n>, notification channels included). Closed without merge is an ERROR, because that is what "closed as stale" looks like from outside. Both viewers carry a PRs board sorted ours-and-oldest first — the sort order is the to-do list. | Born from a real failure: a reviewer requested changes, the request sat unanswered for 51 days, and the PR was closed as stale. Nobody rejected it — it aged out, invisibly.gh carries the wire, auth included. |
usb | usb.<host> — the machine's USB device tree (ioreg's USB plane on macOS, lsusb on Linux): hotplug as snapshot-diffed INFO events, the whole tree riding fields.tree on every change. Both viewers carry a Devices window that renders it live and headlines handsets — 📱 iPhone — connected (mymac), or UNPLUGGED 40s ago, because absence must be as visible as presence. A refresh button pokes the local tailer (loopback POST :7338/poll) to measure now; otherwise everything updates within one 5s poll of plugging in. | The problem being solved is one every device developer knows: "adb can't see the device" and "Xcode lost the phone" both start withis it even connected, and the answer should not require a terminal. The demo starts it unconditionally on macOS. |
fix | fix.<session> — FIX session logs, decoded. QuickFIX, FIX8, or any engine that writes the standard message log speaks SOH-delimited tag=value, one message per line, and this follows those logs by name (tail -F, so a logrotate can't silently end the stream). MsgType (tag 35) is the verb, and the levelling is the point, because a FIX session fails quietly: a Reject / BusinessMessageReject is ERROR with its reason (the Text field) and the offending RefTagID; an ExecutionReport is INFO for a fill but ERROR when it reports a rejected order — the one 8 you must not miss among the ones you can; a Logout, SequenceReset or ResendRequest is WARN (the session that quietly stopped filling); a Heartbeat is DEBUG. ClOrdID, Symbol, Side, OrderQty, Price and OrdStatus ride as fields; the topic is fix.<begin>-<sender>-<target>, derived from the message and not the filename, so several sessions in one log separate cleanly. | A rejected order or a mid-day logout is one line in an engine's message log, buried in a wall of heartbeats, at the exact moment money is on the line — and nobody is tailing that file right then. The tolerant reader also accepts pipe / caret-A delimiters and a leading local-timestamp prefix, so a copied-out message still decodes; checksums aren't re-validated because the engine already did. |
mavlink | mavlink.<sysid> — a drone's telemetry, decoded. ArduPilot and PX4 speak MAVLink, and the failures that end a flight — a battery falling past the reserve, a lost GPS fix, an EKF failsafe, a link that goes quiet — are in that binary stream and nowhere else, shown by a ground station for one second before the next frame scrolls them away. This binds the UDP stream a GCS/SITL forwards (or replays a .tlog), decodes v1 and v2 frames CRC-checked (a byte that merely looks like a start-of-frame can't become a phantom message), and keeps the bench discipline: battery and satellites are DEBUG metric readings; a low battery (--batt-warn/--batt-crit %), a lost 3D fix, an EMERGENCY system status and a link that stops heart-beating are edge-triggered WARN/ERROR that announce recovery; mode and arm changes are one INFO; and the flight controller's own STATUSTEXT rides through at its MAV_SEVERITY (EKF failsafe arrives an ERROR because the autopilot said so). No config — MAVLink is self-describing. | The robotics bench's version of "is it even connected": a drone's health lives in a protocol no log tool reads, so it never reaches the one screen with everything else. Tested without a drone — hand-encoded real-CRC frames — so the decoder is proven, not hoped. |
netstate | net.<host>.state — the network's own state, diffed: interface addresses, default gateway, Wi-Fi SSID, VPN tunnels, the DNS resolver set, and the ARP neighbourhood with judgment — a new LAN device is one INFO at first sight, cache expiry is silence, and the gateway's MAC changing is ERROR, because that is a router swap or an ARP-spoofing MITM. --ping targets (the gateway rides free) publish RTT and loss as metric readings with edge-triggered degradation alarms — and at the moment a target crosses the edge, one traceroute runs and lands beside the alarm on the same trace: the alarm arrives carrying its own diagnosis. | Half of "everything just broke" on a dev bench is the network moving underneath the developer — VPN dropped, DHCP renumbered, captive portal swapped the resolvers — and none of it says so anywhere. This bench lost a live debugging round to a router quietly filtering a tunnel's DNS name; a resolver-change event would have flagged it instantly.The demo starts it unconditionally on macOS. |
topology | net.<host>.topology (+ net.<host>.route.<target>) — the local network as a tree, in its own viewer window: this host and its addresses, the gateway, and the devices under it, rendered like the USB device tree. The ARP table only holds what this machine has talked to, so --discover ping-sweeps the /24 to show the rest (opt-in — it puts a packet on every host). Point --to <target> at a server (or --ssh from a client) and the route is watched over time: per-hop RTT is a DEBUG reading, but a target going unreachable is an edge-triggered ERROR, a sustained path-length change (a reroute) is a WARN, and the noisy middle is charted, never alarmed — because ECMP makes hop-by-hop diffing cry wolf. Addresses carry a reverse-DNS name where one resolves; --geo labels public hops with their AS/owning network (and a country when the registry actually knows it). | Half of "is it them, is it us, or is it the path" is otherwise unanswerable, and a flat log never shows theshape of a network. Secure by default: it reads the LOCAL net and reports to the LOCAL hub; the only off-machine lookups (--geo to RIPE, --discover onto the LAN) are opt-in. And it says the path is up, never that the service is healthy — a route that resolves to a starved gRPC stream still draws green everywhere else; reachable is not verified. |
versions | host.<name>.versions — every version under the bench, diffed: OS and kernel, compilers and toolchains, language runtimes and their active version manager (nvm/pyenv, where the drift hides), databases, and the CPU/GPU. The baseline is silent; a change is the event — a major bump is WARN (majors break things), a tool that vanished is WARN, a new one INFO, a missing one a fact reported once and never re-nagged. It reports; it does not advise — "openssl changed on Tuesday", never "and that matters", because judgment needs a maintained knowledge base (a paid layer, so nothing here is crippled to sell you something). Each fact carries how it was obtained and a version marked unorderable rather than guessed. Opt-in --check-conflicts downloads a known-bad list and checks it locally — your versions never leave the box (a version list is a CVE roadmap). | Half of "it worked yesterday" is one question —what changed — and nothing on a bench answers it: gcc 13.1→13.2 starts miscompiling, postgres 15→16 changes a plan, a version manager swaps node under your feet, and none of it announces itself. The version that hides best is on the hardware — a team lost three days to an FPGA running a bitstream its toolchain no longer produced, because installed and deployed drifted apart and nothing said so. |
sql | sql.<name> — SQL on the bench, two engines. Postgres: the tailer holds LISTEN open, so any trigger, stored procedure or batch job logs with one built-in statement — NOTIFY superlog, '{"level":"ERROR","msg":"reconciliation drift"}' — no extensions, no privileges beyond NOTIFY; JSON payloads carry level/msg/fields, plain text arrives INFO verbatim. SQLite: the database file watched from outside the process — the header's own change counter, page count and -wal growth, read without taking a lock — because in-process code already has a language SDK, and the outside observer is what was missing. Both poll --query "name=SELECT …" into metric readings; a failing query is ONE WARN until it recovers. Batch jobs and triggers are exactly the code that fails silently at 3am; the NOTIFY bridge gives them a voice for the cost of one statement. Delivery latency is bounded by the heartbeat interval (default 1s), and notifications are not queued for absent listeners — the tailer brackets any gap with WARN/RECOVERED so absence is never mistaken for health. | Built for the multi-hundred-gigabyteHugging Face era: tqdm bars are \r-rewritten, mute themselves in pipes, and reset per shard, so beside reading the bar it can --watch the destination itself, which no tool can mute. A stall — no movement for 30s — is an edge-triggered WARN hours before the fetch's own patience runs out, and recovery says so too. A wrapper as transparent as build: same output, same stdin, same exit status. |
| git | git.<host>.<repo> — a checkout on the timeline: commits (subject + shortstat), branch switches, rewritten history, tags and merge conflicts. superlog-git watches repos (silent baseline, then only changes); superlog git install-hooks adds a post-commit hook that stamps each commit the instant it lands; superlog git recall <commit> replays every log the bench collected between that commit and the next — the build that ran, the tests, the services that flapped, correlated to the change that caused them. | A commit is INFO (its subject is the message); rewritten history is WARN — a rebase/amend/force-push, unremarkable on your own branch and the worst news of the day on a shared one, and the watcher cannot tell which; merge conflicts are WARN and resolution recovers; a checkout that vanished is ERROR, said once. recall reads the LOCAL journal (durable recall across sealed segments and other hosts is the Cloud console). |
dns queries one chosen resolver (1.1.1.1 by default) so a change means the
record changed, not that a laptop moved networks and hit a different cache.
build is transparent: it prints the output and exits with the build's own
status, so it can sit inside a Makefile or a CI step unchanged.
dl wraps a fetch the way build wraps a compiler — output, stdin and
exit status untouched — and it exists for the downloads everyone now does:
pulling a large model or dataset from Hugging Face, shard by shard, for
hours.
The first form reads the tool's own bar (tqdm/hf, curl's meter, wget, or
any bare NN%). The second is the one to reach for on a big multi-shard
pull: hf download runs one tqdm bar per shard and each resets to 0%, so
--watch measures the destination directory itself every tick —
symlink-aware, so a Hugging Face cache of blobs and snapshot links counts
each byte once — and --size turns that into the true overall percentage.
The third form needs no command at all: it follows a download some other
process owns, and exits when the size is reached.
Whole fleets
Eight servers with containers each is thirty tailers, and nobody runs thirty commands twice. Describe them once (fleet.json.example):
npm run fleet -- fleet.json starts every stream and restarts any that die.
name is the topic name, so os.api reads better at 3am than
os.ubuntu-4gb-nbg1-1. Everything is pulled over ssh — no agent, no open
port, no route from production to the hub.
Many benches: superlog-bridge
A hub rebroadcasts everything it ingests on /ws, so hubs compose:
subscribes to another machine's loopback hub over an ssh tunnel and re-ingests its whole feed here, verbatim — same topics, same bytes, so nothing downstream can tell a bridged stream from a local one. Neither hub ever listens on the network. One direction only: two hubs bridged at each other is a feedback loop, so pick one bench to be the bench.
Rebroadcast can be turned off. Composability is the default, not a
mandate: a hub rebroadcasts on /ws because that is what makes it composable,
and one environment variable takes it back. SUPER_LOG_NO_EGRESS names topics
the hub accepts but serves to nothing — never on /ws, never from
/recent — so a stream can exist on the bench and still never leave the
machine:
A pattern is an exact topic, a prefix.* glob, or a bare * for the whole
hub; the hub says on the console at startup which topics are cut. It is a
security control in MIT code you can read — an agent, a bridge, a journal, any
/ws subscriber gets nothing for a cut topic, and because a cut topic never
enters the rebroadcast ring, a subscriber that reconnects can't replay it
either. One honest limit: served to nothing is the whole claim today — a cut
topic is not journaled locally, because super-log's own journal is itself
a /ws subscriber. Hub-internal journaling is the scheduled follow-up; until
it lands, a cut topic is dropped, not persisted.
History
The window filters on hub arrival, not the producer's clock: arrival is monotonic, so the window is exact and the scan can stop early.
Modes and policies
Every SDK enforces DEVELOPMENT xor PRODUCTION — neither or both is a
compile error (C++ and Fortran defines, Rust features) or a raised error
(JS, Python, Go, Java, Swift). Each mode
then ships what its policy allows: development everything, production
nothing. Want crash triage from release builds? Say so explicitly —
-DSUPERLOG_PROD_POLICY=ERROR, prod_policy: Policy::AtLeast(Level::Error),
or productionPolicy: 'ERROR'. Below-policy events cost one compare; a
policy of OFF compiles the transport to an inert shell — and says so once on
the console, because a client that is silently doing nothing looks exactly
like a broken one.
Log lines leaving a production box are a security decision, so nothing here makes it for you.
Security posture
The full model — the MIT tool's threat model and how it differs from super-log Cloud's — is docs/SECURITY_ARCHITECTURE.md. In short:
No auth, no TLS: anyone who can reach the port can read every stream and publish to any topic. The defaults are arranged so exposure is a choice, not an accident:
- The hub binds loopback only, demo or not;
SUPER_LOG_LAN=1orSUPER_LOG_BIND=0.0.0.0open it up when real devices need it, on a network you trust. - The ssh tailer and the fleet runner pull, so production logs reach the bench without production ever reaching the hub.
- Production builds forward nothing unless you loosened the policy.
- A topic can be cut from egress at the hub.
SUPER_LOG_NO_EGRESS='secrets.*'(or*for the whole hub) makes the hub accept a stream but serve it to nothing — no/ws, no/recent, no replay — so it stays on the machine. Cut topics are dropped, not journaled; see Many benches above. - Credentials are redacted, not logged:
Authorization,CookieandX-API-Keyheaders in the proxy, token-shaped query values in URLs, and the provider key inside an RPC endpoint. .envis gitignored — an RPC URL with a key in it is spendable.- CSV exports defuse spreadsheet formula injection; viewers render log content as text, never markup.
SaaS and hosted services
The same idea, for the parts of a system you cannot attach a debugger to at all. Both drive the vendor's own CLI, so there is nothing to install in your service and no webhook to host.
Cloudflare Workers
Publishes to cf.<worker>. One invocation becomes several events sharing a
trace — the request, every console line the handler wrote, and any
exception — so /recent?trace=… returns one invocation end to end. Levels
come from the Worker rather than from guesswork: console.error is ERROR, a
500 is an error whether or not the handler said so, and an outcome that is
not ok is an error even when nothing was logged — exceededCpu kills
the isolate silently, which is exactly the failure you cannot see from
inside. CPU and wall time arrive as DEBUG metrics.
It uses wrangler's own login, so no API token is needed. It is live
only: wrangler tail cannot reach backwards, and --since refuses with an
explanation rather than quietly tailing from now and letting you believe you
are looking at an hour ago.
Stripe
Publishes to stripe.<account>.<mode>, one process and one topic per
account, so a busy account cannot delay a quiet one. Levels follow what an
event means: a dispute is CRITICAL because it is money already gone plus a
deadline, a failed payment is ERROR, a refund or cancelled subscription is
WARN. Amounts arrive as a stripe.amount metric.
Redacted by allowlist, and this is the point. A
payment_intent.payment_failed carries the customer's email, name, phone,
full billing address, card brand, last four and fingerprint. That is a
customer record, not log data, and this hub has no authentication. Only
named fields ever leave the process — a blocklist would start leaking the
day Stripe adds a field. What survives is what you would actually debug
with: the decline code, the failure message, the amount, and the customer
id. --unsafe-full turns it off and warns you first.
Setup is the Stripe CLI's own:
stripe login grants test-mode keys; --live needs an account
authorised for it. CLI keys also expire — if a stream goes quiet after a few
months, re-run stripe login before suspecting the tailer.
Why the hub has no auth
(superlog login is a browser door to the optional Cloud — it adds no
authentication to the local hub and makes no network call of its own. This is
about the hub itself.)
The bar this aims at is deliberately modest and deliberately explicit: be no less safe than the logs a developer already has, and never more dangerous than them.
Normal logs are files under /var/log and ~/Library/Logs, adb logcat,
the Metro and Xcode consoles, journalctl. Every one of them is local-only,
enforced by the operating system, and none can be written to from another
machine. Bound to loopback, this is the same thing: the OS is the
authentication, and it is the same OS doing the same job it already does for
your log files. Adding a password on top of that protects nothing that was
not already protected.
So the honest answer to "shouldn't there be auth?" is that for the case this tool is actually used in, auth would be theatre. What matters is not adding a login; it is not quietly becoming reachable.
Two things follow, and they are the whole policy:
The default is the safe one. This was not always true. The hub used to
bind 0.0.0.0 while this file claimed exposure was "a choice, not an
accident" — true of the demo script, false of the binary these instructions
tell you to run. A security claim the code did not honour is worse than
either alone. It binds loopback now, and says so at startup, and says
something louder when it is not.
A token would not fix the case people imagine it fixes. Without TLS a
shared secret crosses the network in plaintext on every request, so anyone
who can sniff that network has it after one request and keeps it. It would
stop accidental access, not an attacker — while adding a real new leak,
because browsers cannot set headers on a WebSocket and the viewer's token
would have to travel in the URL, into browser history and Referer and
every pasted link. That is a poor trade for something the OS already does
properly one layer down.
Devices, without opening anything
The one genuine gap is a phone pushing logs, because a handset cannot reach loopback on your Mac. Use USB rather than the network:
That is parity with normal logs everywhere, with no new code and no open port. It is also strictly better than a LAN bind with a token, and simpler.
Containers, and other machines
Docker on macOS needs nothing. A container reaching
host.docker.internal arrives on the host's loopback, so the repo's own
Ubuntu producer keeps working against a loopback-bound hub — verified, not
assumed. The counter-intuitive part is that --network host does not
work on Docker Desktop: "host" there means the Linux VM, so the
container's 127.0.0.1 is the VM's and not your Mac's. The permissive-
sounding flag is the one that fails.
Docker on Linux is the other way round: --network host shares the
host's network namespace, so 127.0.0.1 in the container really is the
host's loopback and a loopback-bound hub is reachable directly.
Either way, no GUI ever runs in the container — so there is no X11 socket to mount and no Wayland or waypipe forwarding to configure. Only HTTP crosses the container boundary; the viewer runs natively where your eyes are. A Linux workload in Docker on a Mac is visualised by the native macOS viewer, which is the hub/viewer split doing exactly the job it was designed for.
A Raspberry Pi, or any other machine, is the phone problem again — it cannot reach your loopback. Two answers, both already here and neither of which opens a port:
The pull model is the better default and the reason the fleet support exists: logs travel to the bench over ssh, so the machine being watched never needs to reach the hub and the hub never needs to be reachable. A reverse tunnel covers the case where code on that machine wants to use an SDK directly — it carries the traffic over the ssh session you already trust, and is verified working against a real server.
If you must expose it
If devices really must reach it over the network, put the allowlist where
allowlists belong — the firewall, not the application. An IP filter inside
the process is reimplementing pf or nftables badly, and it is defeated by
exactly the same attacker.
Then treat the bench as what it is: a development tool holding whatever your
machines are saying. If that includes production access logs, ssh
authentication failures or anything with a customer in it, the write side
matters as much as the read side — nobody can forge lines into /var/log
from across a network, and an open hub is the one place that stops being
true.
See the Auth/TLS section of docs/ARCHITECTURE.md.
Requirements
- Hub + viewers: macOS or Linux (POSIX phase 1), a C++17 compiler, CMake ≥ 3.16. Windows machines join as producers (SDKs, ssh tailer). Plain C SDK: any C99 compiler with POSIX sockets.
- Displays, on Linux: the native viewer draws through GLFW, built here
for X11 — which a Wayland desktop also runs via XWayland, so it should
work there unchanged. Native Wayland output is a GLFW build switch
(
-DGLFW_BUILD_WAYLAND=ONplus the wayland/xkbcommon dev packages), not a code change. No Linux desktop has been on this bench, so treat the first run of either as bring-up; the web viewer needs only a browser and does not care what your compositor is. - JS: Node ≥ 18 (≥ 22 for journal, chain watcher and MCP).
Ruby: ≥ 3.0, stdlib only (Rails via the
::Loggeradapter). OCaml: ≥ 4.14 (ocamlc -I +unix unix.cma). Haskell: GHC ≥ 9, boot libraries pluscurl. Scala: ≥ 3, riding the Java SDK. Lean: 4.x via elan/lake, core IO pluscurl. Perl: ≥ 5.14, core modules only (HTTP::Tiny,JSON::PP). Lua: any 5.1+ (PUC or LuaJIT) pluscurl. COBOL: GnuCOBOL 3 and a C compiler, riding the C SDK via a 20-line shim. C#: .NET ≥ 8 (RollForwardruns it on newer), BCL only. Zig: a recent Zig (verified on 0.16) and a C compiler, riding the C SDK via@cImport. SQL: thepsqlorsqlite3CLI. Rust: any recent stable. Python: ≥ 3.8, standard library only. Go: ≥ 1.21 (log/slog). Java: ≥ 17, plainjavac, no build tool. Swift: ≥ 5.9, SwiftPM. Fortran: gfortran or any compiler with-cpp. Shell:shandcurl, nothing else. - On macOS, Go 1.21's internal linker omits
LC_UUID, which current dyld rejects; build with-ldflags=-linkmode=externalor use Go ≥ 1.22. - ts-moveables provides the
transport/fan-out/logging fabric. It is not a submodule: CMake uses a
sibling
../TSMoveablescheckout when one exists, and otherwise fetches a pinned SHA. Configure prints which of the two it chose, because a build quietly using someone's working copy is how "works on my machine" is made. - spdlog + fmt, imgui + glfw, and nlohmann/json are pinned submodules in
third_party/(git submodule update --init) — versions chosen to work together, so system-installed ones are never trusted. - Docker (optional) for the Ubuntu build-and-smoke image.
Layout
| Path | What |
|---|---|
hub/ | superlogd - the one process everything meets at |
scripts/ | build_all.sh (rebuild everything), setup.sh (add super-log to a project), smoke.sh, verify-sdks.sh, dev.sh |
tests/ | 106 tests: the tools driven as subprocesses against a real hub |
sdk/cpp/ | header-only: forward sink, spdlog sink, terminate handler |
sdk/c/ | superlog.h: one stb-style header, zero-alloc, POSIX sockets; production compiles to nothing |
sdk/rust/ | super-log crate: core, tracing layer, panic hook |
sdk/python/ | superlog: client, logging handler, excepthook, locals capture |
sdk/go/ | superlog: client, log/slog handler, panic recovery |
sdk/java/ | SuperLog: client, java.util.logging bridge, Kotlin notes |
sdk/swift/ | SuperLog: client, @TaskLocal trace |
sdk/fortran/ | superlog.F90: client over raw POSIX sockets |
sdk/ocaml/ | superlog.ml: client over Unix sockets, mode from SUPERLOG_MODE |
sdk/lean/ | Superlog.lean: Lean 4 client, core IO + curl, mode from SUPERLOG_MODE |
sdk/haskell/ | SuperLog.hs: GHC boot libraries + curl, mode compiled in via -DDEVELOPMENT |
sdk/ruby/ | superlog.rb: stdlib client + the ::Logger adapter Rails plugs into |
sdk/js/ | @super-log/client, @super-log/react, @super-log/mcp |
tailers/ | adb, simctl, OS logs, files, services, docker, ssh, fleet, chain, journal, search, replay, net proxy, power, downloads, hub bridge |
viewer/imgui/ | native viewer |
viewer/react/ | web viewer |
demo/ | the multi-client clock demo: one command, whole bench |
docker/ | Ubuntu build+smoke image and the Linux bench producer |
third_party/ | pinned submodules |
docs/ | PROTOCOL.md (the contract), ARCHITECTURE.md (the shape) |
Status, honestly
Most of this is verified live on a real bench, and where something is
merely written it is labelled as such. Verified: the hub, both C++ paths,
Rust, the JS client in a real Expo app on simulators and hardware plus a
real browser and Node, both viewers, the macOS and journald tailers, the adb
tailer against a physical handset, ssh streaming from cloud hosts, a fleet
of four servers, the chain watcher against Ethereum mainnet, search and
replay over a 1 GB journal, correlation across tiers, the error hooks in all
four SDKs, and the Docker image (which smoke-tests itself during
docker build).
Also verified since: the Go, Java, Swift, Fortran and shell SDKs against a
live hub; sanitizer and valgrind capture against real ASan/TSan/UBSan and
valgrind output; the git and GitHub watchers (the latter catching real
commits as they were pushed); the ROS tailer against genuine ROS 2 Jazzy
/rosout; the socket inlet against real syslog datagrams; the serial tailer
against a pty; and a 20-minute Binance soak that found the hub's replay ring
holding 66 MB for one topic — leaks(1) confirmed no leak, the ring was
bounded by chunk count rather than bytes, and it now peaks at 30 MB under
the same load.
And since then: the power tailer in full root mode on two real Macs (a
Mac Pro and a Ventura iMac), its wattage cross-checked against a hand-run
powermetrics; the hub bridge relaying a second machine's loopback hub
onto this bench byte for byte over ssh; and superlog-dl against both a
live curl transfer and a real 100 GB Hugging Face dataset fetch, watched
overnight from the machine next to it.
CI is green on every job, first run, which is worth stating precisely
because it verifies things this bench cannot. It builds from a clean
checkout on Linux under both gcc and clang and on macOS arm64 (the bench
is x86_64), runs ThreadSanitizer on Linux where macOS's TSan is broken at
the runtime level, builds the hub with no submodules at all, runs the
POSIX shell producer inside Alpine with busybox ash, busybox awk and no
GNU date, and runs verify-sdks.sh — so every SDK is proved to actually
deliver events on a machine that is not the one they were written on.
Still written but not verified: the Windows event-log path (no Windows
machine here), the iOS-hardware tailer, Kotlin (no kotlinc here), Swift on
iOS, the serial tailer against real hardware at a real baud rate, the
CUDA demo (no NVIDIA GPU and no nvcc here — treat its first build as a
bring-up), gRPC against TLS and a real client library, and the OpenGL, D3D
and WebGPU snippets. Not built yet: viewer "load session" and metric
sparklines.
CI lives in .github/workflows/ci.yml; scripts/smoke.sh is the one smoke
test that CI, the Docker image and your terminal all run identically.
Future directions
Deliberately not built yet, and the reasoning matters as much as the list:
superlog-sysfor Linux/Ubuntu. The macOS one reads DiagnosticReports,diskutil activityandkern.sleeptime; the Linux counterpart iscoredumpctlandjournalctl -kfor crashes and OOM kills, udev/udisks events for volumes, andsystemd-logindfor suspend/resume. Same topic (sys.<host>), same event shapes, so the viewers and guide need not care which OS suffered. Waiting on a Linux desktop on the bench to verify against, per the house rule.- A Grafana / Loki / OTLP forwarder. The obvious ask is "integrate Grafana", and the answer is a forwarder, not integration. Teaching the hub to be a Prometheus target or a Grafana datasource would make it depend on an ecosystem it does not need and would blur the line drawn above — the hub's job is to be the thing you can point anything at in ten seconds. A forwarder respects that line: one more subscriber on the firehose that re-posts into Loki or an OTLP collector, in the same shape as every tailer here, so the bench stays a bench and the long-term store stays separate. It is a small script, and it is the right bridge for anyone who wants yesterday's logs in Grafana and today's on the bench.
- FIX and the market-data binary protocols. A
superlog-fixfor the session and application layer (QuickFIX and FIX8 logs, or a tap on the session): heartbeats and gap-fills as DEBUG, a resend request or a sequence reset as WARN, a session logout mid-day as ERROR — the same edge discipline every watcher here keeps, applied to the one protocol whose silence costs the most. Below it, the exchange binary feeds — Nasdaq ITCH (market data) and OUCH (order entry), and their many venue cousins — are fixed-layout binary, so a bounded decoder in the log4j mould (lengths checked, content never evaluated) turns a captured session or a live tap into events: order-book adds/cancels as DEBUG readings, rejects and breaks as WARN/ERROR. Gated on a real session to verify against, per the house rule — a market protocol written but unproven is worse than none. - Viewer "load session" and metric sparklines — the journal can already be searched and replayed, but neither viewer can open a saved session directly.
- A byte budget on the hub's replay ring, which belongs in ts-moveables
rather than here; until it lands,
SUPER_LOG_REPLAY_CHUNKSbounds the ring by count instead. See the comment inhub/src/main.cpp. - zrok as a verified tunnel provider. The gateway is proven with
Cloudflare (quick tunnels, the stable named tunnel, DNS
provisioning, the endpoint factory) and ngrok (
--tunnel ngrok— live round-trip verified on this bench: an alarm fired at the public ngrok URL from the internet landed on the hub; free-tier URLs rotate per restart, a paid domain is stable, and API callers send thengrok-skip-browser-warningheader).--tunnel zrokparses zrok's output and should work, but "should work" is not the house standard: it needs a zrok account on the bench and the same live treatment before the README claims it. The endpoint factory's quick tunnels are Cloudflare-only until then. - Windows as a first-class host for the hub and viewers. Windows machines already work as producers, and the event-log tailer is written but unverified.
Contributing
This was built for my own bench and then it turned out to be useful, so here it is. Pull requests are welcome — new streams especially: if something on your desk emits logs and this cannot read it yet, that is the gap worth filling.
Two things make a change easy to accept. Run it against a real hub before you open the PR, and say in the description what you actually observed — this repo's habit is to label what is verified and what is merely written, and that habit is the reason it can be trusted. And keep the producer contract: bounded queue, drop oldest, count what was dropped, and never block the program you are observing.
Issues describing a stream you wish it read are useful too, even without a patch.
If you run a service that produces logs
An open invitation. If you build a SaaS product that emits logs, events or metrics that developers debug against, a reader for it belongs here and you are the person best placed to write it — you know the event shapes, the severities that actually matter, and which fields are the ones people need at three in the morning.
There are readers here for Cloudflare Workers, Stripe, GitHub Actions, Postgres, nginx, Redis, Kafka, Docker, ROS and a couple of dozen others. Every one of them is a single file of a few hundred lines that spawns your CLI or calls your API and turns the output into events. There is no plugin API to learn and no interface to implement — read one of them and you have seen the whole pattern.
Three things a good one does, and they are the whole review:
Levels mean what your product means. Not what the event is called. A Stripe dispute is CRITICAL because it is money already gone plus a deadline; a Cloudflare Worker that exceeded CPU is an error even though it logged nothing at all. You know which of your events are the three-in-the-morning ones. Encode that, and a developer's level filter starts doing real work.
Redact by allowlist, not blocklist. This hub has no authentication and
is read by anyone who can reach it. A payment_intent.payment_failed
carries an email, a name, a phone number, a billing address and a card
fingerprint — that is a customer record, not log data. The Stripe reader
names the fields that may leave and drops everything else, because a
blocklist starts leaking silently the day you add a field. If yours carries
personal data, do the same.
Keep the producer contract. Bounded queue, drop oldest, count the drops, and never block or kill the program being observed. A logger that can take down the thing it is watching has no business being installed.
If that sounds like your product, open an issue or a PR — or just tell us what the API is and we will have a go. Streams nobody has thought of yet are the most interesting kind.
Releases
Tagged releases carry notes saying what is verified and what is not — CHANGELOG.md. There is no package registry: the clone is the distribution, so pin a tag if you want a stable base.
Licence
MIT. Every source file carries the copyright line and an
SPDX-License-Identifier: MIT, so the licence travels with the file when
someone copies one out — which, for a repo made of self-contained
single-file tools, is how most of it will actually be reused.
Copyright 2026 Saxon Herschel Nicholls.