This listing appears offline
Our automated checks couldn’t reach the source repository, so we’ve removed it from search, browse, and the API — this page stays reachable at this direct link only. If this is your project, claim it to fix the link and restore visibility.
Claim this listingmonitoringllmobservabilitycost-trackingagent-tracing
Self-hostable LLM observability server logging requests, costs, agent traces, anomalies, and user analytics via a read-only API key.
Quick Install
Automated & IDE SetupCopy the AI prompt to install this server into Claude Code, Cursor, or another agent — or use 1-click editor setup below.
Not yet automatically verified
We haven't yet run this listing's install command through our automated sandbox check. This isn't a red flag — we're steadily working through the catalog.
Manual Client & Custom JSON ConfigExpand JSON ▾
Client Config & Setup
Choose your client or environment
Target File:
💡 Paste the JSON block into your client's configuration file under mcpServers, then restart the application.
Overview
Use cases
Log and analyze LLM request details including cost and latency
Trace multi-step agent workflows and tool calls
Detect anomalies and monitor usage patterns
Scan for PII and injection risks in prompts
Compare model costs and optimize usage
Key features
Request logging with full prompt and response details
Cost tracking and spend forecasting
Agent tracing for multi-step LLM workflows
Anomaly detection and alerting
PII and injection scanning
Prompt versioning and A/B experiments
Capabilities & Tool Schemas
Inspect callable tools, capabilities, and parameters exposed to AI agents by Spanlens.
Extracted Tool Capabilities
Request logging with full prompt and response details
Cost tracking and spend forecasting
Agent tracing for multi-step LLM workflows
Anomaly detection and alerting
PII and injection scanning
Prompt versioning and A/B experiments
Documentation Overview
Spanlens


Open-source LLM observability you can turn on in one line. Point your OpenAI, Anthropic, or Gemini client at Spanlens and every call is logged with cost, tokens, latency, and full agent traces. No SDK rewrite, no platform migration. Eleven providers supported, plus native Vercel AI SDK, LangChain, and LlamaIndex integrations, and you can query it all from Cursor or Claude Desktop through the bundled MCP server. Self-hostable in one Docker command. MIT.
Why it exists. I shipped an LLM app on OpenAI and Gemini and hit a wall. The provider dashboards showed total spend and nothing else. I could not tell which feature burned the most tokens, which model was cheapest per task, or what each endpoint actually cost. Spanlens is the layer I wanted. It turns on in one line, stays off the critical path, and is open source so you can self-host the exact code we run.
⭐ If Spanlens is useful to you, please star the repo. It takes a second, and it is the single biggest thing that helps other developers find the project.
Hosted: spanlens.io · npm:
@spanlens/sdk· PyPI:spanlens· CLI:@spanlens/cli· MCP:@spanlens/mcp-server· Status: status.spanlens.io · Changelog: spanlens.io/changelog
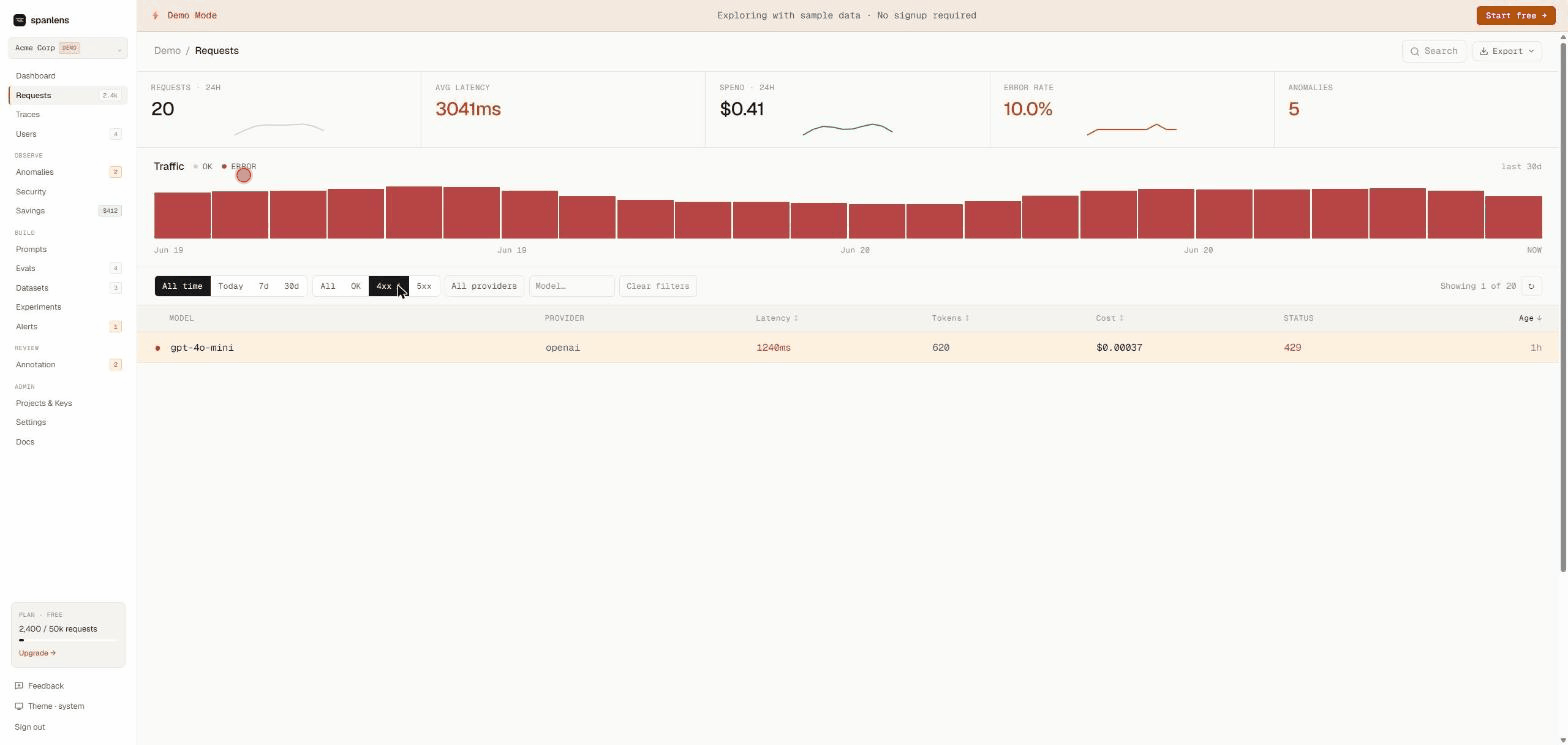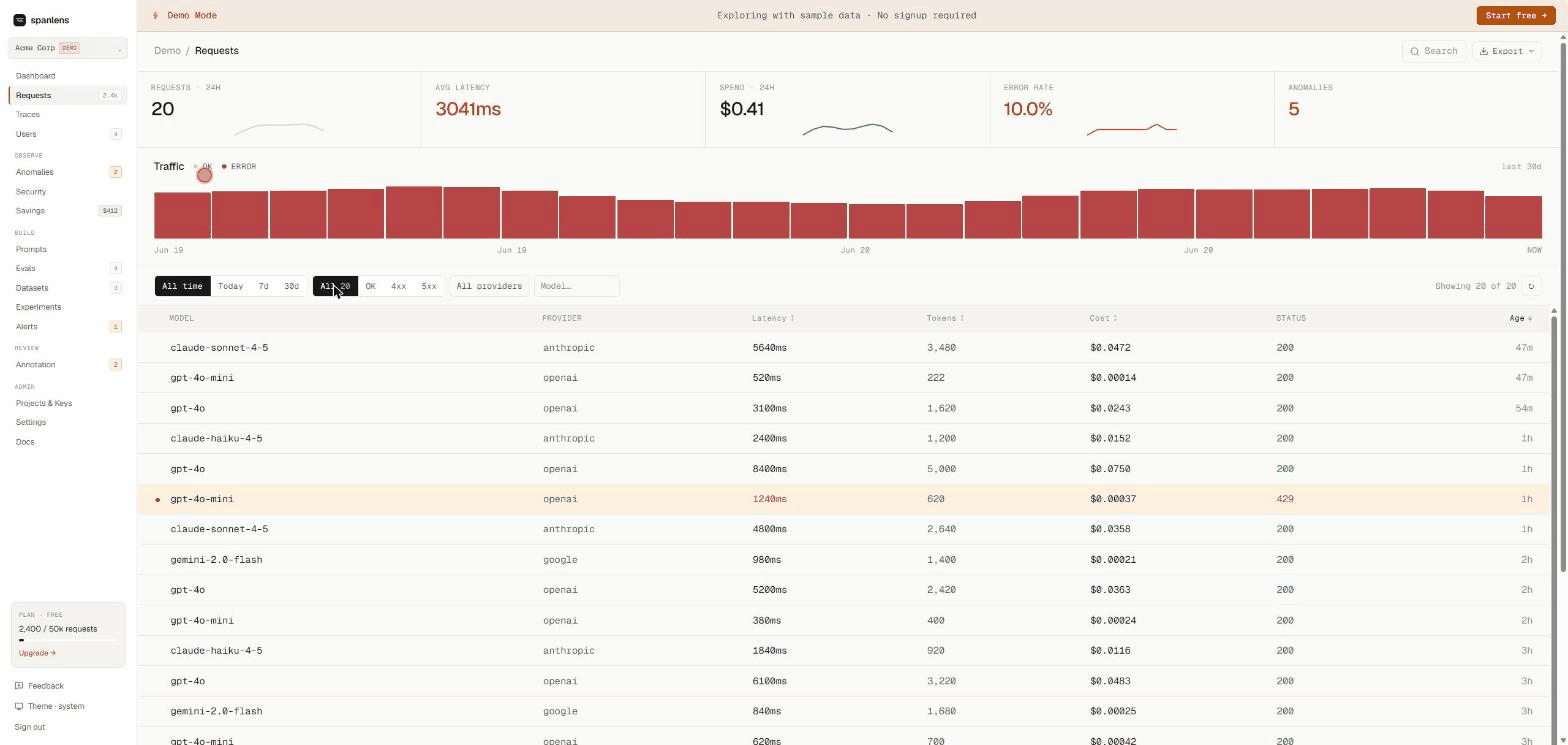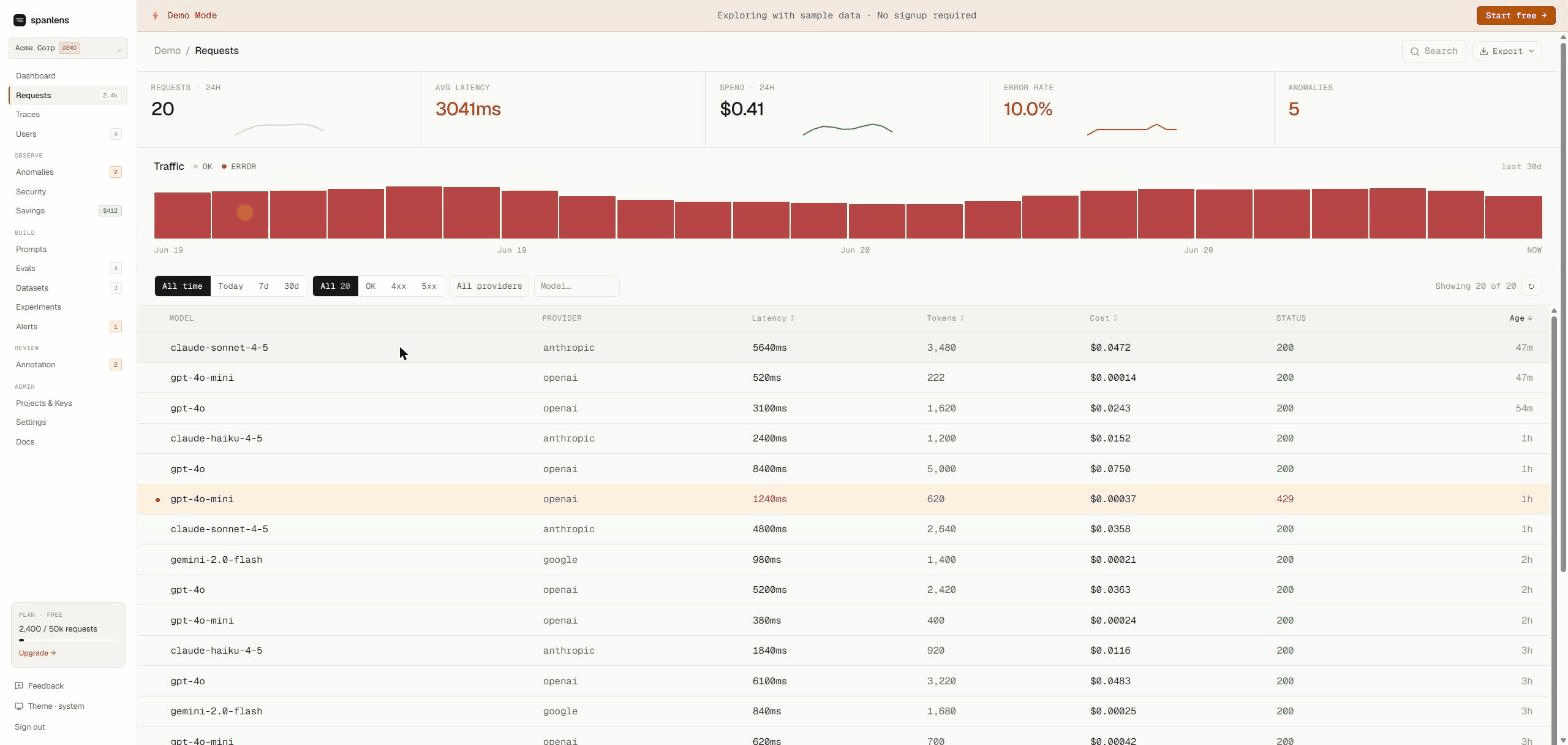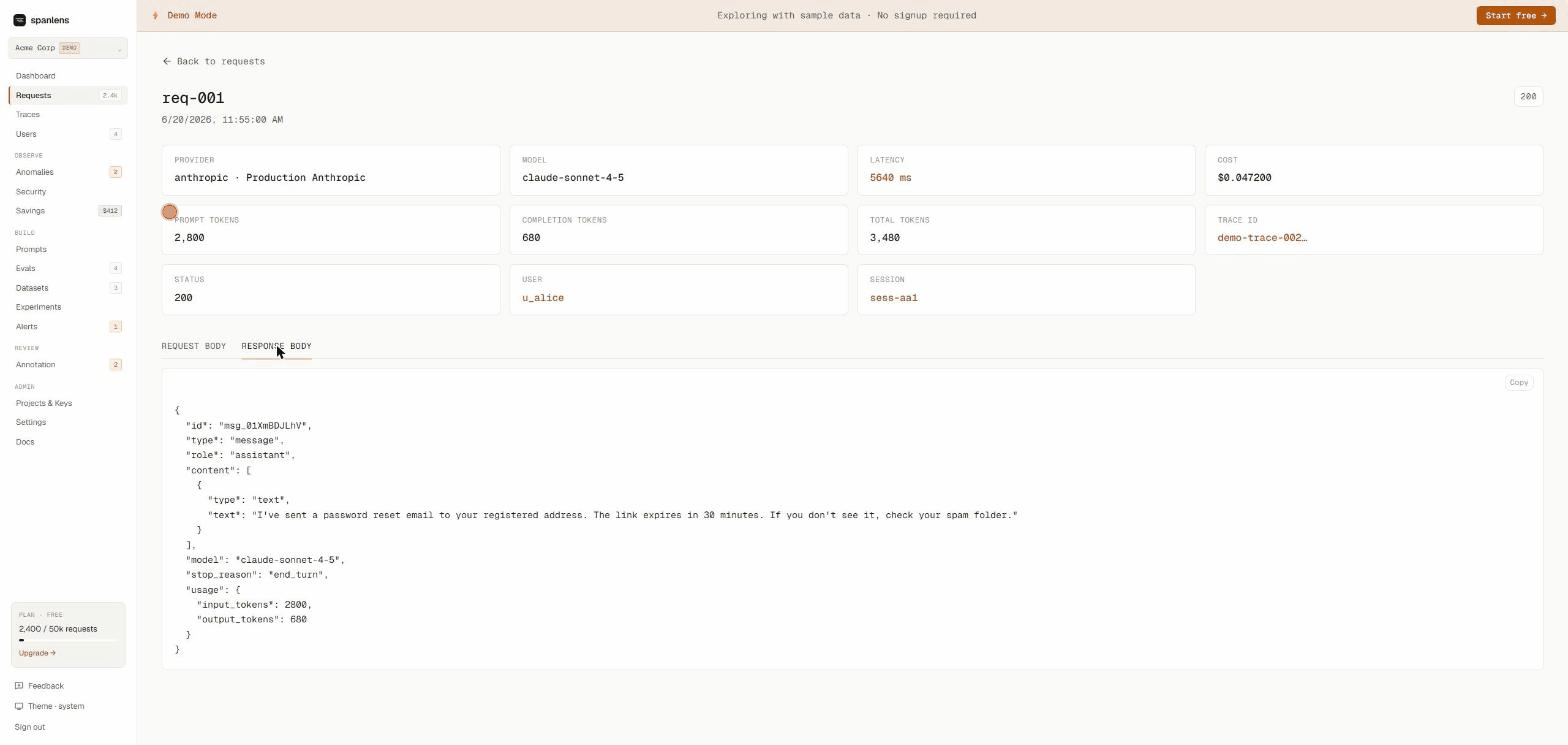
Live demo (no signup): spanlens.io/demo/requests
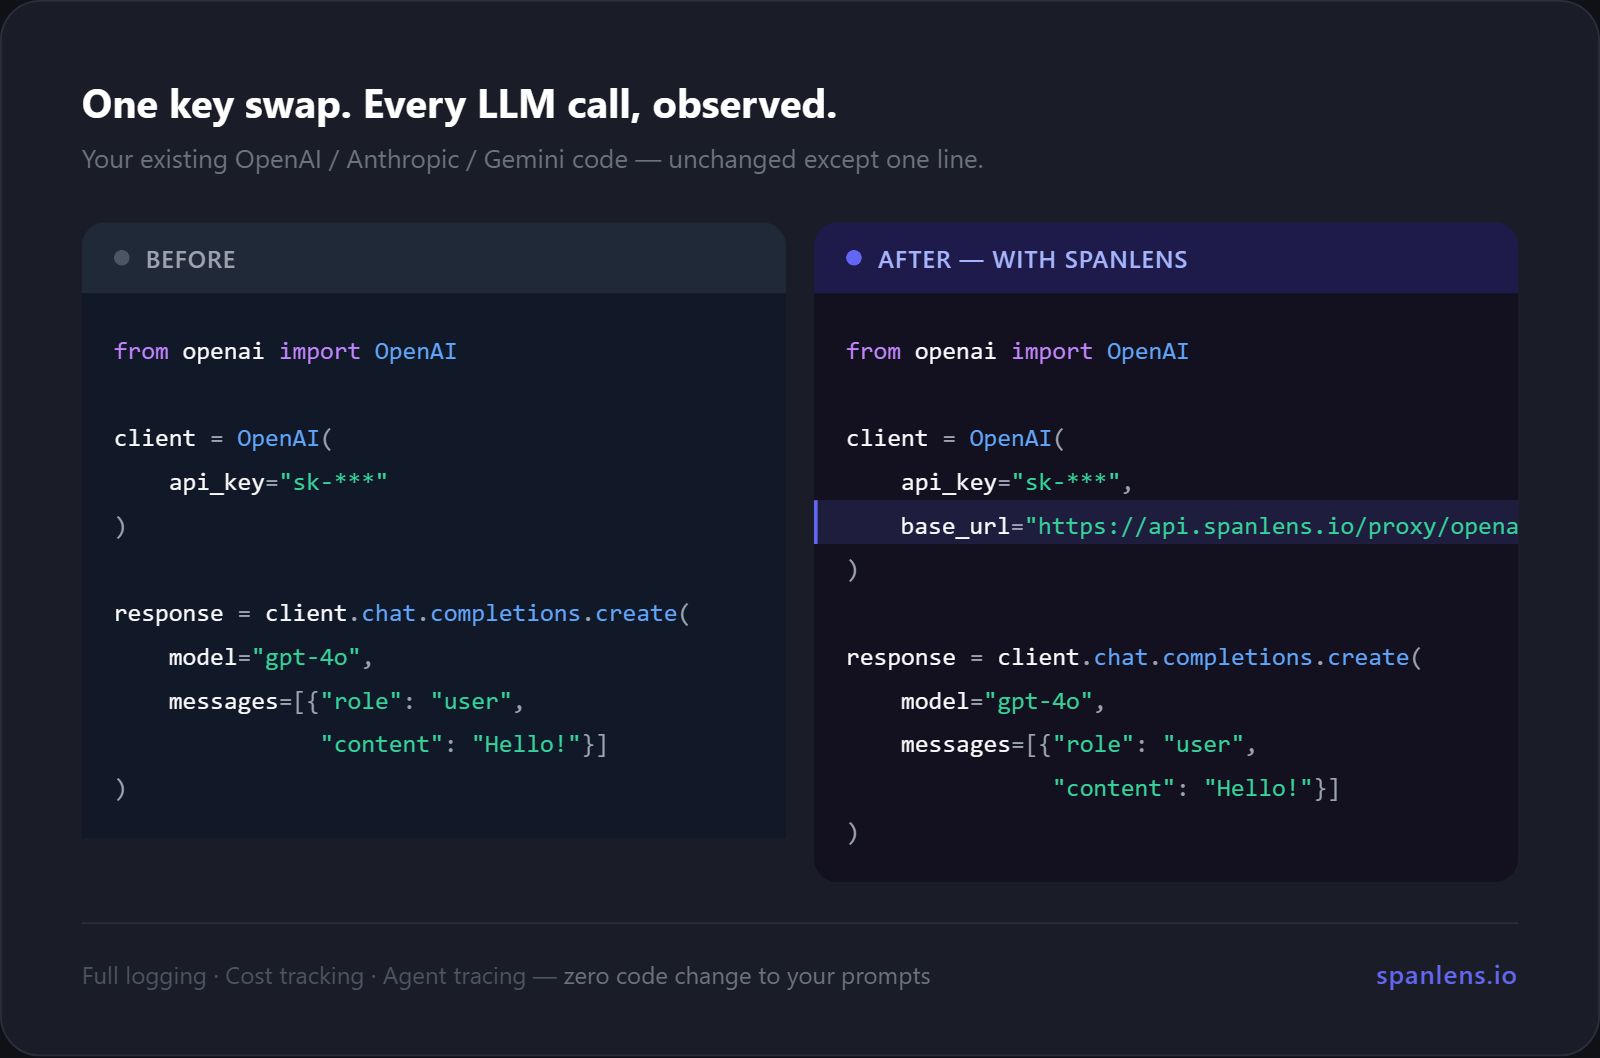
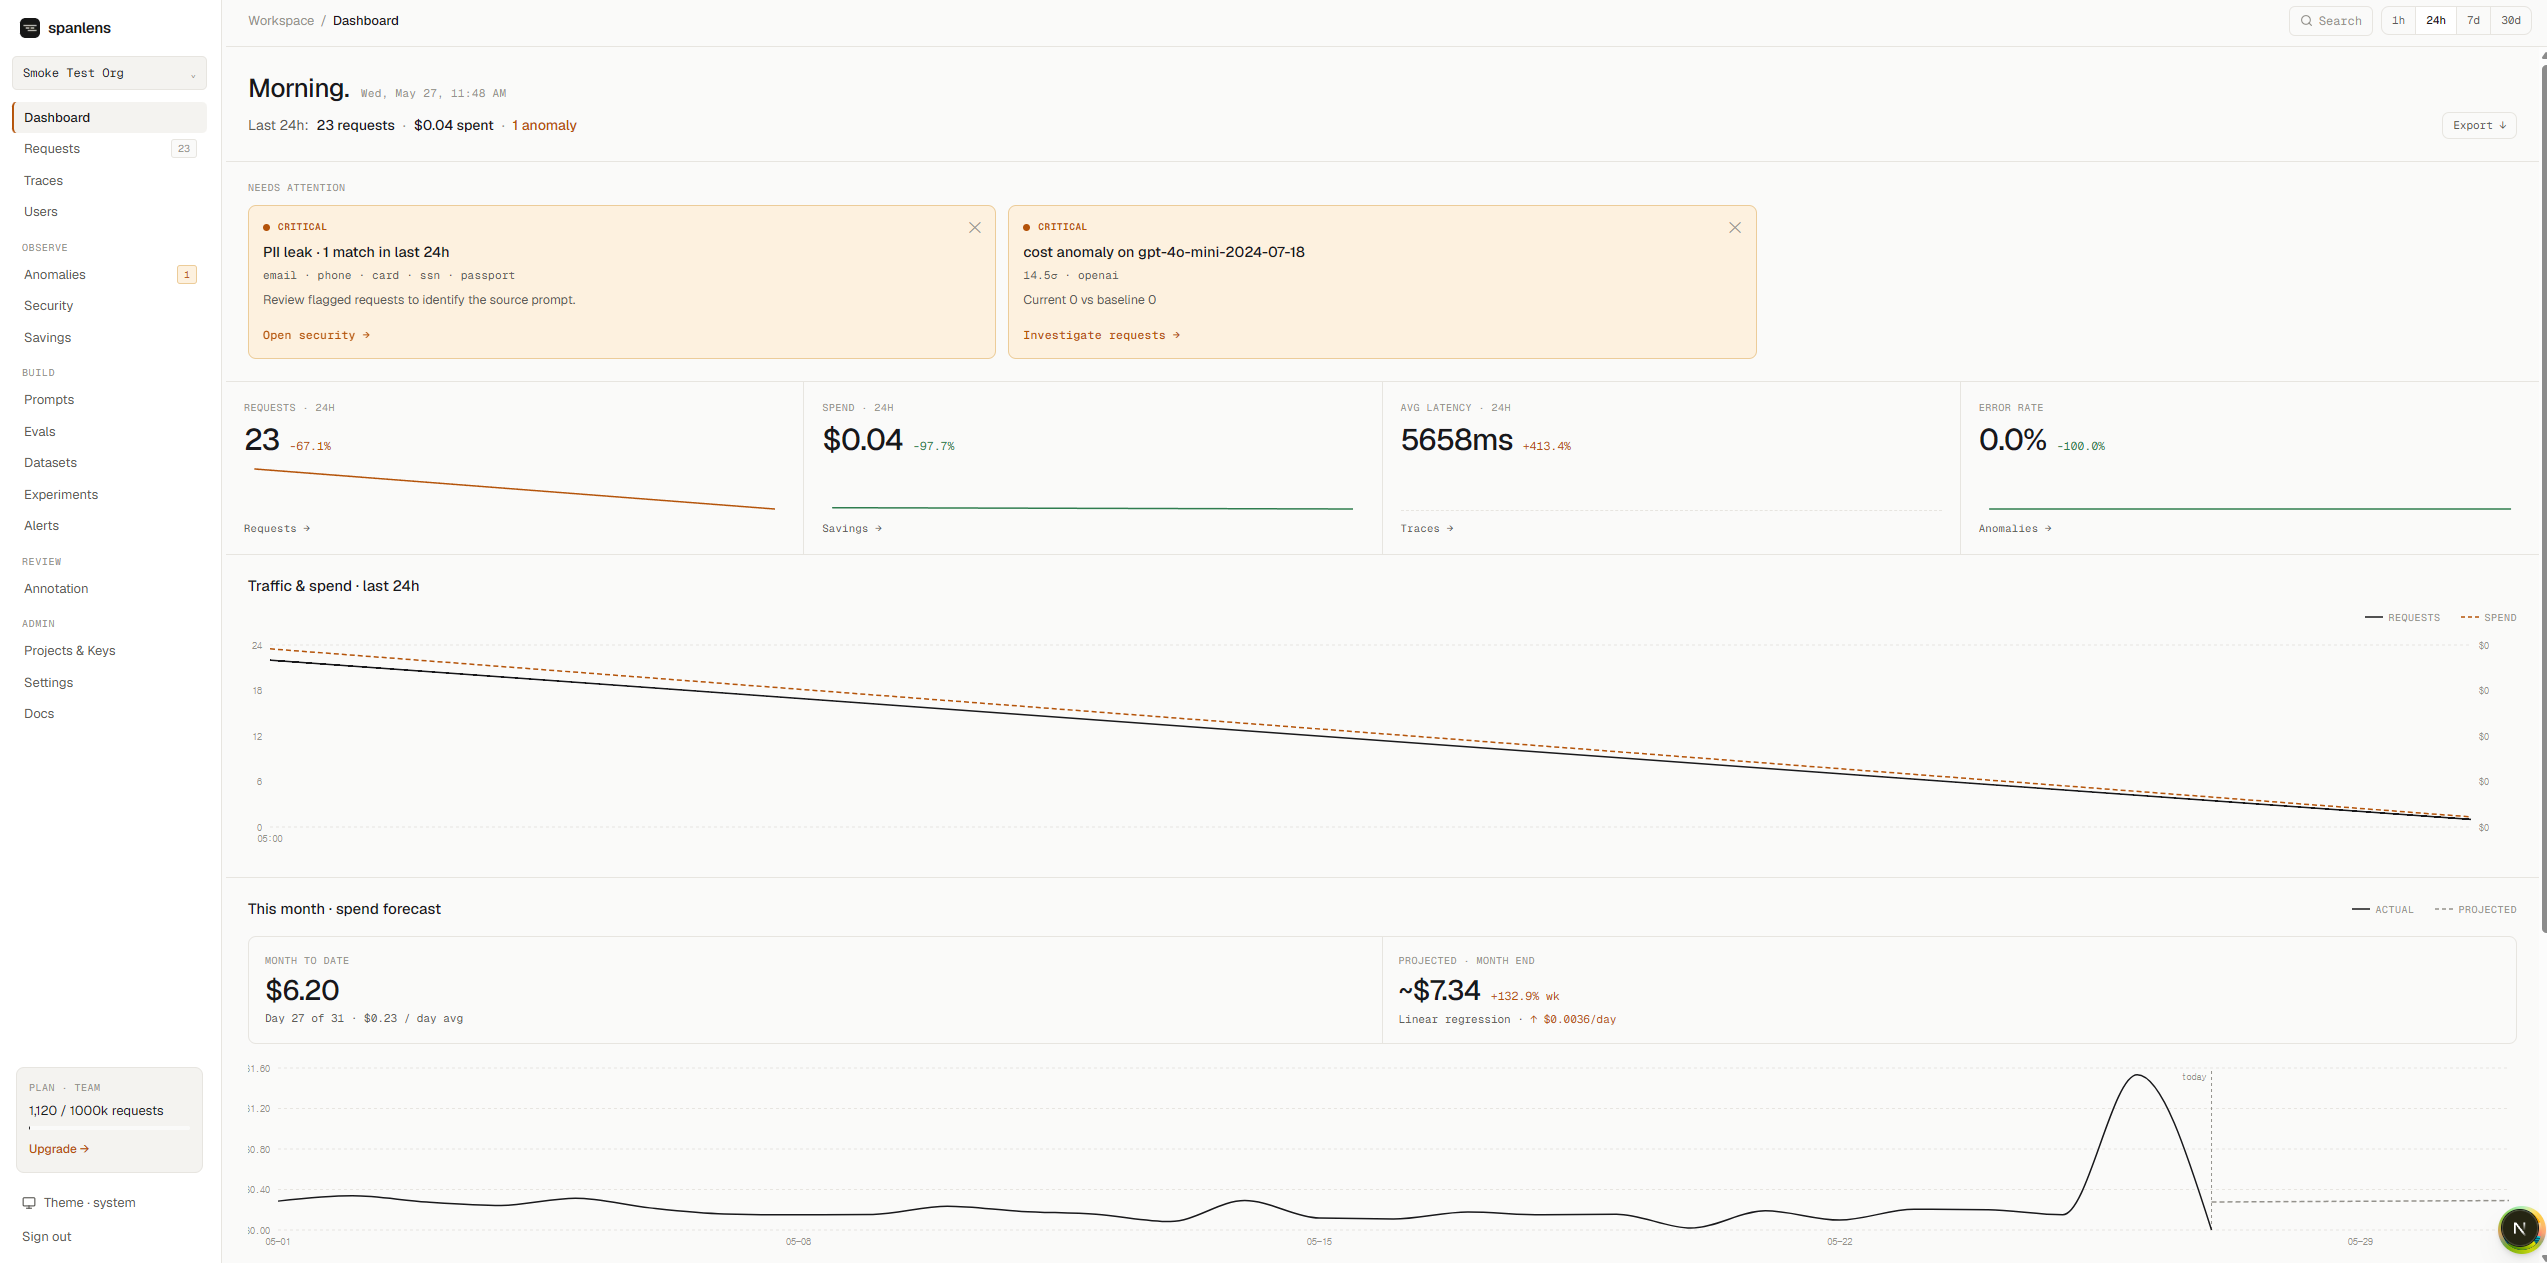
Why Spanlens?
- Helicone was acquired and its roadmap is uncertain.
- Langfuse is powerful but complex to set up and expensive to scale.
- Spanlens ships the 20% of features that cover 80% of real production needs. You get request log, cost tracking, agent tracing, anomaly detection, PII scanning, and prompt versioning with a clean UI, a two-minute setup, and pricing that doesn't punish growth.
| Spanlens | Langfuse Pro | Helicone | |
|---|---|---|---|
| Open source | ✅ MIT | ✅ MIT | ✅ MIT |
| Self-hostable | ✅ Docker one-liner | ✅ | ✅ |
| Free tier | 50K req/mo | 50K events/mo | 10K req/mo |
| Team plan (1M req/mo) | $149/mo | $271/mo | ~$200/mo |
| Agent tracing | ✅ | ✅ | ⚠️ limited |
| LLM-as-judge evals | ✅ | ✅ | ❌ |
| PII + injection scan | ✅ | ❌ | ❌ |
| Model recommendations | ✅ | ❌ | ❌ |
| Prompt A/B experiments | ✅ | ✅ | ❌ |
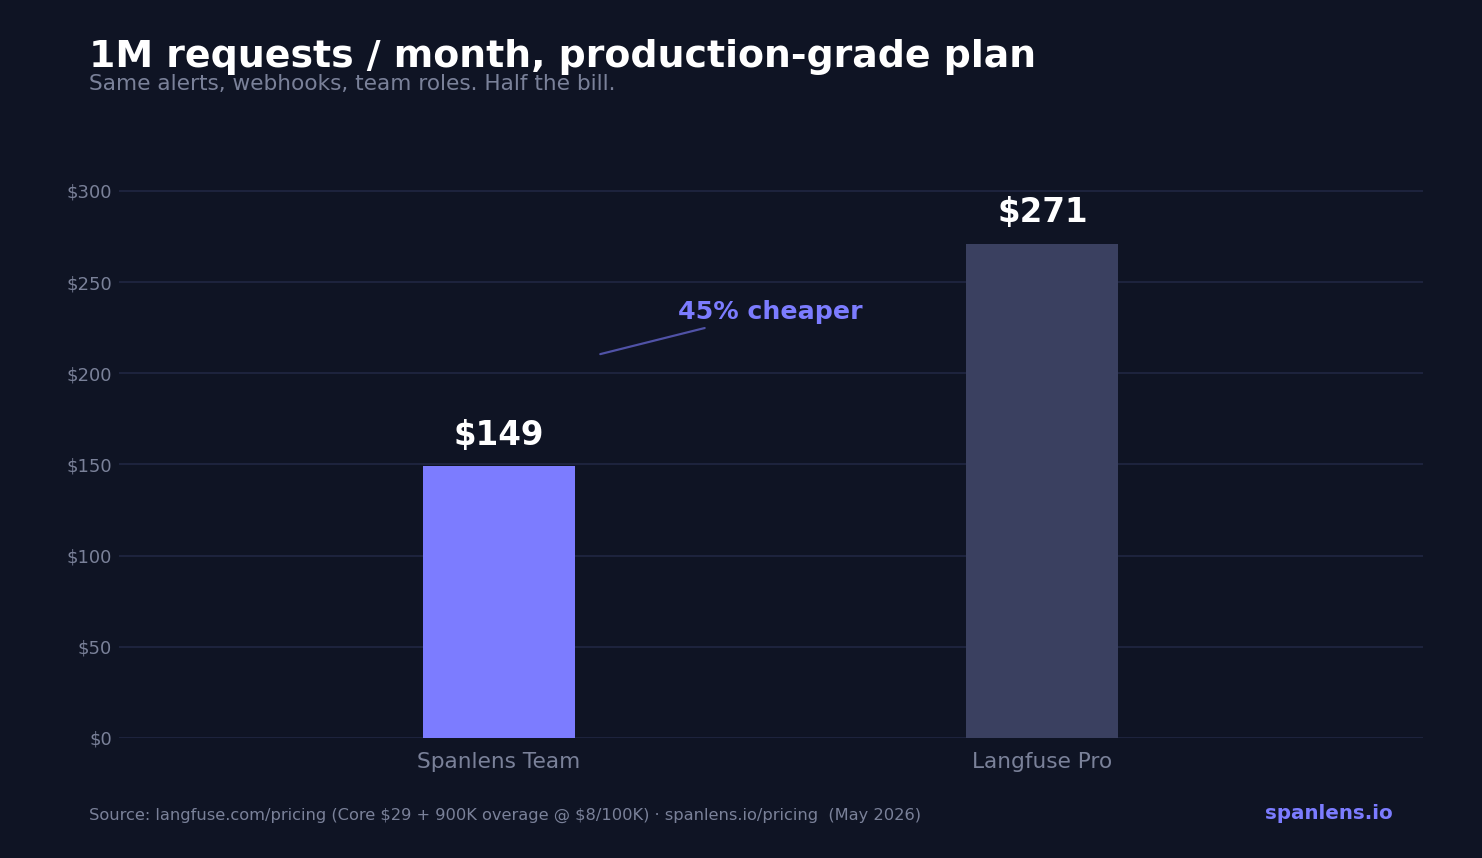
Predictable bills, no quota cliff. Free hits a hard 429 at 50K requests so a runaway loop in dev can't cost you money. Paid plans use a soft limit with authorized overage (Pro: +$8 / 100K, Team: +$5 / 100K) up to a hard cap you control, so a traffic spike charges you fairly instead of dropping requests.
Seats: Free 1 · Pro 3 · Team 10 · Enterprise unlimited. Unlimited projects on every paid tier.
⭐ Like where this is going? A star helps more developers find a lightweight, open alternative in a space full of heavy, acquired tools.
⚡ Quick start in 30 seconds
TypeScript / JavaScript (Next.js)
The wizard:
- Installs
@spanlens/sdkwith your package manager (npm / pnpm / yarn / bun) - Writes
SPANLENS_API_KEYto.env.local - Rewrites every
new OpenAI({ apiKey, baseURL })intocreateOpenAI()
Paste your Spanlens API key once, confirm two prompts, done. Your LLM calls are now flowing through the Spanlens proxy and visible in www.spanlens.io/requests.
Manual TypeScript setup
Python
For agent tracing in Python (multi-step, async, tool calls) see the Python SDK README.
Framework integrations
Already using an orchestration framework? Plug Spanlens in as a callback. No code rewrites.
Vercel AI SDK (Next.js / edge friendly)
LangChain JS / LangGraph
LlamaIndex TS
Python: LangChain: from spanlens.integrations.langchain import SpanlensCallbackHandler. Same BaseCallbackHandler contract, works with chains, LCEL, and LangGraph.
More integrations: AWS Bedrock, CrewAI, Flowise, Instructor, LlamaIndex, OpenAI Assistants, MCP server. Full setup walkthroughs at spanlens.io/docs/integrations.
Ollama (local LLMs): Ollama runs on your machine, so it does not go through the hosted proxy. Get a ready client with createOllama() and wrap each call with observeOllama() so the span is logged and tagged as Ollama.
What you see
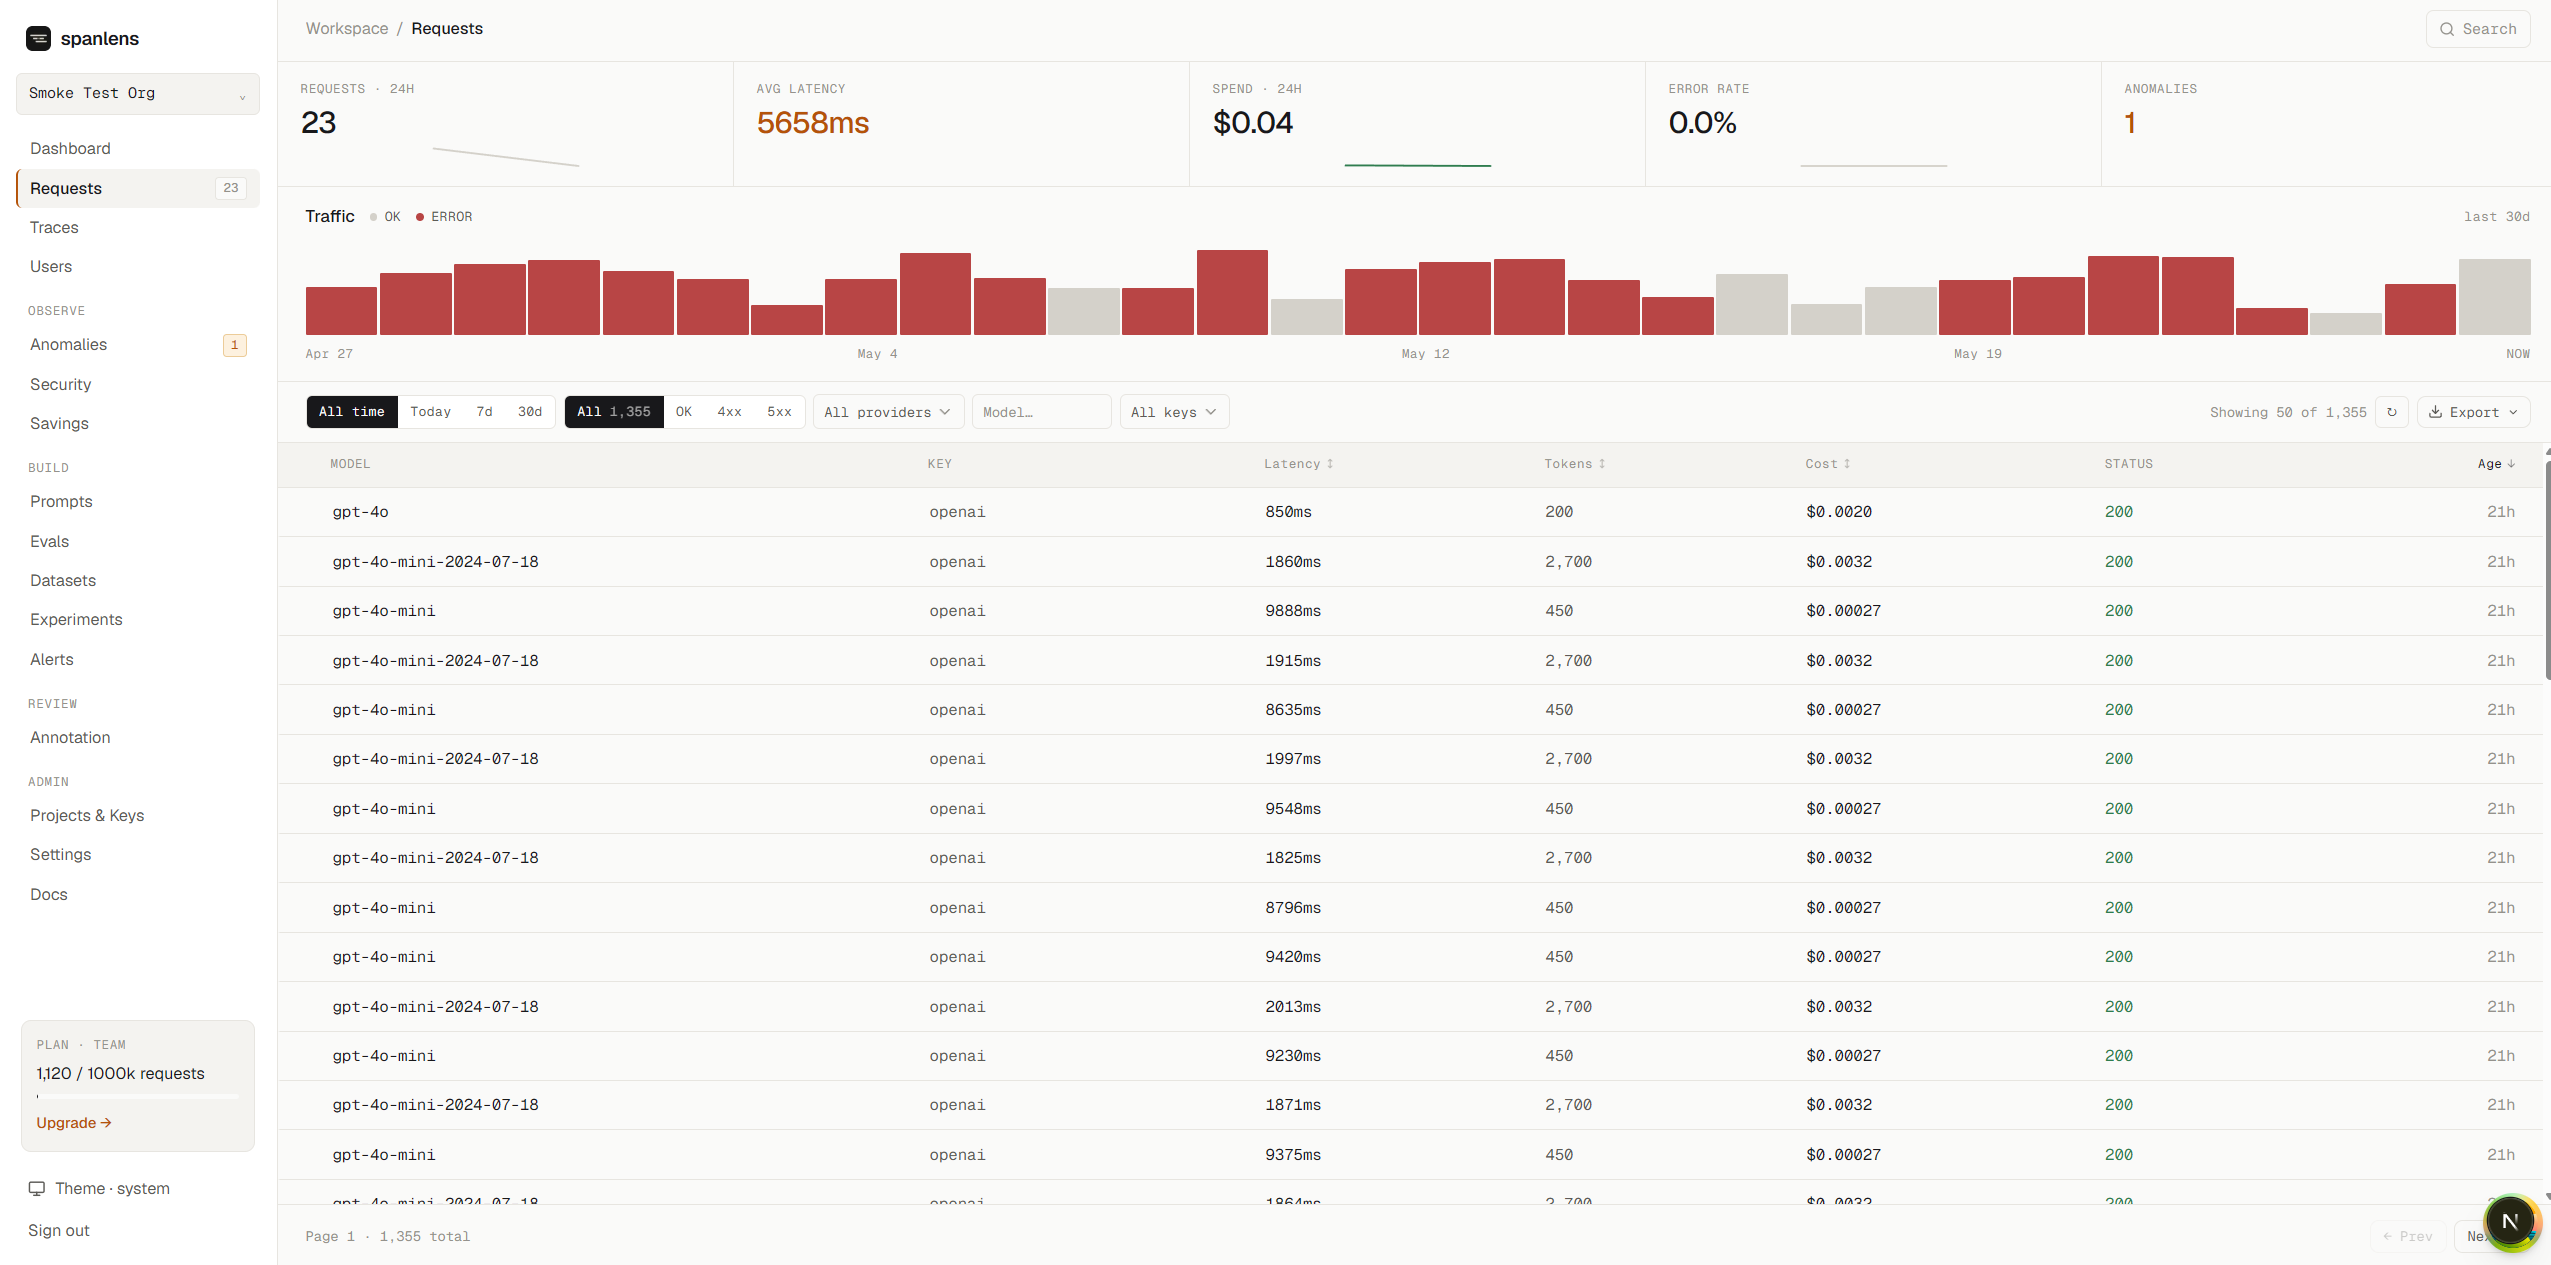
Every request logged with model, provider, latency, tokens, cost, and full prompt + response body. Filter, search, export. Streaming responses reconstructed automatically.
What you get
Related MCP Servers
Adoption & maintenance
Factual signals from GitHub, npm, and our automated checks — not a rating.
GitHub stars
13
Stargazers on the source repository.
Last commit
17d ago
Most recent push to the default branch.
Directory activity
2 views
Config copies, upvotes, and views on AllMCPs.
Reviews
No reviews yet — be the first to share how this listing worked for you.
Frequently Asked Questions about Spanlens
AllMCPs Directory Badge
Showcase your server listing on GitHub or your project documentation. Embed this dynamic SVG badge to highlight official listing status and live engagement.
Badge Style:
Live Dynamic SVG Preview
Markdown (GitHub README)
[](https://allmcps.com/mcp/spanlens-spanlens)HTML Embed
<a href="https://allmcps.com/mcp/spanlens-spanlens"><img src="https://allmcps.com/api/badge/spanlens-spanlens?style=directory" alt="Spanlens on AllMCPs" /></a>