Proxy Scraper README
The full upstream README, mirrored here for reference. Install config, tool schemas, adoption signals, and an original overview live on the Proxy Scraper listing page.





Most free proxy lists are 95 % dead, and a good part of the rest are honeypots or proxies that inject scripts into your pages. proxy-scraper collects public HTTP, SOCKS4 and SOCKS5 proxies from 700+ sources and keeps only the ones that pass every check. It learns with every run which sources are worth it, and it can turn the result into a single rotating proxy.


Table of contents
Install
With pipx (recommended – gives you a proxy-scraper command in its own environment):
The package is called proxy-scraper-cli on PyPI (the plain name is taken), the command is proxy-scraper.
Other ways: Docker, pip, a faster event loop, or straight from the repo
Every release also ships a wheel you can install with pip install <file>.whl, and a multi-arch image (amd64/arm64) on ghcr.io. In the container the wizard never shows up, it runs straight away. For the proxy server use --serve --serve-host 0.0.0.0 with -p 127.0.0.1:8899:8899, so the port is only open on your own machine.
Tab completion for bash, zsh, fish and PowerShell:
Installed, the learned state lives in your user data folder (~/Library/Application Support/proxy-scraper, %LOCALAPPDATA%\proxy-scraper or ~/.local/share/proxy-scraper; override with PROXY_SCRAPER_HOME) and results go to ./results. Run from a clone, both stay inside the project.
Started without arguments, a wizard asks what you are looking for:
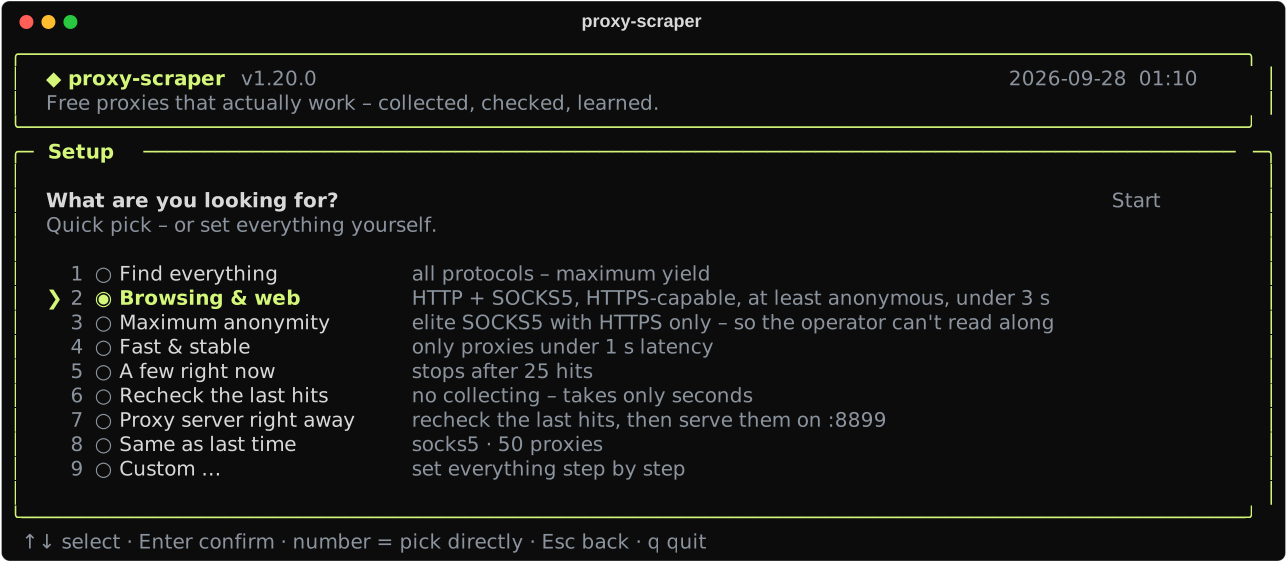
| Preset | What it does |
|---|---|
| Find everything | all protocols, maximum yield |
| Browsing & web | HTTP + SOCKS5, HTTPS-capable, at least anonymous, under 3 s |
| Maximum anonymity | elite SOCKS5 with HTTPS only |
| Fast & stable | proxies under 1 s only |
| A few right now | stops after 25 hits |
| Recheck the last hits | no collecting, takes seconds |
| Proxy server right away | recheck the last hits, then serve them on :8899 |
| Same as last time | your previous choice |
| Custom … | protocols, countries, anonymity, HTTPS, target site, latency, amount, check mode |
Keys: ↑↓ select · Space toggle · 1–9 jump · Enter next · Esc back · q quit. In scripts and cron jobs the wizard never shows up – pass options or -y.
Live proxy list
Don't want to scan yourself? Every hour GitHub Actions runs the tool and publishes the hits to the proxy-list branch – every entry worked in the last run, fastest first.
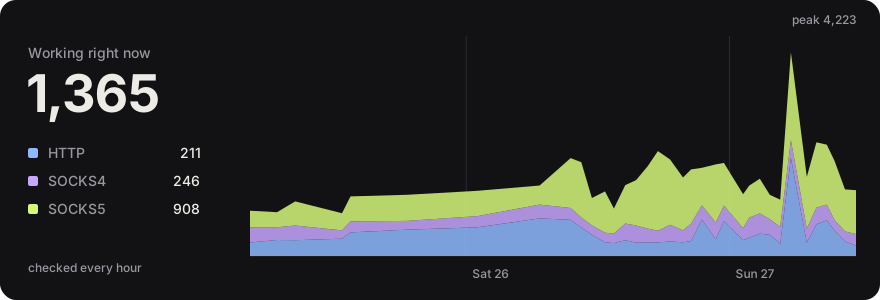
→ Browse it on the website – search, filter by type, country, HTTPS, provider and latency, see how long each proxy has been up and how often it was on the list this week, copy or download exactly the proxies you need.
Every protocol and country also has its own page with a plain download, e.g. SOCKS5 or Germany (country/de/proxies.txt).
| List | Format | Link |
|---|---|---|
| All | socks5://1.2.3.4:1080 | all.txt |
| HTTP · SOCKS4 · SOCKS5 | 1.2.3.4:8080 | http.txt · socks4.txt · socks5.txt |
| HTTPS-capable only | type://ip:port | https.txt |
| Elite only | type://ip:port | elite.txt |
| Gets through to Google · Reddit · Amazon · Instagram · TikTok (no captcha, no block in the last run) | type://ip:port | google.txt · reddit.txt · amazon.txt · instagram.txt · tiktok.txt |
| Stable, on the list in 90 %+ of this week's runs | type://ip:port | stable.txt |
| With all details | latency, country, HTTPS, anonymity, exit IP, uptime, sites | proxies.json · proxies.csv |
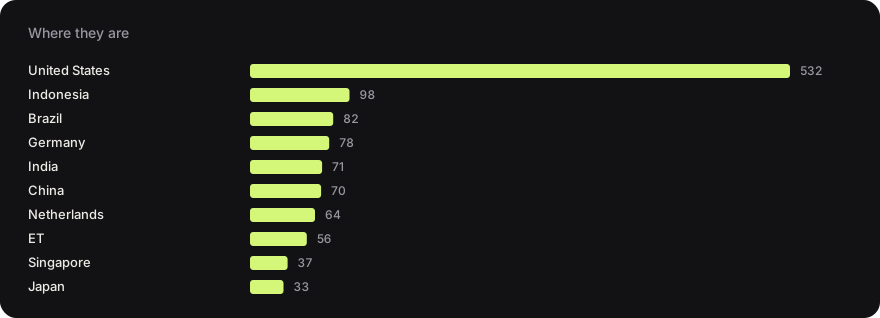
Over time: every day the first run's proxies.json is kept for good as a gzipped asset of the release of that year, like snapshots-2026 – proxies-2026-09-28.json.gz and so on, for anyone who wants to look at free proxies over weeks and months.
Every file is also on GitHub Pages, which sits behind a CDN, isn't rate limited like raw.githubusercontent and sends CORS headers, so it works straight from the browser: https://maximilianfeix.github.io/proxy-scraper/socks5.txt. jsDelivr works too, but can lag behind by a few hours.
Or let the tool start from it: proxy-scraper --recheck live downloads the list and checks it again from your network – about 30 seconds instead of a full scan (517 of 1,169 worked from here). With --serve you have a rotating proxy in under a minute.
For AI agents (MCP)
proxy-scraper-mcp is an MCP server: Claude Code, Claude Desktop, Cursor, VS Code, Codex and any other MCP client can ask for working proxies and load pages through them.
| Tool | What it does |
|---|---|
get_proxies | working proxies right now, from the hourly list – filter by protocol, country, HTTPS, elite, no datacenter, not blocklisted, stable, uptime, latency, gets through to Google/Reddit/Amazon |
check_proxies | checks proxies from your own network, so they work from where your code runs (30–90 s, reports progress) |
fetch_url | loads a page through a verified proxy, switches proxies by itself when one fails, returns readable text – HTTPS only through proxies with verified TLS |
Things to ask your agent: "Load bbc.com/news as seen from the UK", "Give me 5 SOCKS5 proxies from Germany that aren't in a datacenter", "Check which of these sites block free proxies".
Needs uv – it fetches a suitable Python by itself if yours is older than 3.10. Claude Code:
Claude Desktop, Cursor and most other clients – add this to the MCP config (Claude Desktop: Settings → Developer → Edit Config, Cursor: ~/.cursor/mcp.json):
VS Code, Codex, or without uv
VS Code – .vscode/mcp.json:
Codex – ~/.codex/config.toml:
Without uv: pipx install --python python3.12 "proxy-scraper-cli[mcp]" (any Python 3.10+), then use proxy-scraper-mcp as the command.
It's also in the official MCP registry as io.github.maximilianfeix/proxy-scraper, so clients that browse the registry can install it from there.
The server tells agents what it tells you: free proxies are run by strangers, so no logins, cookies or personal data through them. Local and private addresses are refused, and results go to proxy-scraper's data folder, not into the project you're working in.
Features
|
Setup wizard |
Fast |
|
Real verification |
Learns with every run |
|
Finds new sources by itself |
Filters & target sites |
|
Live dashboard |
Rotating proxy server |
|
Runs everywhere |
Thoroughly tested |
Why not just download a list?
| Typical proxy list repo | proxy-scraper | |
|---|---|---|
| Proxies checked right before you use them | ❌ | ✅ |
| Honeypots that fake a successful check filtered out | ❌ | ✅ |
| Proxies that inject scripts or ads filtered out | ❌ | ✅ |
| HTTPS tested with verified TLS | rarely | ✅ |
| Anonymity level and country per proxy | sometimes | ✅ |
| Only proxies that reach your target site | ❌ | ✅ --target |
| Learns which sources are worth it | ❌ | ✅ |
| Usable as a single rotating proxy | ❌ | ✅ --serve |
| Ready-made list without running anything | ✅ | ✅ live list |
Examples
Running from a clone? Replace proxy-scraper with python3 proxy_scraper.py.
From Python
Same run as the command line – sources, learning, every check, result files – just without terminal output. Each result has url, latency, exit_ip, https, anonymity, country, asn, org and hosting. There's an async version of both (find_proxies_async, check_proxies_async).
Don't need a fresh scan? live_proxies takes the live list instead – no checks, one download, done in about a second:
Same filters as find_proxies, plus min_uptime, works_on (["google"], "reddit", "amazon", "instagram", "tiktok") and limit. Every result also has uptime_24h, uptime_7d, first_seen, up_for_hours and sites.
Or let the library do the retrying: ProxyRotator loads a URL through the list and moves on to the next proxy when one fails – HTTPS only through proxies with verified TLS.
Usually a few seconds; when many proxies in a row are down it can take a minute (timeout= is per attempt). There's aget() with async with for asyncio code.
Already using requests, httpx, Playwright or Scrapy? proxy_url() gives you one local proxy address that rotates behind the scenes – every connection goes out through another proxy from the list, best first, dead ones skipped:
It runs on 127.0.0.1 with a random password, takes over each new hourly list by itself and stops with the with block.
Rotating proxy server
A list is nice – but usually you just want to enter one proxy that always works:
Like commercial rotating proxies, the username carries what you want: country-XX, type-http|socks4|socks5 and session-NAME, combinable (country-us-type-socks5-session-a). It works for HTTP (Proxy-Authorization) and SOCKS5 (username/password auth). By default the password is ignored and the server only listens on 127.0.0.1.
To reach it from other machines, give it a password – every client then has to send it, over HTTP and SOCKS5 alike, and the status page wants it as Basic auth:
Without a password, --serve-host means anyone who reaches the port can use it. The ready-made compose.yaml starts the server in Docker from the live list, with a password, a health check and learned state in a volume: put PROXY_PASSWORD=… into .env, then docker compose up -d.
| Option | What it does |
|---|---|
--rotate weighted | default: fast and proven proxies more often, everyone gets a chance |
--rotate random / round-robin | evenly, at random or in turn |
--rotate fastest | always the fastest one that isn't busy |
--sticky 300 | the same site keeps its proxy for 5 minutes (logins, carts) |
- every connection goes through a different proxy (unless sticky); fast and proven ones are preferred
CONNECTfor HTTPS and plain HTTP requests; HTTP, SOCKS4 and SOCKS5 proxies can sit behind it (SOCKS5 with DNS through the proxy)- HTTPS only uses proxies that passed the test with verified TLS – no broken encryption
- if a proxy stays silent inside the tunnel or returns an error page instead of TLS, the same first packet quietly goes to the next one
- three failures in a row and a proxy leaves the rotation – every 5 minutes those get re-checked and come back if they work again
--serve-refill 6checks fresh proxies every 6 hours in the background (the live list with--recheck live, otherwise the last run + history) with the same checks and filters, and adds the hits – a server that runs for days doesn't run dry- listens on
127.0.0.1only (unless--serve-hostsays otherwise), optionally with a password; live view with requests, success rate, pool and the latest connections
In testing: 20 of 20 HTTPS requests succeeded, over 15 different exit IPs. In the wizard this is Proxy server right away.
Discord and Telegram bot
The live list can also come to you: bot/ is a Discord bot that posts every run into a server – a summary with the fastest proxies, the full lists per protocol as files, and slash commands like /proxies type:socks5 country:DE https:true. It sets up its own read-only channels when you invite it, and a GitHub Action deploys it to a server as a systemd service. The same process answers on Telegram too: /proxy de socks5 for one proxy with a curl line, /proxies 10 us https for a short list. Setup in bot/README.md.
How it works
- Sources – the curated list in
sources.json, meta sources (other projects that maintain lists of proxy sources) and, once a day, a GitHub search for actively maintained repos. Every search adds to what earlier ones found; a list the search hasn't seen for three weeks drops out. - Collect – plain text, HTML tables, JSON APIs and
type://ip:portlines are recognized; private and reserved address ranges are dropped. Lists that haven't changed since the last run answer304and come from a local cache – a second run right after the first loads 0 MB instead of ~160 MB. - Prioritize – known working proxies first, then by the learned hit rate of their sources.
- Check – every proxy has to fetch its exit IP from a check target (
checkip.amazonaws.com, withifconfig.me,ipinfo.io,wtfismyip.comandident.meas reserves – none of them behind Cloudflare) and return a valid, foreign IP. If the target goes down mid-run, the tool switches and re-checks the proxies that were affected, so the statistics don't learn from an outage. Anyone passing your own IP through is out. Then comes the confirmation viahttpbin.org: fake proxies that only answer the first check with “200 + IP” fail here. Finally a static HTML page has to arrive byte for byte as it does without a proxy – anyone injecting ads or scripts is out. - Countries and providers – looked up offline in the free DB-IP databases, including the provider (ASN) and whether it's probably a datacenter (about 45 % of working proxies are) (downloaded once a month, ~2 µs per lookup); ip-api.com is only asked for the few addresses it doesn't know.
- Blocklists – one DNS lookup per exit IP against SpamCop, cached for the run: about 29 % of working proxies exit from a listed IP, and sites that use the list show those captchas or block them.
--no-blocklisteddrops them. If your DNS resolver is refused by SpamCop (large public resolvers are), the lookup is skipped instead of guessing. - Learn – hit rates and history are stored. Sources without hits, with content unchanged for a week or permanently unreachable are skipped.
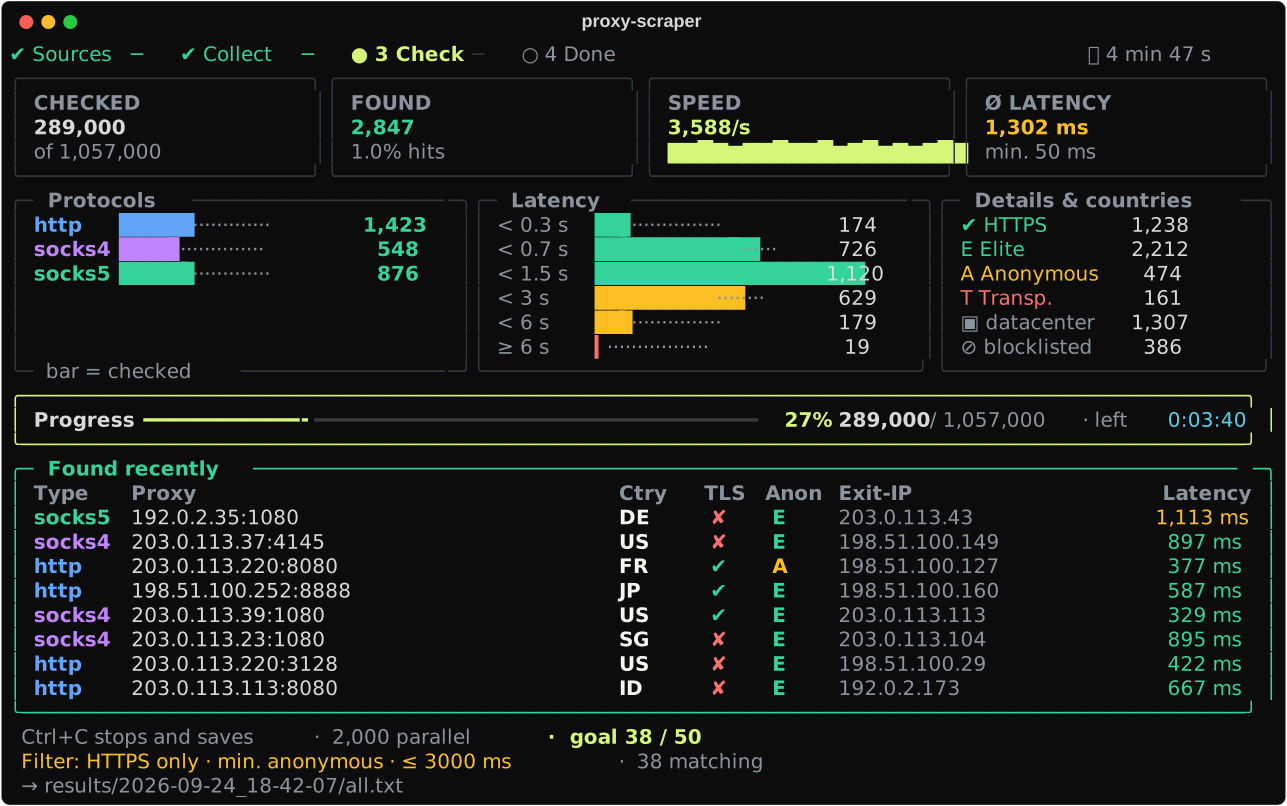
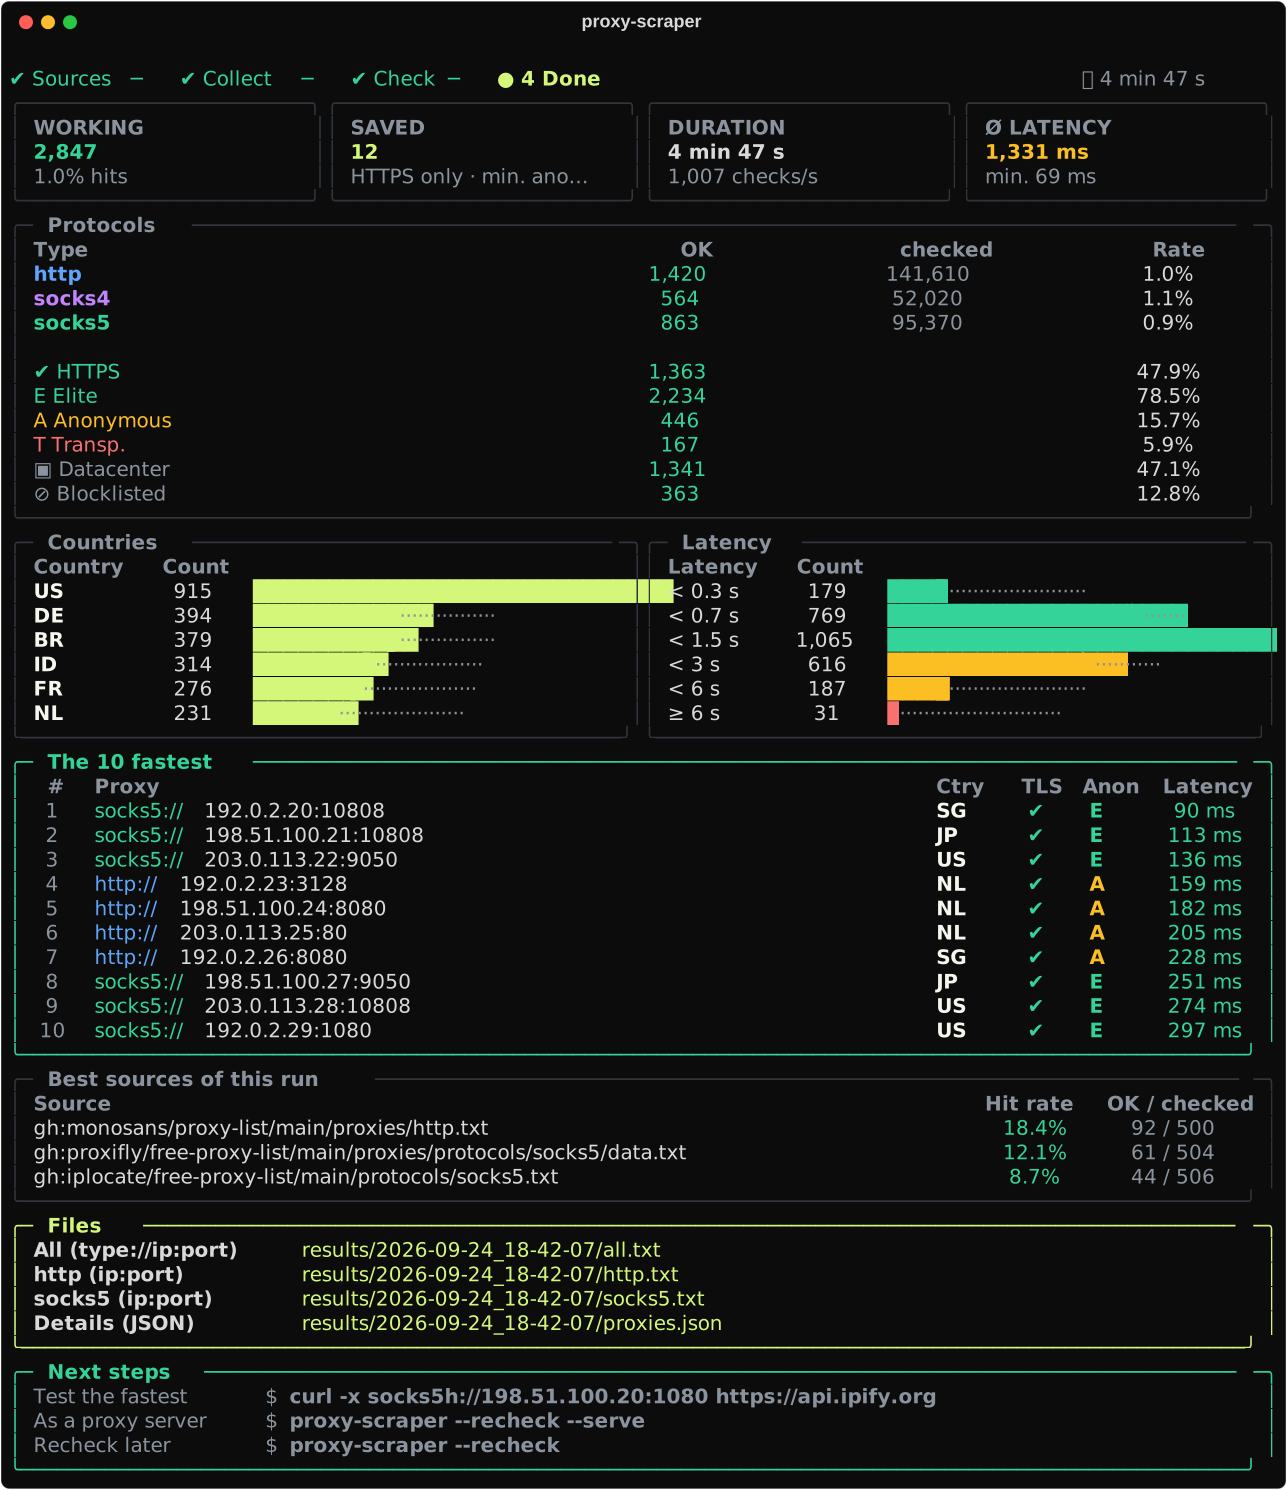
📸 See the live dashboard and final report
Output
Every run gets its own folder; results/latest.txt always names the newest one (on macOS/Linux there is also the symlink results/latest):
Recipes
Use the fastest proxy from the last run – free proxies die quickly, so --recheck first if the run is older than a few minutes
For HTTPS, pick a proxy with "https": true from proxies.json – like the Python example below does.
Python requests (pip install "requests[socks]" for SOCKS)
httpx (pip install "httpx[socks]") – straight from the hourly list, no scan
aiohttp (pip install aiohttp aiohttp-socks – aiohttp alone can't do SOCKS)
Scrapy – a downloader middleware that sends every request, retries included, through the next proxy. Scrapy only speaks HTTP proxies, https=True picks the ones that can tunnel https:// pages
In a Scrapy project, put RotatingProxy in middlewares.py and add it to DOWNLOADER_MIDDLEWARES in settings.py. For long crawls, reload the pool now and then – the list changes every hour.
proxychains, Clash / Mihomo, sing-box – ready-made configs with --export
clash.yaml has all HTTP and SOCKS5 proxies plus a url-test group that always picks the fastest. singbox.json does the same for sing-box, SOCKS4 included, and opens a local proxy: sing-box run -c results/latest/singbox.json, then use 127.0.0.1:2080 as HTTP or SOCKS5 proxy. All three leave out HTTP proxies that can't tunnel (CONNECT), because these tools tunnel everything.
In a pipe – -o - prints the hits to stdout, the interface moves to stderr
Any tool, through the rotating server
In a GitHub workflow – the action picks working proxies for the next steps
proxy is the fastest one, file a text file with all of them (up to limit, default 20), count how many. Without a match the step fails, unless fail-if-empty: false.
In the shell, without a scan – --pick takes proxies from the hourly list in about half a second
"Fastest first" means the first answer plus the download speed measured in the last check – in a test with real pages, the 25 fastest by download loaded four times as many pages as the 25 quickest to answer a tiny request.
Without installing anything – straight from the live list
The shell snippets are for macOS and Linux, where results/latest points to the newest run. On Windows, results/latest.txt holds the folder name instead – in PowerShell:
Options
Show all options
| Option | Description |
|---|---|
-i, --interactive | setup wizard (shown automatically without arguments) |
-y, --yes | start right away without the wizard |
--types http socks5 | only these protocols |
-l, --limit N | only check the N most promising proxies |
--want N | stop as soon as N matching proxies are found |
--country DE,AT | only these countries |
--https-only | only proxies that can tunnel HTTPS |
--anonymity elite | minimum anonymity (anonymous or elite) |
--max-latency MS | maximum latency |
--no-datacenter | skip proxies whose exit is (probably) in a datacenter – those get blocked sooner |
--no-blocklisted | skip proxies whose exit IP is on the SpamCop blocklist – those often get captchas |
--no-dnsbl | skip the blocklist lookup |
--target URL | only proxies that reach this site (repeatable) |
--recheck [FILE|live] | only check proxies from a file, the last run, or the public live list |
--fast | skip the HTTPS test (confirmation and anonymity still run) |
--no-geo | skip the country lookup |
-c, --concurrency N | simultaneous checks (default: 2000) |
-t, --timeout S | timeout per proxy (default: 8 s) |
--discover | search GitHub for new sources right now |
--no-cache | download every list again (unchanged ones are normally skipped via ETag) |
--list-sources [N] | show the source ranking (add --json for scripts: url, status, hit rate, checks, last change) |
--pick [N] | print N proxies (default 1) from the hourly checked list and exit – no scan, same filters, plus --min-uptime PERCENT, --min-speed KBPS and --works-on google,reddit,… |
--serve-host ADDR | where the proxy server listens (default 127.0.0.1; 0.0.0.0 for Docker, with a warning) |
--serve-password SECRET | clients must send this password in the proxy login; better set PROXY_SCRAPER_SERVE_PASSWORD |
--rotate STRATEGY · --sticky SEC | how the proxy server picks proxies, see above |
--serve-refill HOURS | while serving, check fresh proxies every HOURS and add the hits to the pool |
--serve [PORT] | afterwards serve as a rotating proxy on 127.0.0.1:PORT (default: 8899) |
-o FILE | also write all hits to this file; -o - prints them to stdout |
--export FORMATS | extra files for other tools: proxychains, clash, singbox, curl or all |
-V, --version | print the version |
--completion SHELL | print the tab completion script for bash, zsh, fish or PowerShell |
Everything else: proxy-scraper --help
[!TIP] For the GitHub search a logged-in
ghor theGITHUB_TOKENenvironment variable is enough. Without a token the API limit is 60 requests per hour, and only 40 repos are searched.
GitHub Actions
The repo does part of the work itself:
| Workflow | What it does |
|---|---|
| tests | 3 operating systems × 3 Python versions, plus a built and installed package – on every push and pull request |
| lint | ruff with a pinned version – same rules locally and in CI |
| codeql | security analysis on every push and once a week |
| proxy list | every hour: collect, check, publish to proxy-list. The learned statistics live in the Actions cache, so the tool keeps getting better in the cloud too |
| docker | builds the image on every change and runs a real scan inside it; on a version tag it publishes linux/amd64 + linux/arm64 to ghcr.io |
| release | on a version tag: test, build, smoke-test and publish a GitHub release with the wheel |
| discord bot | tests the bot and deploys it to the server on every change in bot/ |
| Dependabot | keeps the action versions up to date |
FAQ
Almost nothing gets through.
Many company, school and university networks block proxy connections. The tool notices a hit rate below 0.2 % and warns you – a different network such as a phone hotspot helps. The learned statistics are not downgraded in such a run.
Does it work on Windows?
Yes, in PowerShell and Windows Terminal. uvloop doesn't exist there and is skipped automatically. In the old cmd.exe window some symbols may be missing depending on the font.
Why does it find fewer proxies than other lists claim to have?
Because only proxies that pass every check are kept. Many lists count anything that accepts a TCP connection; here a proxy must fetch two independent pages and show a foreign IP. That's usually a few hundred out of a million candidates – but they work.
What about proxies with a username and password?
Lines like socks5://user:pass@1.2.3.4:1080 keep their login: HTTP proxies get a Proxy-Authorization header, SOCKS5 uses username/password auth (RFC 1929), SOCKS4 the user ID. The same works for --recheck with your own list. The result files keep the credentials, the terminal only shows user:•••.
How fresh is the live list?
It's rebuilt every hour; the “updated” badge shows the last run. Free proxies come and go quickly, so for anything important run proxy-scraper --recheck right before use.
Is it safe to use free proxies?
Only for things that don't matter. Public proxies are run by strangers who can read everything that isn't encrypted. Never send passwords or personal data through them, and only use them for legal purposes.
Roadmap
What's next is in the open issues – ideas and wishes are welcome as an issue. During Hacktoberfest there are beginner-friendly issues with pointers on where to start.
Shipped in v1.8 and v1.9: uptime per proxy and stable.txt, which proxies get through to Google, Reddit and Amazon, live_proxies() in Python, a page per proxy with its week of checks, a weekly report, live charts in this README, shareable filters on the website, sources mined from other scrapers' lists, untyped lists tried as HTTP and SOCKS5, --export singbox, PowerShell completion and recipes for httpx, aiohttp and Scrapy.
Shipped in v1.7: an MCP server so AI agents get working proxies and can load pages through them, 28 new sources and a GitHub search that runs daily and keeps what it found, and a cleaner website.
Shipped in v1.6: spam blocklist check for every exit IP, a live list refreshed every hour, pages per protocol and country, an optional password for the proxy server and a pool that refills itself while it runs, compose.yaml, -o - for pipes, a Discord bot, and a new website and README – everything in English now.
Shipped in v1.5: content tampering check, live list website with trend and stable proxies, provider/datacenter info, a much bigger proxy server (rotation strategies, sticky sessions, SOCKS5 inbound, status and Prometheus metrics), --recheck live, Python API, shell completion. Measured and dropped earlier: protocol detection with an extra connection (#3) and IPv6 (#1).
Contributing
Bug reports, new sources and pull requests are very welcome – see CONTRIBUTING.md, and docs/ARCHITECTURE.md for how the pieces fit together. The short version:
Project structure
Acknowledgements
proxy-scraper stands on the work of the people who publish free proxy lists. Thanks to everyone listed in sources.json, and especially to
- monosans/proxy-scraper-checker and gfpcom/free-proxy-list, whose curated source collections are read as meta sources
- Textualize/rich, which draws the whole terminal UI
- IP Geolocation by DB-IP – the free country database (CC BY 4.0) used for offline country lookups
- httpbin, checkip.amazonaws.com, ifconfig.me, ipinfo.io, wtfismyip.com, ident.me and ip-api.com, used as check targets and for country lookups
Disclaimer
This tool only collects publicly listed proxies and checks whether they work. You are responsible for how you use them – respect the terms of the sites you visit and the laws where you live.
Made in Germany by @maximilianfeix · MIT License · Changelog · Security · Contributing
If proxy-scraper saves you time, a ⭐ helps others find it.