Persistent project memory for AI coding agents: one compact digest instead of re-reading the repo.
Quick Install
Automated & IDE SetupCopy the AI prompt to install this server into Claude Code, Cursor, or another agent — or use 1-click editor setup below.
Not yet automatically verified
We haven't yet run this listing's install command through our automated sandbox check. This isn't a red flag — we're steadily working through the catalog.
Manual Client & Custom JSON ConfigExpand JSON ▾
Client Config & Setup
Choose your client or environment
Target File:
💡 Paste the JSON block into your client's configuration file under mcpServers, then restart the application.
Documentation Overview
projectmind
Persistent, compact project memory for AI coding agents. Your agent reads one small digest instead of re-scanning the codebase every session — and a local ledger shows you exactly how many tokens (and dollars) that saved.




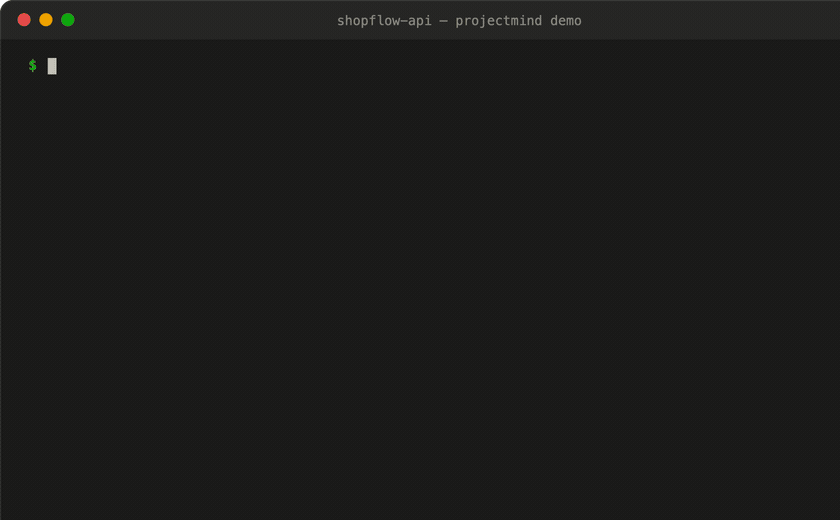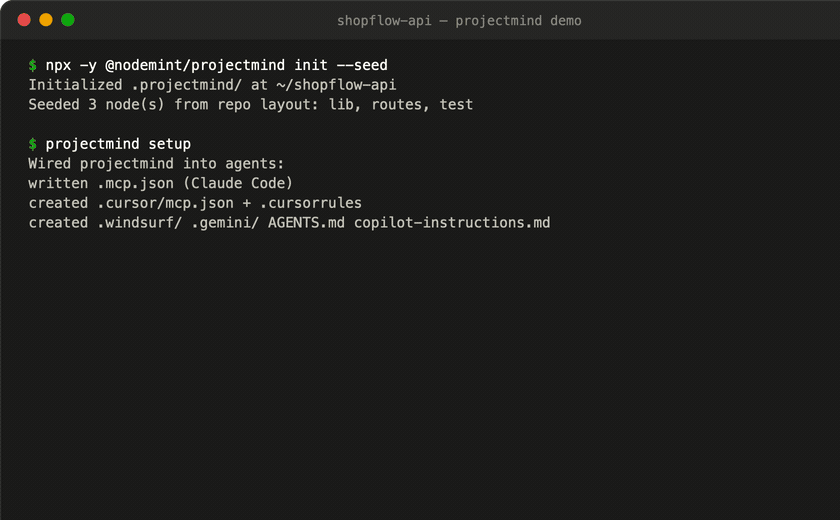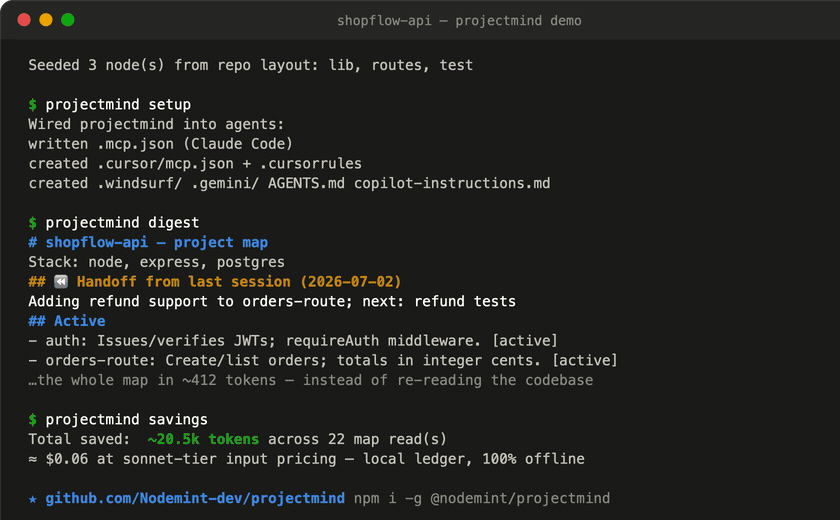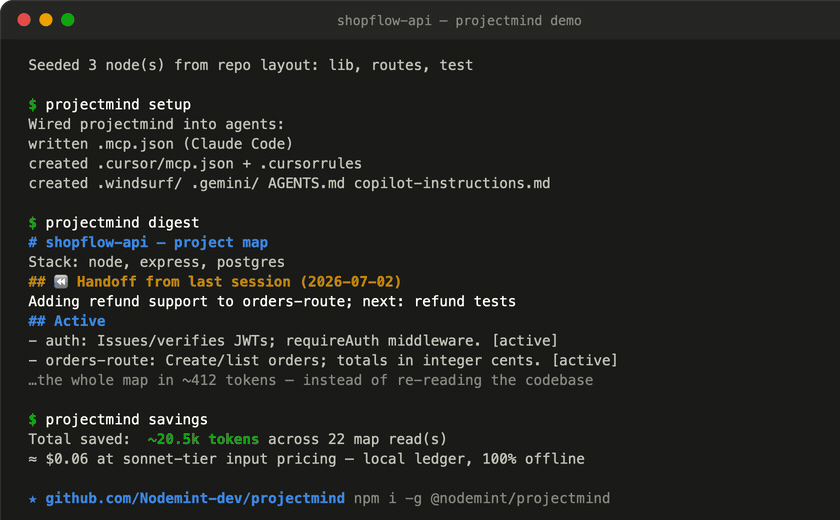

Every AI coding session starts the same way: the agent has no memory of your project, so it re-reads files, re-derives your architecture, or asks you to re-explain decisions you made months ago. You pay for that in tokens, time, and wrong guesses — every single session, on every machine, for every teammate.
projectmind fixes this with a structured, persistent project map
(.projectmind/map.json): your modules, their dependencies, your architectural
decisions, your conventions, your domain glossary. The agent reads a ~400-token
digest first, drills into single nodes only when needed, and writes back what it
learns — so the next session (yours, a teammate's, or a different AI tool's)
starts already knowing the project.
The digest scales with your project's conceptual size (modules, decisions), not its byte size — so the savings grow with the repo.
Quick start — one command
That single init does everything: scaffolds the map, seeds it from your
repo layout, detects which AI agents are installed on your machine and
wires each one (MCP server + a rules file carrying the live map), adds
.projectmind/ to your .gitignore (the map stays local — nothing to push),
and installs the git hook that keeps the map fresh on every commit.
Then the one step no tool can do for you: restart your agent (or start a
new chat session). AI agents load their config and rules files at session
start — a chat that was already open keeps its old context, and every session
after that has the map automatically. Using the VS Code savings extension?
Cmd+Shift+P → "Developer: Reload Window" once.
Want it available in every future project without even running init?
(projectmind init --bare scaffolds only, and projectmind setup re-wires
agents on demand, if you prefer the pieces separately.)
See what it saves you — measured, not promised
The MCP server keeps a local savings ledger: every time your agent reads the map instead of scanning files, it records the tokens actually served vs. the estimated tokens of the files the agent would have read instead.

Check it anytime:
The dollar figure needs zero configuration: it defaults to Sonnet-tier input
pricing from a built-in table of published rates (Haiku $1 / Sonnet $3 / Opus $5
/ Fable $10 per MTok input, as of June 2026), and says exactly which assumption
it used. If you run a different model, set savings.model (or an exact
savings.inputPricePerMTok) in .projectmind/config.json — but nobody has to.
(Real output from a scripted day of agent work on the sample project in
test/fixtures/ — 12 session starts, 6 module drill-ins, 4 task-context reads.
Reproduce the per-session number with npm run benchmark.)
VS Code status bar: the integrations/vscode extension
shows a live ✦ ~20.5k tokens saved counter that reads the same local ledger.
Zero dependencies, zero network.
The ledger is honest by design: every number is labelled an estimate
(ceil(bytes ÷ 4), the rough English+code average), savings are floored at zero,
and the file is gitignored — it's your private data, on your machine, deletable
at any time.
One deliberate gap, stated plainly: the ledger only counts tool calls
(mind_digest, mind_query, mind_context). The embedded digest described
below never requires a tool call — that's the whole point — so its savings
don't show up as a number here. projectmind savings names which rules files
carry it instead of inventing a token count we can't actually observe.
Session handoff — pick up exactly where you left off
The thing every agent session loses is working state: what you were in the middle of, what's next, the gotcha you just discovered. Code graphs can't capture it; chat history dies with the session. projectmind carries it over:
Your agent calls mind_handoff before the session ends (or before its context
gets compacted); the note leads the very next digest, so the next session —
tonight on your laptop, tomorrow on your desktop, or a different AI tool
entirely — resumes in one read instead of re-deriving the task. Notes live in
your gitignored local overlay: personal working state, never committed, cleared
with mind_handoff({clear: true}) when done. Humans can use it too:
projectmind handoff "note".
Works everywhere your team works
No language assumptions, no platform assumptions: the full test suite (85 tests, including the git-hook end-to-end and offline-guarantee tests) runs in CI on Linux, macOS, and Windows × Node 18/20/22. Paths, globs, atomic renames, and the installed git hook are exercised on all three. The map format is plain JSON — nothing OS-specific is ever written to your repo.
Verified against real open-source repos (fresh clone → projectmind init --seed,
2026-07-02):
| Repo | Stack detected | Seeded nodes | Repo size (est.) | Digest |
|---|---|---|---|---|
| expressjs/express | node | examples, lib, test | ~175k tokens / 152 files | ~86 tokens |
| pallets/flask | python | examples, src, tests | ~153k tokens / 104 files | ~111 tokens |
| flutter/pinball | dart, flutter | lib, packages, test, web | ~513k tokens / 637 files | ~99 tokens |
That's the core scaling property in the wild: the digest tracks a project's conceptual size, staying ~100 tokens whether the repo is 150k or 500k tokens. (A freshly seeded digest is a starter skeleton — a curated map with decisions and conventions lands around 400 tokens, like the benchmark fixture. We quote the honest per-session savings number — 78.9% — from the benchmark, not from these whole-repo ratios.)
How it works
Two update paths keep the map current without burning tokens:
- Deterministic: the git hook (and optional
projectmind watch) map changed files to modules via globs and bump freshness. Pure local computation, zero LLM. - Agent-recorded: when the agent makes an architectural decision or learns a
convention, it calls
mind_update— a few tokens once, instead of re-discovery every session.
There is deliberately no background LLM summarization — that would burn the tokens this tool exists to save.
What the agent actually reads
Related MCP Servers
Adoption & maintenance
Factual signals from GitHub, npm, and our automated checks — not a rating.
GitHub stars
2
Stargazers on the source repository.
Last commit
2mo ago
Most recent push to the default branch.
Reviews
No reviews yet — be the first to share how this listing worked for you.
Frequently Asked Questions about Projectmind
AllMCPs Directory Badge
Showcase your server listing on GitHub or your project documentation. Embed this dynamic SVG badge to highlight official listing status and live engagement.
Badge Style:
Live Dynamic SVG Preview
Markdown (GitHub README)
[](https://allmcps.com/mcp/projectmind)HTML Embed
<a href="https://allmcps.com/mcp/projectmind"><img src="https://allmcps.com/api/badge/projectmind?style=directory" alt="Projectmind on AllMCPs" /></a>