PersonalKnowHow README
The full upstream README, mirrored here for reference. Install config, tool schemas, adoption signals, and an original overview live on the PersonalKnowHow listing page.
Join the Waitlist · Live Demo · Issues
Turns a scattered personal learning/work history — LinkedIn, GitHub, course platforms, Gmail completion emails, sibling project repos — into a unified knowledge graph, queryable with semantic search instead of keyword matching. Run it locally against your own data in two commands, no account required — or query the real, deployed MCP servers described further down.
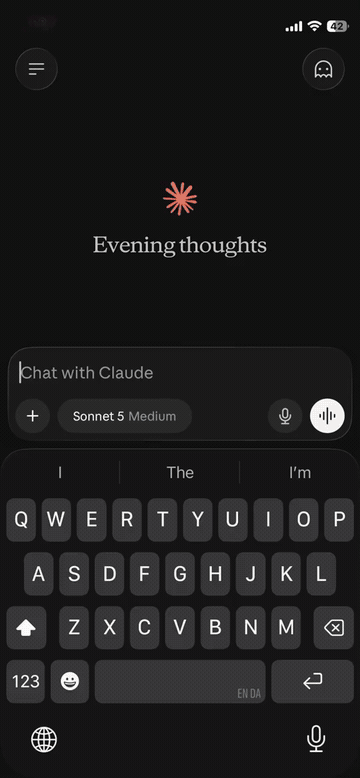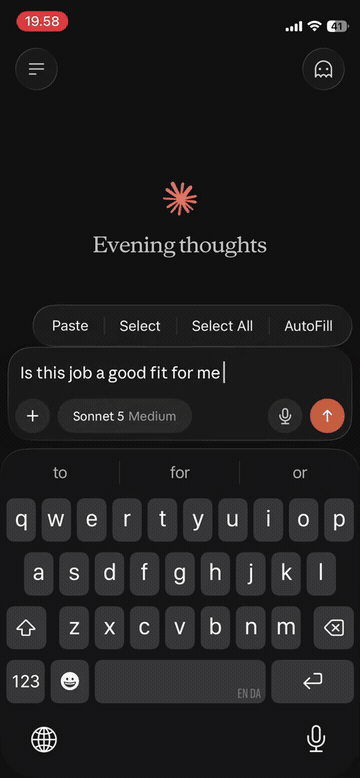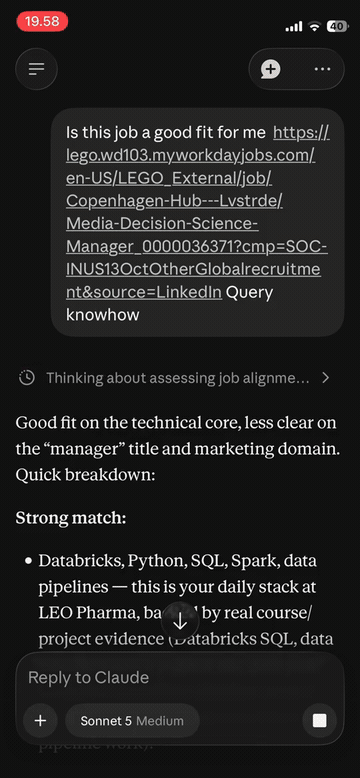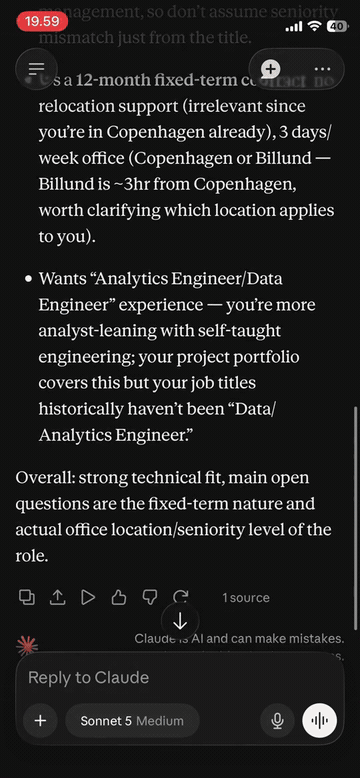
Asking Claude (via the deployed MCP server) to evaluate a job posting against the graph — real evidence pulled from LinkedIn/GitHub history, not a guess. (full-resolution video)
Try it locally in 60 seconds
No Cloudflare account, no signup, nothing deployed — just your own machine.
quickstart.py auto-detects whatever sources are already available on your machine and skips
the rest with a clear reason — at minimum, an already-authenticated GitHub CLI (gh auth login)
or your sibling project repos are enough to get real results. query_local.py embeds your graph
with a small local model (BAAI/bge-small-en-v1.5
via sentence-transformers, downloaded once from Hugging Face on first run — the one real network
dependency of local mode, distinct from needing a cloud account) and ranks results by cosine
similarity, the same approach the deployed MCP servers use.
Want your own LinkedIn history in the graph, not just GitHub/local-project evidence? Request your export at linkedin.com → Settings & Privacy → Data privacy → Get a copy of your data, then:
quickstart.py handles unzipping and routing it to the right ingest script itself — no manual
file placement, no flags to figure out. (Requesting the export happens entirely on LinkedIn's
site and can take a few minutes for them to prepare — everything after that is the two commands
above.)
Every other source (edX, DataCamp, Gmail) needs its own one-time setup (a hand-populated JSON
file or OAuth credentials) — quickstart.py detects and skips each one gracefully with a
one-line reason if it's not set up; see ingest/CLAUDE.md for per-source
details if you want to add one.
Try the live demo
https://personalknowhow-demo.kxtwrdzt6g.workers.dev/mcp is a real, deployed MCP server — but
it's not a webpage. Opening that URL in a browser sends a plain GET, and MCP servers only
speak POST with JSON-RPC framing, so you'll just see a bare {"error":{"message":"Method not allowed."}}. That's expected, not broken — it means you're looking at it the wrong way.
The actual way to use it is as an MCP connector. In Claude Desktop, edit
claude_desktop_config.json (config file location):
Restart Claude Desktop, then ask something like "use personalknowhow-demo to check if I have
Django experience" — Claude calls the query_knowhow tool over MCP and gets back
semantically-matched evidence (courses, projects, certifications) with similarity scores, no
auth required.
If you just want to confirm the server is alive without setting up a client:
A 200 with a JSON-RPC response back confirms it's live — the Accept header above is required;
without it the server correctly returns 406 Not Acceptable, which is a different, also-expected
error from the browser-GET one above.
Why this exists
Course-completion lists and keyword-matched resumes are a weak signal of what someone actually knows. This project builds a real knowledge graph from primary sources (not self-reported summaries), embeds every entry with a real embedding model, and exposes it as a queryable MCP tool — so "do I have Django experience?" gets answered by walking real evidence (a project's README, a course completion, an endorsement) with a similarity score attached, not a guess.
Architecture
Ingestion sources: LinkedIn (via the Member Data Portability
API, EU-only —
see docs/linkedin-connector-notes.md for notes on the
manual-export alternative for other regions), GitHub (via the gh CLI, excluding forks — a fork
is evidence of browsing, not building), DataCamp/edX/Skilljar course completions, Gmail
(completion emails from other platforms), and sibling project repos (auto-discovered, evidenced
via README + tracked filenames + a keyword pass, not self-reported).
ingest/merge.py deduplicates across sources (idempotent — safe to re-run). ingest/build_graph.py
extracts nodes/edges from corpus/ frontmatter into graph.json.
The RAG layer
Both mcp/ and mcp-private/ are stateless Cloudflare Workers (createMcpHandler, no Durable
Object) that embed every corpus entry with Workers AI (@cf/baai/bge-base-en-v1.5, 768-dim) at
export time, and embed the query string at request time, then rank by cosine similarity. Two MCP
tools are exposed: query_knowhow(topic) for semantic search, and list_by_type(type) for a
plain listing. The private server additionally tags every result with an evidence_tier
(demonstrated vs. signal_only), so a job application or career-interest entry can never be
mistaken for proof of a skill.
Privacy design
corpus/ and graph.json are never public — no public-facing code reads them directly. The
only sanctioned public data source is mcp/public_entries.json, built by
ingest/build_public_export.py via a fail-closed allowlist: only explicitly listed corpus
categories (courses, projects, certifications, education, endorsements, positions, profile,
recommendations, articles) get exported. A new corpus category is excluded by default until
someone deliberately adds it to the allowlist — the same discipline that keeps job applications
and career-interest data out of the public server entirely; that data only exists in
mcp-private/, gated behind a bearer token, and is never committed to this repo either (see
.gitignore).
Career-agent tooling
A second layer built on top of the same corpus: ingest/analyze_job_postings.py scores scraped
job postings against known skill coverage using the same embeddings (graded known/peripheral
similarity, not binary keyword matching), ingest/cv_tailor.py matches a posting's requirements
against CV bullets with an explicit two-tier system (exact-term matches vs. semantically-related
matches, the latter always labeled "verify before claiming" rather than asserted), and
ingest/recommend_courses.py cross-references course catalogs against coverage gaps.
Running individual ingest sources manually
python quickstart.py (see the top of this README) runs everything below automatically for
whichever sources it detects. For finer control — a single source, non-default flags, or
re-running just one step after a corpus change — run any of these directly:
Each ingest/*_ingest.py script is independent — run whichever sources apply to you. All of them
write markdown into corpus/<source>/ using the shared schema below.
Corpus schema
Every markdown file in corpus/ uses this YAML frontmatter:
Deploy your own hosted MCP server (optional, needs a Cloudflare account)
Local mode (above) is enough to query your own graph — this section is only for hosting it as a real MCP server other clients/people can connect to, the same way the live demo works.
Both need a Cloudflare account with Workers AI access ([ai] binding, remote = true in
wrangler.toml). Rebuilding the embeddings after a corpus change:
Adding a new ingest source
- Create
ingest/<source>_ingest.pythat reads the raw export and writes markdown files tocorpus/<source>/using the schema above. merge.pyandbuild_graph.pyrequire no changes — they scancorpus/generically.- If the new category should ever be public, add it deliberately to
ALLOWLISTiningest/build_public_export.py— it's excluded by default otherwise.