Ownvoice README
The full upstream README, mirrored here for reference. Install config, tool schemas, adoption signals, and an original overview live on the Ownvoice listing page.
OwnVoice
Train a LoRA voice adapter for pocket-tts and keep the result: a file on your own disk, not an API subscription.


Requires Python 3.11 or newer. See Install below for the npx / agent-sandbox path.
Table of Contents
- Install
- Quickstart
- CLI Reference
- Features
- How It Works
- Setup-Time Benchmark vs Comparable Tools
- Why OwnVoice Exists
- What OwnVoice Is Not
- Consent and Misuse
- Implementation Status
- FAQ
- Contributing
- License
Install
npx / agent-native environments: OwnVoice is a Python/PyTorch CLI, so the npm package is a thin wrapper, not a Node reimplementation. It bootstraps into the real CLI via uv or pipx, whichever is already on PATH, useful for coding-agent sandboxes and CI runners that default to a Node toolchain. The npm package was renamed to ownvoice-cli (from the old plain ownvoice, now deprecated) to match its PyPI counterpart.
Both the npm wrapper and the PyPI package (ownvoice-cli) are live, so the command above works today.
Torch and CUDA: ownvoice check needs no GPU at all and runs on CPU, matching pocket-tts's own CPU-capable design. Training a real adapter is much faster on an NVIDIA GPU. If you have one, install the CUDA build of PyTorch first by following pytorch.org/get-started/locally, then install OwnVoice on top of it, so pip does not silently pull the CPU-only wheel instead. On Apple Silicon or a CPU-only machine, the default pip install of torch is fine: ownvoice check and ownvoice infer run normally, ownvoice train just takes longer per epoch.
Quickstart
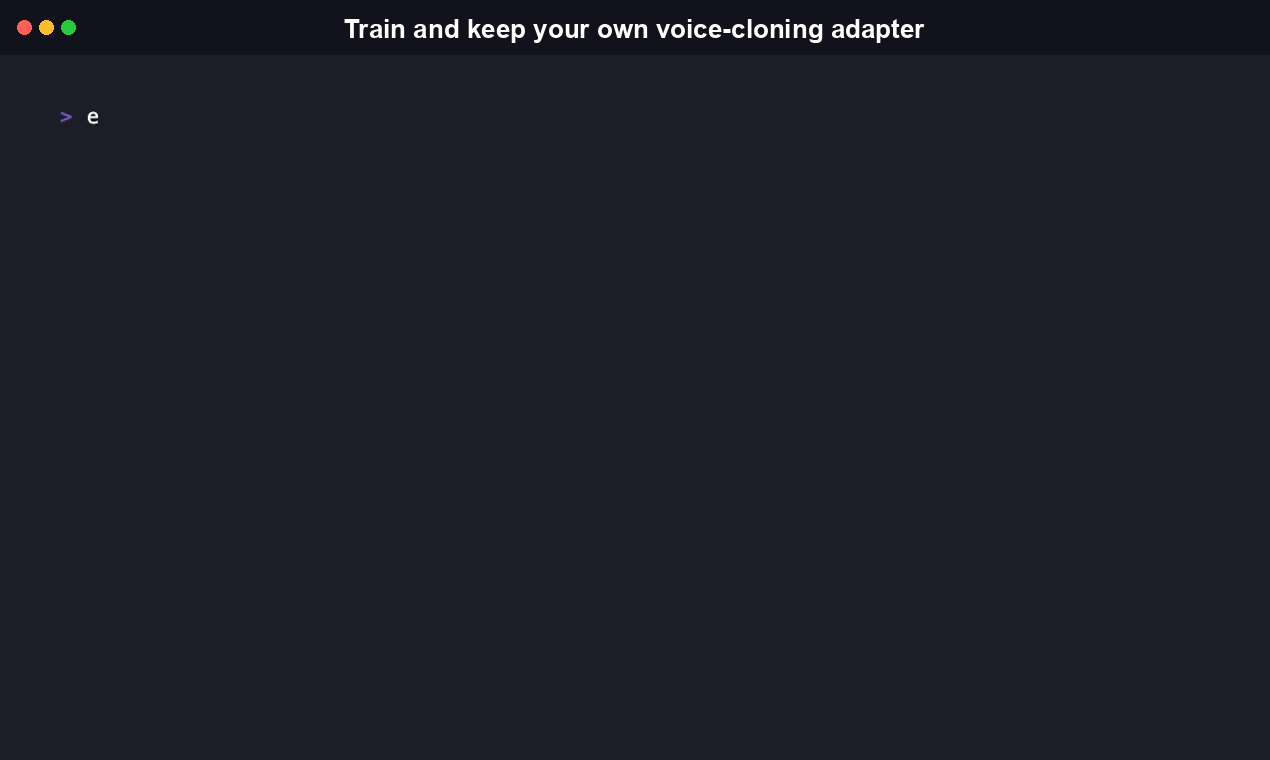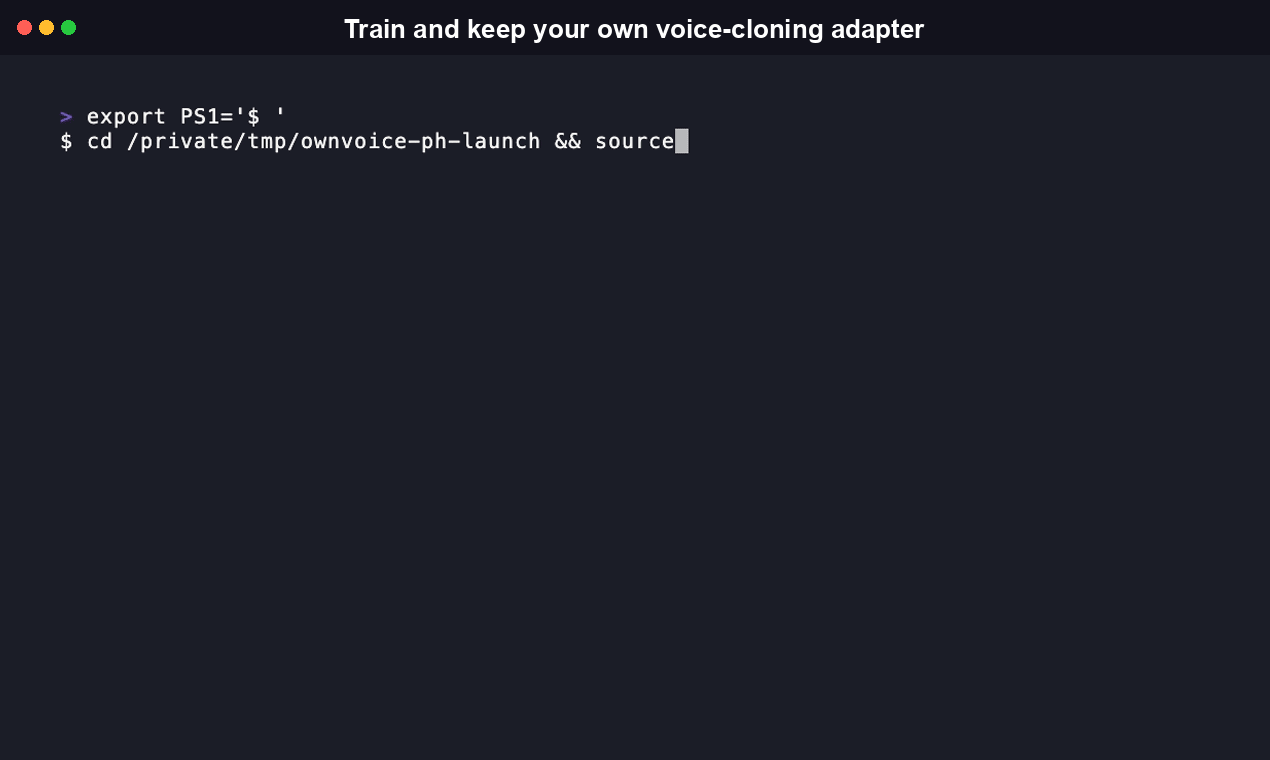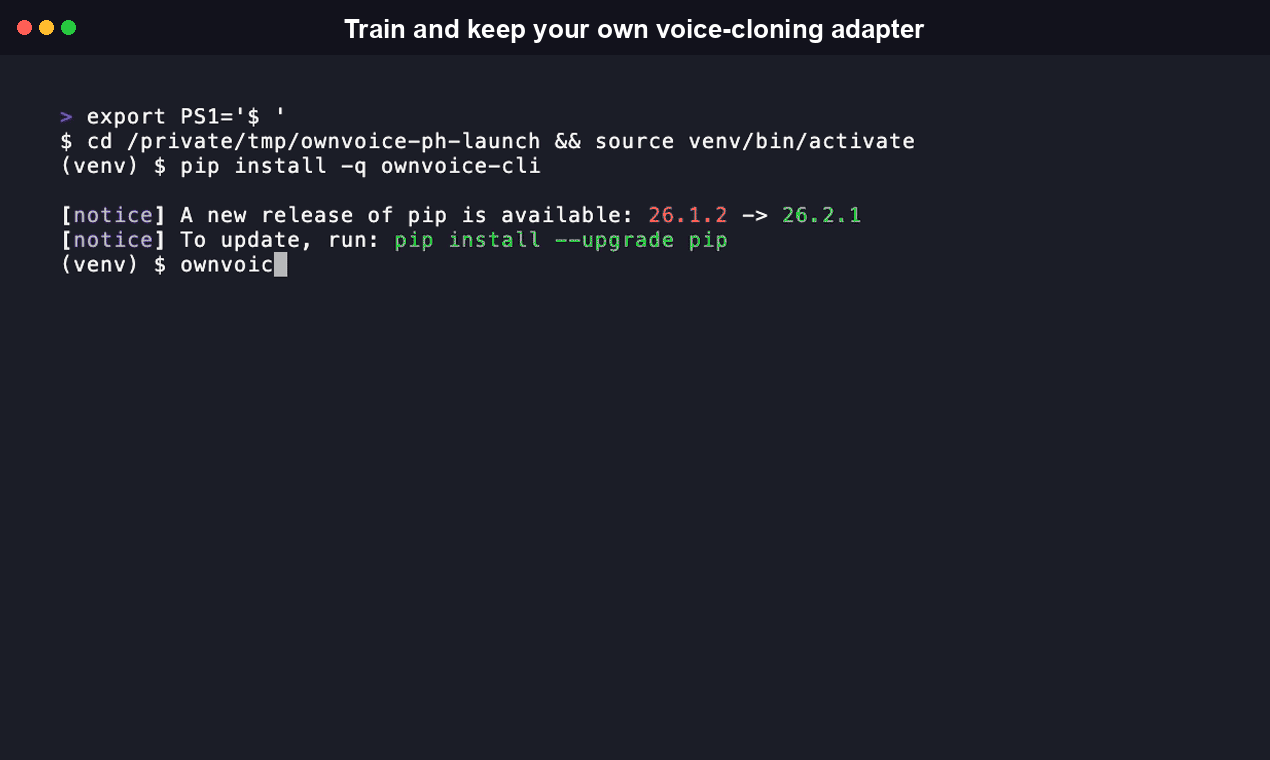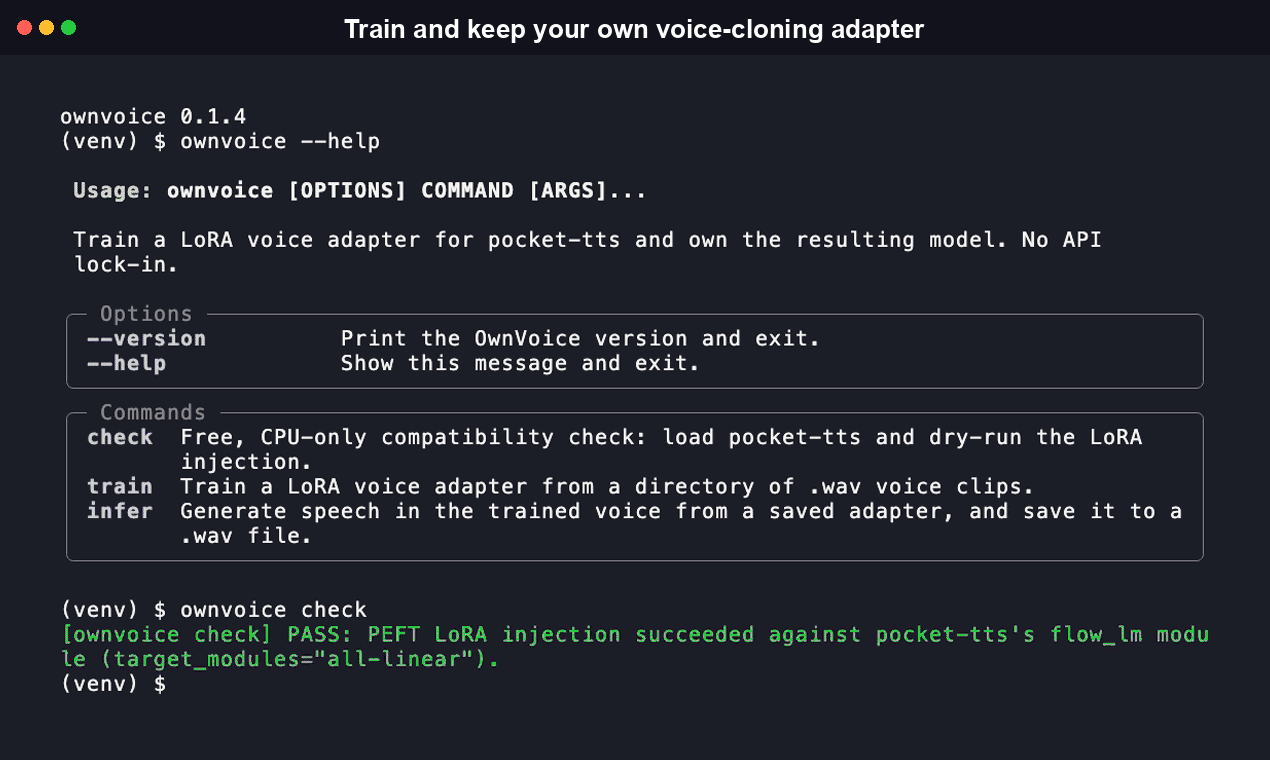
1. ownvoice check, the free Day-0 validation
Before recording anything or renting a GPU, confirm that PEFT's LoRA injection actually works against pocket-tts's real model structure. This is entirely free: CPU only, no training, no GPU.
If it fails, OwnVoice prints the model's real module tree instead of a raw stack trace, so you can see exactly what did not match and report it precisely:
2. ownvoice train
Record 5 to 10 minutes of clean audio of the voice you want to train (your own voice, with your own consent, see Consent and misuse), split into a few .wav clips in one directory, then point OwnVoice at it:
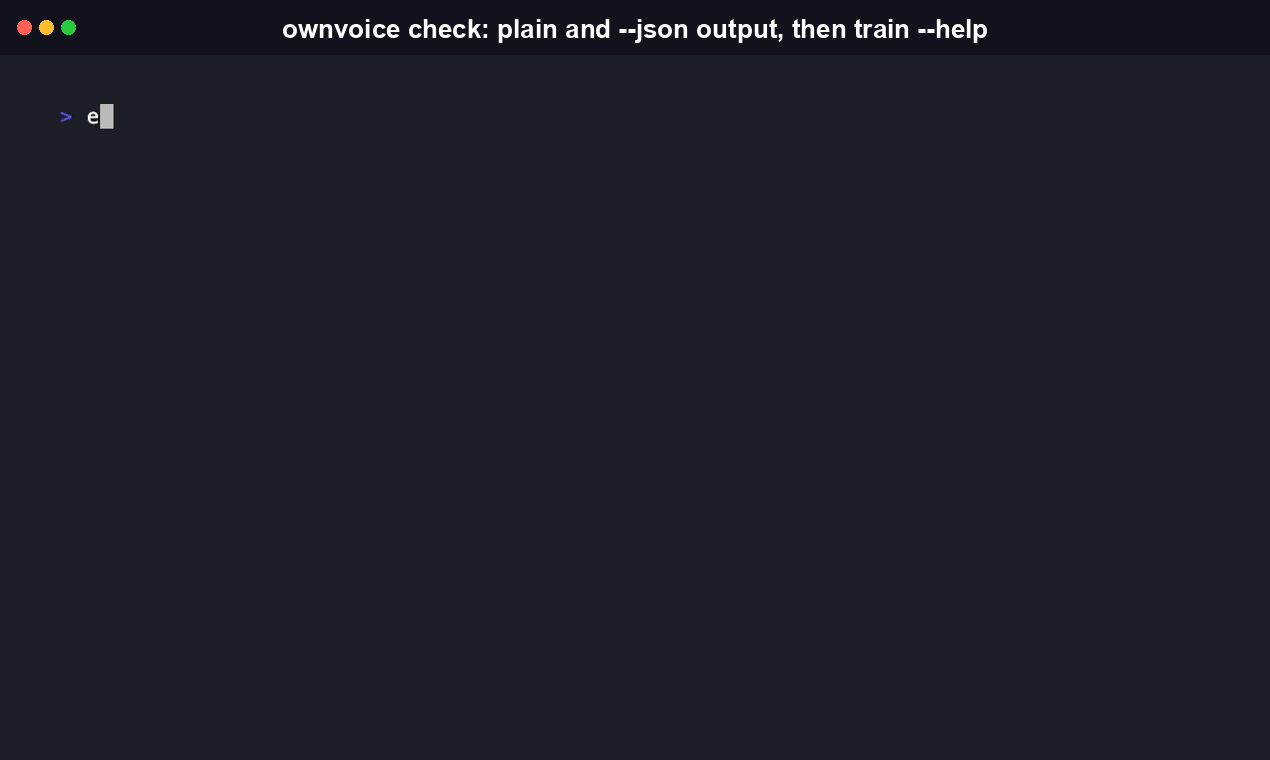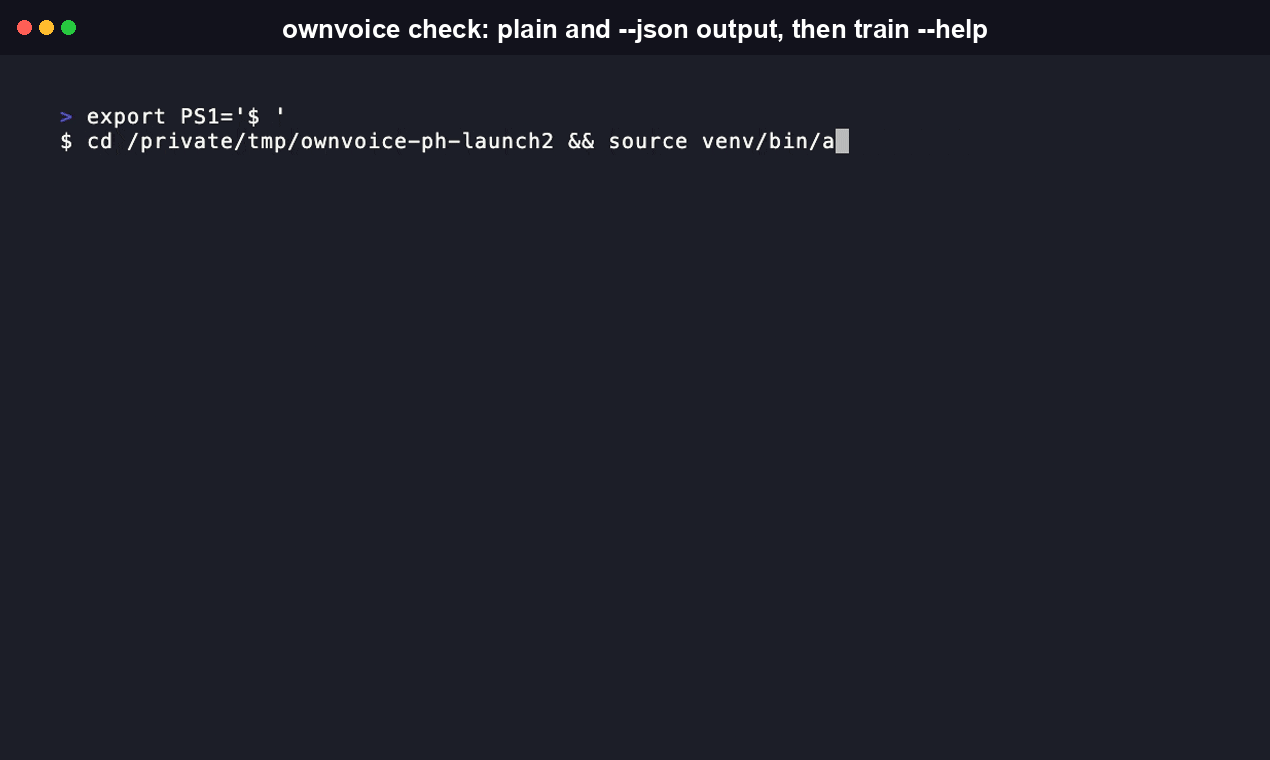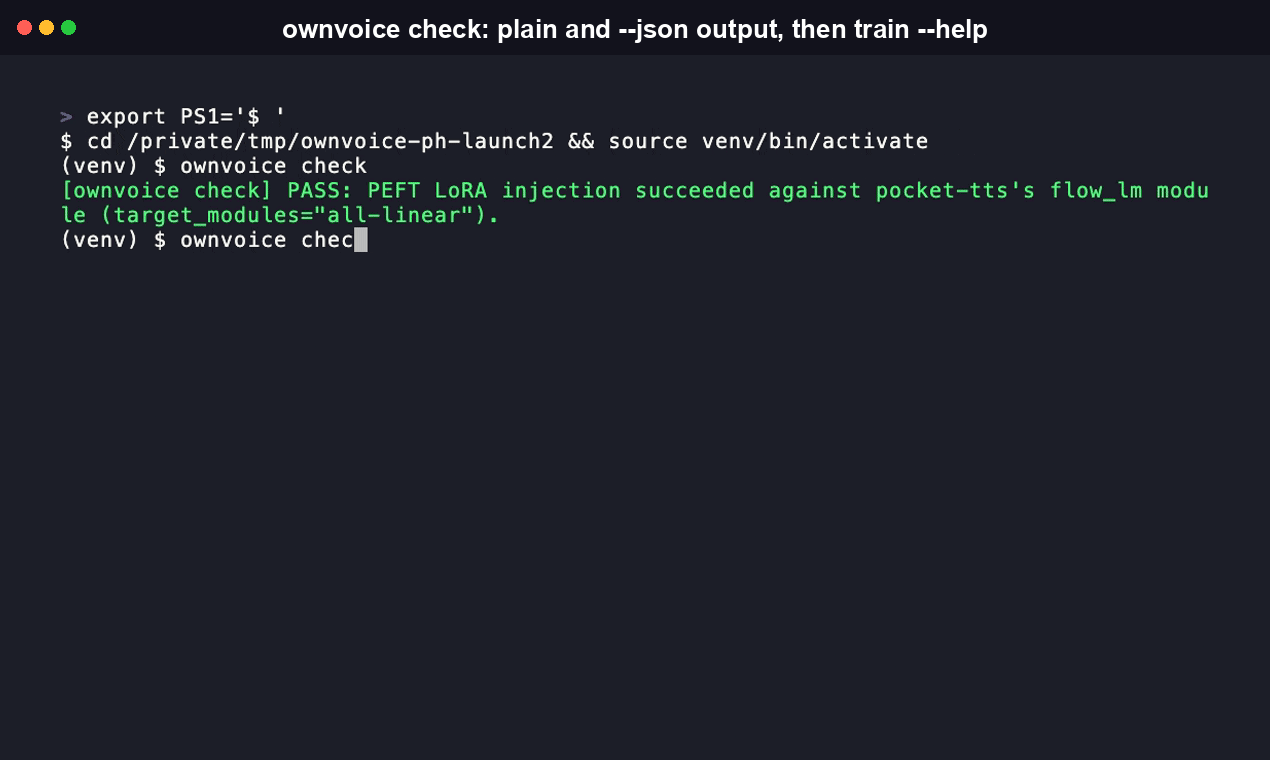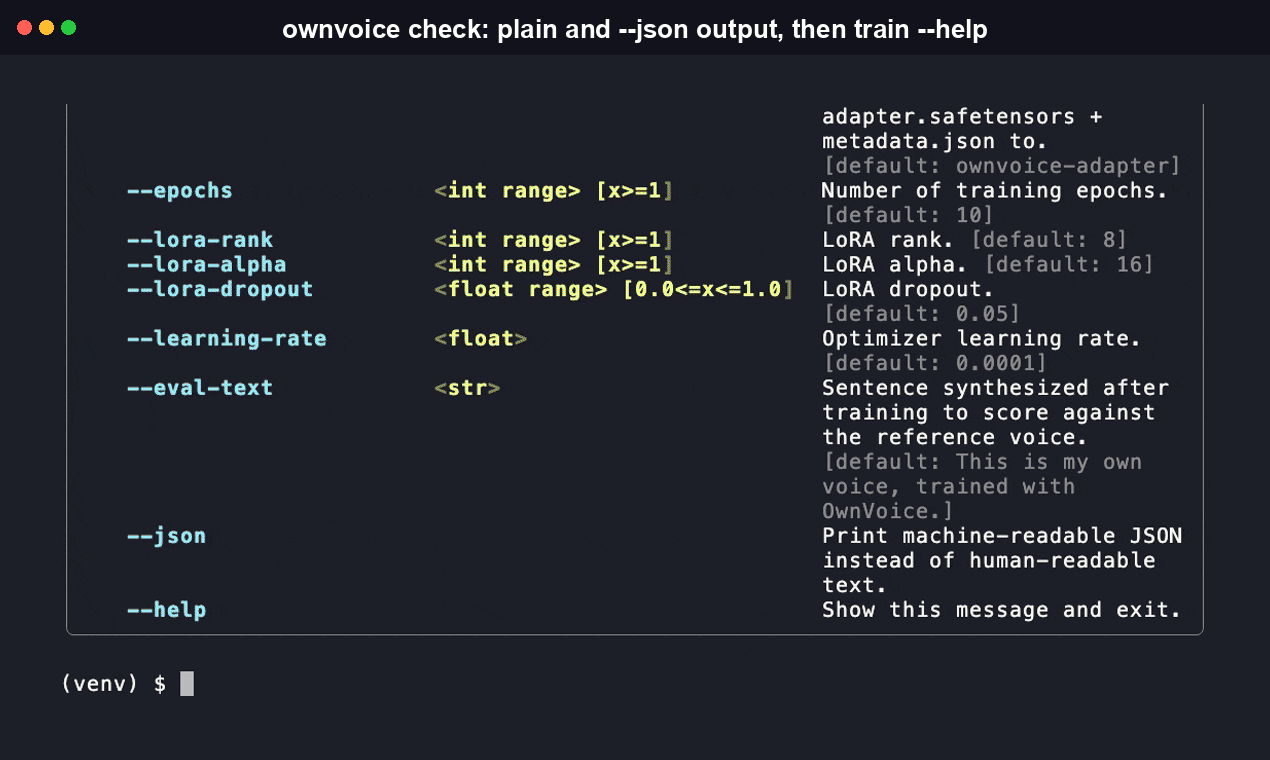
Only --voice-clips is required. Every other flag has a sensible default (see the full CLI Reference below).
A run that finishes but does not clear the similarity bar still exits 0. It is a labeled result with a concrete next step, not a crash:
Only a data-loading problem (no usable clips) or a caught PEFT-injection failure exits non-zero. A finished run always writes adapter.safetensors and metadata.json (training config, similarity score, a timestamp) to the output directory: two files you keep, with no server round-trip needed to use them again.
3. ownvoice infer
Every subcommand also supports --json for a structured, machine-parseable output mode, useful if a script or an agent is calling ownvoice programmatically instead of a person reading the terminal:
CLI Reference
Reference below is taken directly from each subcommand's real --help output (ownvoice-cli 0.1.2 on PyPI).
Global
| Flag | Description |
|---|---|
--version | Print the OwnVoice version and exit. |
--help | Show the help message and exit. |
ownvoice check
Free, CPU-only compatibility check: load pocket-tts and dry-run the LoRA injection. No GPU and no training required.
| Flag | Description |
|---|---|
--json | Print machine-readable JSON instead of human-readable text. |
--help | Show the help message and exit. |
ownvoice train
Train a LoRA voice adapter from a directory of .wav voice clips. Only --voice-clips is required.
| Flag | Type | Default | Description |
|---|---|---|---|
--voice-clips | directory, required | – | Directory of .wav voice-clip recordings to train from. |
--out | path | ownvoice-adapter | Directory to write adapter.safetensors + metadata.json to. |
--epochs | int, >=1 | 10 | Number of training epochs. |
--lora-rank | int, >=1 | 8 | LoRA rank. |
--lora-alpha | int, >=1 | 16 | LoRA alpha. |
--lora-dropout | float, 0.0–1.0 | 0.05 | LoRA dropout. |
--learning-rate | float | 0.0001 | Optimizer learning rate. |
--eval-text | string | "This is my own voice, trained with OwnVoice." | Sentence synthesized after training to score against the reference voice. |
--json | flag | off | Print machine-readable JSON instead of human-readable text. |
--help | flag | – | Show the help message and exit. |
ownvoice infer
Generate speech in the trained voice from a saved adapter, and save it to a .wav file.
| Flag | Type | Default | Description |
|---|---|---|---|
--adapter | path, required | – | Path to a trained adapter.safetensors file. |
--text | string, required | – | Text to synthesize in the trained voice. |
--out | path | ownvoice-output.wav | Output .wav file path. |
--reference-audio | path | recorded reference | Override the reference clip OwnVoice recorded in metadata.json at train time. |
--json | flag | off | Print machine-readable JSON instead of human-readable text. |
--help | flag | – | Show the help message and exit. |
Features
- A free compatibility check before you spend anything on a GPU.
ownvoice checkloads pocket-tts and dry-runs PEFT's LoRA injection against its realflow_lmmodule tree, CPU only, no training. On failure it prints the actual module tree instead of a stack trace, so a real blocker is reportable instead of silent. - An objective usable/not-usable signal, not a guess. Every training run resamples the generated test utterance to 16kHz mono and scores it against your reference clips with Resemblyzer cosine similarity.
0.75or higher is labeledUSABLE ADAPTER; anything lower isBELOW THRESHOLD, a labeled outcome and not a crash, exit code0either way. - Structured output on every subcommand.
check,train, andinferall accept--json, returning one machine-parseable object instead of colored terminal text: confirmed directly,ownvoice check --jsonreturns{"success": true, "message": "...", "module_tree": null}. - Two files you keep, no server round-trip. A finished training run writes
adapter.safetensors(the trained weights, a few megabytes at the default--lora-rank 8) andmetadata.json(the full training config, similarity score, per-epoch loss, and a timestamp) to disk. Load them back any time later withownvoice infer, no network call required. - One base model, on purpose. OwnVoice wraps pocket-tts only. There is no abstraction layer for a second base model, matching the codebase's own single-target-by-design architecture note: the LoRA injection path (
target_modules="all-linear"against pocket-tts's realflow_lmlayers) stays exact instead of generic.
How It Works
ownvoice/data.py loads and validates the voice-clip directory. ownvoice/train.py loads pocket-tts's frozen base model, injects a LoRA adapter into its flow_lm transformer with PEFT (target_modules="all-linear"), runs the training loop, and saves the adapter plus a manifest. ownvoice/infer.py loads a saved adapter back onto the base model and generates speech. ownvoice/score.py resamples audio to 16kHz mono with torchaudio.transforms.Resample and scores speaker similarity with Resemblyzer.
OwnVoice is intentionally single-model: it wraps pocket-tts only, with no abstraction layer for a second base model, since none is in scope.
Setup-Time Benchmark vs Comparable Tools
| Tool | Time to first working setup | Notable design choice | Source |
|---|---|---|---|
| kokoro-tts | under 2 minutes | pip install git+..., instant CLI synthesis, no fine-tuning | kokoro-tts README |
| Unsloth | under 1 minute to start a run | one-command training start (uv pip install) | Unsloth docs |
| pocket-tts | seconds | --voice <wav> zero-shot cloning, no training available | pocket-tts README |
| OwnVoice | under 2 minutes to a confirmed-working training environment | ownvoice check: free, instant, CPU-only PEFT-compatibility validation before spending anything on a GPU | this repo |
OwnVoice's own training run is real GPU time, honestly labeled and not hidden behind a fake progress bar, the same category norm Unsloth uses. What OwnVoice compresses to under two minutes is everything before that: confirming your environment actually works.
Why OwnVoice Exists
pocket-tts is a genuinely good, MIT-licensed, CPU-capable local text-to-speech model from Kyutai. Its own maintainers have been clear that fine-tuning code isn't coming any time soon: on issue #30, maintainer @vvolhejn wrote "We are not planning to release fine-tuning code for our TTS and STT models in the near future," and 18 people reacted to that thread asking for exactly this. OwnVoice is a small, standalone CLI that fills that specific gap: point it at a handful of your own voice recordings, and it trains a LoRA adapter you keep and run yourself.
It is not a hosted service, it has no billing, and it does not track usage. It is a training script, an inference script, and a scoring script, wired together behind three CLI commands.
What OwnVoice Is Not
pocket-tts already ships zero-shot voice cloning out of the box: pass a .wav file to --voice (or call get_state_for_audio_prompt() from Python) and it clones that voice with no training step at all. If that is all you need, use pocket-tts directly, it is simpler and faster.
OwnVoice exists for a narrower case: baking a voice permanently into trained weights, so generation no longer depends on distributing or re-processing a reference audio clip at runtime, with (based on the training objective, not yet independently benchmarked at scale) more consistent output across many generations than a single-clip zero-shot embedding tends to produce. That is the specific gap the 18 reactors on issue #30 were describing, and it is the only thing OwnVoice adds on top of what pocket-tts already does well.
Consent and Misuse
This tool clones a voice from audio you have the right to use. Do not clone someone else's voice, or a public figure's voice, without their explicit consent. OwnVoice ships no bulk-generation or auto-scaling feature in this version, keeping the blast radius of any single misuse case small.
Implementation Status
This is a young, early-stage release. ownvoice check, the CLI argument parsing, voice-clip validation, the similarity scoring math, and the adapter/manifest save and load path are implemented and covered by the test suite (pytest). LoRA injection was verified structurally against pocket-tts's real source and then confirmed for real: ownvoice check was run against pocket-tts's actual downloaded weights, on CPU, and PEFT's target_modules="all-linear" injection genuinely succeeded. The full training and generation path has since been verified end to end for real too: a real 2-epoch LoRA training run against loaded pocket-tts weights produced a finite, non-NaN flow-matching loss, and the resulting adapter produced a real, non-silent generated .wav file via ownvoice infer. That validation surfaced two real gaps in the naive approach and fixed them: (1) pocket-tts's published, inference-only PyPI package does not actually expose a way to compute the training loss through FlowLMModel.forward() despite its own docstring claiming otherwise, so OwnVoice computes the flow-matching loss directly from flow_lm's real submodules instead; (2) swapping base_model.flow_lm to the PEFT-wrapped model before calling generate_audio() breaks pocket-tts's internal KV-cache state lookup -- no swap is needed at all, since PEFT's LoRA injection already mutates base_model.flow_lm in place. One real, external limitation to know about: the publicly downloadable pocket-tts weights (kyutai/pocket-tts-without-voice-cloning) refuse a raw reference-clip path/URL outright; OwnVoice works around this by pre-loading and resampling the clip itself, but voice-cloning fidelity from that checkpoint is a known limitation of the base model, not an OwnVoice bug -- for kyutai's best-quality cloning weights, request gated access at huggingface.co/kyutai/pocket-tts. Run ownvoice check yourself and read the source before trusting any of it further, that is the right amount of skepticism for a project this early.
FAQ
What is OwnVoice, and why not just use pocket-tts by itself?
OwnVoice trains a LoRA adapter for pocket-tts and saves it to your own disk as adapter.safetensors plus metadata.json. It exists because pocket-tts's own maintainers have said fine-tuning code is not on their near-term roadmap (see issue #30). Once you have a trained adapter, you never need OwnVoice again to use it: ownvoice infer just loads the adapter back onto the base model.
How is this different from pocket-tts's own built-in --voice <wav> zero-shot cloning?
pocket-tts already clones a voice from a single reference clip with no training step, --voice <wav> at the CLI or get_state_for_audio_prompt() in Python. OwnVoice trades that speed for a permanently trained adapter, so generation no longer depends on carrying around a reference clip at runtime, with (based on the training objective, not yet independently benchmarked at scale) more consistent output across repeated generations than a single-clip zero-shot embedding tends to give. If zero-shot is enough for your use case, use pocket-tts directly, it is simpler and faster.
What do I need to install it, and does it run on Apple Silicon or a CPU-only machine?
Python 3.11 or newer, then pip install ownvoice-cli. ownvoice check and ownvoice infer need no GPU at all and run fine on Apple Silicon or a CPU-only machine, matching pocket-tts's own CPU-capable design. ownvoice train runs on CPU too, it just takes longer per epoch; install the CUDA build of PyTorch first if you have an NVIDIA GPU and want training to go faster.
How does OwnVoice compare to kokoro-tts and Unsloth?
kokoro-tts gets you synthesizing speech in under 2 minutes but has no fine-tuning step at all. Unsloth gets a training run started in under a minute but is a general LLM fine-tuning framework, not TTS-specific. OwnVoice is narrower than either: one base model (pocket-tts only), one job (a voice adapter), plus a free ownvoice check step that confirms PEFT's LoRA injection actually works against your environment before you spend anything on a GPU, a check neither of those tools has an equivalent of.
My training run finished but printed "BELOW THRESHOLD", is that a bug?
No. It is a labeled outcome, not a crash, ownvoice train exits 0 either way. Below the 0.75 cosine-similarity bar, the adapter is still saved to disk and OwnVoice tells you plainly to try more or cleaner voice clips, more epochs, or a higher --lora-rank, then re-run. Only two things actually fail the command with a non-zero exit: no usable clips to load, or a caught PEFT-injection failure.
Can I use OwnVoice, and the adapters it produces, commercially?
OwnVoice's own code is MIT (see LICENSE). pocket-tts's code package is MIT too, but the model weights OwnVoice actually downloads and trains against, kyutai/pocket-tts-without-voice-cloning and the gated kyutai/pocket-tts, are licensed CC-BY-4.0, not MIT. CC-BY-4.0 permits commercial use but requires attribution to Kyutai. Since any adapter you train is derived from those weights, check that attribution requirement before shipping a commercial product built on it.
Whose voice can I actually clone with this? Only your own, or someone else's with their explicit, checked consent, never a public figure's voice without it. See Consent and Misuse above. OwnVoice ships no bulk-generation or auto-scaling feature in this version, which keeps the blast radius of any single misuse case small.
MCP Server
OwnVoice ships a Model Context Protocol server, so an MCP-compatible agent can drive ownvoice check / train / infer directly over stdio instead of shelling out and parsing text itself.
Add it to an MCP client's config (for example, Claude Desktop's claude_desktop_config.json):
The server exposes a single tool, run(args: list[str]) -> dict, that shells out to the real ownvoice CLI with the given argv and returns its result as structured JSON, so a caller gets the exact same behavior the human-facing CLI has, including --json mode. Example call: run(args=["check", "--json"]) returns {"result": {"success": true, "message": "...", "module_tree": null}}. A non-zero exit, a launch failure, or a subprocess timeout is always returned as {"error": "..."} rather than raised.
Contributing
Issues and PRs welcome, MIT licensed throughout. If you want to help close the actual gap this project targets, the most useful contribution is upstream: a lightweight LoRA-adapter training script contributed back to kyutai-labs/pocket-tts itself, discussed on issue #30.
License
MIT. See LICENSE.