Read, replay and fork recorded coding-agent runs.
Quick Install
Automated & IDE SetupCopy the AI prompt to install this server into Claude Code, Cursor, or another agent — or use 1-click editor setup below.
One-click editor setup isn’t available for this listing yet — we don’t have a confirmed install command, and we’d rather show nothing than point your editor at the wrong package or host. Follow the project’s own setup instructions, linked above.
Manual Client & Custom JSON ConfigExpand JSON ▾
No confirmed setup config for this listing yet. We only publish a config block when the install details come from the project itself — its README, its docs, or a verified owner. We haven’t found those for orcareplay, and we’d rather show nothing than a guess you’d paste into your client. Follow the project’s own setup instructions for the current steps.
Documentation Overview
OrcaReplay
English · 简体中文 · 日本語 · 한국어 · Deutsch · Français · Español · العربية
Your agent broke something at 2am. Replay it at 9am — exactly, offline, as many times as you like.
Record any coding agent. Reproduce the run byte-for-byte with no model called. Fork it from any step onto a different model and see who gets it right.
Built by the team behind OrcaRouter — one API key and one endpoint
for Claude, GPT, Gemini, Grok, DeepSeek, Qwen and the rest. It is what orca setup points at by
default, and what makes orca compare a single command instead of four provider accounts.
Find us: OrcaRouter All model APIs
Github Repos: OrcaCode Review · OrcaRouter Lite
Connect: X · Discord · Hugging Face · Ollama




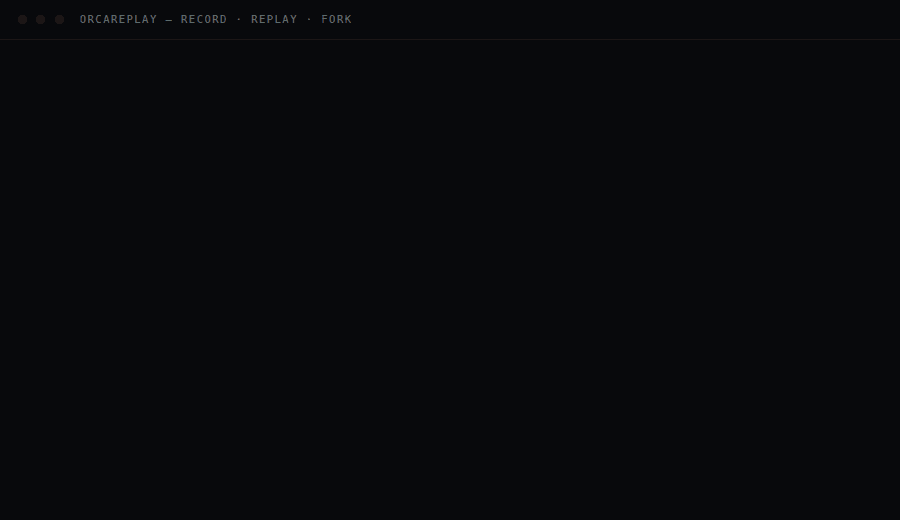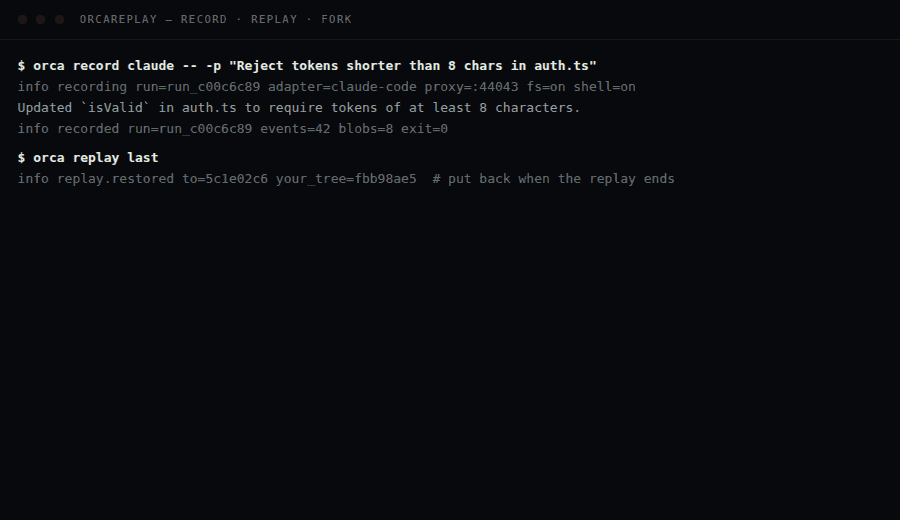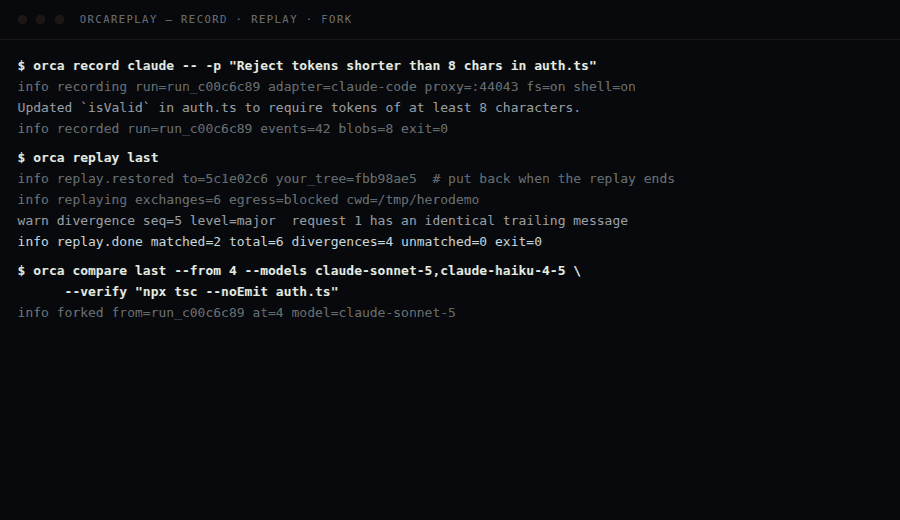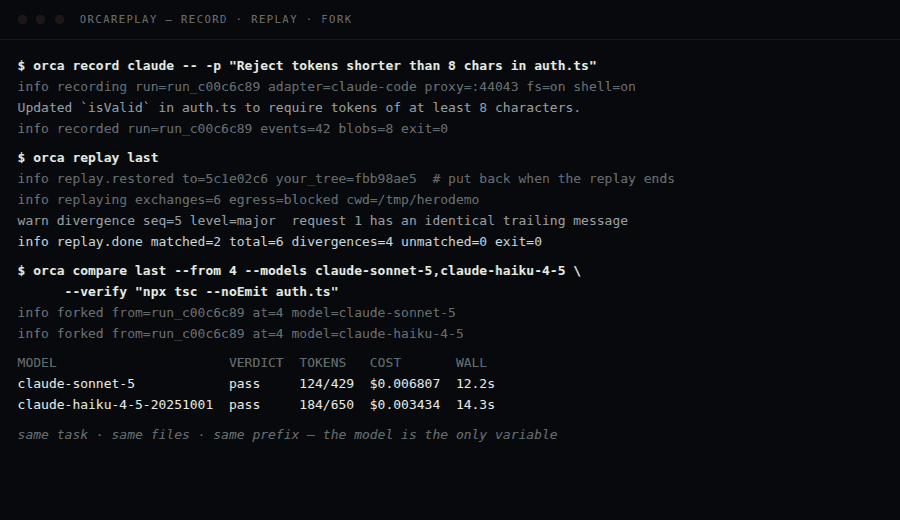
Real output from one session — a Claude Code run recorded, replayed against the recording, then
forked at checkpoint 4 onto two models and graded by npx tsc --noEmit. Nothing here is mocked up.
Try it in three commands
One npm package named orcareplay, which puts one command named orca on your PATH. There is no
separate tool called "orca", and nothing is installed into your agent.
The third line is the one people stay for: same files, same conversation prefix, different model from step 4 onward. The model is the only variable, which is what makes the answer mean anything.
The three commands at the top need an agent installed, a key, a network and real tokens. If you have none of those yet, one command brings its own:
It writes a small project with a genuine bug in it and a recording of an agent fixing that bug,
then replays the recording against the project with no model called: two failing tests before,
four passing after, three turns served from the trace and nothing spent. --full prints the whole
timeline and the replay as it happened.
Read your agent's own system prompt
A proxy that sees the whole loop also sees the prompt the harness assembled before it sent anything. One command captures it, scrubs the machine out of it, and files it by model:
Interactive prompts and -p prompts are not the same prompt, and neither is the same across
models. See capture/README.md for the measured differences, the pitfalls,
and the sanitising rules.
Why this exists
Agent debugging today is archaeology. You scroll a terminal, you re-run and get a different failure, you add print statements to someone else's harness. The tools that exist are observability tools: they tell you a run cost $4.12 and used 61k tokens, which is not the question you have. The question you have is why did it delete my migration file.
OrcaReplay answers that by giving you the run back.
| Observability tools | OrcaReplay | |
|---|---|---|
| Tells you what a run cost | ✅ | ✅ |
| Tells you which tool call deleted the file | sometimes | ✅ |
| Runs the agent again and gets the same answer | ❌ | ✅ from the recording, byte-for-byte |
| Lets you change the model and re-run from step 4 | ❌ | ✅ |
| Needs you to modify your agent | usually an SDK wrapper | ❌ two env vars |
| Works after you close the terminal | ❌ | ✅ it is a file |
| Sees past the model API — shell exit codes, file writes | ❌ | ✅ every turn |
| Records an agent with no API endpoint to redirect | ❌ | ✅ opt-in --tls-intercept |
The last two rows are the ones an SDK wrapper structurally cannot reach. Capture happens below the agent — at the process and socket boundary — so it does not matter whether the agent is yours, whether you can edit it, or whether it even holds an API key: a Codex CLI signed in with a ChatGPT subscription talks to its own backend over TLS, with a credential that only that backend accepts, so it cannot be pointed elsewhere and stay the same session — and orca can still record it. See when the harness will not be redirected.
How it works
Model APIs are stateless, so on every turn an agent resends the entire conversation — including the previous turn's tool results. A proxy in front of the model therefore sees the whole loop: each request, each streamed response, every tool call the model emitted, and every tool result the harness produced. That one property is what the tool is built on, and it is why OrcaReplay does not patch your agent — it stands up a local proxy, sets two environment variables, and gets out of the way.
What "egress blocked" means, exactly. On replay the proxy refuses to forward anything it cannot serve from the trace, so no model is called and no tokens are spent — that run prints egress=blocked. --loose lifts it deliberately: an unmatched request is then answered by the provider and recorded as a major divergence, and the same line reads egress=live-on-unmatched. A replay still executes the recorded tool calls for real, and a tool that opens its own socket — a shell command running curl, an MCP server fetching something — is outside the guarantee either way. By default it never reaches the proxy and goes to the network as usual. Under --tls-intercept it does reach the proxy, because that sets HTTPS_PROXY for the whole child: a host off the intercept list is tunnelled through untouched, though its hostname, port and byte counts still land in the trace, and a host on the list is refused there like any other unmatched call. Replay is not a sandbox; if you need one, run it inside one.
Three more layers catch what the protocol cannot see: an exit code, a real duration, which stream a byte came out of, a file written without telling anyone. A fifth exists for the agents that read no base-URL variable at all — see which agents. A sixth reads the agent's own account of its structure, for a harness that has one: which sub-agent ran, which handed off to which, whether a guardrail tripped, which graph node produced what and which of them called no model at all — none of which reaches the wire.
They all land in the same timeline, ordered by when they actually happened rather than when orca got around to reading them.
Exact, fork and compare are one thing
They are not three subsystems. They are the same proxy with a cursor — the position in the recorded stream where it stops answering from disk and starts answering from the network.
| command | where the cursor sits | what you get |
|---|---|---|
orca replay last | at the end | the whole run again, network blocked — no tokens, no charge, no variance |
orca replay last --from 4 --model X | at checkpoint 4 | turns up to 4 identical, then a different model takes over |
orca compare last --from 4 --models a,b | at checkpoint 4, several times | one table, one variable — the model |
A checkpoint is not recorded; it is derived — any point where the conversation prefix is complete and the workspace was snapshotted. Every fork therefore starts from a state that provably existed.
What a bug hunt actually looks like
Your agent was supposed to fix a failing auth test. It exited 0 and the test still fails. Start with what it actually did:
Related MCP Servers
Reviews
No reviews yet — be the first to share how this listing worked for you.
Frequently Asked Questions about Orcareplay
AllMCPs Directory Badge
Showcase your server listing on GitHub or your project documentation. Embed this dynamic SVG badge to highlight official listing status and live engagement.
Badge Style:
Live Dynamic SVG Preview
Markdown (GitHub README)
[](https://allmcps.com/mcp/orcareplay)HTML Embed
<a href="https://allmcps.com/mcp/orcareplay"><img src="https://allmcps.com/api/badge/orcareplay?style=directory" alt="Orcareplay on AllMCPs" /></a>