Nanomem README
The full upstream README, mirrored here for reference. Install config, tool schemas, adoption signals, and an original overview live on the Nanomem listing page.
nanomem



An embedded store for facts that change.
A fact your application remembers is not a document. It gets corrected — people move, change jobs, switch phone numbers. A vector store keeps both statements and returns whichever one is worded closer to the question, which is how an assistant ends up confidently repeating an address you left two years ago. nanomem keeps the chain and knows which end of it is current.
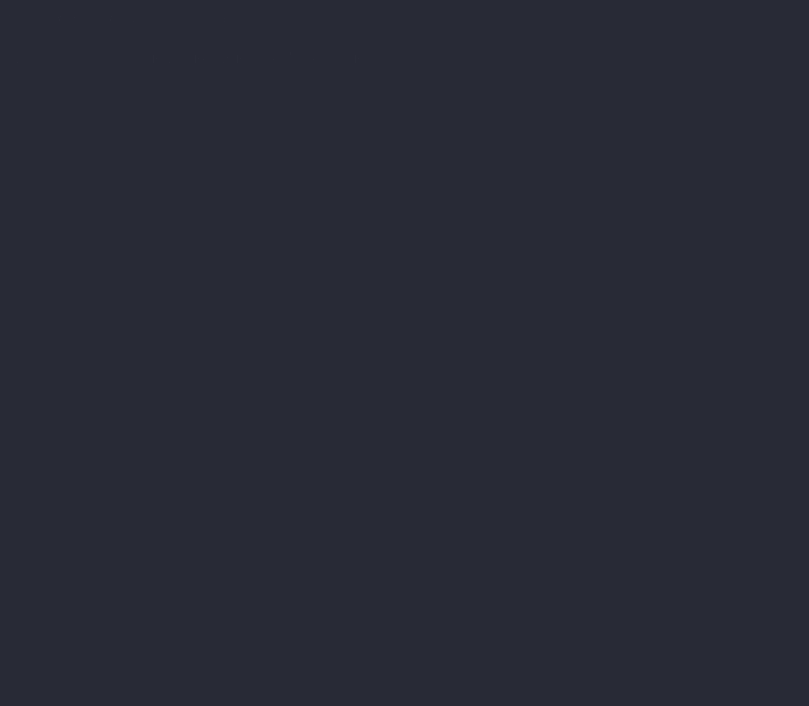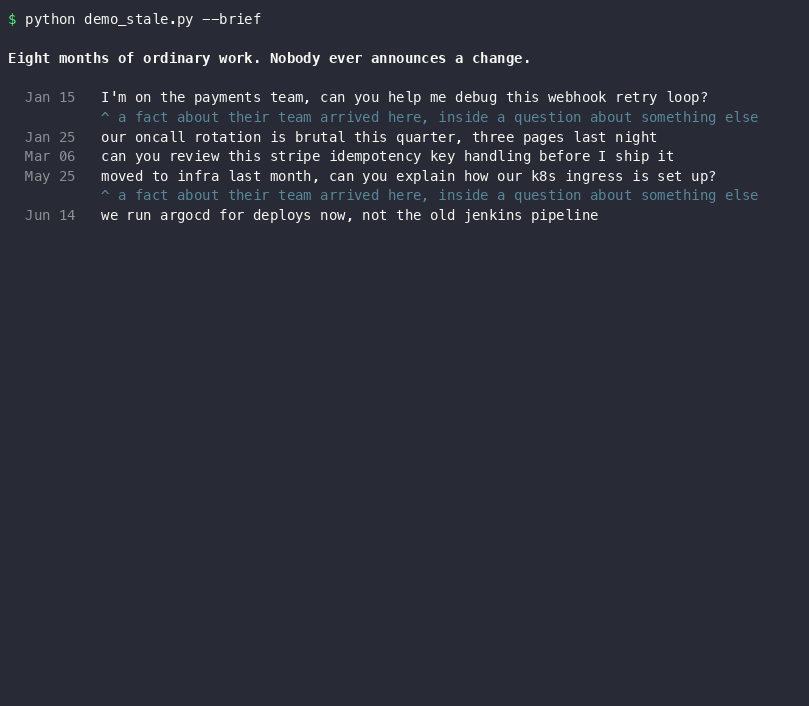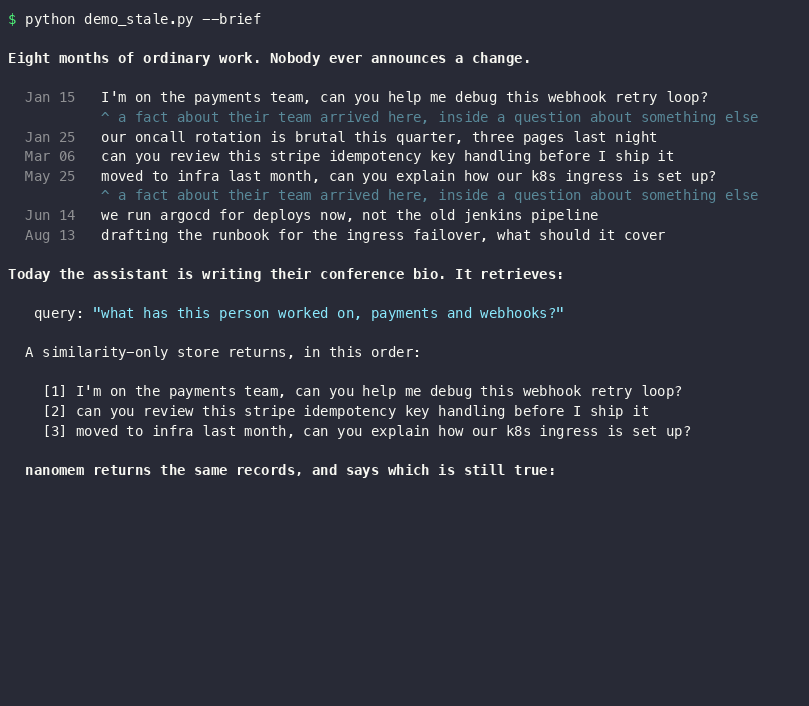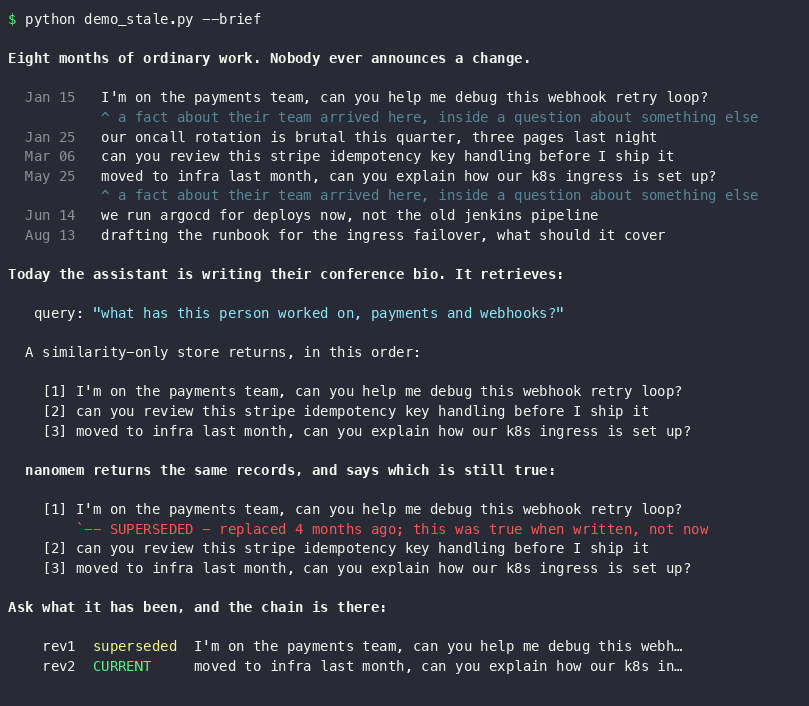
Eight months of ordinary chat; the team fact changed once, in passing.
Similarity still ranks the old one first, because the question is worded
like the old job — so nanomem hands it over labelled rather than pretending
otherwise. A real run of demo_stale.py against a local Ollama
(nomic-embed-text); regenerate it with python3 assets/record_demo.py. The
label does not come from the model: run the same demo with no embedding
endpoint reachable at all and the SUPERSEDED line is still there, because it
is computed from revision order rather than similarity.
Evidence — how it compares to FAISS, sqlite-vec and Chroma (including where it loses), what happens when the process is killed mid-write, and the pytest command that re-runs most of those claims on the copy you just installed.
Quickstart — give your assistant a memory that knows what changed
Add this to your MCP client's config. On macOS claude_desktop_config.json
lives in ~/Library/Application Support/Claude/:
That is the whole configuration. The vault defaults to ~/.nanomem/memory.dat;
set NANOMEM_VAULT, or pass --vault /some/path.dat, to put it elsewhere.
Restart the client and tell it something that will change later:
"Remember that I work at Acme Corp." (a week later) "Actually I moved — I'm at Globex now." "Where do I work? And where did I work before?"
It answers Globex, and can tell you it used to be Acme — not because the second sentence was worded closer to the question, but because nanomem kept the chain and knows which end of it is current. Ask it "what did I believe about this in March?" and it can answer that too.
Seven tools: nanomem_add, nanomem_search, nanomem_history,
nanomem_as_of, nanomem_changes, nanomem_volatility, nanomem_stats — so
the assistant can ask what a fact USED to be, what the memory believed at a past
moment, what changed last week, and which of its own beliefs have gone stale.
The vault is an ordinary file. Point the CLI or a Python script at the same path to read what the assistant wrote — a write is on disk before its reply is sent, so another process sees it immediately and stopping the server cannot lose it.
Through 0.7.17 that was not true: the server flushed only on a clean exit, and an
MCP client stops its servers with SIGTERM. Twenty nanomem_add calls, each
answered "Stored …", then SIGTERM, left zero rows in the vault. If you ran
an earlier version, anything the assistant "remembered" in a session that was not
closed cleanly was never written.
Or use it from Python
One file on disk. One runtime dependency (numpy). No server, no daemon, no
index to rebuild. Search is exact — a full cosine scan, not an approximate
index — so recall is 100% by construction and every interesting question is
about time rather than ranking.
It tells you when the answer is cut short
search returns at most top_k records. It now also tells you what it left
behind, which matters most when the caller is a model that cannot look:
For a multi-part question, the useful number is which parts got nothing at all:
explain() returns "" when nothing informative was cut, so it is safe to
append unconditionally — and the MCP nanomem_search tool does exactly that.
It only speaks when there is a min_score. With the default 0.0 every
record clears the floor, so "showing 3 of 101" would be true of every query ever
asked, including one whose answer really is a single record. A signal that fires
every time carries nothing. The count is still on r.n_above_floor either way.
The counts are free: the scan is exhaustive, so both numbers already existed on
the line that applies top_k and were being discarded.
It marks answers that are no longer true
A timestamp says when a record was written. It cannot say whether it is still true — a fact written ten years ago can be current, and one written last week can already be dead. The difference is whether a later record replaced it, which is what the revision chain knows.
Search for a fact that has changed and you get several of its values, because that is what a chain is. Each one now says where it stands:
ask() puts that in the prompt, so the model is told which facts are dead
before it writes; the MCP tool marks them in the text an assistant reads:
A ten-year-old fact that never changed is marked with nothing. superseded is
None — not False — for a record in no chain, because there "nothing replaced
it" is unknown rather than true.
Tell it what an attribute is
metadata={"entity": "employer"} is doing real work above, and it is worth a
paragraph because little else here matters as much.
Name the attribute and nanomem knows those three statements are one fact, so it
keeps them as a chain. Leave it out and a lexical tagger guesses from the text —
measured, on 100 chains per arm, every member of a chain got the same correct tag in
70 of 100 plainly-worded chains and 0 of 100 on narrative
phrasing. In the example above it tags "I moved jobs, I now work at Initech."
as location rather than career, because "moved" outweighs "work at", and the
chain silently splits in two.
So if your application has attributes of its own, declare them. Everything nanomem does that a vector store does not rests on knowing which statements are about the same thing — and you know that, while the tagger is guessing.
Package 0.8.3 · engine 3.4.6 · container format 3 · arena cache format 4.
Licence: Apache-2.0. Use it commercially, modify it, ship it inside a
closed-source product — keep the LICENSE and NOTICE files with any
redistribution, say what you changed, and do not use the project's or the
author's name to endorse yours. That is the whole obligation.
nanomem was AGPL-3.0-or-later from 0.6.0 through 0.7.22, with a commercial licence alongside it. That combination protected something worth less than the users it was turning away: most companies ban AGPL by policy and many developers skip it without reading it. Copies distributed under the old terms keep them, and both superseded texts still ship — LICENSE.agpl-3.0-or-later.md and LICENSE.preview-v1.0.md. Up to 0.6.0 the wheel metadata said Apache-2.0 while the LICENSE file said All Rights Reserved; that contradiction was resolved in 0.6.0 and has stayed resolved.
Run the demo
Add --brief to either one to drop the explanatory prose and keep only the
computed lines; that is what the recording at the top of this file shows.
demo_stale.py is eight months of ordinary work sessions where nobody ever
announces a change — the team fact arrives twice, both times inside a question
about something else. Then the assistant writes a bio, similarity puts the
old team first because the question is worded like the old job, and nanomem
hands it over marked SUPERSEDED - replaced 4 months ago. Every line it prints
is computed; edit the sessions at the top and re-run it.
It stores a few facts, updates one of them to show revision handling, searches
with citations, and prints the vault's real stats() — document count, file
size, the measured active_heap_ram_kb, and whether the file is encrypted (by
default it is not).
Run the tests
845 tests, no network needed.
There is no test_security.py. Earlier versions of this README told you to run
one to "prove that zero plaintext exists on disk"; that file never existed, and
the claim was wrong anyway — a vault is a plaintext file unless you give it a
passphrase. To check for yourself:
Use it from your own script
add() returns the document id, so you can get, update or delete by it
later. For an encrypted vault, pass password="…" (or set NANOMEM_PASSWORD).
Embeddings are yours to choose. The default is nomic-embed-text on a
local Ollama-compatible daemon, but any model of any width works — the width is
probed from the model itself, and the vault is sized from what it returns:
Point it anywhere with base_url= or NANOMEM_EMBED_URL. Pass dim= to
EmbeddingProvider to skip the probe entirely (air-gapped installs). An
existing vault's width always wins over the one you request, so you cannot
silently corrupt a vault by naming a different model later — you get a warning
and the file keeps its own width. That handle is then only partly usable: your
encoder is still the model you named, so every call that needs a NEW vector --
add, update(text=), search, history -- raises until you reopen with one of
the file's width. Reads still work, and delete, prune, compact and
forget_superseded still run and still rewrite the file, behaving exactly as they
do through a matched handle (measured across 8 operations: 0 differed). This said
"every call raises" through 0.7.20, which is what led a reviewer to read a normal
prune as silent destruction. Nothing is lost, but it does not quietly carry on.
Without a daemon there is a fallback, and it is worth knowing what it is:
a deterministic lexical encoder at 768-d — words and character trigrams
hashed, no semantics. It scores "the server is up" against "the server is down" at 0.783, and "I drive a car" against "I own an automobile" at
0.286. Opposites look identical, synonyms look unrelated. It keeps the
pipeline running offline and is fine for a smoke test; it is not a substitute
for an embedding model, and there are no bundled neural weights.
What makes it different from a vector store
nanomem is an append-only log, so it keeps every value a fact has ever had, not just the current one. That makes four questions answerable that a vector index cannot represent, because none of them keeps the history to answer from.
as_of and since are unix timestamps in Python; the CLI below takes
YYYY-MM-DD as well. history() returns each value with its timestamp and a superseded flag; the
last entry is the current one. A fact that never changed returns one entry,
which is an answer, not an empty result.
volatility() is the one to look at. It reads the revision log and reports, per
fact, how many times it has been restated, the typical interval between changes,
and how long the current value has stood unconfirmed — so an agent can work out
which of its own beliefs have gone stale and ask again:
No model and no query: differenced timestamps off two resident columns, off the
search path. staleness() will turn that into a probability, but it returns
None unless you pass assume_memoryless=True — the per-fact rate only beat a
single corpus-wide rate on data generated to match its own assumption, so it is
not on by default (evidence/staleness_calibration.json).
What bounds this. Two records are only treated as one fact when nanomem can
tell they are the same attribute, and that needs either a vocabulary or the
query — five vocabulary-free signals were measured and all are at chance against
sibling attributes like home-vs-office address
(evidence/grouping_signal_results.json). With canonical phrasing every member
of a chain gets the same correct tag in 70 of 100 chains; with narrative phrasing
("ported the line over the weekend, reach me on …") in 0 of 100
(evidence/temporal_drift_results.json). If your application knows its
own attributes, declare them — pass metadata={"entity": "employer"} on write
— and set group_floor_sim=0.45, worth +19.0 points of top-1 on exactly the
phrasing the tagger struggles with (floor_retune_results.json). Leave both
alone if you are relying on the tagger; the same setting costs 13.9 points there.
Declare it wherever you write from. metadata={"entity": ...} in Python,
entity on the MCP nanomem_add tool, --entity on nanomem add. Until
0.7.12 the last two did not exist, so the two surfaces most callers integrate
through were locked onto the tagger with nothing saying so.
What it costs when you cannot declare one. On a group the tagger inferred,
search and history can disagree about which value is current: history
resolves the tagged chain and reads the revision counter, while search also
applies a relevance floor that can drop the newest value when it is phrased
further from the question than an older one. Exempting the newest member of an
inferred group was measured and rejected — it costs -19.4 points on the
3-persona chat set, and a sweep from 0.40 to 0.80 found no threshold that bought
the one without paying the other
(evidence/floor_current_value_results.json). So this is a deliberate
trade, not an oversight.
0.7.12 said here that history is authoritative and should be believed over
search. That was wrong and the claim was withdrawn: history could itself
return a shorter chain than existed, in the worst case one entry flagged
superseded=False, which this library defines as "this fact never changed".
That truncation is fixed in 0.7.14 and 0.7.15 — a declared chain now returns
every revision it holds, and changes() agrees with it.
What remains is the disagreement itself. Until 0.7.16 this section said
"declare the entity and the disagreement goes away", on the strength of
three chains scoring 3/3 (evidence/entity_declaration_results.json). A third
independent black-box review found a declared chain where it does not, and the
claim was wrong in a way the measurement could not see: in all three of those
chains every revision RESTATES the attribute ("I now work at Initech"), which
keeps the chain's members close together. When revision 1 names the attribute
and later revisions refer to it implicitly -- "My desk is on the third floor of
Kestrel House" then "Now parked in the Maple Wharf building" -- the members
spread apart, and the lift that promotes the current value was capped below what
that spread needs. search[0] returned a desk location two moves old while
history() returned the right one, with the entity declared.
0.7.16 raises that cap on a sweep over eight arms and two embedders
(evidence/revision_lead_cap_results.json). Measured over twelve chains of the
phrasing that broke it, each alone in its vault, in two timestamp regimes:
declared chains, search top-1 == history's current value | 0.7.15 | 0.7.16 |
|---|---|---|
| later revisions refer implicitly, real model (24 cases) | 41.7% | 100.0% |
| the same chains on the offline fallback encoder (12) | 25.0% | 75.0% |
| drifting phrasing, generated set (100) | 71.0% | 100.0% |
and left to the tagger stays 2/3, unchanged and still measured on three chains
only (evidence/entity_declaration_results.json).
Declaring the entity is what makes the chain resolvable, and on a real
embedding model it is what makes search and history agree on these sets.
It is not a guarantee. On the twelve offline-encoder chains measured here, every
remaining failure has the same cause: that encoder is lexical, the newest revision
lands so far from the question that the relevance screen drops it from the result
entirely, and no ranking boost can promote a record that was never returned
(6 of 6 failures, revision_lead_cap_results.json arm H).
That is the cause on THIS corpus, not the only one there is. An independent
reviewer, building chains of the same described shape, measured failures of a
second kind: the newest revision IS returned, the boost is applied and saturates
at max_boost, and the lift needed to lead the chain (~0.68) still exceeds the
0.60 cap. Those would be fixed by a larger cap; the ones measured here would not,
which is why the published sweep shows this arm flat from 0.60 through 1.50. Two
corpora of the same shape can differ this much on a lexical encoder, so treat the
75.0% as what it is — a measurement of twelve chains, not a property of the
fallback. tests/test_revision_lead_cap.py fails if the cap is ever reached on
the sets it checks. changes() is the unfiltered view to cross-check against.
Building RAG on it
Retrieval is the core; generation is optional and uses no extra dependency
(stdlib urllib to whatever endpoint you point it at).
nanomem proxy additionally serves an OpenAI-compatible /v1/chat/completions
that injects memory, so an existing app can point at nanomem instead of its
provider and gain memory without code changes.
Providers. Pass base_url= and api_key= to ask()/chat(), or set them
on the Vault. The base URL decides the request shape:
| Ollama (default) | http://localhost:11434 → native /api/generate |
| OpenAI, Groq, Together, Mistral, DeepSeek, OpenRouter, Fireworks | any base ending /v1 |
| LM Studio, vLLM, llama.cpp | :1234, :8000, :8080 |
| Anthropic | https://api.anthropic.com/v1 → /v1/messages, x-api-key |
| Azure OpenAI | pass the full deployment URL ending /chat/completions |
Embeddings come from NANOMEM_EMBED_URL (default nomic-embed-text on
Ollama). Routing is decided by the PARSED PORT, not by a substring of the URL —
before 0.6.1 a host named web8000.internal was misrouted and Anthropic was
POSTed to /v1/chat/completions, which 404s.
CLI
add prints the document id and its own elapsed time.
What it does, measured
Search is an exact linear scan. For the text it scans, it returns what an
exhaustive fp32 cosine scan returns — 0 of 120 top-4 order differences on a
1,190-document corpus (evidence/exactness_v3r2.json) — and its latency
therefore grows with the corpus.
Which text it scans depends on decompose, which defaults to True. A
multi-clause question is split and each sub-query is scanned exhaustively, then
the best hits are interleaved — so the result is the exhaustive answer to each
clause, not the exhaustive top-k of the whole sentence, and for a multi-clause
question the two differ. That is the point of decomposition: a two-part question
gets both parts answered. Pass decompose=False when you want the whole string
treated as one query and the exactness claim above to apply end to end.
| Corpus | p50 | recall@4 | same as exhaustive numpy? | same as FAISS flat? | index | RSS per doc |
|---|---|---|---|---|---|---|
| 1,190 | 0.052 ms | 68.3 % | yes | yes | 2.5 MB | — |
| 10,000 | 0.345 ms | 70.4 % | yes | yes | 22.0 MB | 8.4 KB |
| 71,433 | 1.762 ms | 60.6 % | yes | yes | 155.9 MB | 8.8 KB |
evidence/scale_results_v3r4.json, headtohead_v3.json,
rss_v3r4.json. Measured on Apple M4 Pro / Python 3.12, nomic-embed-text
768-d, random insertion order, 500 held-out questions, ingest → close → re-open
→ search. (Every evidence/… path in these documents is relative to the
repository root, not to this folder; the JSONs and the scripts that wrote them
live there.)
The "same as exhaustive" columns are recall. Ordering is identical too at 1,190
documents (0 of 120 top-4 order differences); at 10,000 and 71,433 a few
tie-breaks differ — 2 of 500 and 5 of 500 questions, largest cosine gap 2.2e-05 —
because the on-disk vectors are fp16 (evidence/verify_round3_v3r3.json).
The scores are exact in the same sense and not a bit further: two float32
matmuls of different shapes reduce in different orders, so the score attached to
a hit can differ in its last bit or two between one BLAS and another — measured
2.98e-08, two ulps, between Apple Accelerate and OpenBLAS on the same query. The
answer does not move with it. Over 4,000 documents at 128 and 768 dimensions the
worst |fp32 − fp64| error is 2.01e-07 while the smallest gap between rank 4 and
rank 5 is 4.46e-06 — twenty times larger — and 0 of 150 queries were undecided
at k = 1, 4 or 10 (evidence/screen_exactness_results.json). So "returns
what an exhaustive scan returns" is a claim about which documents come back and
in what order — except among documents the ranking genuinely cannot separate,
where the corpus contains no tie-break to be faithful to. It is not a claim
about the bit pattern of the float beside them, and it never could have been.
Resident memory is roughly 8–9 KB per document. Earlier documentation claimed
a "< 500 KB RAM" or "160 KB active heap" footprint; those were constants printed
by stats(), not measurements, and they are gone.
Writes are flat as the vault grows: 19.81 µs mean over the first 500 of 4,000
adds, 19.32 µs over the last 500, excluding embedding
(evidence/headtohead_v3.json).
Deleting one record is a full atomic rewrite — 7.5 ms at 1,000 records, 70.5
ms at 10,000 (evidence/rewrite_cost_v3r4.json). There are no tombstones
in 3.0.
Documentation
- USER_MANUAL.md — hub, and the full measured-performance tables
- USER_MANUAL_PERSONAL.md — chat, profiles, privacy
- USER_MANUAL_DEVELOPER.md — SDK, CLI, concurrency, migration
- SERVICES_AND_API_SPECIFICATION.md — REST endpoints and limits
- MULTIHOP_REASONING_AND_TOPOLOGY_GUIDE.md — the bridge, and what did not work
- CHANGELOG.md — breaking changes from 0.1.x
Read nanomem.THREAT_MODEL before relying on the optional password mode. It is
scrypt + a SHAKE256 keystream + an HMAC-SHA256 tag, built from the Python
standard library. It is not AES, not "256-bit encryption", and it has not been
audited.