Mirofy README
The full upstream README, mirrored here for reference. Install config, tool schemas, adoption signals, and an original overview live on the Mirofy listing page.

Diagrams of your system that cite their sources — and say what they could not see.



This is the whole product: one HTML file, open in a browser. Every colour
in it is the system’s own vocabulary — backend, database, cloud,
security, message bus, external — and nothing else. Colour never marks
where an arrow goes, only what a thing is.
Open this exact file ↗ —
click any node for its evidence, trace what reaches it, search it, present it.
What it is
Point Mirofy at a repository. It reads the code into an evidence graph, builds a model from that graph, and compiles the model into one HTML file you can open, search, share and check.
Every relationship it draws can answer one question: what is the evidence for this? Each carries the file, the line range and the commit it came from. Where nothing is known, the diagram says so instead of filling the gap.
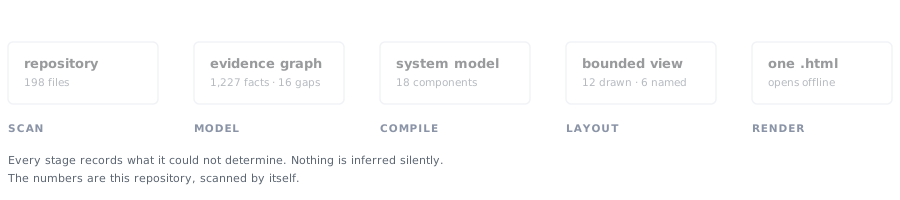
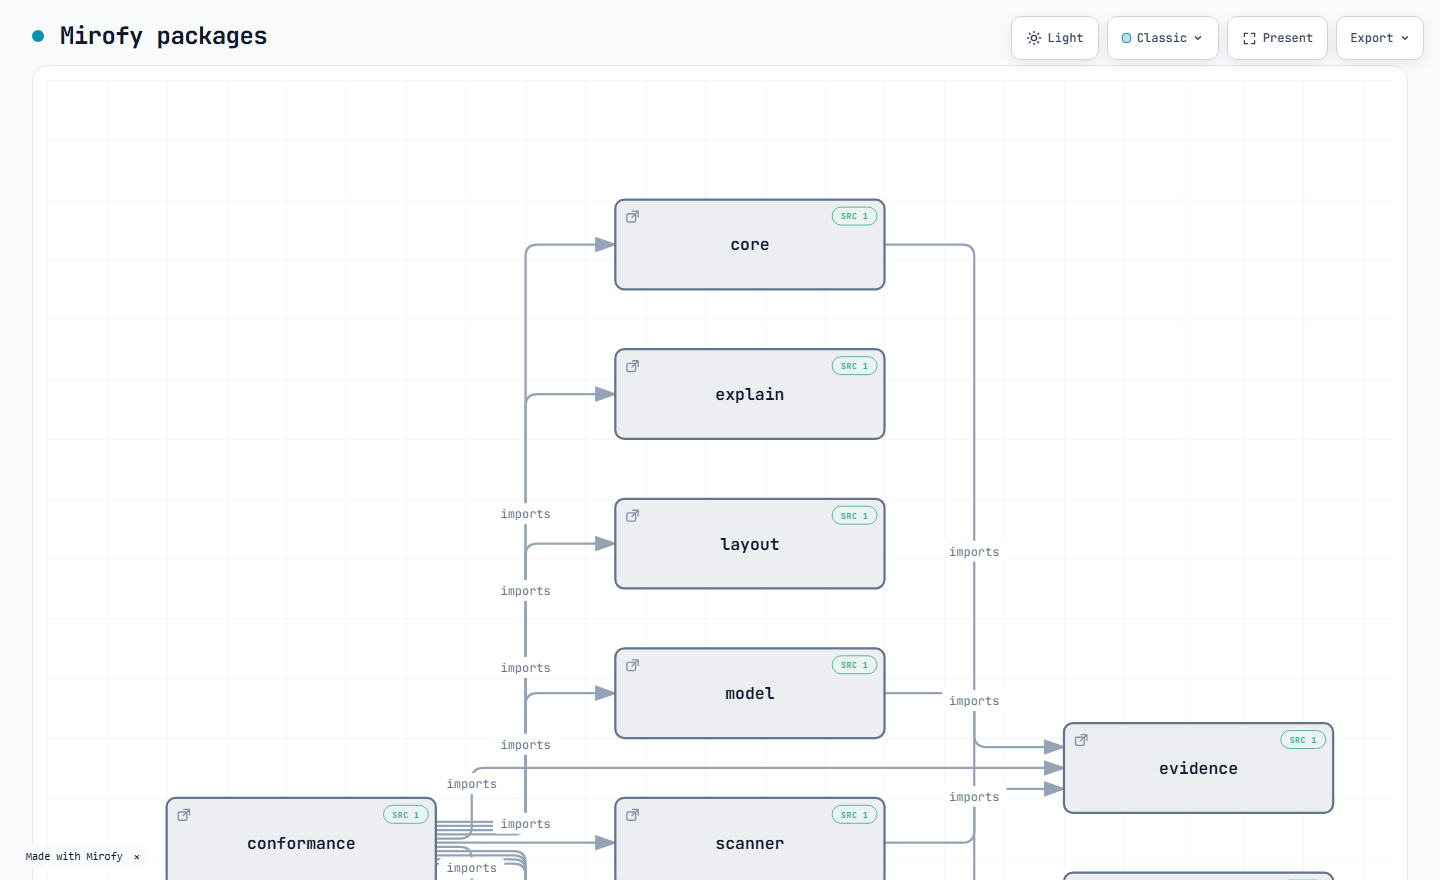
Run it against this repository and you get this — not a mock-up, and not drawn by hand:
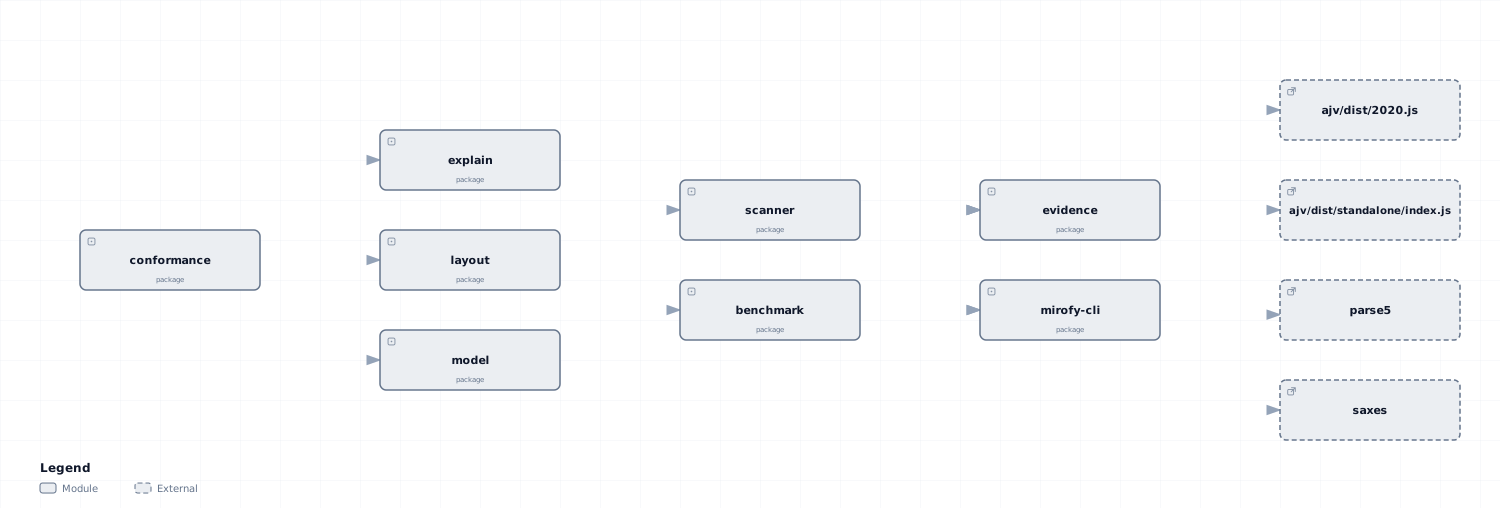
Every box is the same colour here, and that is the point. All twelve of
these are the same thing — a package, derived from a manifest — so there is
nothing for colour to say, and it says nothing. The picture at the top is
colourful because that system genuinely has six kinds in it. A tool that
tinted these boxes to look livelier would be inventing a distinction it had
not found.
Open the live one ↗ — click any
node for the file, line range and commit behind it.
Install
Nothing to install — one command, and a diagram opens:
Give it to your agent instead — one line, and the skill installs for Claude Code, Cursor, Gemini CLI, Amp and a dozen others:
Then ask: map this repository's architecture. Your agent reads
SKILL.md and drives the same CLI.
In Claude Code, the plugin carries both the skill and the MCP server:
Every one of these routes is the same package. The agent never draws the diagram — it runs the CLI you would have run, which is why nothing it reports can drift from what the CLI reports.
map runs the whole pipeline in the directory you point it at — scan, model,
compile, layout, render — and writes architecture.html next to your code.
map --out <dir> sends the diagram and the intermediates there instead, so
nothing lands in your repository; without it the intermediates go to
<target>/scan. Naming an output path still wins over both. It works on a repository that declares no
workspaces: where there are no packages to draw, it models the source
directories and the imports between them.
What it reads
JavaScript and TypeScript imports · Python imports · Go imports ·
Java imports · Rust imports · Kotlin imports ·
package.json workspaces · Express and Next routes · docker-compose.
That is the whole list, and the list is the point. Everything else is
reported, not skipped: coverage.md names every file no adapter opened,
grouped by type, and map says so on its way out when the unread files
outnumber the read ones. Point it at a Ruby repository and you get an honest
empty answer naming every unread .rb file — not a confident small one drawn
from the two JavaScript files in an examples/ folder.
Python resolves by file existence, not by convention: relative imports
against the importing file's directory, absolute ones against the repository
root and any directory that actually holds a package. A specifier that matches
two source roots is a gap naming both, because which one wins depends on
sys.path, which is configuration and not in the source.
Go resolves against the module path go.mod declares, and decides the
standard library the way the toolchain does — a first path segment containing a
dot is a domain, and a domain means a module fetched from somewhere. Java
builds its index from the package statements files declare, not from
directory layout: Maven convention puts com.acme.store under
src/main/java/com/acme/store and convention is not always, but the
declaration is what the compiler reads.
Rust peels a use from the right until a real file appears, because
use crate::a::b::C does not say which of a, b or C is the file. It reads the
crate name and the source root from Cargo.toml — including a declared
[lib] path, since src/ is only the default — and knows that Cargo compiles
every direct child of tests, benches and examples as its own crate.
Kotlin reads its type index from the declarations themselves — class, interface,
object, typealias and fun interface among them — rather than from file
names, because a Kotlin file need not be named after the type
it holds and may declare several. It shares that index with Java: the two
compile to one namespace and import each other freely, so an index of one
extension reports a real edge to the other as a missing type.
In every one of them, an import that names something inside this repository which is not there is a gap — never a dependency on a published copy of yourself.
npx mirofy-cli guide "show an API request with a cache miss" picks the
diagram type for you if you are not sure which one you want.
As a CLI you keep — npm install -g mirofy-cli. The command it installs is
mirofy; the package carries the -cli suffix because npm refused the bare
name as too close to the existing minify.
From source — no install at all, because there is nothing to install:
That works on a bare checkout with no npm install, because every package here
has zero runtime dependencies.
As an agent skill — build the bundle and copy it where your agent looks:
Then ask: Use mirofy to map this repository's runtime architecture.
The bundle is 2.8 MB and named for the skill inside it — copying packages/core
instead installs a skill called core that says in its own frontmatter it is
called mirofy, and drags the test suite along with it. Before writing the
bundle, build:skill copies it somewhere with no repository around it and
renders a diagram: a bundle that only works inside its own checkout is not a
bundle.
Nothing is downloaded at runtime and nothing phones home — there is no update check, because a tool that reaches the network to tell you about itself is a tool that reaches the network.
The pipeline, one step at a time
mirofy map is these five steps in order. If you only want the intermediates,
mirofy map . out.html --out ./scan writes every one of them — the evidence
graph, the model, the view and the positioned document — into that directory.
To run a step on its own, or point one somewhere else, you need a checkout; these are the repository's own npm scripts, not commands the installed package exposes:
Against this repository it records 1,227 facts across 223 files, with 16 gaps it could not read; derives 18 components and 20 relationships — every one citing the file and line it came from — and draws twelve, recording what it left out and why.
Those figures are checked, not remembered — see the numbers on this page below.
Those commands reproduce the diagram at the top of this page. It is checked in
under assets/ as documentation; the interactive artifacts are built, never
stored.
No repository? Author a JSON document, or convert a Mermaid diagram:
What you get
Open any edge and it tells you why it is on the page: the relation, its
provenance class, the file and line it came from, and the commit it was
checked against. Underneath is the half most tools leave out — what the
scanner could not determine, written down instead of guessed.
That record is real, and taken from this repository. So is the gap.
Three claims about the pictures below, each with the thing that keeps it honest.
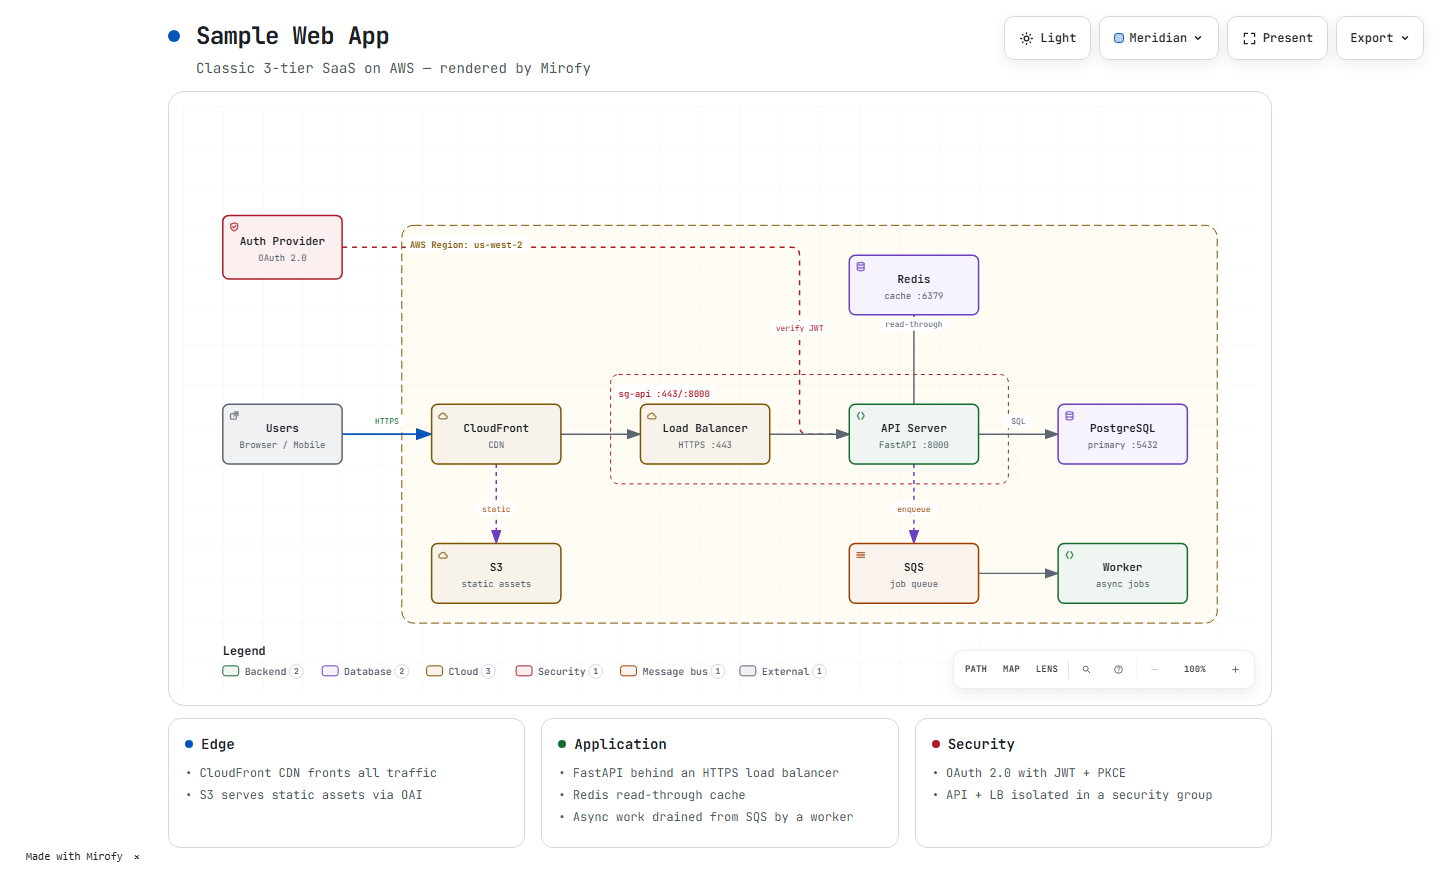
Colour tells you what a node is, never where an arrow goes.
Six presets, light and dark. |
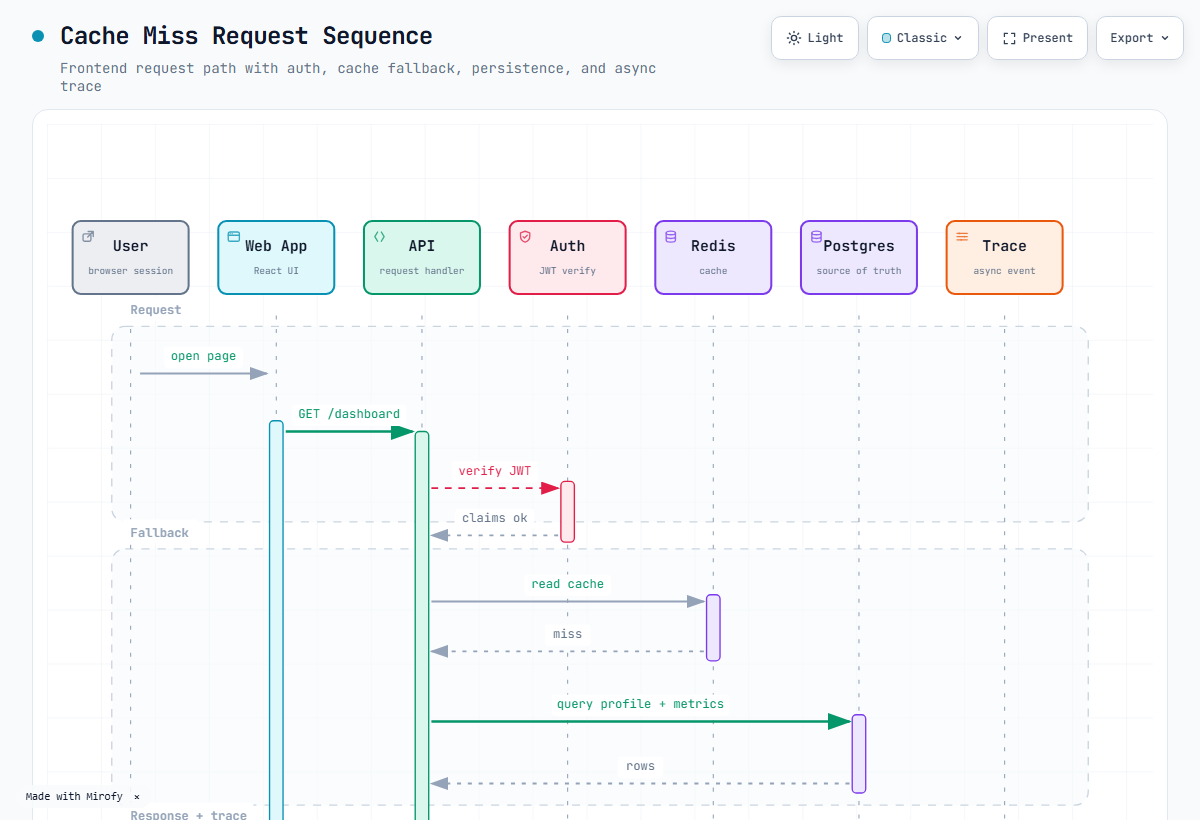
Five diagram types, one schema, one validator.
architecture · workflow · sequence · dataflow · lifecycle — the same typed IR
behind all of them.
|
One file. No server — and nothing it needs from the network.
The diagram, the evidence, the search and every interaction are in the
file. The one thing it ever asks the internet for is a webfont
it does not wait for and does not need, and it falls back to
your system monospace without it.
Checked on every run by scripts/check-readme-claims.mjs,
which fails the build the moment a reference appears that could block first
paint or change what the diagram says — and which fails just as loudly if this
sentence ever overstates what the artifact actually fetches.
All thirty are live ↗ — five types × six presets, rebuilt from every commit.
The viewer, actually being used
Not mock-ups. Every frame below is a capture of the shipped viewer, driven
through real clicks by scripts/build-screenshots.mjs — which fails rather than
reuse an old picture if a control is renamed or a panel stops opening, and
refuses to save a shot of a feature that did nothing.
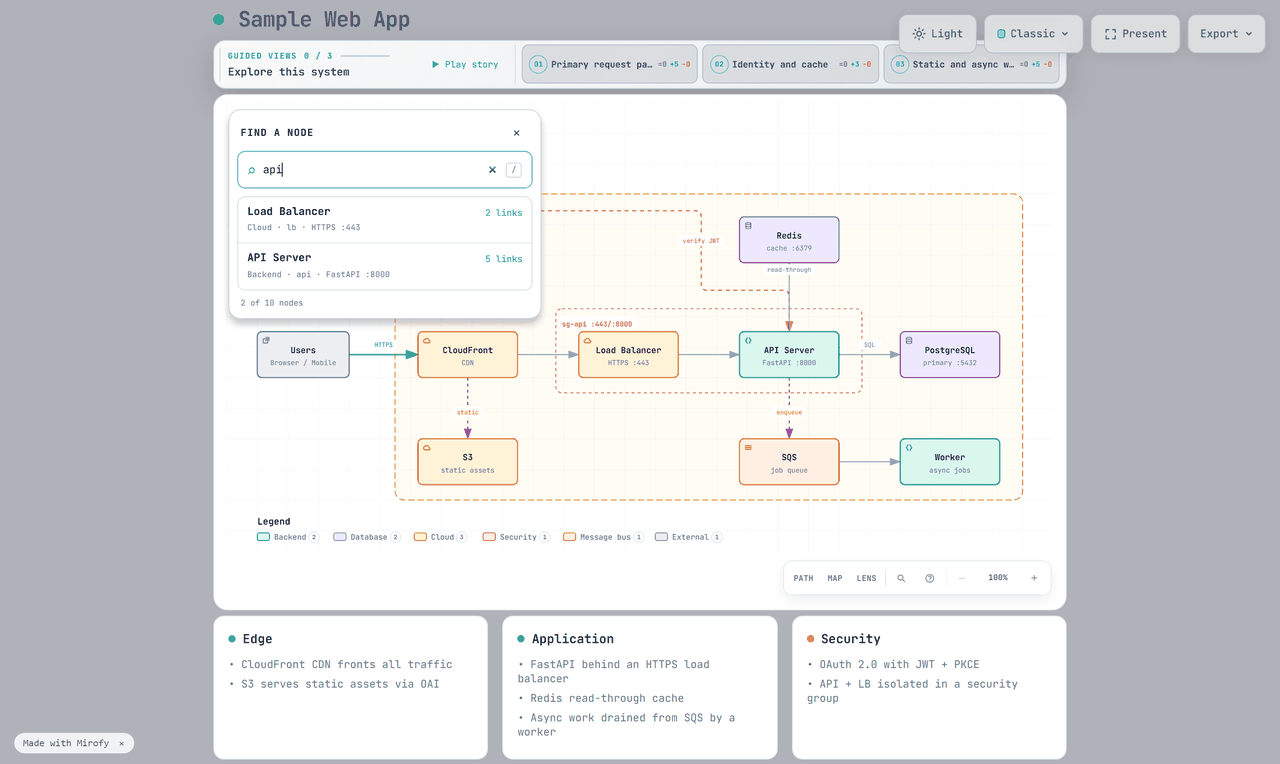
Find anything. Typing |
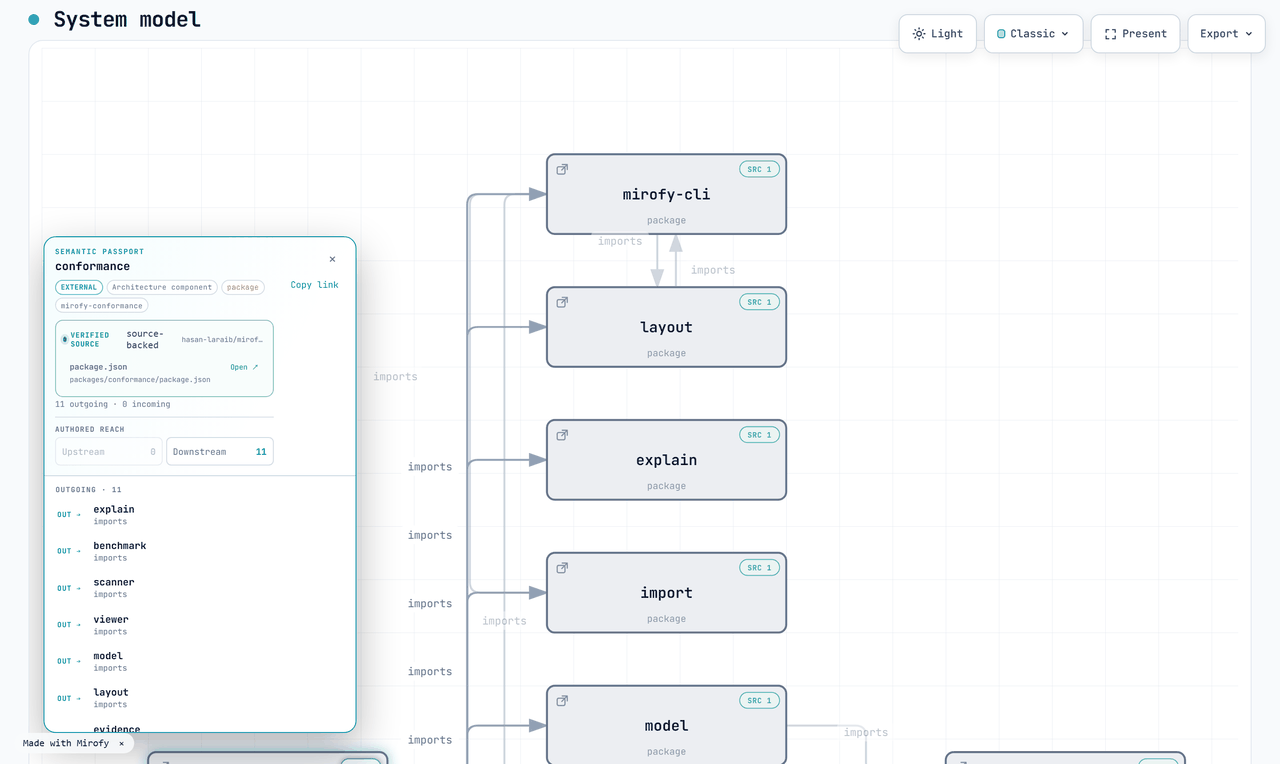
Ask a node where it came from. |
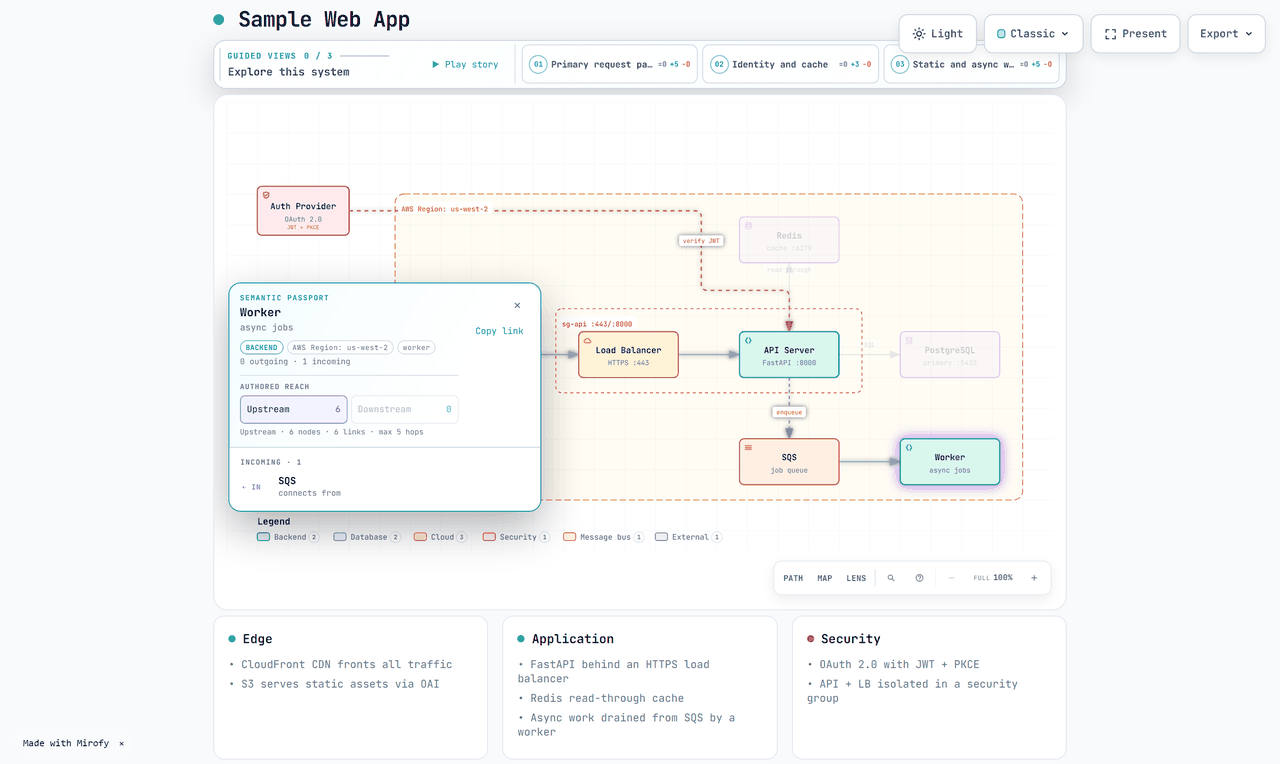
Follow what reaches what. Upstream of |
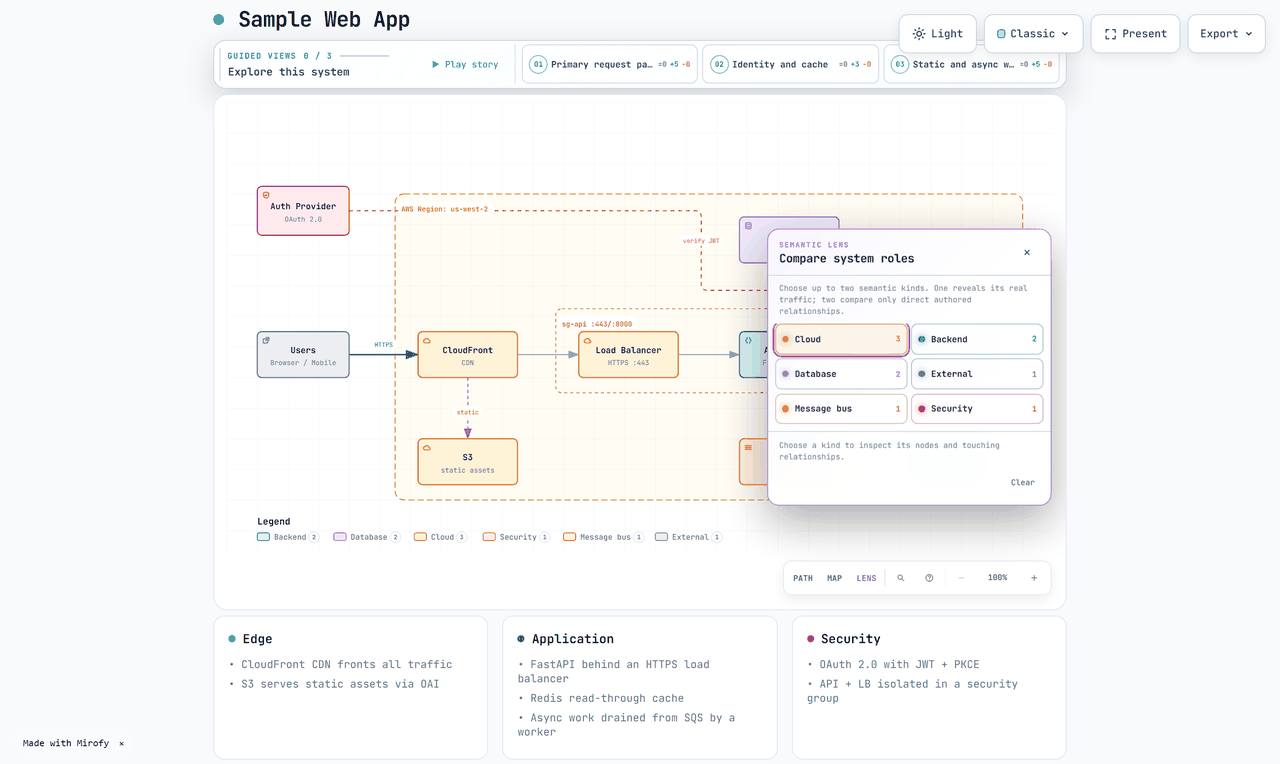
Compare roles across the whole system. The Semantic Lens answers provenance and kind for every node at once, rather than one node at a time. |
What it does that a diagram tool doesn't
It refuses to guess
A file the scanner cannot parse becomes a recorded gap, never a silent
omission. Every fact is labelled with one of six provenance classes, so
source-backed and inferred never look alike.
The same rule holds where a decision has to be made that evidence cannot
settle. A derived component's kind is package — the scanner knows a manifest
exists, not whether something is a "backend". 784 imports of Node builtins are
counted and named, not drawn and not dropped in silence. In Python a computed
importlib.import_module(name) is a gap with its line, and docstrings are
blanked before parsing — a docstring full of example imports would otherwise
become edges the code does not have, cited to prose. A citation with no
pinned commit to verify against is discarded rather than shown, because a
citation nobody can check is worse than none — map reads the commit from
your origin remote, or takes --repo-url and --revision when there is no
remote to read.
A passport lists at most three sources, because forty-three links is not a passport. It says “Showing 3 of 43 cited sources” when it does, so a bound on the drawing is never mistaken for a claim about the evidence.
It answers questions about your system
Every answer names the unread files that could change it. "Nothing calls PaymentService" is useful if the scanner read everything and reckless if six files failed to parse — so an empty result means not found, never does not exist.
impact answers as reachability and refuses to be more. What is connected is
a fact about the graph; whether a change breaks it is a judgement about a
running system, and Mirofy has no evidence for that.
Your agent can ask too
The same queries over MCP — 11 tools, the same engine, not a second
implementation that could disagree with the CLI. assert and timeline are
there too, because "is this change allowed" and "what has been moving here" are
questions an agent asks while editing, and one that has to shell out to ask
them will not ask at all:
Point any MCP client at that. It reads ./scan — whatever map --out ./scan
last wrote — relative to the directory the client starts it in; --model and
--graph override. No clone, and nothing to install first.
The incompleteness warning is in the prose an agent reads, not only the JSON. Most clients feed the text to the model and drop the rest.
It checks architecture rules — with three outcomes, not two
pass, fail, and unproven. A rule that found no violation over a scan
with unread files has not been shown to hold, so it never counts as passing.
Turning a gap into a green check is the one failure this project exists to
avoid.
Some gaps are permanent — a dynamic import whose base path is a variable cannot be resolved without guessing. Those can be acknowledged, one path at a time, quoting the gap's reason and carrying a written argument. An acknowledgement written for a dynamic import stops applying the day that file fails to parse instead. And a rule that passes on the strength of one says so:
It tells you what is moving
Drift reports changed facts and nothing else — no score, no risk label, no merge recommendation. It runs on every pull request and can never fail one.
The number we would rather not publish
A benchmark asks one question: hand a model a written brief, and how often does the diagram it writes come out usable on the first attempt?
Right now, over eight briefs authored by Claude Code: 2 of 8.
That is not a good number and it is the real one. Three things make it worth printing anyway.
Usable means clean, not accepted. A warning is the diagram telling you it needs a second look, which is exactly what a first-pass rate is supposed to exclude. Two more documents in that set validate with zero errors and are still not counted.
It is measured against a saved corpus, not a fresh one. --keep stores what
the model produced; --replay re-runs the tool over those exact documents
without calling the model again. Without that split, every re-run changes both
the documents and the tool, and any movement can be attributed to either — which
is why the rate sat at zero for weeks without anyone being able to say what was
wrong. A replay cannot even claim a different author: the model is read from the
saved manifest, and --model is refused if it disagrees.
It moves for reasons you can name. The last change to the layout engine took the same eight documents from 0 of 8 to 2 of 8, and total composition errors from 121 to 34, because a diagnostic that said "shorten the label or widen size" was asking an author to rename part of their system to fit a box the renderer had picked. The renderer now widens the box.
If you compare this to a number published elsewhere, check what was measured. A rate for an agent that can call a validator and repair its own output, reviewed by a person at the end, is a different measurement from a blind single-shot model — not a worse one, a different one. Ours is the second kind.
Inside the artifact
- Node Finder, Semantic Lens, Semantic Radar — search, filter and overview a diagram too large to read at once
- Route Probe — resolve a directed path and see it traced, hop by hop
- Semantic Passport — click a node for its type, tags and cited evidence, with a Verified Source Beacon on anything backed by a pinned commit
- Your code, drawn apart from everyone else’s — a module you wrote is solid, a third-party package is dashed. Not a colour: the colour-blind-safe preset already spends all seven of its hues on the seven semantic roles, so an eighth would be a distinction only some readers could see
- Guided views, presentation mode, motion governor, and
?embed=1 - Three exports, copied straight to the clipboard:
- Export → Share Card — a 1200×630 PNG in the current theme and preset
- Export → Route Share Card — the exact route a Route Probe resolved
- Export → Reach Share Card — the set a reachability query returned
A card shows what the reader actually did. None of them claim validation, and none are produced from a query that returned nothing.
The second is what CI publishes to hasan-laraib.github.io/Mirofy on every commit. Nothing is committed: the site is built from the code at the commit it describes, so it cannot go on quietly describing an older one.
Taking it elsewhere
The interactive file is ~720 KB and earns it. None of that survives a README, a pull request or a Notion page, though — all of them strip scripts. So:
| where it goes | how |
|---|---|
| README, pull request, Notion, Confluence | svg-static |
| Figma, Canva, Illustrator, Sketch | svg-static — styling is written as attributes, so it arrives with its colours |
| diagrams.net · draw.io VS Code extension | drawio — real shapes and connectors |
| Excalidraw · Obsidian · VS Code | excalidraw — bound arrows, movable boxes |
The SVG carries its styling twice: in a stylesheet and on the elements. In SVG a stylesheet outranks an attribute, so a browser renders from the CSS, and the attributes speak only where the CSS is ignored — which is exactly what Figma, Canva and Illustrator do. Without them the diagram imports shape-correct and colour-dead.
Both editor exports say exactly what they lost, computed from your document rather than recited as a disclaimer. A diagram you can only edit in the tool that made it is a diagram held hostage.
What is proved
The conformance matrix has 105 rows. 85 are proved without a browser;
19 more need headless Chrome (MIROFY_CHROME), bringing the total to 104.
Every row names a test, and the title must match character-for-character — a row whose proof file passes while its own test was renamed counts as unproven, never as passing. One row (6.10, deterministic ZIP packaging) is UNPROVEN and counted as such rather than quietly dropped.
Skipped is not passed. Browser rows never count toward the proved total unless a browser actually ran them.
And the numbers on this page are checked too:
It counts the matrix, reads the tool list the MCP server serves, renders an artifact to measure it, and re-runs the benchmark. This exists because a review found three numbers here wrong at once — none of them dishonest, all of them true when written and left behind by the repository. A page that argues for checking claims has no business making unchecked ones.
Evidence and provenance
Six classes, never blurred:
| class | means |
|---|---|
authored | a human wrote it |
source-backed | read out of a cited file and line range |
statically-derived | computed from code without running it |
config-derived | read from a manifest — configuration, not code |
runtime-observed | seen in a real run |
inferred | a guess, and labelled as one |
Source citations verify against a pinned 40-character commit in a real local checkout before they render. A path that does not exist at that revision is an error, not a broken link.
Several repositories can be declared at once, and a citation names which one it belongs to. Verifying against a repository rather than the right one is how a path from a sibling repo passes as evidence for this one.
Packages
| package | does |
|---|---|
scanner | adapters that read a repository into facts and gaps |
evidence | append-only evidence graph, query, honest coverage |
model | the system model: stable ids, evidence refs, human overrides |
compile | view compiler and the planner seam |
explain | graph queries, architecture rules, drift, timeline |
mcp | the model as agent context |
import | Mermaid into typed documents |
export | draw.io and Excalidraw escape hatches |
layout | constraint layout: intent to coordinates (dev-time) |
core | renderers, schemas, validators, CLI |
viewer | the interactive viewer, built into one template |
benchmark | first-pass usable rate, over a saved corpus |
conformance | the matrix, and the tests every row names |
Zero runtime dependencies in every package. The artifact ships nothing but itself.
packages/core/assets/template.html is generated from packages/viewer/.
Never edit it directly — edit the source and run npm run build:template.
npm run check:template rebuilds from source and fails if the committed file
has drifted.
Attribution
Every artifact says what made it. The viewer footer is dismissible — the diagram is yours, and a banner you cannot close is an imposition on someone else's document. Share Cards carry a permanent one, because a card travels without its context and lands where nothing says where it came from.
It names the tool and claims nothing about the diagram, and carries no URL: a link baked into every shared artifact outlives the address it points at.
MIT. packages/core/LICENSE retains, verbatim, the required third-party
copyright notice for the imported rendering core; the root LICENSE covers this
project's own work.