MCP server for MDMA — exposes spec, prompts, docs, and package metadata to AI assistants.
Quick Install
Automated & IDE SetupCopy the AI prompt to install this server into Claude Code, Cursor, or another agent — or use 1-click editor setup below.
Not yet automatically verified
We haven't yet run this listing's install command through our automated sandbox check. This isn't a red flag — we're steadily working through the catalog.
Manual Client & Custom JSON ConfigExpand JSON ▾
Client Config & Setup
Choose your client or environment
Target File:
💡 Paste the JSON block into your client's configuration file under mcpServers, then restart the application.
Capabilities & Tool Schemas (8)
Inspect callable tools, capabilities, and parameters exposed to AI agents by Mdma.
get-specReturns the full MDMA specification: component types, JSON schemas, binding syntax, and authoring rules
get-promptReturns a named prompt (`mdma-author`, `mdma-reviewer`, or `mdma-fixer`). For `mdma-author`, accepts an optional `variantId` (e.g. `google/gemini-2.5-pro`) to return the model-optimised variant
list-prompt-variantsReturns all available `MDMA_AUTHOR` prompt variants (id, label, description) — use the id with `get-prompt` to fetch the model-optimised prompt
build-system-promptGenerates a custom MDMA prompt from structured input (domain, components, fields, steps, business rules)
validate-promptValidates a custom prompt against MDMA conventions — returns warnings, suggestions, and constraint reference
list-packagesReturns all MDMA packages with purpose, install command, and usage example
Documentation Overview

MDMA
Markdown Document with Mounted Applications
Interactive documents from Markdown. Built for next gen-apps
🌐 Website · 🚀 Live Demo · 📖 Docs · 💬 Discord · 🤗 Model
Why MDMA?
AI conversations today are plain text — the user reads a response and manually acts on it. MDMA changes that. When an LLM knows the MDMA spec, it can respond with interactive components (forms, tables, approval gates) instead of just text. The conversation becomes actionable: the user fills out a form, approves a step, or reviews structured data — all inline, with a predictable schema that your app already knows how to render and process.
No custom UI per use case. No parsing free-form text. The AI generates structured, validated components and your frontend renders them instantly.
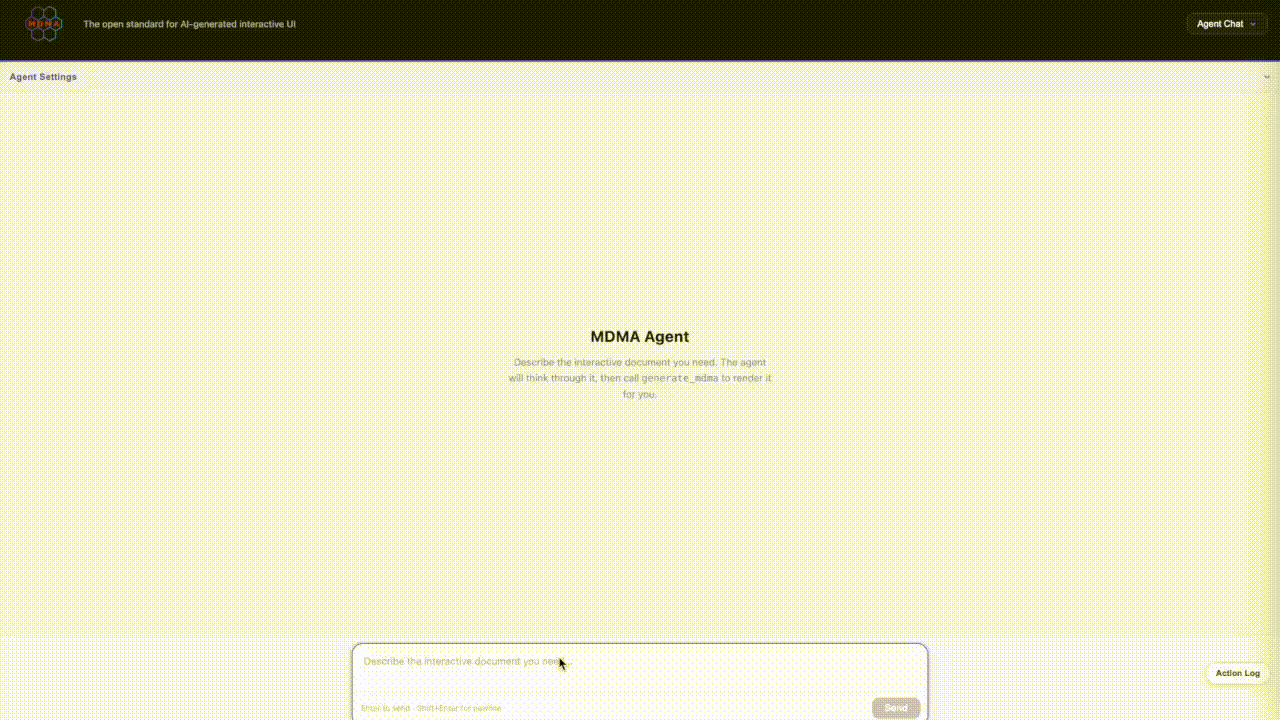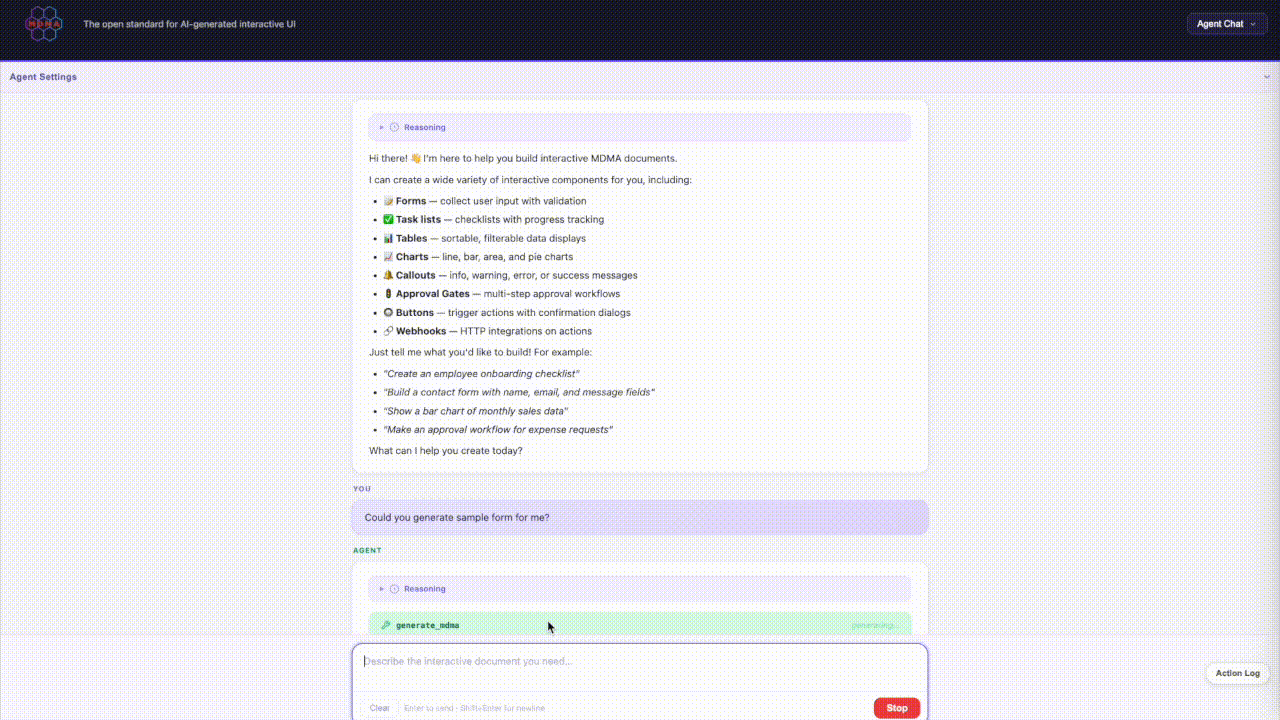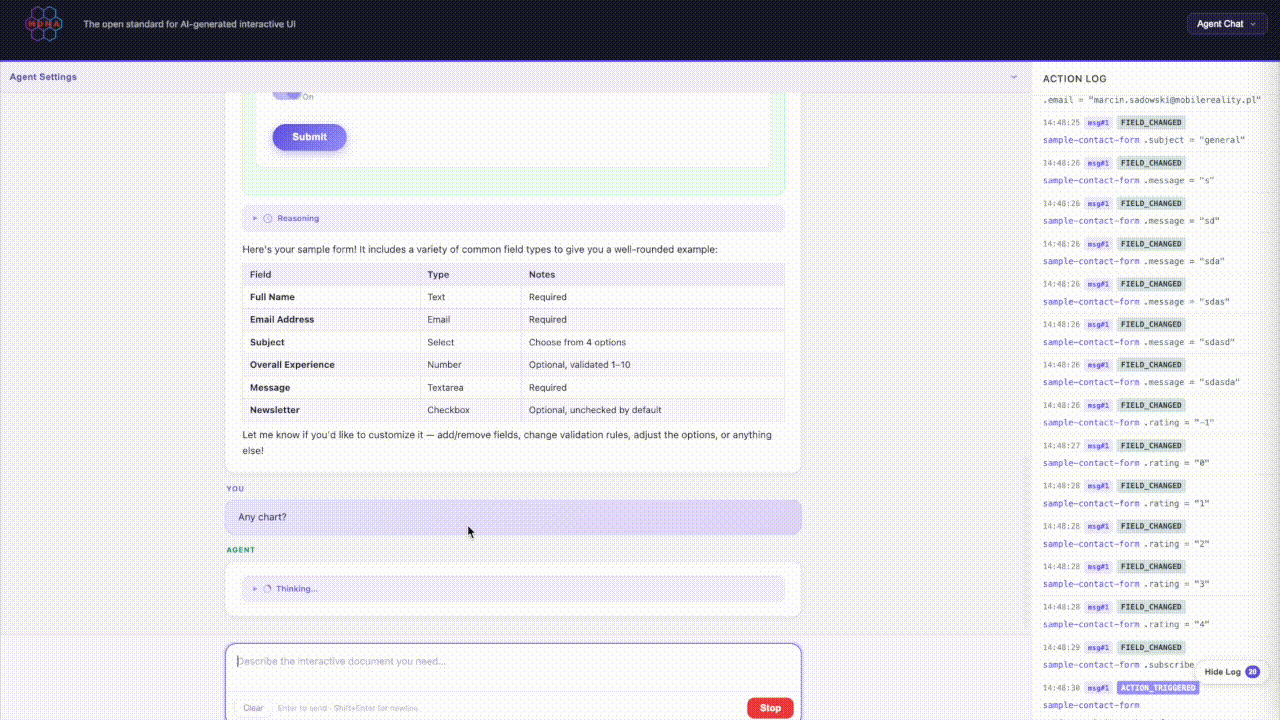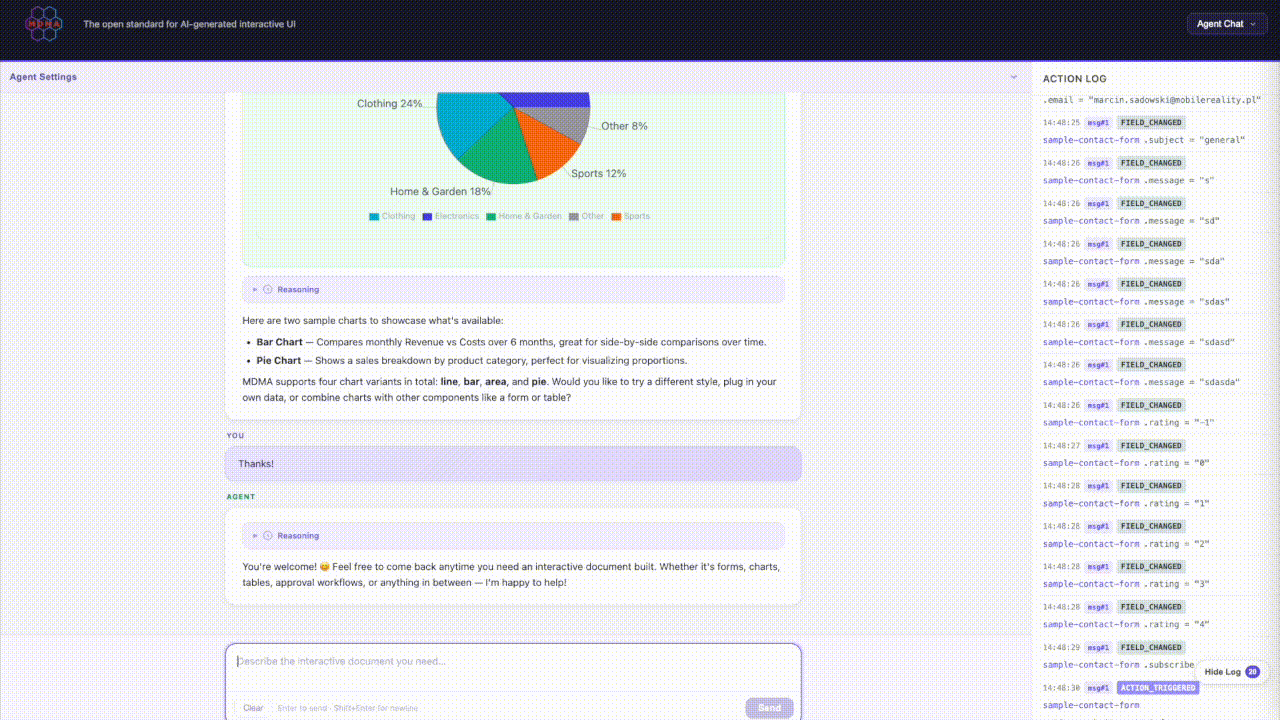
What is MDMA?
MDMA extends Markdown with interactive components defined in fenced mdma code blocks. A regular Markdown file becomes an interactive application:
Speed comparison
Same scenario, two models. GPT-5.5 and our own hosted MDMA-IL model.
Our model is available on Hugging Face: MobileReality/mdma-gemma4-26b-dsl-unsloth-v1
| GPT-5.5 | Our own hosted model |
|---|---|
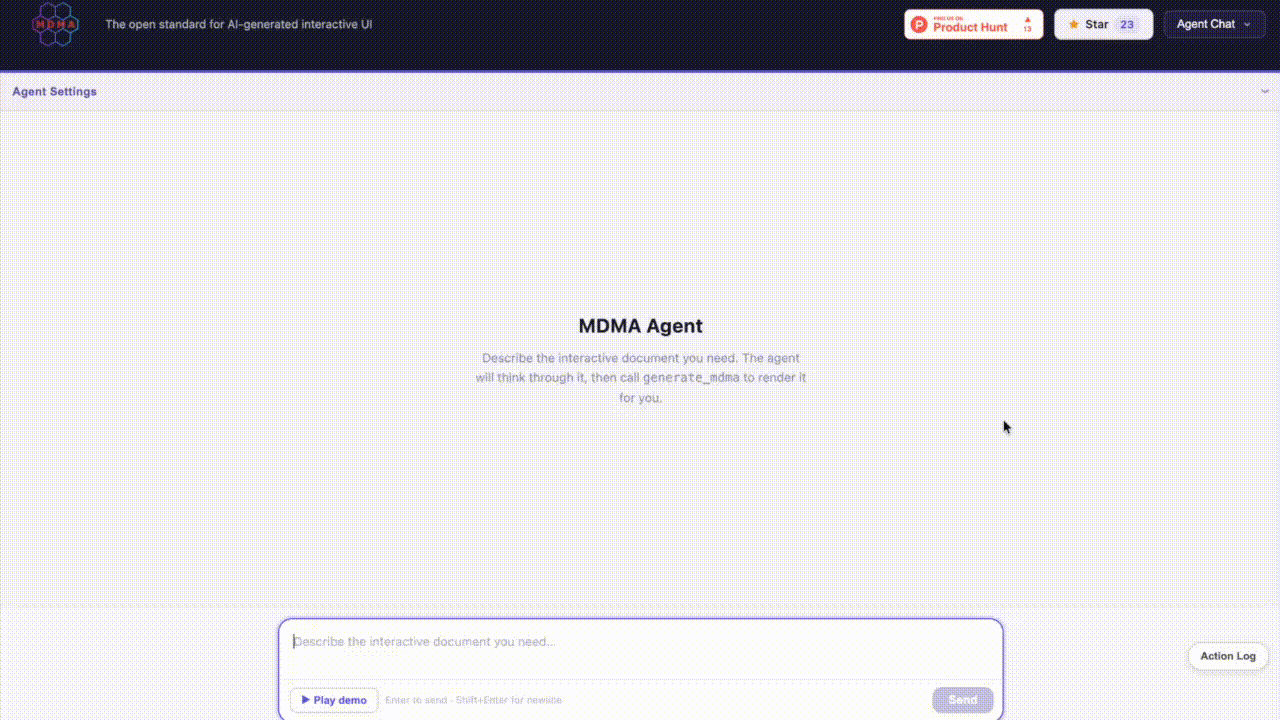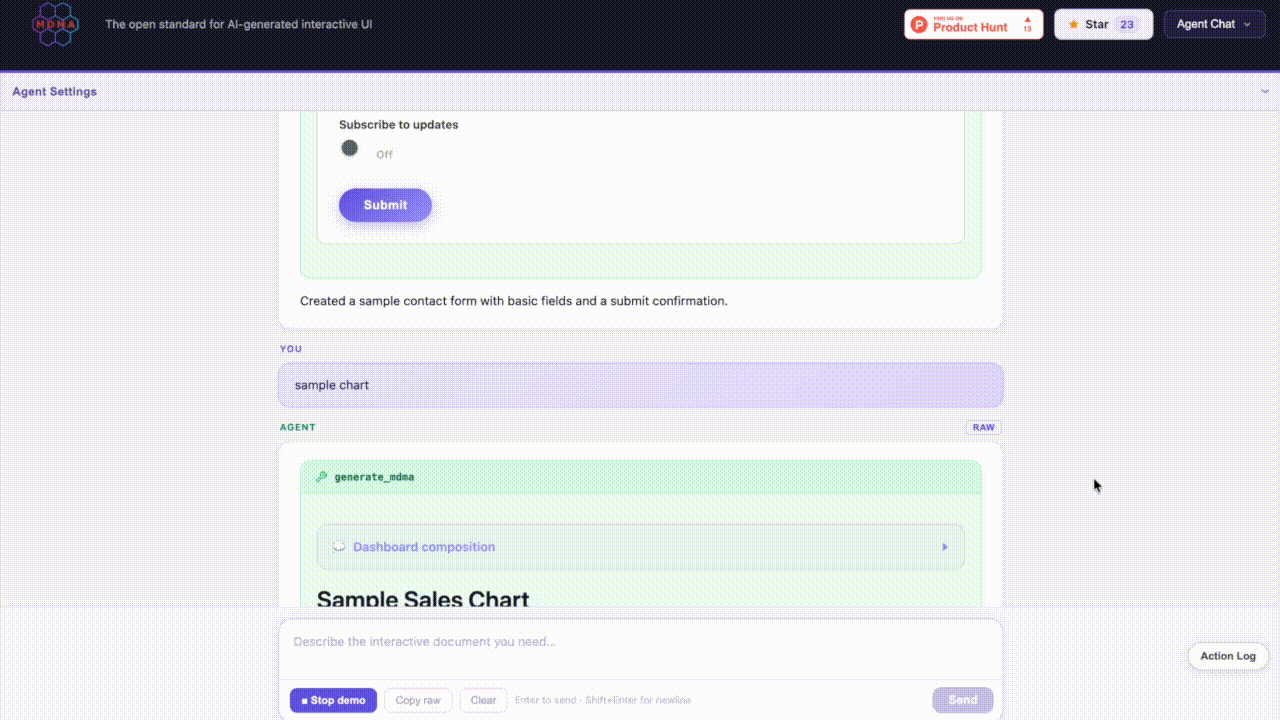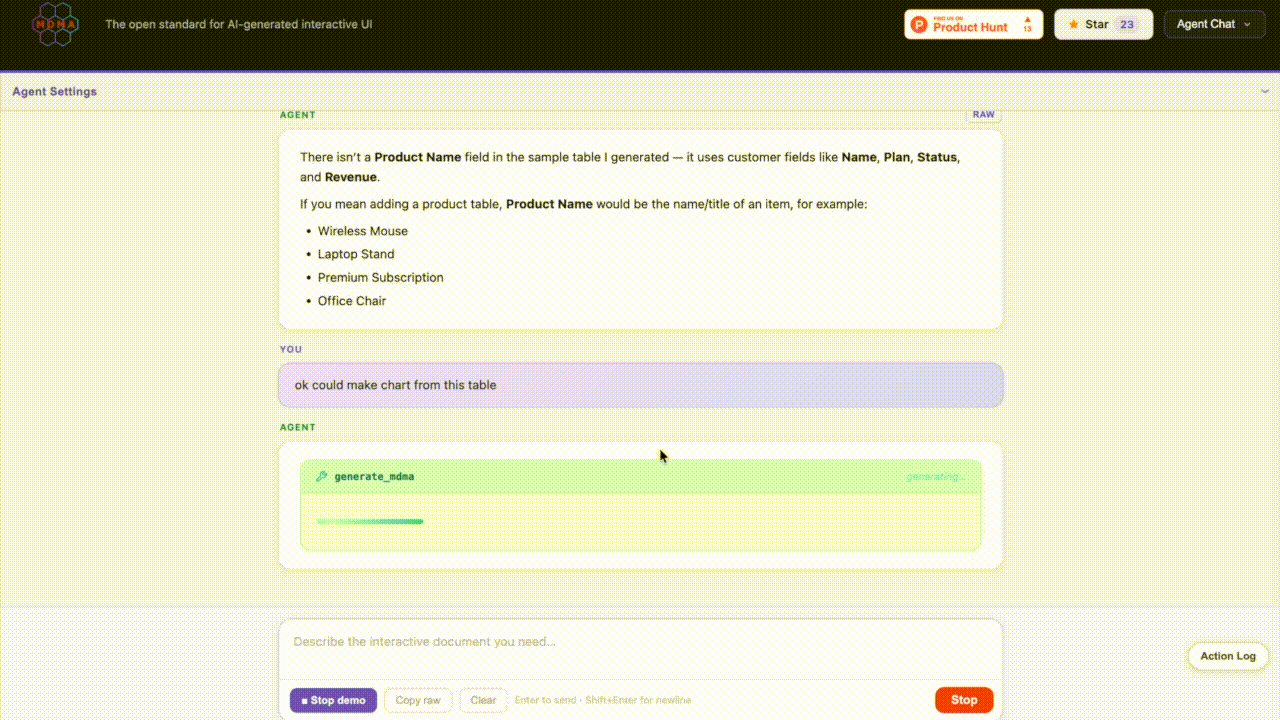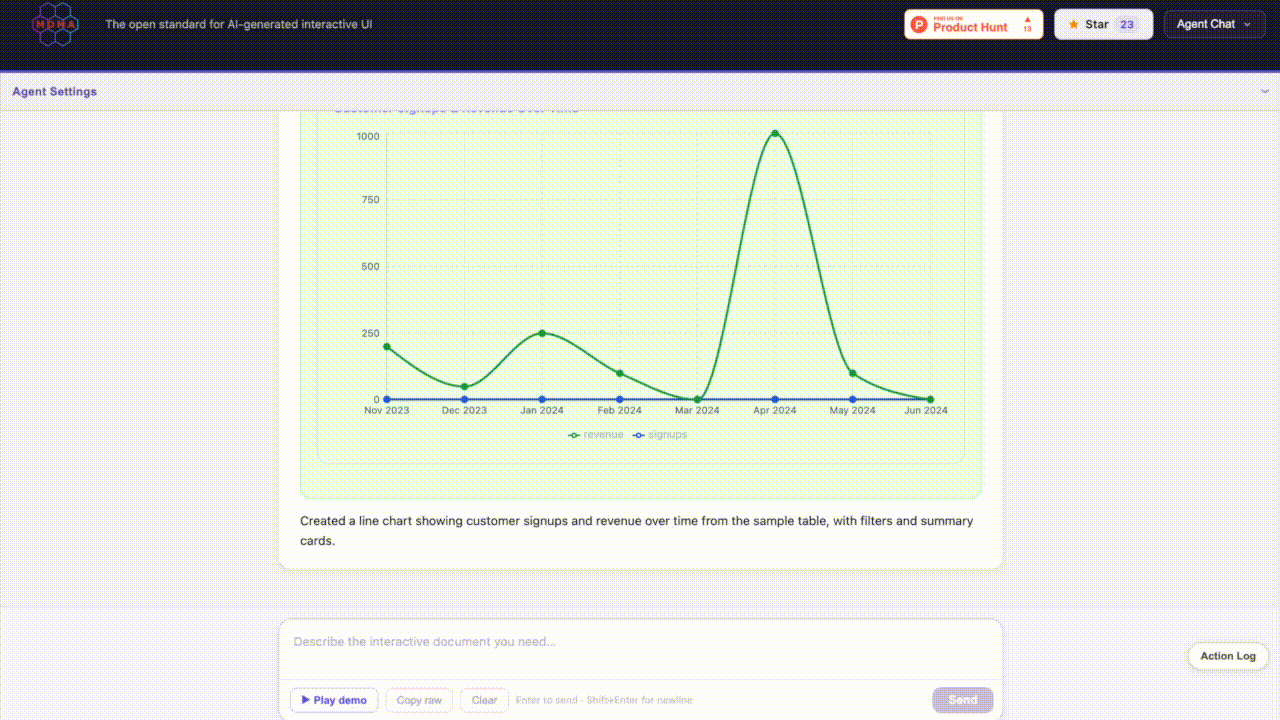 | 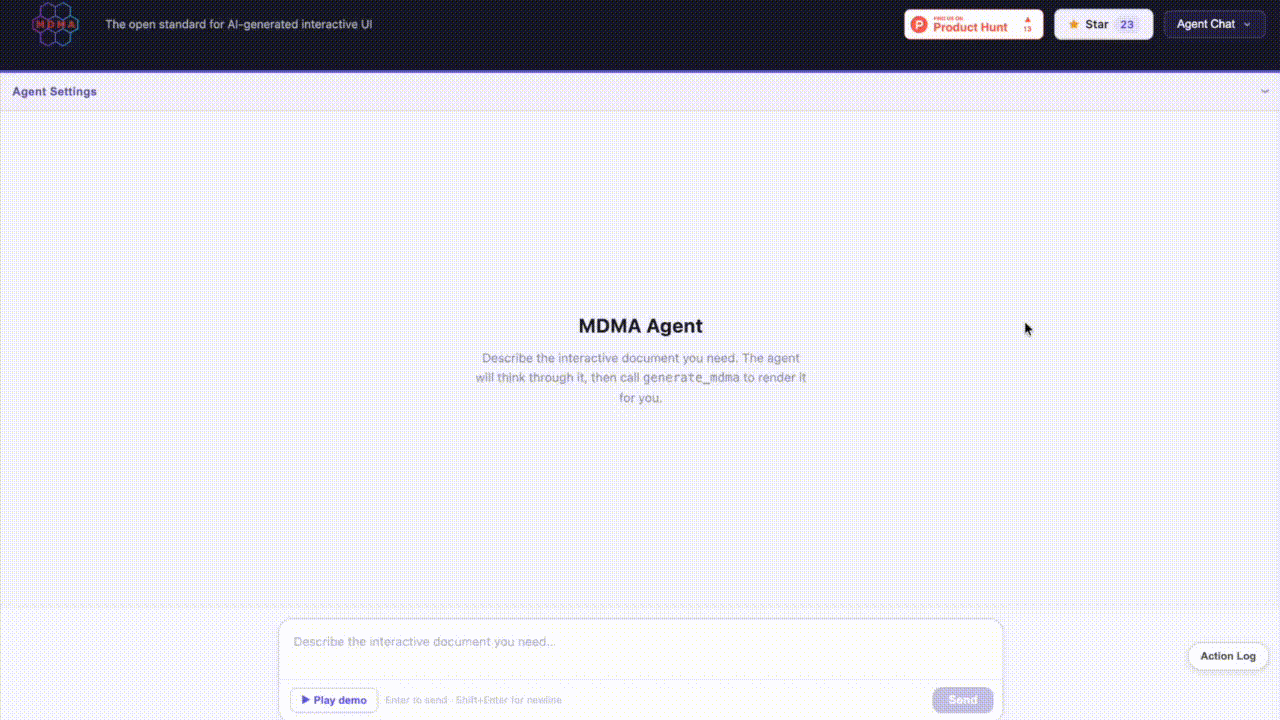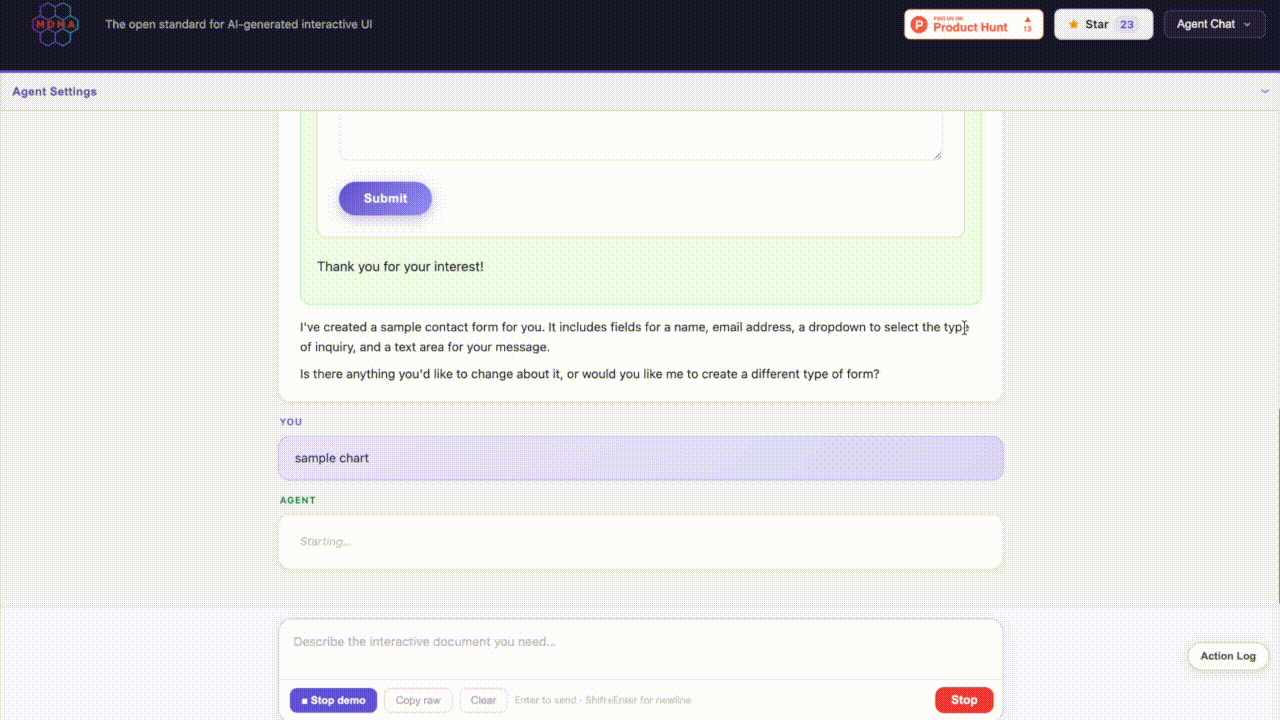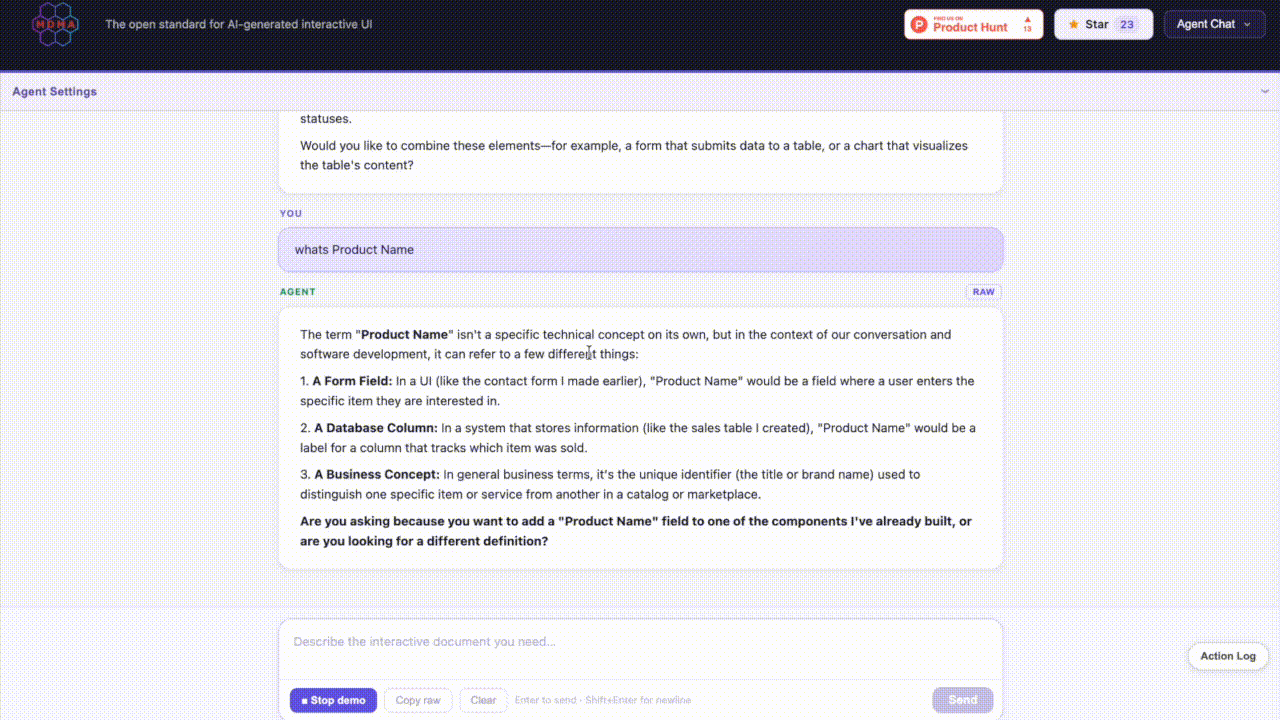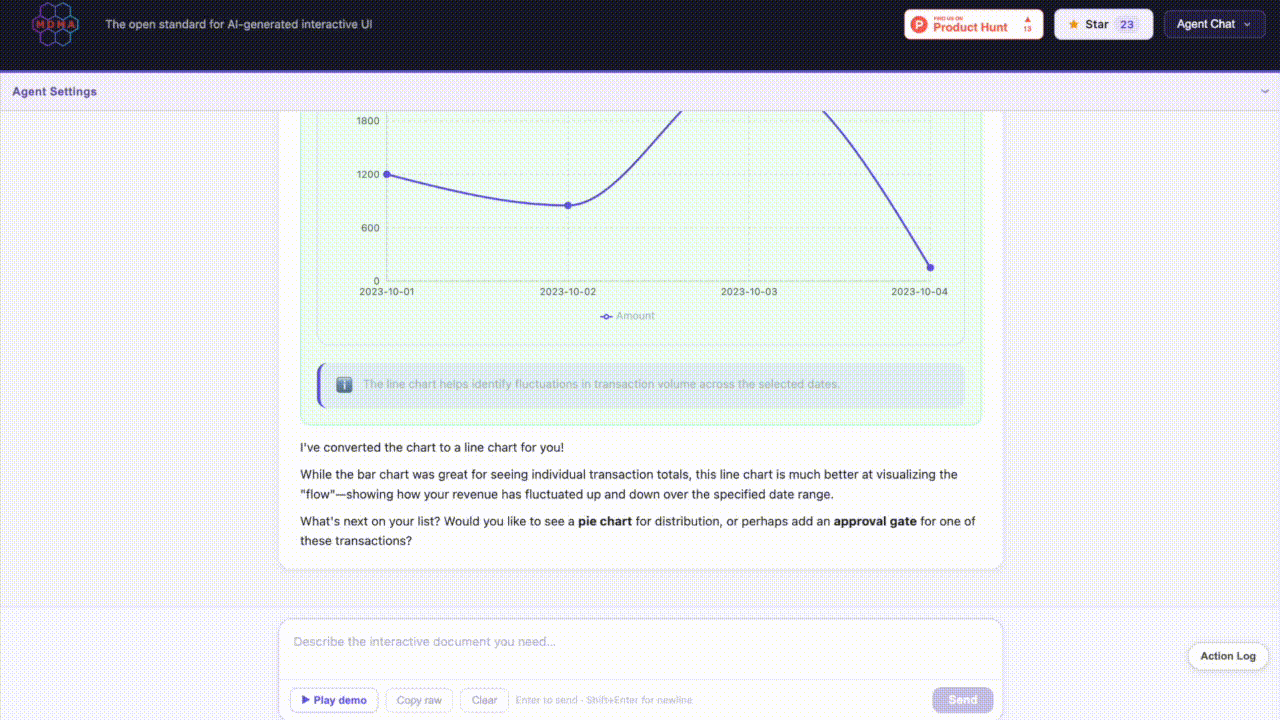 |
MDMA_AUTHOR prompt matrix
Each cell shows the pass rate of the model-specialized MDMA_AUTHOR prompt variant on the listed eval suite.
✅ 100% on the suite.
🟡 Scoring between 80–99% on the suite.
🔴 Scoring below 80% on the suite.
| Variant | one-shot | one-shot with custom prompt | conversation | specific flow of conversation |
|---|---|---|---|---|
| OpenAI | ||||
gpt-5.6-sol | ✅ | ✅ | ✅ | ✅ |
gpt-5.6-terra | ✅ | ✅ | ✅ | ✅ |
gpt-5.6-luna | ✅ | ✅ | ✅ | ✅ |
gpt-5.5 | ✅ | ✅ | ✅ | ✅ |
gpt-5.4 | ✅ | ✅ † | ✅ † | ✅ † |
gpt-5.4-mini | ✅ | ✅ | ✅ * | ✅ * |
gpt-5.4-nano | ✅ | ✅ | ✅ * | ✅ * |
gpt-5.2 | ✅ | ✅ | ✅ | ✅ |
gpt-5.1 | ✅ | ✅ | ✅ | ✅ |
gpt-5 [i] | ✅ | ✅ | ✅ | ✅ |
gpt-5-mini [i] | ✅ | ✅ | ✅ * | ✅ * |
gpt-5-nano [i] | ✅ | ✅ | 🟡 * | 🟡 * |
gpt-4.1 | ✅ | ✅ | ✅ | ✅ |
gpt-4.1-mini | ✅ | ✅ | ✅ * | ✅ * |
gpt-4.1-nano | ✅ | ✅ | ✅ * | 🟡 * |
| Anthropic | ||||
claude-opus-4.8 | ✅ | ✅ | ✅ | ✅ |
claude-opus-4.7 | ✅ | ✅ | ✅ | ✅ |
claude-opus-4.6 | ✅ | ✅ | ✅ | ✅ |
claude-sonnet-4.6 | ✅ | ✅ | ✅ | ✅ |
claude-haiku-4.5 | ✅ | ✅ | ✅ * | ✅ * |
claude-fable-5 | ✅ | ✅ | ✅ | ✅ |
gemini-3.5-flash | ✅ | ✅ | ✅ | ✅ |
gemini-3.1-pro-preview | ✅ | ✅ | ✅ | 🟡 ‡ |
gemini-3.1-pro-preview-customtools | ✅ | ✅ | ✅ | ✅ |
gemini-3.1-flash-lite-preview | ✅ | ✅ | ✅ * | ✅ * |
gemini-3-flash-preview | ✅ | ✅ | ✅ * | ✅ * |
gemini-2.5-pro | ✅ | ✅ | ✅ | ✅ |
gemini-2.5-flash | ✅ | ✅ | ✅ * | ✅ * |
gemini-2.5-flash-lite | ✅ | ✅ | ✅ * | ✅ * |
| xAI | ||||
grok-4.3 [i] | 🟡 | 🔴 | 🔴 | 🔴 |
grok-4.20 | ✅ | ✅ | ✅ | ✅ |
grok-4.5 | ✅ | ✅ | ✅ | ✅ |
| Zhipu (z.ai) | ||||
glm-4-plus | TBD | TBD | TBD | TBD |
| Moonshot | ||||
kimi-k2 | TBD | TBD | TBD | TBD |
| Alibaba | ||||
qwen3-max | TBD | TBD | TBD | TBD |
| MiniMax | ||||
minimax-m1 | TBD | TBD | TBD | TBD |
| Other | ||||
| model | — | — | — | — |
Don't see your model? Add a prompt variant under
packages/prompt-pack/src/prompts/mdma-author/<vendor>/and open a PR — we'll run the eval suite and add it to this table.
† gpt-5.4 intermittent duplication bug — gpt-5.4 passes one-shot evals reliably but shows a non-deterministic output duplication in multi-turn, custom-prompt, and flow evals (~7–15% of runs). The model generates a complete, correct response and then immediately re-emits the entire output verbatim, causing [duplicate-ids] validation errors. This is a known model-level issue unrelated to the prompt variant. See the OpenAI community thread for details. If this affects your use case, prefer gpt-5.5 or gpt-5.2.
‡ gemini-3.1-pro-preview stochastic preamble loop — on ~7–15% of flow-eval runs, the model emits a chain-of-thought as visible Markdown prose (e.g. **Investigating Production Errors** repeated 3–5 times) instead of opening a ```mdma block, producing either [yaml-correctness: outside fenced block] or [duplicate-ids] errors. Per Google's official Gemini 3 prompting guide, this is a model-level behavior driven by temperature/sampling — prompt-level fixes shift which test loops rather than eliminating the loops. If deterministic flow output matters, prefer gemini-2.5-pro for production multi-step flows.
* Smaller / lower-tier models from any lab (OpenAI mini · nano, Anthropic Haiku, Google Gemini Flash, etc.) pass our eval suites, which exercise short, structured test cases. In longer real-world conversations they tend to hallucinate, forget earlier turns, or drift from the spec. For production use that involves multi-turn dialogue or stateful flows, prefer the flagship-tier model from the same family.
[i] Noticeably slow response times — single-turn responses commonly take tens of seconds and full eval runs measure in minutes.
MDMA_FIXER prompt matrix
Each cell shows the pass rate of the model-specialized MDMA_FIXER prompt variant on the single-block fixer eval (16 tests covering structural fixes, bindings, PII, forms, tables/charts, approvals, and custom-component extraction). The fixer is what powers automatic repair of LLM output that fails validate() — every supported model lands at ✅ via model-tailored inline guards (no-leading-separator, preserve-input-structure, table-key-direction, replace-all-placeholders, fix-all-listed-errors, etc.).
✅ 100% on the single-block fixer eval (16/16).
| Variant | single-block fixer | notes for testing |
|---|---|---|
| OpenAI | ||
gpt-5.6-sol | ✅ | |
gpt-5.6-terra | ✅ | |
gpt-5.6-luna | ✅ | |
gpt-5.5 | ✅ | |
gpt-5.4 | ✅ | |
gpt-5.4-mini | ✅ | |
gpt-5.4-nano | ✅ | |
gpt-5.2 | ✅ | |
gpt-5.1 | ✅ | |
gpt-5 | ✅ | |
gpt-5-mini | ✅ | |
gpt-5-nano | ✅ | |
gpt-4.1 | ✅ | |
gpt-4.1-mini | ✅ | |
gpt-4.1-nano | ✅ | |
| Anthropic | ||
claude-opus-4.8 | ✅ | |
claude-opus-4.7 | ✅ | |
claude-opus-4.6 | ✅ | |
claude-sonnet | ✅ | catch-all variant — matches claude-sonnet-4-5, claude-sonnet-4-6, etc. |
claude-haiku | ✅ | |
claude-fable-5 | ✅ ‡ | requires reasoning.exclude: true (wired in evals/promptfooconfig.fixer.js) |
gemini-3.5-flash | ✅ ‡ | requires reasoning.exclude: true; adds an inline no-leading-separator guard |
gemini-3.1-pro-preview | ✅ ‡ | requires OpenRouter reasoning.exclude: true (already wired in evals/promptfooconfig.fixer.js) |
gemini-3.1-pro-preview-customtools | ✅ ‡ | same reasoning.exclude requirement |
gemini-3.1-flash-lite-preview | ✅ | |
gemini-3-flash-preview | ✅ | |
gemini-2.5-pro | ✅ ‡ | same reasoning.exclude requirement |
gemini-2.5-flash | ✅ | |
gemini-2.5-flash-lite | ✅ | |
| xAI | ||
grok-4.3 | ✅ ‡ | minimal prompt + reasoning.exclude: true — extra framing regresses Grok 4.3 |
grok-4.20 | ✅ | |
grok-4.5 | ✅ ‡ | requires reasoning.exclude: true (hidden-reasoning model) |
‡ Reasoning-token leak suppression — for reasoning-flavoured Gemini Pro variants and Grok 4.3, the fixer would otherwise see visible "Thinking: Topic" prose prepended to every response. The eval config sets passthrough.reasoning.exclude: true (and the demo's usePreviewValidation does the same per-provider) to strip reasoning tokens from the response body at the API layer rather than at the prompt layer.
Components
10 built-in component types, all rendered out of the box by @mobile-reality/mdma-renderer-react:
Related MCP Servers
Adoption & maintenance
Factual signals from GitHub, npm, and our automated checks — not a rating.
GitHub stars
67
Stargazers on the source repository.
npm downloads
73
Package downloads in the last 30 days.
Last commit
1mo ago
Most recent push to the default branch.
Tools exposed
8
Callable tools this server registers over MCP.
Reviews
No reviews yet — be the first to share how this listing worked for you.
Frequently Asked Questions about Mdma
AllMCPs Directory Badge
Showcase your server listing on GitHub or your project documentation. Embed this dynamic SVG badge to highlight official listing status and live engagement.
Badge Style:
Live Dynamic SVG Preview
Markdown (GitHub README)
[](https://allmcps.com/mcp/mdma)HTML Embed
<a href="https://allmcps.com/mcp/mdma"><img src="https://allmcps.com/api/badge/mdma?style=directory" alt="Mdma on AllMCPs" /></a>Technical Specs & Signals
CategoryDeveloper Tools
11/13 checks healthy over the last 46d
57Quality signal: Good · 57/100How this signal is calculated ▾
Server availabilityNot measured
Not scored for repo-hosted servers — we can't reach the running server, only its GitHub page. Hosted MCP endpoints are health-checked live.
Verified ownership10/20
Documentation & tools25/30
Adoption & activity8/15
Community engagement0/10
A guidance signal from public completeness & health data — not a user rating. New listings start lower and rise as they add docs, get verified, and grow adoption. Signals we can't observe for a listing are skipped, not counted against it.
Supply-chain signal
No high-severity advisories surfaced by our automated scan.
Critical 0High 0Medium 0Low 0
Scanned 2d ago via OSV.dev · @mobile-reality/mdma-cli (npm)
Own this project?
This directory is pre-filled from public sources. Claim via GitHub README, site badge, or DNS TXT to unlock edit access and the Official badge — proof is checked automatically, then reviewed by our team.
Free dofollow backlink: add your website and place the AllMCPs badge on it — no claim needed. We detect it automatically and keep it verified as long as the badge stays live.
Claim & get free dofollowShare & Embed
Add our SVG badge (dark/light directory styles) or embeddable widget to your site.