MCP Cost Optimizer
See what your LLM calls cost and how much you'd save by switching models — local MCP server, no API keys.
Find overspending in your AI agent's usage records. Compare the cost of every model you're considering. Make decisions with real numbers, not guesses.



🚀 Quick Install
Cursor

Click the button above to install in Cursor with one click, or use this deeplink:
cursor://anysphere.cursor-deeplink/mcp/install?name=cost-optimizer&config=eyJjb21tYW5kIjoibnB4IiwiYXJncyI6WyIteSIsIm1jcC1jb3N0LW9wdGltaXplciJdfQ==
Claude Code
# Quick install
claude mcp add cost-optimizer -- npx -y mcp-cost-optimizer

# Or via marketplace
/plugin marketplace add petrovicistefan/mcp-cost-optimizer
/plugin install mcp-cost-optimizer@mcp-cost-optimizer
VS Code
Or manually add to .vscode/mcp.json:
{
  "servers": {
    "cost-optimizer": {
      "type": "stdio",
      "command": "npx",
      "args": ["-y", "mcp-cost-optimizer"]
    }
  }
}
Any MCP Client
npx -y mcp-cost-optimizer
See detailed setup instructions for other clients (Windsurf, Cline, Gemini CLI, Zed, Codex CLI).
Table of Contents
- Quickstart
- Why MCP Cost Optimizer?
- Example Prompts
- MCP Tools
- Importing Usage Data
- Use Cases
- Privacy & Security
- Comparison
- Limitations
- Free and Pro
- Roadmap
- Contributing
- License
- More MCP Servers by the Author
Quickstart
Claude Code Plugin
/plugin marketplace add petrovicistefan/mcp-cost-optimizer
/plugin install mcp-cost-optimizer@mcp-cost-optimizer
Any MCP Client
Works with Cursor, VS Code, Windsurf, Claude Desktop, Cline, Codex CLI, Zed, and Gemini CLI. Install with one command:
npx -y mcp-cost-optimizer
Or add to your MCP config file:
Claude Desktop, Cursor, Windsurf, Cline, Gemini CLI — claude_desktop_config.json, ~/.cursor/mcp.json, ~/.codeium/windsurf/mcp_config.json, Cline MCP settings, ~/.gemini/settings.json:
{
  "mcpServers": {
    "cost-optimizer": {
      "command": "npx",
      "args": ["-y", "mcp-cost-optimizer"]
    }
  }
}
VS Code / GitHub Copilot — .vscode/mcp.json:
{
  "servers": {
    "cost-optimizer": {
      "type": "stdio",
      "command": "npx",
      "args": ["-y", "mcp-cost-optimizer"]
    }
  }
}
Zed — settings.json:
{
  "context_servers": {
    "cost-optimizer": {
      "command": "npx",
      "args": ["-y", "mcp-cost-optimizer"]
    }
  }
}
Codex CLI:
codex mcp add cost-optimizer -- npx -y mcp-cost-optimizer
⭐ Support This Project
Found this MCP useful? Star this repository!
A GitHub star helps other developers discover the project and lets you save it for later. Thanks for supporting open source!
Demo
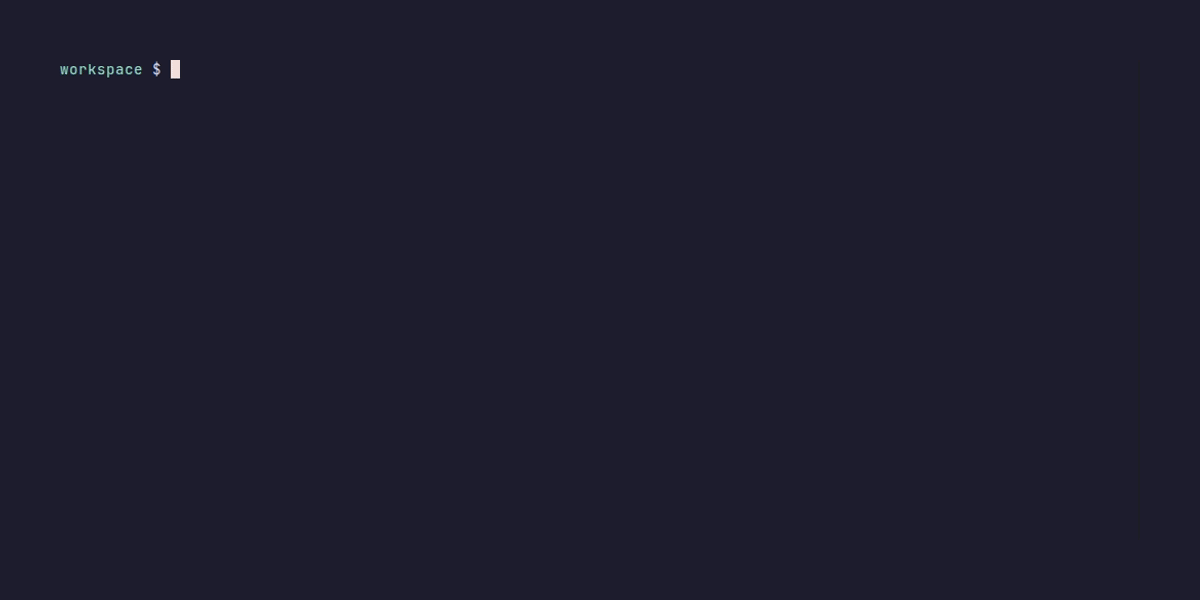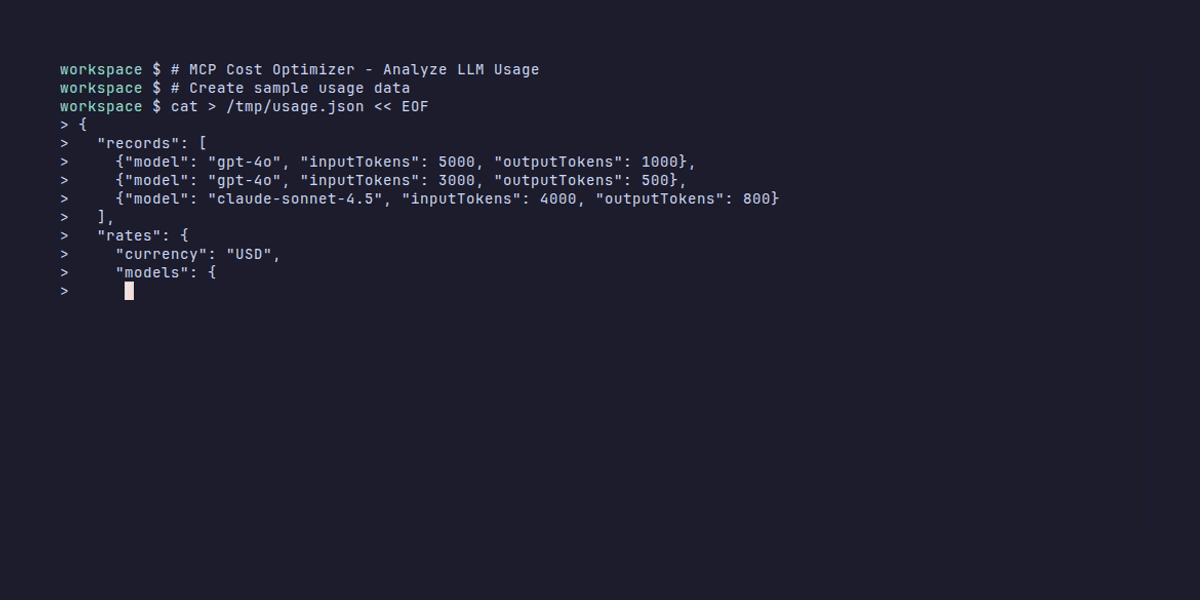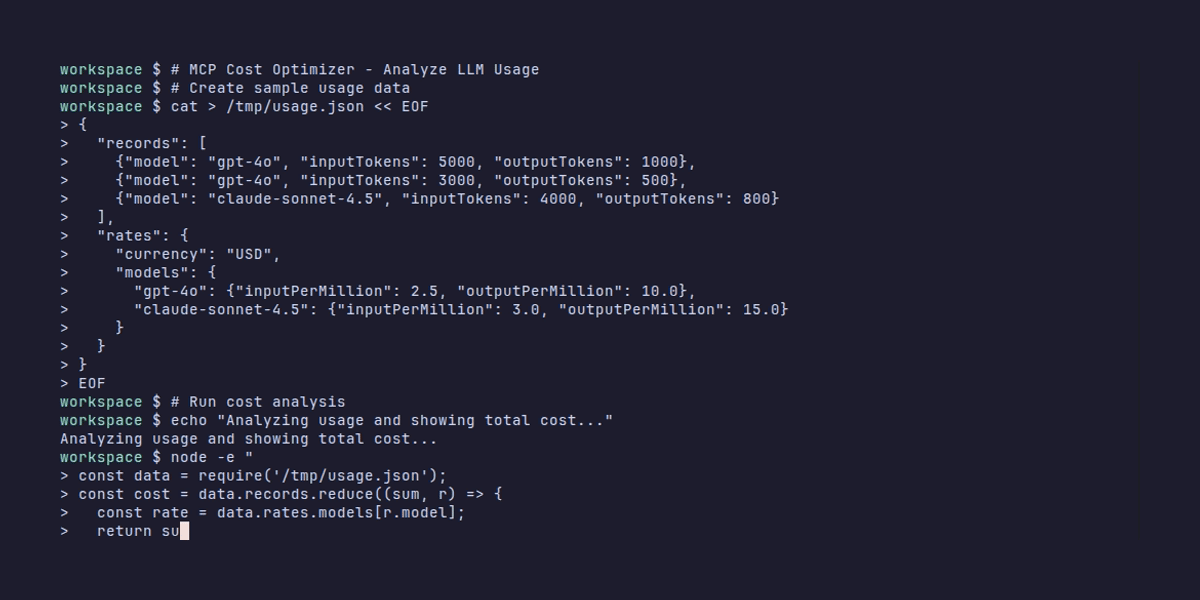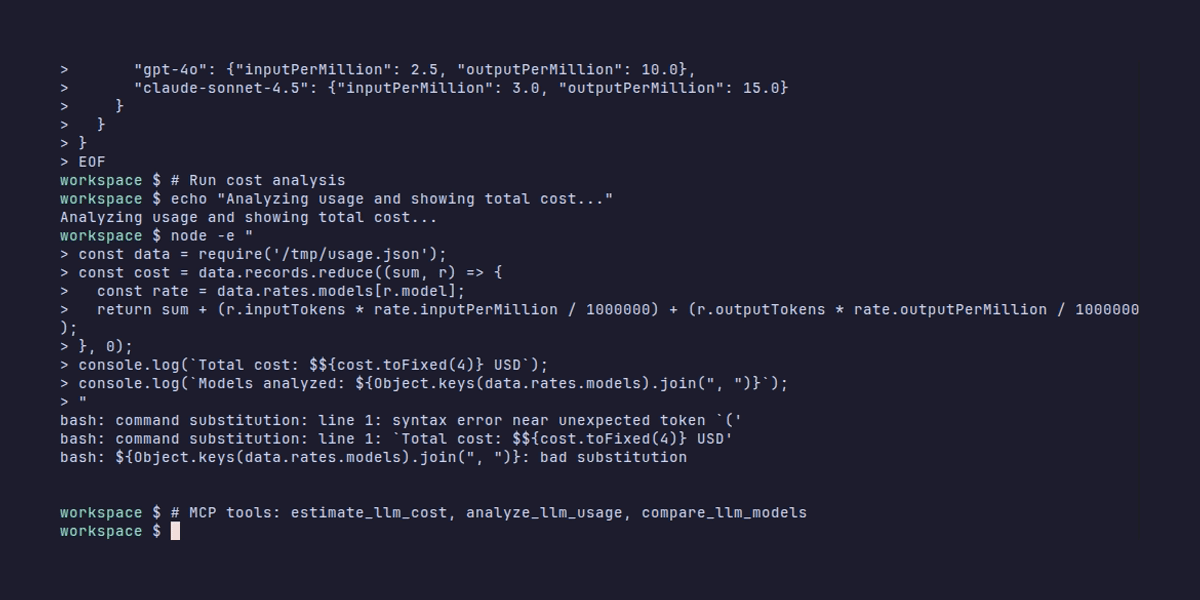
Analyzing LLM usage across multiple models with custom pricing rates
Why MCP Cost Optimizer?
You're running AI agents. You have usage logs. You're wondering:
- How much did that cost? Analyze normalized usage records and see total cost, per-model breakdown, and which models lack pricing data.
- What if I switched models? Compare migration scenarios: keep your token counts, change the model, see estimated savings (or extra cost).
- Am I repeating the same requests? Identify conditional response-cache opportunities when you supply request hashes.
MCP Cost Optimizer is:
- Local-first: No API keys, no accounts, no outbound requests. Your usage data stays on your machine.
- Provider-agnostic: Bring your own pricing tables. Works with any LLM provider.
- Transparent: All calculations are deterministic. No hidden assumptions, no magic. You supply the prices, you get exact estimates.
Example Prompts
Once installed, try asking your AI agent:
"Analyze these normalized usage records with my supplied rates. Identify unknown models and repeated requests, then compare a cheaper model. Explain assumptions and do not change production routing."
"I have 50,000 requests across gpt-4o and claude-sonnet-4.5. Estimate the cost with these rates, then show me the savings if I switched to gpt-4o-mini for half of them."
"Compare my current model usage to claude-haiku-3-5. What would I save per month if I migrated?"
Tools
The server exposes three MCP tools for cost analysis:
| Tool | Description | Inputs | Output |
|---|---|---|---|
estimate_llm_cost | Estimate one LLM request from supplied per-million token rates. Input tokens include cached tokens. | record (model, tokens), rates (pricing) | Single-request cost estimate with currency and pricing date |
analyze_llm_usage | Analyze normalized LLM usage; report costs, unknown models and conditional response-cache opportunities. No network or file access. | records (array, max 100k), rates (pricing) | Aggregate analysis: total cost, per-model breakdown, unknown models, duplicate request opportunities, token totals |
compare_llm_models | Compare a target model with known-price baseline. Scenario only; requires quality evaluation and does not change routing. | records (array, max 100k), rates (pricing), targetModel (string) | Migration scenario: what you'd spend with a different model, keeping the same token counts (requires quality evaluation separately) |
All tools:
- Accept structured JSON arguments
- Return formatted text + structured JSON
- Read-only and idempotent (safe to call repeatedly)
- No network requests or file access
Importing Usage Data
The hook is weak because the tools require normalized usage records. Here's how to get them.
Expected Input Format
Each usage record must include:
{
  "model": "gpt-4o",
  "inputTokens": 1000,
  "outputTokens": 50,
  "cachedInputTokens": 0,
  "requestHash": "optional-unique-identifier"
}
Rules:
model: Exact model name (must match your rates file)inputTokens: Total input tokens, including cached tokensoutputTokens: Total output tokenscachedInputTokens: (Optional) Prompt cache hits (must be ≤inputTokens)requestHash: (Optional) Unique identifier for the entire request (tenant, model params, system context, tool state, freshness) — used to identify conditional response-cache opportunities
Important: OpenAI's prompt_tokens and Anthropic's separate cache fields are not accepted directly. You must normalize them first.
Example: OpenAI Usage Export
If you export usage from OpenAI's dashboard, you might get CSV with columns like model, prompt_tokens, completion_tokens, cached_tokens.
Transform to normalized format:
// Example transformation (Node.js)
const fs = require('fs');
const Papa = require('papaparse'); // npm install papaparse

const csv = fs.readFileSync('openai-usage-export.csv', 'utf8');
const parsed = Papa.parse(csv, { header: true, dynamicTyping: true });

const normalized = parsed.data.map(row => ({
  model: row.model,
  inputTokens: row.prompt_tokens, // OpenAI prompt_tokens = total input
  outputTokens: row.completion_tokens,
  cachedInputTokens: row.cached_tokens || 0,
  requestHash: row.request_id // if available
}));

fs.writeFileSync('normalized-usage.jsonl', normalized.map(r => JSON.stringify(r)).join('\n'));
Then supply normalized-usage.jsonl to your agent along with your rates file.
Example: Anthropic Usage Export
Anthropic's usage exports include separate fields for input_tokens, cache_creation_input_tokens, cache_read_input_tokens, and output_tokens.
Transform to normalized format:
// Anthropic → normalized format
const normalized = anthropicUsage.map(row => ({
  model: row.model,
  inputTokens: row.input_tokens + row.cache_creation_input_tokens + row.cache_read_input_tokens,
  outputTokens: row.output_tokens,
  cachedInputTokens: row.cache_read_input_tokens,
  requestHash: row.request_id // if available
}));
Note: Cache-write pricing is separate from normal input pricing. This MVP does not support differential cache-write rates. If you supply cachedInputPerMillion in your rates file, it applies to cache reads only.
Rates File Format
Supply your own pricing table as JSON:
{
  "currency": "USD",
  "asOf": "2026-10-19",
  "models": {
    "gpt-4o": {
      "inputPerMillion": 2.5,
      "outputPerMillion": 10.0,
      "cachedInputPerMillion": 1.25
    },
    "claude-sonnet-4.5": {
      "inputPerMillion": 3.0,
      "outputPerMillion": 15.0
    }
  }
}
currency: Three-letter code (e.g.,"USD","EUR")asOf: (Optional) Date when prices were verifiedmodels: Keyed by exact model nameinputPerMillion: Price per million input tokensoutputPerMillion: Price per million output tokenscachedInputPerMillion: (Optional) Price per million cached input tokens (defaults toinputPerMillionif omitted)
All models in the rates file must use the same currency. Unknown models are excluded from totals and marked as incomplete.
See examples/rates.json for a demo file (fictional prices).
Use Cases
1. AI Agent Cost Audit
You've run Claude Code or Cursor for a month. You have session logs. You want to know:
- Total spend per model
- Which models lacked pricing data
- Where you can save by switching models
Workflow: Export your usage, normalize it, supply it to your agent with this MCP server installed. Ask: "Analyze my usage and compare it to a cheaper model."
2. Model Migration Planning
You're considering migrating from gpt-4o to gpt-4o-mini for some workloads.
Workflow: Use compare_llm_models to estimate savings. Keep in mind: the tool assumes token counts stay the same. You must separately evaluate quality, context window, and latency.
3. Response Cache Opportunity Detection
You supply requestHash for each request (a hash of tenant, model params, system context, tool state, freshness requirements).
Workflow: The analyze_llm_usage tool identifies duplicate hashes and reports upper-bound savings if you implemented conditional response caching. This is not provider prompt caching—it's request-level deduplication.
4. Individual Developer / Freelancer
You're working across multiple clients. You want to track LLM costs per project.
Workflow: Keep separate usage logs per project. Analyze each independently. Sum totals for invoicing.
5. Team / Enterprise
Your team shares an API key. You want to attribute costs per engineer or per feature.
Workflow: Tag usage records with engineer/feature identifiers. Analyze subsets. (Future: hosted path with budgets and alerts.)
Privacy & Security
- No telemetry: Zero outbound requests from the local MCP server or CLI.
- No credentials: The server never asks for or stores API keys.
- No file writes: MCP tools accept structured data only; they do not read or write files.
- CLI sandboxing: The CLI reads JSON/JSONL files only under its current directory, resolves symlinks, and rejects paths outside that root. Files are checked for regular-file type and size (≤20 MiB) before reading. JSONL is parsed incrementally and capped at 100,000 records.
- Safe arithmetic: Aggregated token counts reject unsafe integer totals. Cost calculations reject infinite results.
Comparison
| Tool | Focus | Local | Import Format | Model Comparison | Cache Opportunities | MCP Server |
|---|---|---|---|---|---|---|
| MCP Cost Optimizer | Cost analysis & model-switch scenarios | ✅ | Normalized JSON | ✅ | ✅ (request-level) | ✅ |
| agentacct | Agent work intelligence & cost dashboard | ✅ | Claude Code/Codex logs | ❌ | ❌ | ❌ (Python dashboard) |
| Tokenscope | Menu-bar dashboard for Claude CLI | ✅ | Claude CLI logs | ❌ | ❌ | ❌ (macOS/Windows app) |
| tokentop | Real-time terminal monitoring | ✅ | Provider APIs + session files | ❌ | ✅ (provider cache %) | ❌ (TUI) |
| llm-cost-dashboard | Terminal dashboard with budgets & forecasts | ✅ | Log file / stdin | ❌ | ❌ | ❌ (Rust TUI) |
What sets MCP Cost Optimizer apart:
- MCP-native: Works with any MCP client (Claude Code, Cursor, VS Code, Windsurf, Cline, Zed, Claude Desktop, Gemini CLI, Codex CLI).
- Model comparison: Estimate savings (or extra cost) for migration scenarios.
- Request-level cache detection: Identify duplicate requests when you supply hashes.
- Provider-agnostic: Bring your own pricing tables (OpenAI, Anthropic, Gemini, Llama, Mistral, etc.).
- Transparent: All calculations are deterministic. No guesswork, no hidden assumptions.
Limitations
This is an MVP (v0.1.2). Here's what it doesn't do yet:
- Cache-write pricing: Separate cache-write rates are not supported. Only cache-read pricing is configurable via
cachedInputPerMillion. - Reasoning tokens: Extended reasoning tokens (e.g., OpenAI o1/o3 series) are not separately priced in this version.
- Automatic pricing updates: You must maintain your own rates file. The tool does not fetch live pricing from providers.
- Invoice reconciliation: Estimates are based on your supplied prices, not provider invoices. Currency conversion and taxes are not included.
- Quality evaluation: Model comparisons assume token counts stay the same. You must separately evaluate quality, tokenizer differences, context window, tool support, and latency.
- Automatic routing: The tool provides estimates only. It does not change your application's model selection.
Free and Pro
- Local MCP/CLI: Free forever. Works offline. No accounts, no API keys, no quotas.
- Hosted path (future): For teams that want centralized quotas, budgets, and alerts, a hosted HTTP path with control-plane integration is planned. Pricing TBD.
Roadmap
- Provider adapters for automatic normalization (OpenAI, Anthropic, Gemini, Bedrock)
- Cache-write and reasoning token accounting
- Verified versioned pricing catalog
- Project budgets and alerts
- Quality-gated model evaluation
- Hosted reporting dashboard
Validate these features with real usage before adding automatic optimizations.
Contributing
Contributions welcome! See CONTRIBUTING.md (if exists) or open an issue.
Before contributing:
- Run
npm testandnpm run checkto verify your changes. - Follow the existing code style (zero external dependencies in core.js, ESM modules, node:test for tests).
- Add tests for new features.
License
MIT License - see LICENSE file for details.
Copyright © 2026 Stefan Petrovici
Free to use, modify, and distribute. No warranty provided.
More MCP Servers by the Author
Part of the petrovicistefan MCP suite — local-first guardrails for AI coding agents.
| Server | Purpose | Link |
|---|---|---|
| 🛡️ MCP Security Guard | Detect tool poisoning, rug pulls, prompt injection in MCP servers | GitHub |
| 💰 MCP Cost Optimizer | Analyze LLM costs and model-switch savings | GitHub |
| 🗄️ MCP Database Doctor | Diagnose schema issues, slow queries, missing indexes | GitHub |
| 📦 MCP Dependency Doctor | Find outdated packages, CVEs, license conflicts | GitHub |
| 🔍 MCP SEO Auditor | Local SEO checks for meta tags, schema, performance | GitHub |
| 🌐 MCP API Guardian | Validate OpenAPI specs, detect breaking changes | GitHub |
| 🏪 MCP Marketplace | Browse and discover the full suite | GitHub |
Found this useful? ⭐ Star this repo to help others discover it!