Loci README
The full upstream README, mirrored here for reference. Install config, tool schemas, adoption signals, and an original overview live on the Loci listing page.
loci 🧠



Two thousand years ago, orators stored their speeches in the rooms of a palace and walked through them to remember. loci does the same for your files.
Loci is the method behind every memory palace: place knowledge in locations, recall it by walking the path.
A queryable "second brain" for the project docs, notes, and chat logs scattered across a dozen directories — and an MCP server so your AI agents can use it too.
Local files → heading-aware chunking → embeddings → hybrid retrieval (vector + BM25) → LLM answer with section-level citations. The index lives entirely on your machine; only embedding/chat calls go out, to any OpenAI-compatible API (Zhipu / DeepSeek / Kimi / OpenAI / …).
The thesis (from studying the 90k-star platforms and the graveyard of dead lightweight tools — see our competitive landscape study): don't build another chat app. Build the memory layer that every chat app can mount. Claude Desktop, Cursor, Cline, or any MCP host becomes this project's UI, for free.
Demo
Real session, indexed against the docs of minimax-h3-turing (paths shortened for display):
Hybrid retrieval means a Chinese query still finds the English doc (and vice
versa) — keyword evidence (BM25) catches what embeddings miss, and every
citation points at a section, not just a file.
Does hybrid actually help? (mini-eval, 10 bilingual queries)
Hybrid also fixed the #1 ranking on keyword-ish queries (e.g. "T8 block cache threshold speedup": vector put an FAQ first, hybrid puts the actual T8 writeup first). Run it against your own corpus with your own cases file.
Reranking: two providers
--rerank reorders the fused candidates for precision:
| Provider | How | Cost |
|---|---|---|
llm (default) | pointwise 0–3 relevance scoring by your chat model | one extra LLM call |
local | cross-encoder, via pip install 'loci[rerank]' | ~30–70 ms for 5 pairs on GPU — offline, free |
The local model downloads on first use (~1.1 GB; set HF_ENDPOINT=https://hf-mirror.com
if HuggingFace is slow in your region). Measured on a 2080 Ti, bilingual query.
Office documents, PDF tables, web pages, org files, chat logs
- PDFs: with the
[pdf]extra, PyMuPDF4LLM extracts pages as markdown — tables come through as pipe rows (plain pypdf text is the fallback) - Word: with the
[docx]extra,.docxparagraphs and table rows are indexed - HTML:
.html/.htmpages become text with headings preserved (stdlibhtml.parser, zero dependencies —<meta charset>honored, script/style skipped) - org-mode:
.orgnotes convert faithfully —#+TITLEbecomes the h1 with*-sections nested under it,#+FILETAGSbecome searchable tags - Chat exports: drop a ChatGPT or Claude
conversations.jsoninto any source directory — it becomes one searchable document per conversation, taggedchatlog(search --tag chatlogscopes to chat history)
How it relates to Obsidian / your note app
It doesn't compete — the two layer up. Obsidian (or any editor) is the
note-taking frontend; this is the cross-vault search engine: point
sources at any directories (Obsidian vaults, project docs, chat exports)
and query all of them at once — from your terminal, your scripts, or your AI
agent via MCP. Obsidian-native details are understood: frontmatter tags:
(filter with search --tag), [[wikilinks]] (walk the graph with links),
code blocks are never cut mid-block, and one-line notes stay searchable.
How it works
The write path in one line: loaders → chunker (heading-aware split) → embedder → store (ChromaDB, persistent) — incremental, deduplicated by content hash.
Install & quick start
Requires Python 3.11+ (uses the stdlib tomllib).
The workflow
Commands
| Command | What it does |
|---|---|
ingest | scan sources, index new/changed files, prune deleted ones (--force re-embeds everything) |
search "query" | retrieval only — ranked excerpts with path > section breadcrumbs |
ask "question" | retrieval + LLM answer with [source: path > section] citations |
ask "…" --verify | additionally audit the answer claim-by-claim against the sources (✓ supported, ~ partial, ✗ unsupported) |
Filter operators (combine freely, on search and ask):
| Flag | Filters to |
|---|---|
--tag foo | files whose frontmatter tags contain foo |
--in docs/en | files whose path contains the substring |
--since 2026-08 / --since 2026-08-15 | files modified on/after that date |
-e "exact phrase" | chunks containing the exact phrase |
-k N | return N hits (default 5) |
links "note" | show the [[wikilink]] graph around a note — outbound and inbound |
chat | multi-turn Q&A loop with conversation memory (/clear, /exit) |
watch | keep the index current by polling sources (interval in [watch]) |
ask "…" --rewrite | LLM-rewrite the query (keyword + cross-language variants) before retrieval |
feedback good|bad | rate the chunks used in the last ask; bad-rated chunks sink in future results |
wiki --suggest | suggest wiki-worthy topics that don't have a page yet |
bench cases.jsonl | retrieval benchmark: hit@k, vector-only vs hybrid |
sync push|pull | sync memories/wiki across machines via git ([sync] remote) |
serve-http | HTTP REST API (search/ask/remember/stats) with Bearer auth |
graph build / graph show ENTITY | knowledge graph over memories/wiki (LLM-extracted triples in graph.json) |
stats | what's in the index: chunks per source, models, retrieval settings |
doctor | health check: config, source dirs, embed/LLM endpoints, store (exit code 1 on failure — CI-friendly) |
python mcp_server.py | MCP server over stdio (see below) |
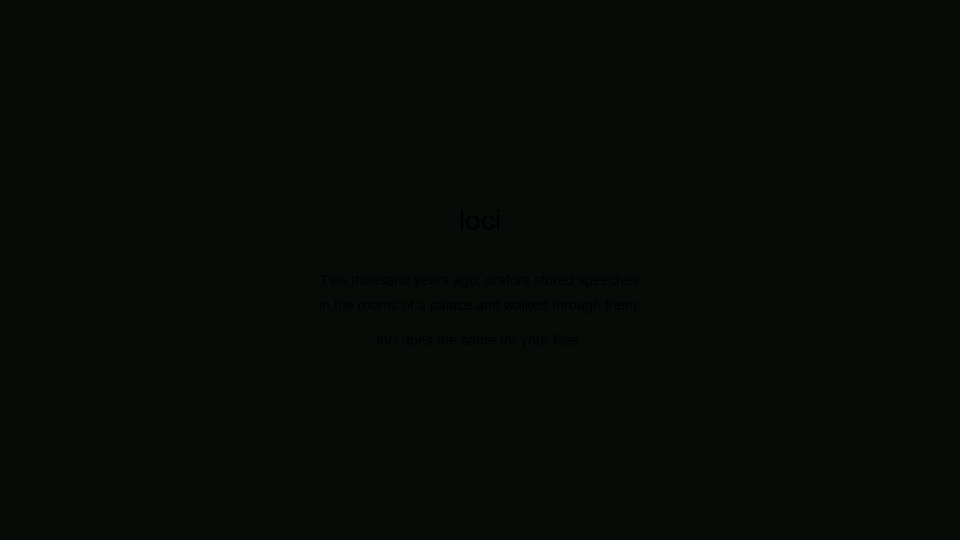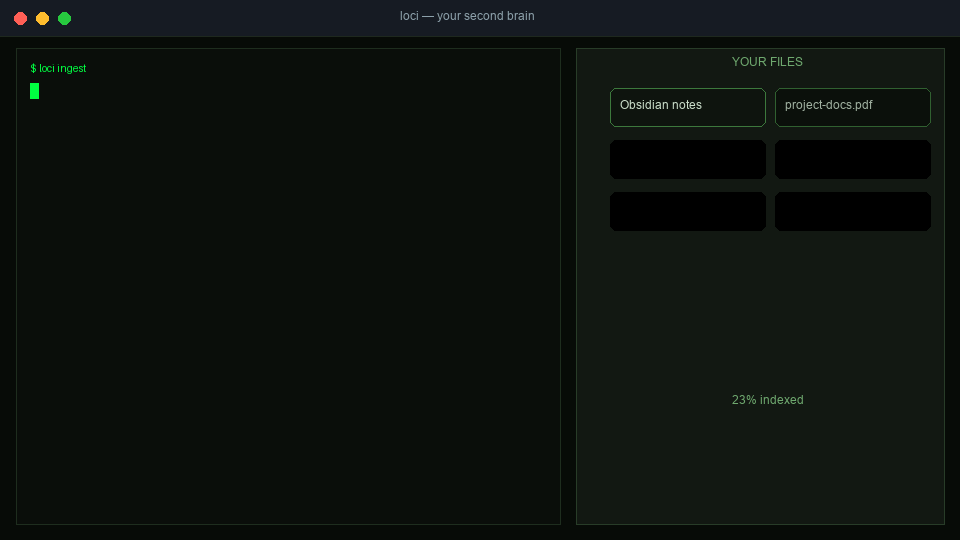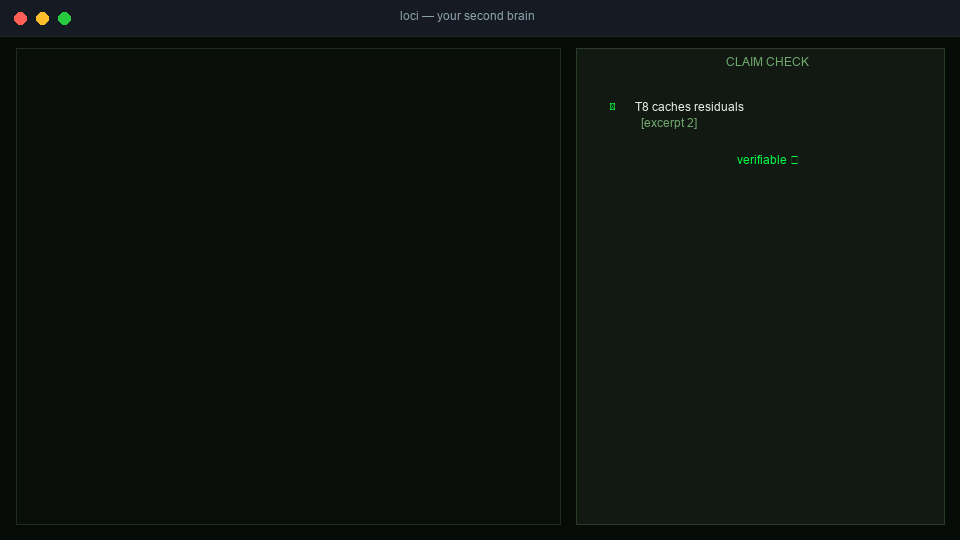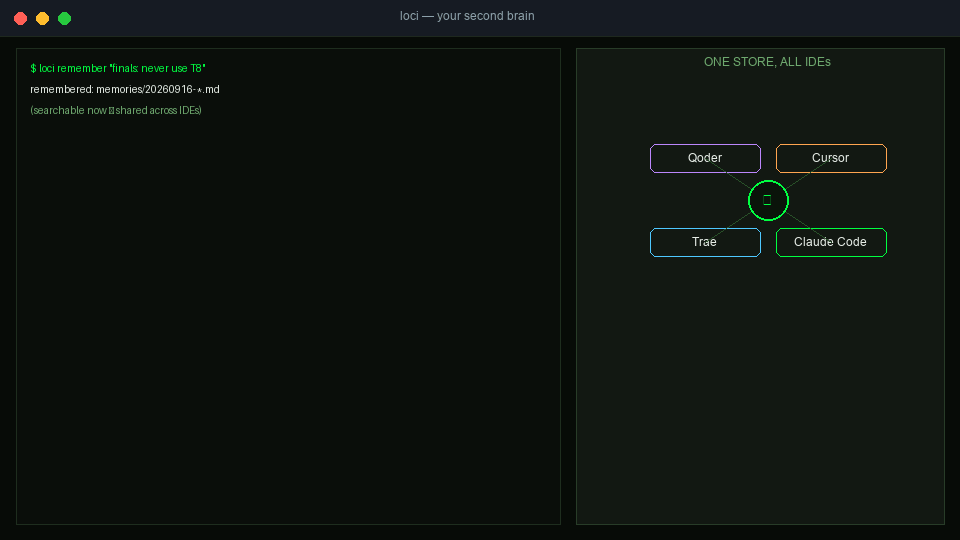
One memory, every IDE
Because every MCP host mounts the same loci server (same config.toml, same
index), memory written from one tool is recalled from every other:
Then, from any of them: "remember that the staging password rotates on
Mondays" → brain_remember → later, from a different IDE:
"when does the staging password rotate?" → answered, with the memory cited.
Memories live as plain markdown in the memories directory (git-friendly, no
lock-in) and are tagged memory, so loci search --tag memory scopes to them.
Cross-IDE tip: the default
store/memoriespaths are relative to the directory loci is launched from. If your IDEs start in different project folders, point both at one absolute location inconfig.toml— e.g.store.path = "~/.loci/store"andmemories.path = "~/.loci/memories"— and every IDE shares the exact same memory store.
Ecosystem
- loci-dsh — visual plugin for
DeepSeek Harness: search,
ask, quick-capture memories and watch index stats from a sidebar in the dsh
web UI, talking to
loci serve-httpover local REST.
Mount it in any MCP host
Add to claude_desktop_config.json (Claude Desktop) or your MCP client's
config:
The server exposes three tools (zero dependencies beyond the core):
| Tool | Purpose |
|---|---|
brain_search(query, k?, tag?, in?) | ranked excerpts with breadcrumbs |
brain_ask(question, verify?) | grounded answer with citations; verify=true adds a claim-by-claim audit |
brain_links(note) | outbound/inbound [[wikilink]] graph around a note |
brain_stats() | index overview (chunks per source) |
brain_graph(entity?) | knowledge-graph relations for an entity (omit for hub entities) |
brain_remember(text, title?, tags?) | write a memory — durable, shared across sessions and IDEs |
brain_forget(query) | soft-delete matching memories (they go to a .trash folder) |
brain_wiki(topic) | memory consolidation — distill the index into a curated wiki page about a topic |
brain_ingest(force?) | incremental re-index |
Beyond tools, the server speaks the full protocol:
- Resources —
resources/listexposesbrain://statsplus onebrain://note/…resource per indexed file (raw markdown viaresources/read) - Prompts — three ready-made templates:
brain-briefing,study-plan,contradiction-check; hosts render them with your topic pre-filled
Fully offline with Ollama
The index is local by design — and the embedding/chat calls can be too. Any OpenAI-compatible server works; Ollama is verified end-to-end:
With this config, ingest / search / ask make zero cloud calls.
Swap in a bigger local chat model for better answers — the pipeline is
model-agnostic.
Configuration
| Key | Meaning |
|---|---|
[llm] | base_url / api_key / model — any OpenAI-compatible endpoint |
[embed] | same; the model must be an embedding model (e.g. embedding-3) |
[[sources]] | document directories, scanned recursively for .md / .txt / .html / .org (plus .pdf/.docx/images with the matching extras) |
[[sources]] chunk_size / chunk_overlap | optional per-directory chunking override — wins over the global [chunk] block |
[chunk] | chunking params (default 800 chars / 100 overlap) |
[top_k] | number of hits per search (default 5) |
[retrieval] | hybrid (vector+BM25 fusion, default on), rrf_k, rerank (LLM reranking, default off) |
[watch] | poll interval seconds |
API keys can also come from the environment variables BRAIN_LLM_API_KEY /
BRAIN_EMBED_API_KEY (these override the config file).
Development
See CONTRIBUTING.md for the ground rules (no frameworks, tests stay offline, citations are sacred).
Design decisions
- ~300 lines of core, no LangChain — every stage is readable, hackable, and learnable. The whole engine fits in one sitting.
- MCP-first — the agent ecosystem is the UI layer. No web app to maintain.
- Hybrid retrieval on by default — vector search fused with a native ~60-line BM25 (CJK-aware tokenizer) via Reciprocal Rank Fusion.
- Citations always, with breadcrumbs —
path > section, so claims are verifiable at a glance. - Robust, inspectable indexing — defensive loaders (skip what can't be
parsed, never hang), content-hash incrementality, real pruning,
statsanddoctorso the index is never a black box. - Tiny notes stay searchable — no minimum-chunk filter; a one-line note is still indexed (a lesson from watching other tools drop or choke on them).
- Keys never in code —
config.toml(gitignored) or env vars.
Where it sits
| loci | AnythingLLM (65k★) | Khoj (37k★) | RAGFlow (90k★) | |
|---|---|---|---|---|
| Positioning | personal retrieval backend + MCP | all-in-one chat platform | self-hosted AI assistant | enterprise RAG engine |
| Footprint | 2 runtime deps, no Docker | desktop app / Docker | Django server + workers | Docker, DeepDoc models |
| UI | your terminal & your agents | built-in web/desktop | web + Obsidian/Emacs | web |
| MCP server | ✅ native | consumer | — | — |
| Hackable core | ✅ ~300 lines | ❌ | ❌ | ❌ |
| Multi-user | by design, no | ✅ | ✅ | ✅ |
(Full data and reasoning: competitive landscape study.)
Roadmap
See docs/roadmap.md — reranking, GraphRAG experiments, more loaders.
License
MIT