Infranodus MCP Server Infranodus vs Openevidence MCP
A side-by-side look at the Infranodus MCP Server Infranodus and Openevidence MCP MCP servers: transport, auth, tools, quality signals, and the config to install either one in Claude, Cursor, Windsurf or VS Code.
Verdict: choose Infranodus MCP Server Infranodus for research work as a local process; choose Openevidence MCP for research as a local process. You can also run both side by side in one mcpServers block.
Which MCP server should you choose?
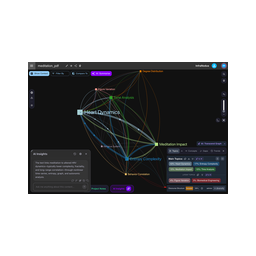 Choose Infranodus MCP Server Infranodus when
- You need dedicated capabilities in the Research domain.
- You prefer a local stdio subprocess transport.
- Its auth model fits you: API key required.
- You want tools like
generate_knowledge_graph, create_knowledge_graph, generate_ontology_graph.
 Choose Openevidence MCP when
- You need dedicated capabilities in the Research domain.
- You prefer a local stdio subprocess transport.
- You want tools like
oe_auth_status, oe_history_list, oe_article_get.
Feature & specification comparison
Rows where the two servers differ are marked.
| Spec | ||
|---|---|---|
| Category | Research | Research |
| Quality signal | 69/100 · Great | 65/100 · Great |
| Install command | Confirmed | Confirmed |
| Transport | Local subprocess (stdio) | Local subprocess (stdio) |
| Auth | API key required | Not declared |
| Pricing | Not declared | Not declared |
| Required env vars | None listed | None listed |
| Verified owner | Community listing | Community listing |
| GitHub stars | 104 | 45 |
| Directory activity | 4 views 0 installs 0 upvotes | 1 views 0 installs 0 upvotes |
| Tools | 40 | 5 |
| Full listing | View Infranodus MCP Server Infranodus | View Openevidence MCP |
Tools & capabilities
Infranodus MCP Server Infranodus tools 40
generate_knowledge_graphGenerate a knowledge graph with main topics, topical clusters, concepts, concepts (nodes) relations (edges) and structural gaps. Only use when explicitly asked to analyze a text or generate a knowledge graph. Do not use for short clarifying questions that you already have an answer to from the context of the conversation.create_knowledge_graphCreate a knowledge graph in InfraNodus from text or from a URL, save it, and provide its name and a link to it for future use.generate_ontology_graphUse AI to generate a reasoning ontology knowledge graph (entities and the relations between them) and optionally save it as a InfraNodus graph. Three sources, provide exactly one: prompt (a topic — one AI call), text (a long document or a structural digest of a project, chunked server-side), or sourceGraphName (an existing graph — e.g. a fully ingested repo, vault, or corpus — whose statements are read back, chunked, and condensed into an ontology). Set ontologyMode: 'codebase' for software projects, or 'procedural' to write a DIGEST of how the project works (prose statements with [[wikilinks]], not relation triples) from an already-uploaded graph — save it as <repo|vault>-<project>-digest for optimize_knowledge_base. Use to get a rich overview, a reasoning map of a topic, or a condensed 'how it fits together' graph of a large corpus.memory_add_relationsAdd relations to the InfraNodus memory from text, save it, and provide its name and a link to it for future use.memory_get_relationsProvide a list of relations from the InfraNodus memory for a given concept or entityanalyze_existing_graph_by_nameExtract and analyze the content of an existing InfraNodus graph from your account.analyze_textExtract and analyze a graph from text, URL, YouTube video transcript, or an existing InfraNodus graph.generate_content_gapsGenerate content gaps from text, URL, or an existing graph using knowledge graph analysis.generate_topical_clustersGenerate topics and clusters of keywords from text, URL, or an existing graph using knowledge graph analysis.generate_research_questionsAnalyze text or an existing graph and generate innovative research questions based on the content gaps identified between the topical clusters. Provide either text, url, or graphName. Can be used to improve the text and the discourse it relates togenerate_research_ideasAnalyze text or an existing graph and generate innovative research ideas based on the content gaps identified between the topical clusters inside the text that can be used to improve the text and the discourse it relates to.generate_responses_from_graphUse text, URL, or an existing InfraNodus knowledge graph and generate responses and expert advice based on a prompt provided.- +28 more on the listing page
Openevidence MCP tools 5
oe_auth_statusCheck whether the saved OpenEvidence browser session is authenticated. Use before history/article/ask tools when auth state is unknown. Returns authenticated=true/false and basic account metadata when available. Requires the local browser profile created by npm run login:session. No side effects. Can fail if the profile is missing, expired, or network access fails.oe_history_listList prior OpenEvidence articles from the authenticated account. Use only when the user asks to inspect prior OpenEvidence work or needs an article_id. Inputs: limit, offset, optional search, optional include_raw=false. Returns a privacy-reduced list by default; include_raw=true may expose private prior questions and must be used only with explicit user intent. Requires authenticated session. No side effects.oe_article_getFetch an OpenEvidence article by article_id. Use after history lookup or oe_ask returns an article ID. Inputs: article_id UUID, optional include_raw=false. Returns normalized status, question, and answer fields by default. include_raw=true may expose private thread context and must be used only with explicit user intent. Requires authenticated session. No side effects.oe_article_waitWait for an existing OpenEvidence article_id to finish, then return normalized fields. Use after oe_ask with wait_for_completion=false, especially for long research questions that may exceed MCP host timeouts. Inputs: article_id UUID, optional timeout_sec, poll_interval_ms, and include_raw=false. include_raw=true may expose private thread context and must be used only with explicit user intent. Requires authenticated session. No side effects.oe_askCreate an OpenEvidence research question, not medical advice or patient-specific diagnosis. For long questions, prefer wait_for_completion=false and then call oe_article_wait with the returned article_id. Use original_article_id only for true follow-up continuity; omit it for fresh questions. Returns privacy-reduced created article data and optionally normalized completed fields. Side effect: creates a question/article in the user's OpenEvidence account through the local browser profile.
Ready-to-paste client configs
Paste either block (or both) into your client config, e.g. claude_desktop_config.json or ~/.cursor/mcp.json. We only show a config when the install command is confirmed.
Infranodus MCP Server Infranodus
{
  "mcpServers": {
    "infranodus-mcp-server-infranodus": {
      "command": "npx",
      "args": [
        "-y",
        "infranodus-mcp-server"
      ]
    }
  }
}
Openevidence MCP
{
  "mcpServers": {
    "openevidence-mcp": {
      "command": "npx",
      "args": [
        "-y",
        "openevidence-mcp"
      ]
    }
  }
}
Frequently asked questions
Infranodus MCP Server Infranodus is categorized under Research and uses a local stdio subprocess. Openevidence MCP belongs to Research and uses a local stdio subprocess. Pick Infranodus MCP Server Infranodus for research work and Openevidence MCP for research.
Copy the mcpServers block from the config section on this page into your client's config (for example claude_desktop_config.json or ~/.cursor/mcp.json), then fully restart the client.
Infranodus MCP Server Infranodus has no declared pricing — check the project's own site. Auth: api key required. Openevidence MCP has no declared pricing — check the project's own site. If a server needs environment variables such as API keys, define them under the env key in your client's MCP config.
Yes. MCP clients support multiple servers: add infranodus-mcp-server-infranodus and openevidence-mcp as separate keys in the same mcpServers object, and your assistant will call tools from either one.
On AllMCPs, Infranodus MCP Server Infranodus has a quality signal of 69/100 (Great) with 4 views, 0 installs and 104 GitHub stars. Openevidence MCP has 65/100 (Great) with 1 views, 0 installs and 45 GitHub stars.