Self-hosted homelab dashboard with a built-in read-only MCP server (hosts, Docker, GPU, services).
Quick Install
Automated & IDE SetupCopy the AI prompt to install this server into Claude Code, Cursor, or another agent — or use 1-click editor setup below.
Manual Client & Custom JSON ConfigExpand JSON ▾
Client Config & Setup
Remote HTTPChoose your client or environment
Target File:
💡 Paste the JSON block into your client's configuration file under mcpServers, then restart the application.
Documentation Overview
 HomeLab Monitor


One page for your whole home lab & AI rig — GPU truth (any vendor), tokens/sec, power cost by the hour, uptime, training runs, containers, disks. No agents, no separate metrics stack, no cloud.
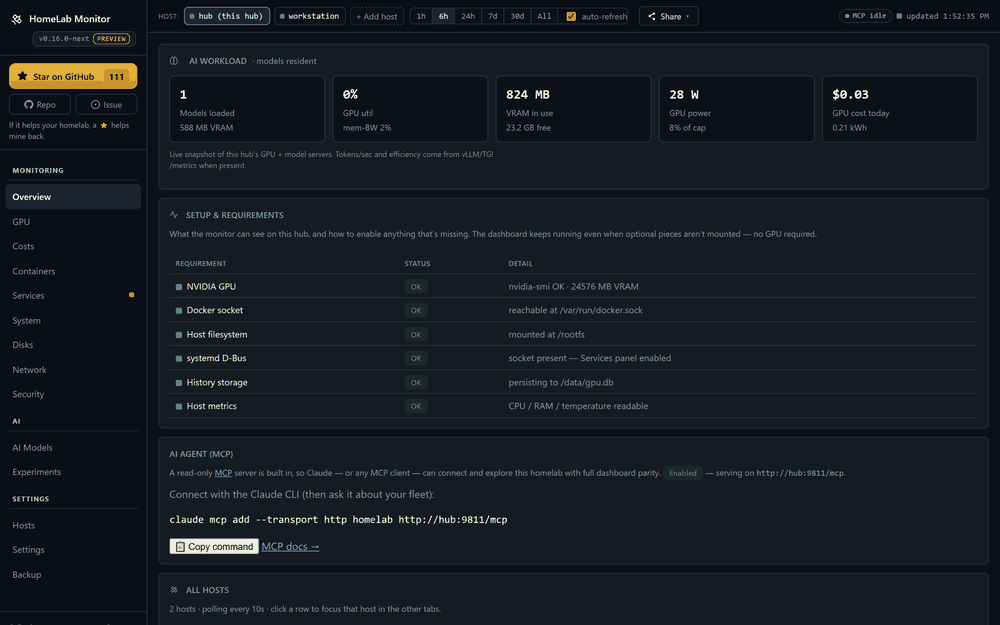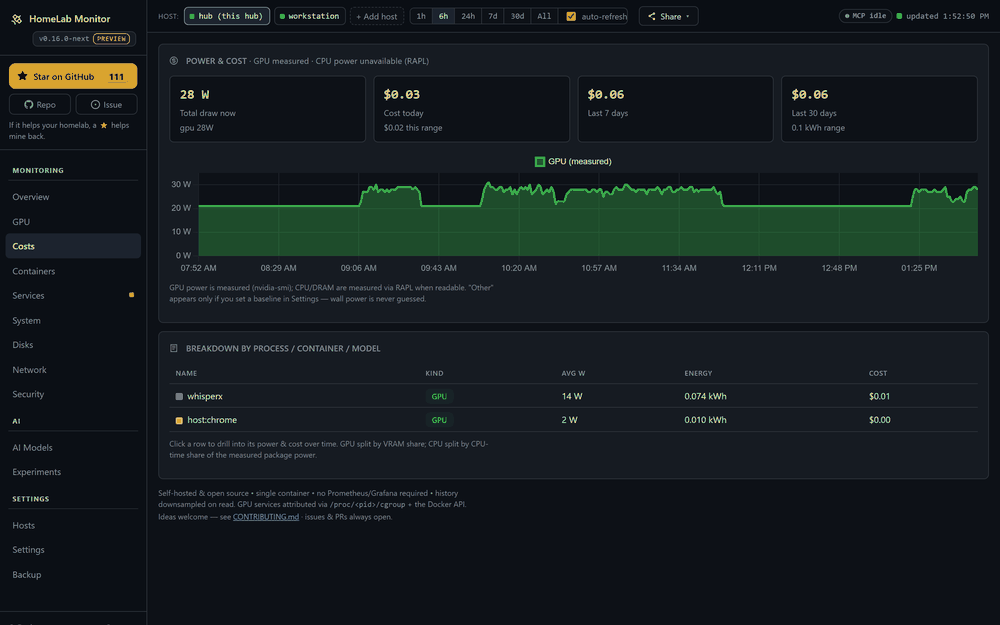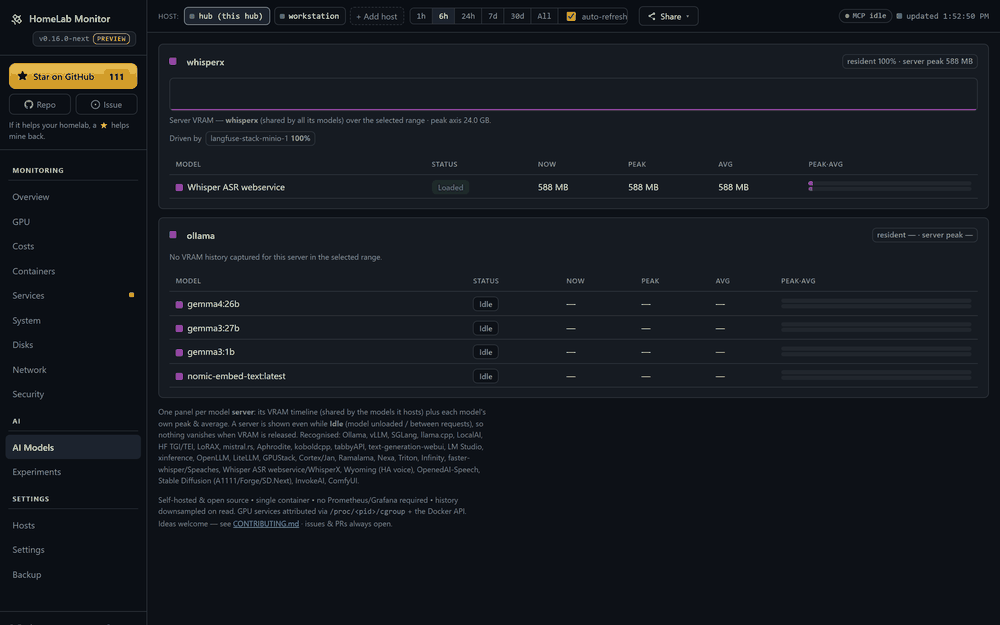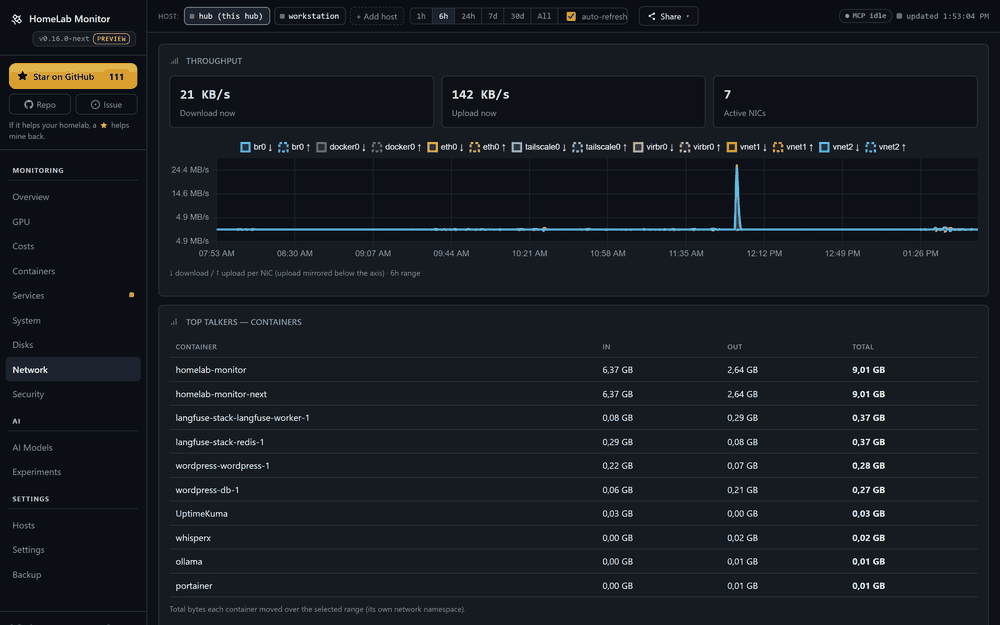
Your home lab grew into a couple of machines, a Pi, and a GPU that's mysteriously always busy — and lately it's running models too. HomeLab Monitor gives you one self-hosted page that answers the real questions: what's that GPU actually doing, which model is holding it, what's it costing you to run, which container is eating RAM, what's filling your disks, and is anything down — across every box over SSH: Linux, a Pi, even Windows. Readable from your phone over the VPN.
Get started
Open http://<your-host>:9800 and you're done. Full options (from source, GPU toolkit, Windows/WSL2) → Install docs.
🆕 What's new — every release is written up in full, with the reasoning behind it: latest release · changelog. The dashboard also shows you the notes once, in-app, after it updates itself.
What you get
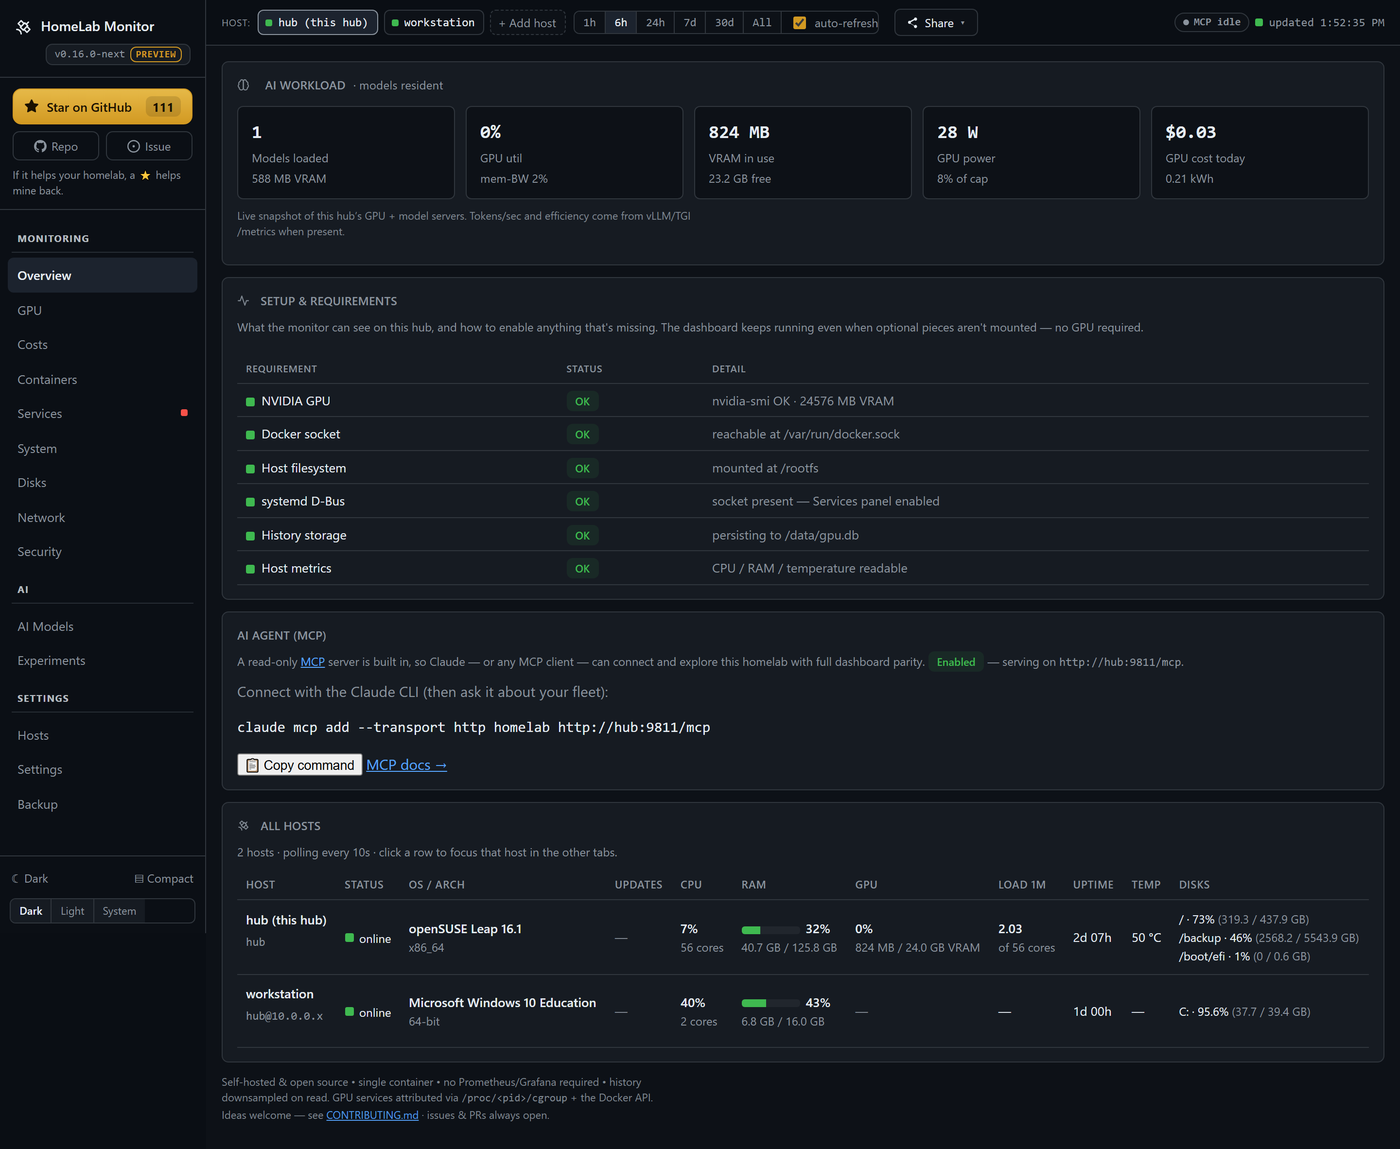
One page, every box, the questions you actually have. The classics are all here — and a whole AI cockpit builds on top of them.
A front page for your lab — and a wall screen. The Overview opens with a Launchpad: the apps you actually open, as tiles with their real logos, pinned straight from a container row with the address already filled in, grouped and dragged into the order you want. Pins live on the hub, not in one browser — pin it on the laptop and it's there on the phone and on the wall. The whole board fits the screen: it measures its own overrun after every paint and gives ground in order — trimming lists, tightening the fleet rail, folding pins behind a +N more — rather than clipping a card in half or running past the fold. Verified from 4K down to 1366×768. And ⛶ Display (or /?display=1, all a dedicated kiosk box needs) drops every scrap of chrome and fills the monitor: you choose which panels the wall shows, and on Chromium-based browsers it opens full-screen on whichever screen you point it at.
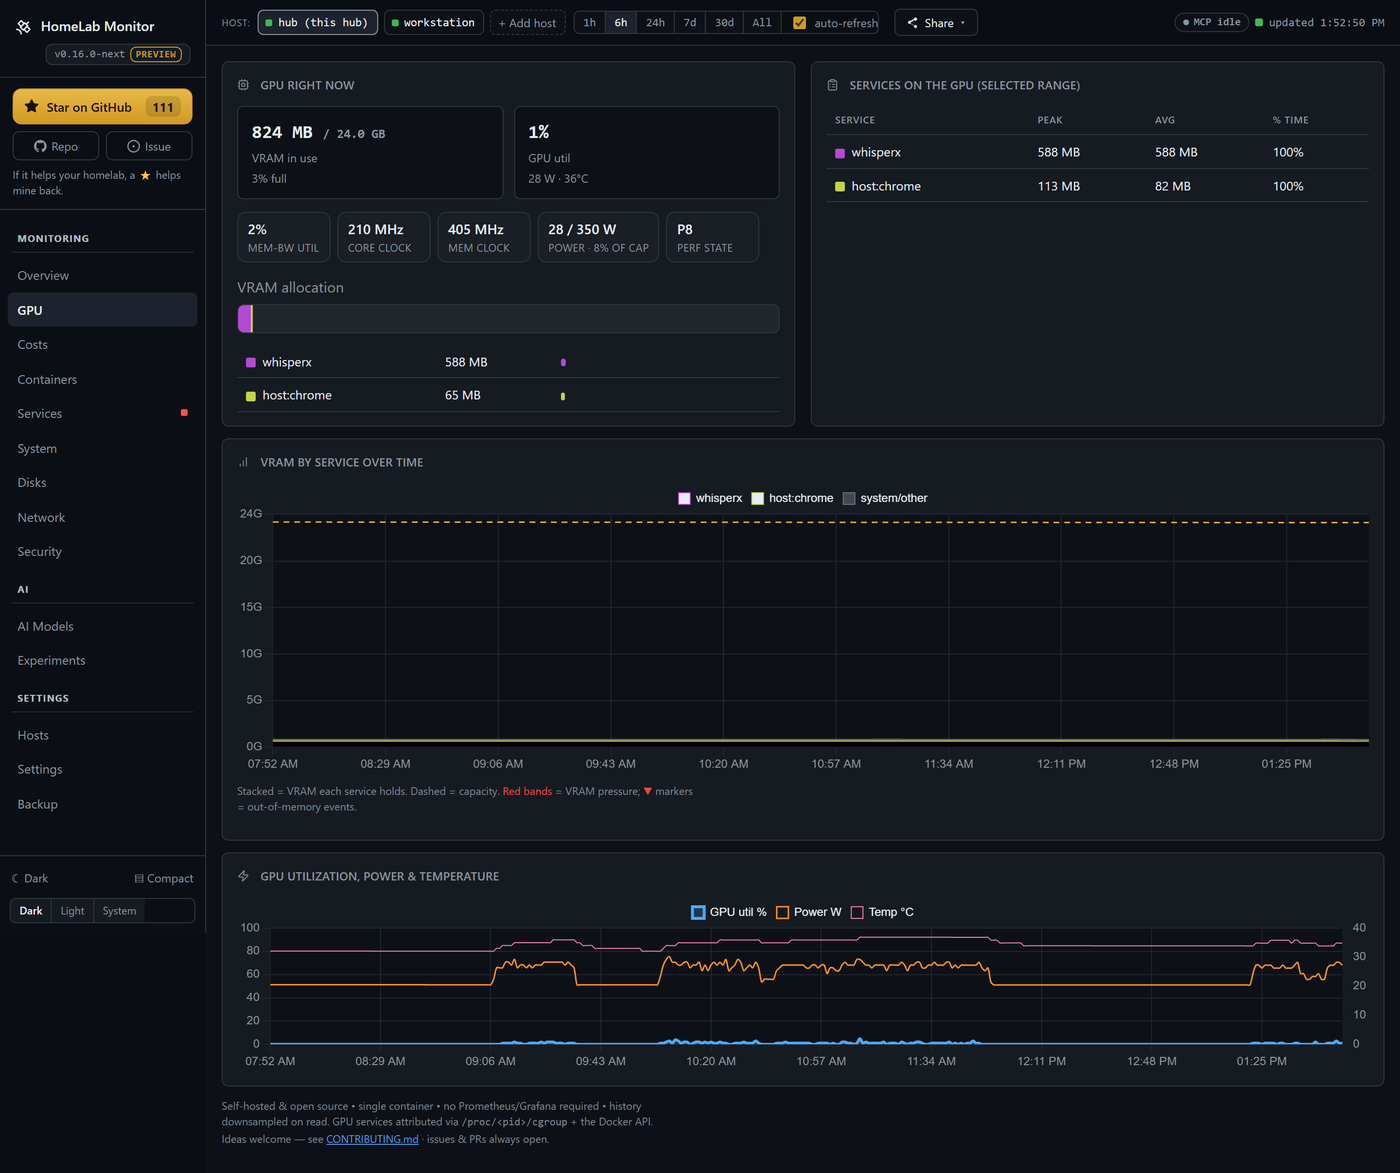
Your GPU, demystified — and the same tab on every box. A card pinned at "100% util" can still be throttling, memory-bandwidth-bound, or quietly drooping its clocks. The GPU tab decodes nvidia-smi's throttle reasons, and shows memory-bandwidth util, core/mem clocks, power-vs-limit, p-state — and fan speed — for every machine in the fleet, not just the one running the container. Multi-GPU boxes get one panel per card on a shared scale per metric, so a taller temperature line really is a hotter card; thermal-throttle windows are shaded right on the sparkline. You can see which card a service is sitting on (a 3×3090 box shows a model's 63 GB split 22.5 / 22.1 / 18.8 across the cards, not one pooled number), what each service cost in energy, and get alerted when a card throttles, overheats or loses a fan — sustained, per card, with per-host thresholds, because a box running a deliberately lowered power limit is supposed to sit at its cap. And it's no longer NVIDIA-only: AMD GPUs are read on Linux straight from the kernel's amdgpu interface (no ROCm), and AMD and Intel GPUs on Windows hosts — so your card shows up with its name, utilisation and VRAM, no vendor tools required. Anything a driver won't report says so, instead of drawing a confident zero.
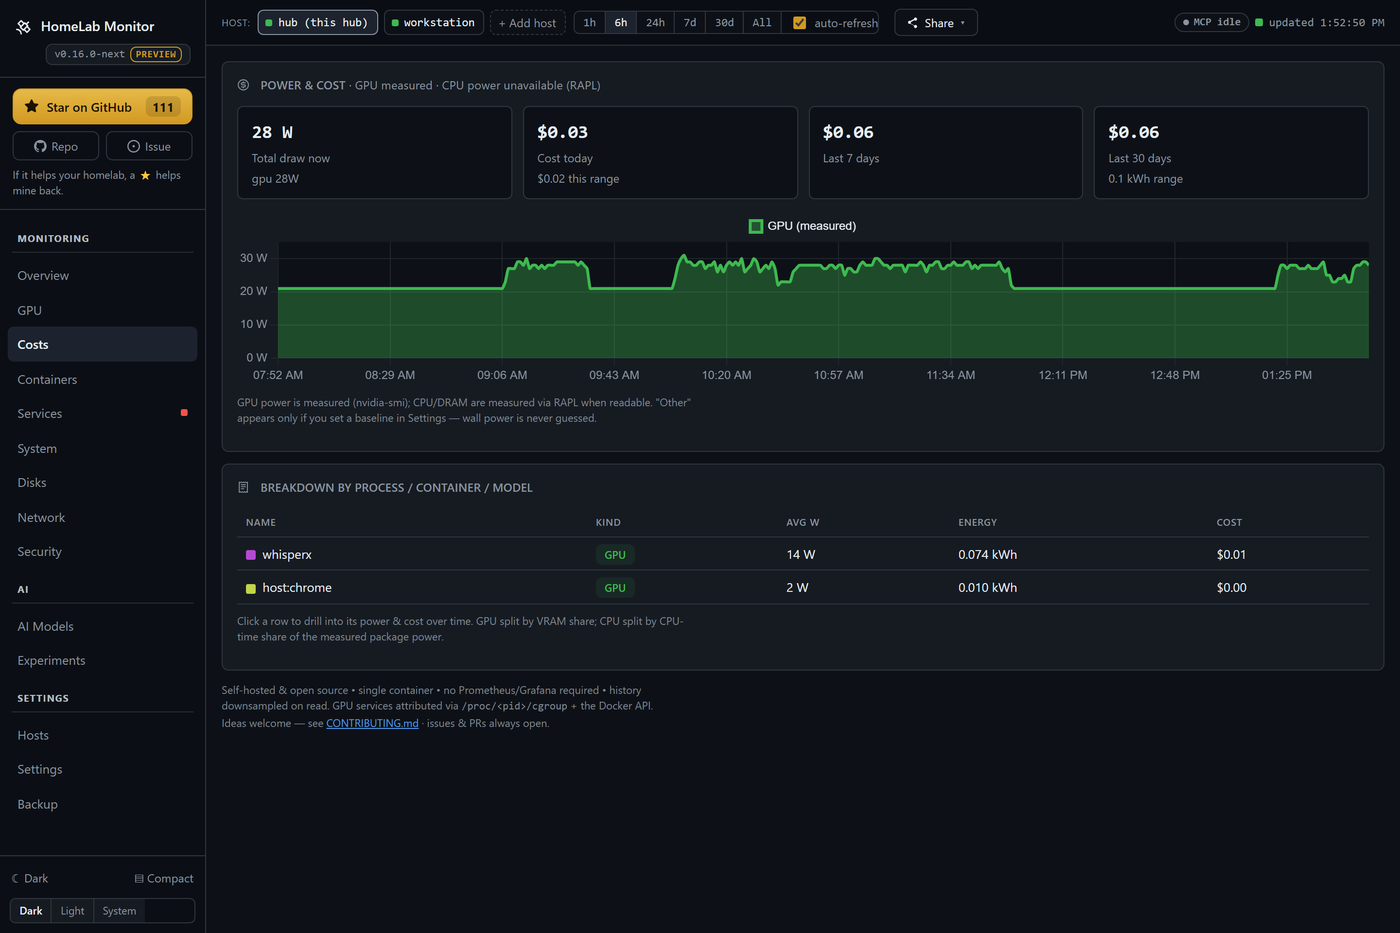
What it costs — down to the process. Power becomes money: per machine, then per component (GPU measured via nvidia-smi, CPU/DRAM via RAPL), then per process, container or model — click any row to see what it drew and what it cost over any window. Day & night tariffs (Economy 7, Heures Creuses, …), or just pick your country for a sensible estimate. Every watt is measured or a baseline you set; wall power is never guessed. And a busy-hours heatmap turns months of samples into one picture of when your lab costs you money — a 7×24 day-of-week × hour grid that shows which hour of the week is priciest at a glance.
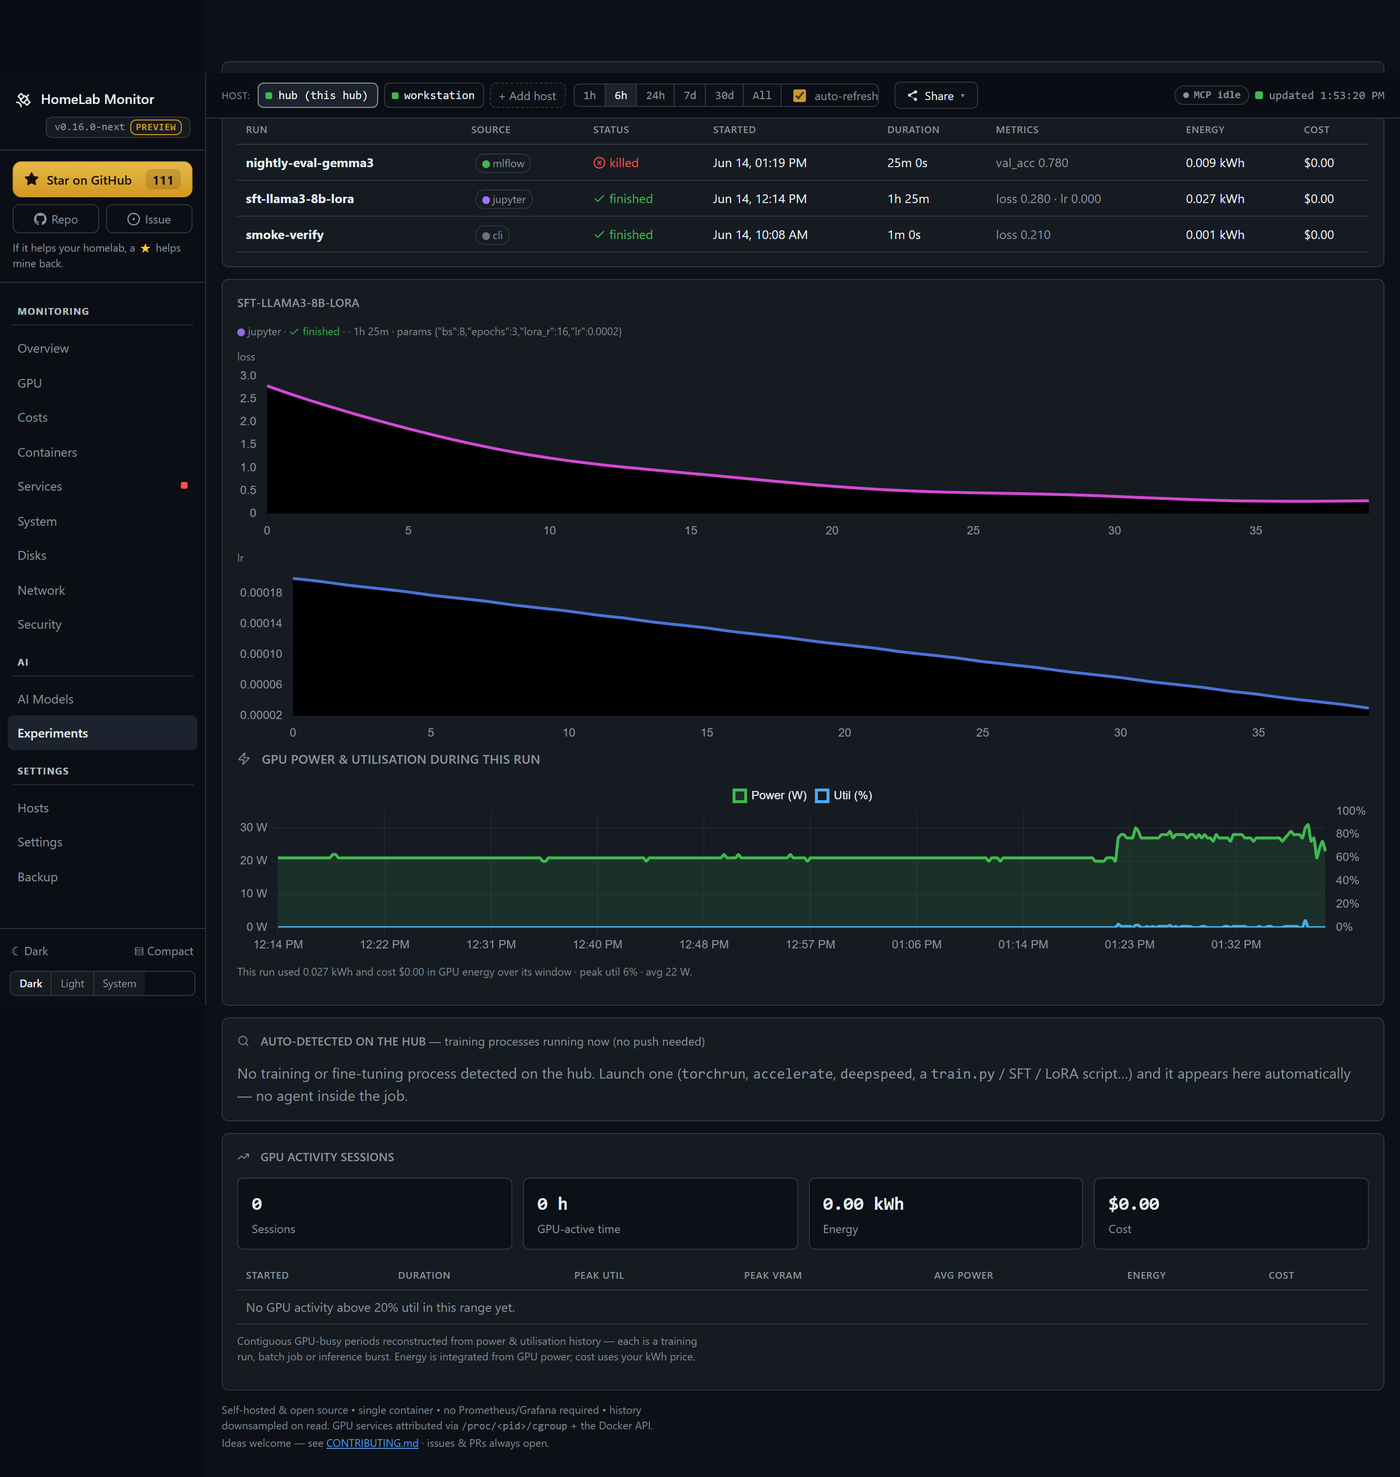
Your training runs, priced. Push a run from Jupyter, Colab or Kaggle with a one-file client (or mirror it from MLflow), and it comes back with the loss curve and the real GPU energy it burned, on the same timeline. Create, name, expire and revoke API keys yourself.
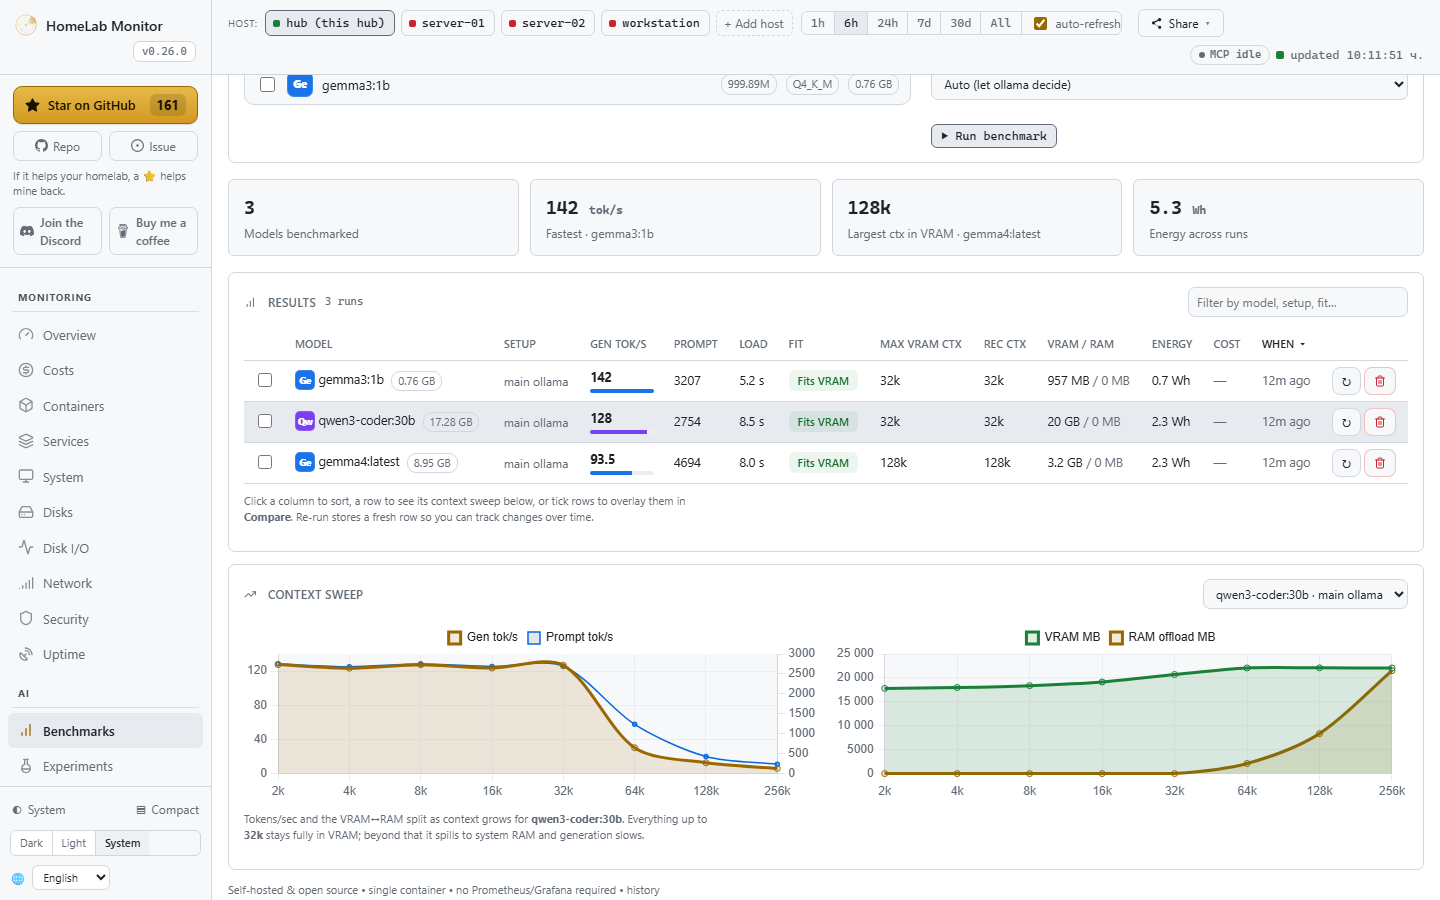
"Will it fit?" — measured, not guessed. The Benchmark Lab loads each of your local ollama models and sweeps a ladder of context sizes on your actual cards, recording generation & prompt tokens/sec, load time, how much spilled from VRAM into system RAM, and the largest context that still fits fully in VRAM — the cap worth setting. Pick which GPU(s) to test (via a throwaway pinned ollama container — your main one is never touched), overlay stored runs to compare cards, and every run comes back with the energy it burned and what it cost. Results are stored: benchmark once, re-run only when something changes.
And the rest of the lab, the way it always was:
- Containers, honestly — health plus RAM and VRAM in separate columns (real resident RAM, not page cache), and click one to tail its logs in a side drawer. Every box in the fleet gets the same controls — logs, start/stop/restart, restart policy, pin — over the same SSH connection the probe already uses, and the whole tab works on a phone.
- systemd services — local or remote, your own units highlighted, failures first.
- WizTree-style disk treemaps — on any box in the fleet. Click into the folders filling a disk on the hub or on any Linux host you've added; a remote is scanned over the same SSH connection everything else uses, so there's still nothing to install on it. Plus network I/O with per-container top talkers and a mini-htop for who's eating CPU and RAM.
- It moves like a live dashboard. Utilisation, RAM, temperature and power update every couple of seconds over a push stream instead of a fixed poll — and it does that while making fewer requests than before, because the expensive history query is fetched only as often as its own chart buckets can change, and a tab you're not looking at stops costing anything at all. Sampling and storage cadence are untouched, so history stays exactly as dense (and costs stay exactly as accurate) as they were.
- Multi-machine over SSH — paste one key per box; Linux, a Pi, even Windows. No agents, no installs. The GPU tab works per host too: a remote multi-GPU rig shows every card's VRAM, utilisation, power and temperature, and the processes holding the memory.
- Uptime monitoring, in the box — watch any HTTP endpoint or TCP port (your services, a NAS, a remote site) straight from the container: heartbeat strip, 24h/7d uptime %, latency, and smart per-check alerts — anti-flap confirm, recovery with downtime, and an optional slow-response warning. No extra uptime service to self-host — it's already in the box.
- Push alerts — Discord, ntfy.sh and Telegram, edge-triggered so they don't spam.
Full tab-by-tab tour → Features.
Multi-machine, in two sentences
Open the Hosts tab, paste the hub's auto-generated SSH key onto each remote, and the hub starts polling it — no agents, just SSH + Python 3 (PowerShell on Windows). The hub pipes a small self-contained probe over SSH; nothing persists on the remote. The same connection is what lets you open a remote's GPU cockpit and scan its disks from the hub — still with nothing installed on the far end.
Related MCP Servers
Adoption & maintenance
Factual signals from GitHub, npm, and our automated checks — not a rating.
GitHub stars
206
Stargazers on the source repository.
Last commit
3d ago
Most recent push to the default branch.
Directory activity
1 views
Config copies, upvotes, and views on AllMCPs.
Reviews
No reviews yet — be the first to share how this listing worked for you.
Frequently Asked Questions about HomeLab Monitor
AllMCPs Directory Badge
Showcase your server listing on GitHub or your project documentation. Embed this dynamic SVG badge to highlight official listing status and live engagement.
Badge Style:
Live Dynamic SVG Preview
Markdown (GitHub README)
[](https://allmcps.com/mcp/homelab-monitor)HTML Embed
<a href="https://allmcps.com/mcp/homelab-monitor"><img src="https://allmcps.com/api/badge/homelab-monitor?style=directory" alt="HomeLab Monitor on AllMCPs" /></a>Technical Specs & Signals
CategoryCloud Platforms
7/11 checks healthy over the last 46d
45Quality signal: Fair · 45/100How this signal is calculated ▾
Server availabilityNot measured
Not scored for repo-hosted servers — we can't reach the running server, only its GitHub page. Hosted MCP endpoints are health-checked live.
Verified ownership10/20
Documentation & tools16/30
Adoption & activity8/15
Community engagement0/10
A guidance signal from public completeness & health data — not a user rating. New listings start lower and rise as they add docs, get verified, and grow adoption. Signals we can't observe for a listing are skipped, not counted against it.
Own this project?
This directory is pre-filled from public sources. Claim via GitHub README, site badge, or DNS TXT to unlock edit access and the Official badge — proof is checked automatically, then reviewed by our team.
Free dofollow backlink: add your website and place the AllMCPs badge on it — no claim needed. We detect it automatically and keep it verified as long as the badge stays live.
Claim & get free dofollowShare & Embed
Add our SVG badge (dark/light directory styles) or embeddable widget to your site.