Groundwork README
The full upstream README, mirrored here for reference. Install config, tool schemas, adoption signals, and an original overview live on the Groundwork listing page.
Groundwork
Deployment-readiness harnesses for AI deployment patterns.
Redaction · evals from your real failures · a CI gate that fails fabrication


Website · Getting started · Examples · Roadmap · Contributing · Changelog
You have a prototype: your documents, a model, useful output. What you don't have is the apparatus that makes it responsible to ship — a privacy pre-step, an evaluation built from your own failures, and a gate that stops a quiet prompt tweak from deploying a system that fabricates. That apparatus usually requires an ML engineer. Groundwork scaffolds it instead.
Groundwork's units are deployment patterns, not products — think Terraform modules for trustworthy AI deployments. groundwork init <archetype> scaffolds the whole harness for a pattern:
| Archetype | The pattern | Status |
|---|---|---|
document-qa | documents → retrieval → grounded answers → human review | ✅ shipped |
extraction | documents → structured fields → schema validation → human review | ✅ shipped |
| research synthesis | questions → evidence → synthesis → human review | planned — see the roadmap |
Every check is deterministic: same inputs, same result, every time — no LLM judge, and no API key for the checks themselves.
Quick start — 60 seconds, no API key
The same loop for structured extraction:
That red build is the product: a fabricated figure, a guessed field, or a failed abstention becomes a CI failure, not a user complaint.
Ready for your own system?
How it works
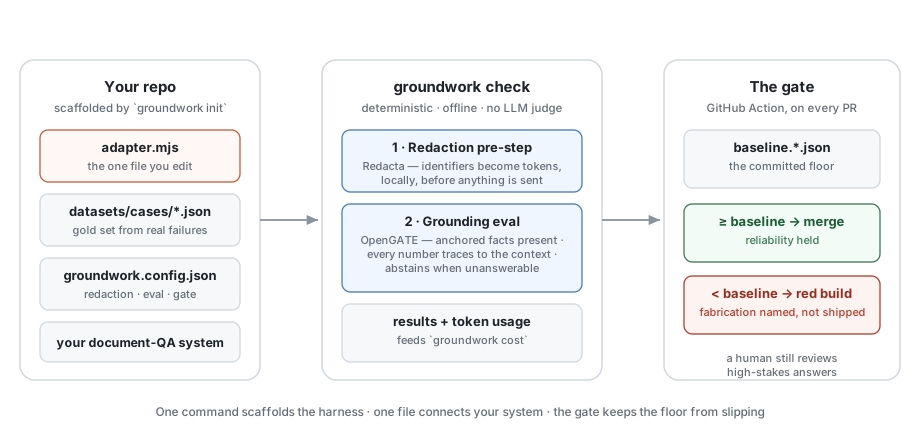
| You edit | Groundwork runs | The gate enforces |
|---|---|---|
adapter.mjs — one file: answer() for document QA, extract() for extraction | Redaction pre-step (Redacta) — identifiers become labelled tokens locally, before anything is sent | check --baseline freezes a good run as the floor |
datasets/cases/*.json — gold cases from real questions and real documents, labelled by hand | The archetype's eval (OpenGATE) — document QA: anchored facts · numbers trace to context · abstention. Extraction: schema validity · field accuracy vs gold · no fabricated fields | check --ci in the scaffolded GitHub Action fails any PR below it |
groundwork.config.json — archetype, redaction, eval, and gate settings | Cost profiling — measured token usage, savings in leverage order (caching → batching → trimming → routing) | A human still reviews high-stakes outputs — the gate is a floor, not a certification |
For extraction, one schema choice does most of the safety work: nullability is the abstention contract. A field the system must always find is non-nullable; a field the document may not state is nullable, and the system returns null for it — unknown → null, never guessed. A guessed value in a null-gold field fails by name: FABRICATED field "date_of_birth": document does not state it.
Examples
| Example | What it shows | Run |
|---|---|---|
demo/ | Document QA: the full loop on a tiny local system — and the gate catching fabrication by name. Zero network. | npm run demo / npm run demo:break |
demo-extraction/ | Structured extraction: schema validation, field accuracy, and the gate naming a guessed date of birth and a dropped required field. Zero network. | npm run demo:extraction / npm run demo:extraction:break |
examples/claude-doc-qa/ | A real Claude-backed system: answer-from-document-only prompting, prompt caching, key-gated evals, measured usage feeding groundwork cost — plus a mock API so the whole loop runs offline in CI. | npm run example:mock (offline) / npm run example:check (live) |
examples/claude-extraction/ | Claude filling a schema from fictional referral letters: unknown → null in the prompt contract, the schema as the cached prefix, and the gate catching a guessed date of birth — plus a mock API for offline CI. | npm run example:extraction:mock (offline) / npm run example:extraction:check (live) |
Commands
Two ways to learn it: docs/GETTING-STARTED.md is the reference walkthrough (about half an hour), and the course covers the same ground as checkpoint-driven lessons — including the sabotage test, where you deliberately break your own system to prove the gate catches it, and a lesson on the extraction archetype. The scaffolded playbook (GROUNDWORK.md) lives inside your repo, where your team will actually read it.
Use from Claude
The same checks ship as an MCP server (groundwork-mcp, stdio) so Claude Code, Cowork, or Claude Desktop can run them conversationally — check_readiness on a repo, check_answer_grounding on a single answer, check_extraction on a single record (no repo needed), scaffold_harness, cost_summary:
There's also an Agent Skill (skills/groundwork-readiness/) that teaches an agent to run the gate and report results honestly — including refusing to present a green check as a safety certification.
What Groundwork is not
Groundwork is a strong floor, not a guarantee. Deterministic checks catch the failures that can be caught deterministically; they cannot certify an AI system safe. For high-stakes outputs — anything touching health, money, legal standing, or safety — a human must review before the output reaches the person it affects. Extraction raises the stakes quietly: the record feeds decisions, so a wrong field is a wrong decision. The scaffolded playbook says this too, on purpose.
Project
- Status — two archetypes shipped (document QA, structured extraction) of a planned three. Depth before breadth: each pattern gets finished properly before the next starts. See the roadmap.
- Contributing — bug reports, gold-case patterns, and examples are especially welcome: CONTRIBUTING.md.
- Releases — tagged on GitHub, versions on npm, history in CHANGELOG.md.
- Built on — OpenGATE (evaluation) and Redacta (privacy), both open source.
Licence
MIT. Everything init scaffolds into your repo is MIT-0 — yours, no attribution needed.