Graphiti Local README
The full upstream README, mirrored here for reference. Install config, tool schemas, adoption signals, and an original overview live on the Graphiti Local listing page.
Graphiti Local
Local memory for your agents. You approve what they learn.
Retrieve project decisions through six read-only MCP tools or the kg CLI.
Proposed updates stay in a separate queue until a human approves and applies them.
Ollama handles local inference; embedded LadybugDB stores the graph. No Docker or
cloud API key is needed for the local setup.
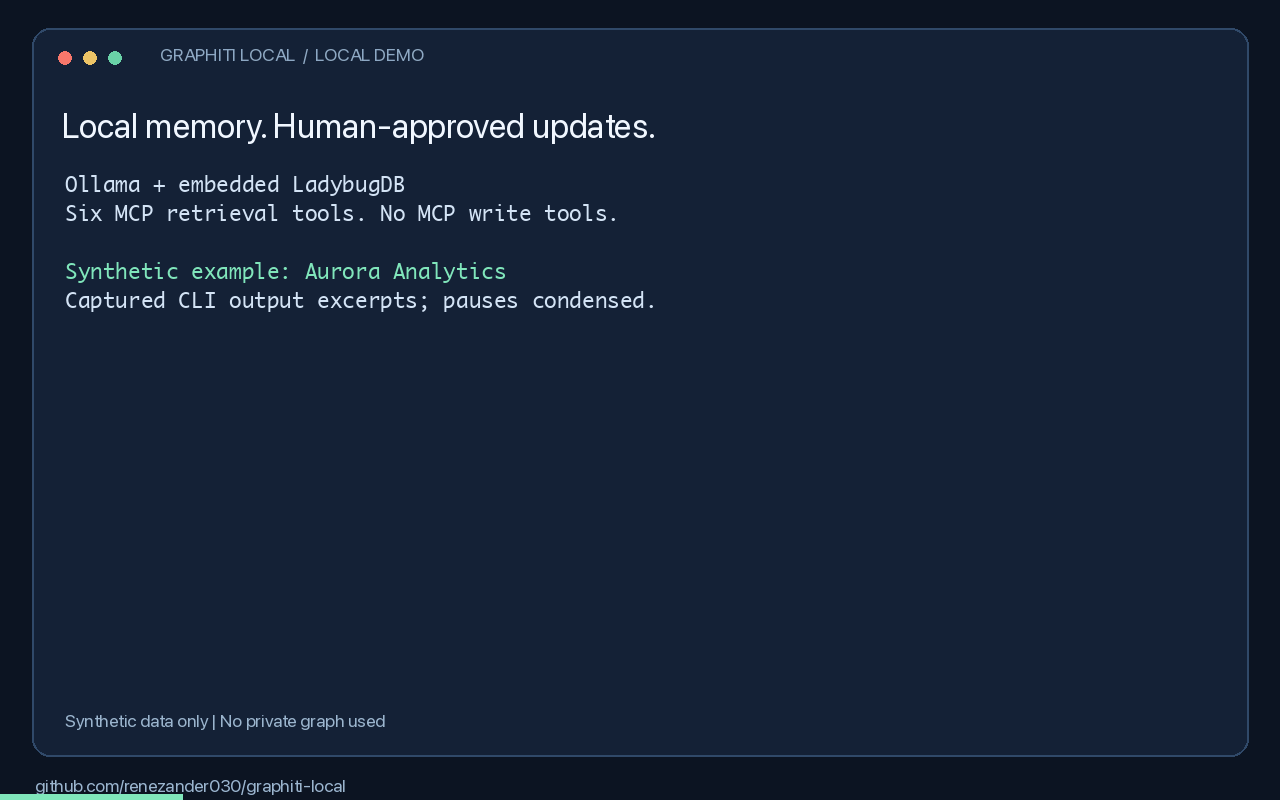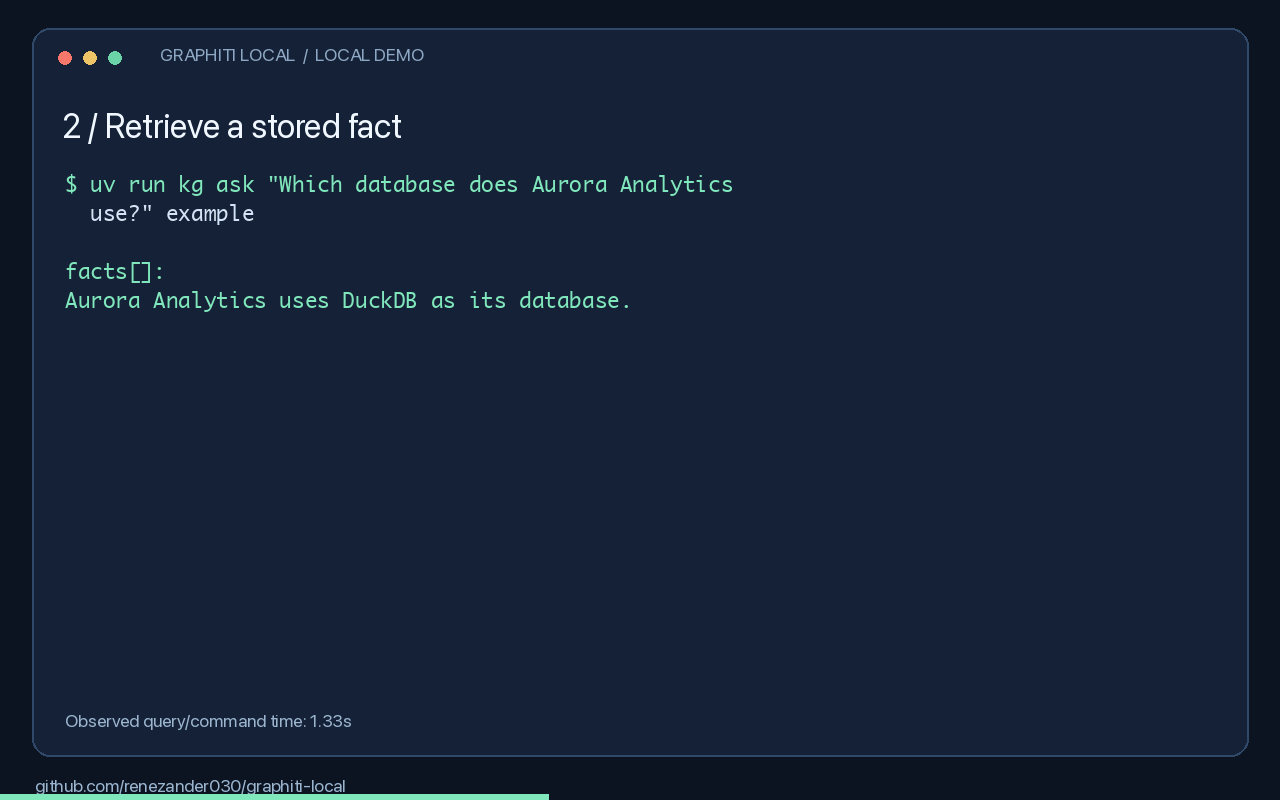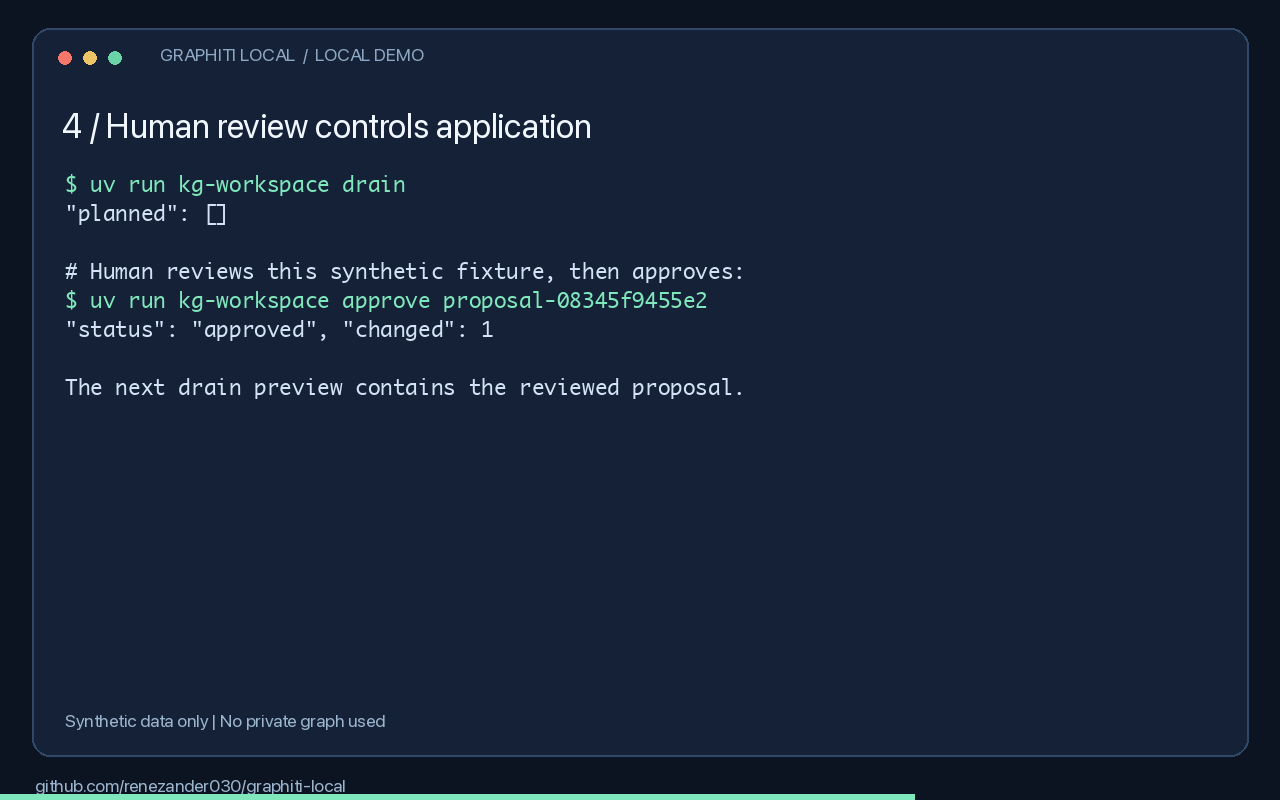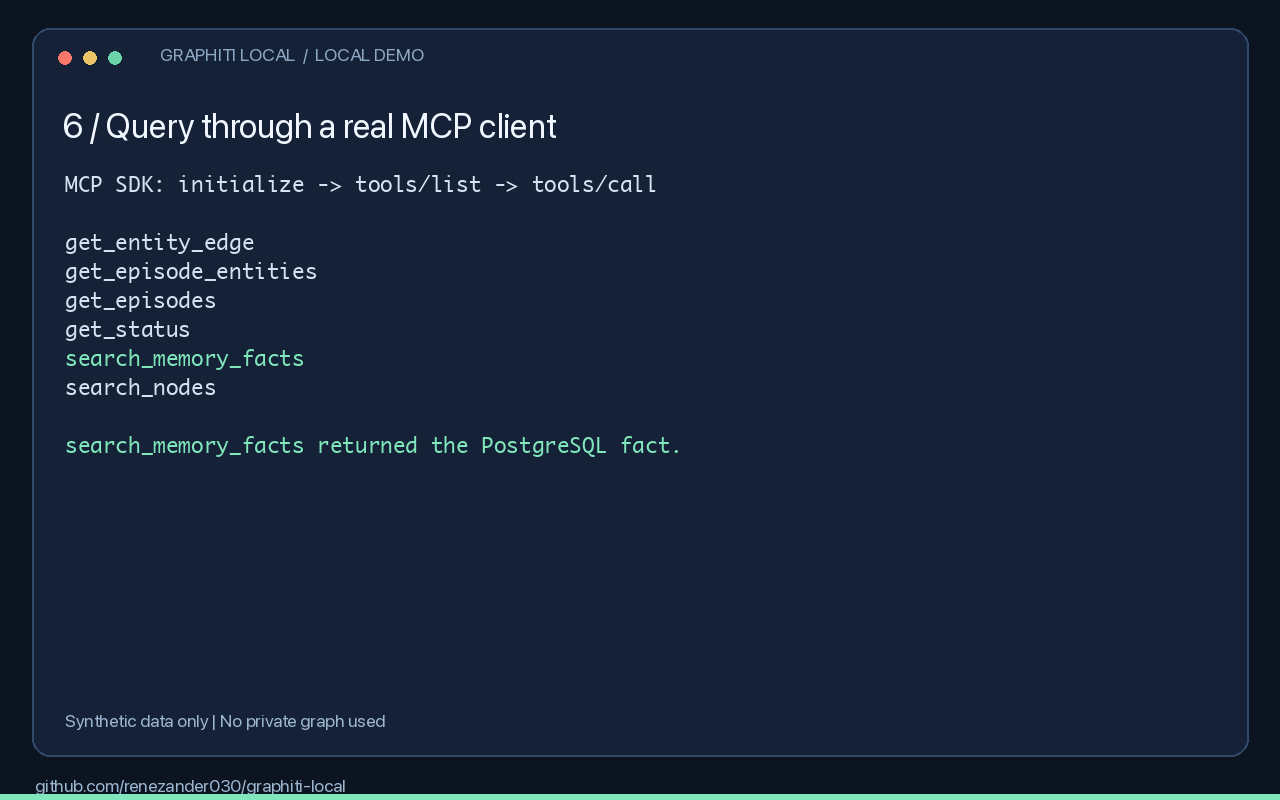
Captured output excerpts with pauses condensed. Measured results and limitations.
Try it in one command
Answers a question against a small synthetic graph shipped with the package. No Ollama, no model downloads, no database setup: retrieval runs on keywords alone, so nothing contacts a model. Ask your own question by passing it as an argument.
This is the read path only. Building a graph from your own text needs extraction, which needs a model, and that is the full setup below.
Try it locally
Install uv and Ollama, then start Ollama. Setup downloads need internet access. Run these commands in bash or zsh:
The synthetic example returns DuckDB. Follow the complete walkthrough to propose PostgreSQL, review and apply that update, and retrieve it from an MCP client. Model extraction can be wrong; inspect the returned facts and validity timestamps.
To review extraction before it touches the configured graph, run
kg-ingest INPUT --review-output review.jsonl, inspect the snapshot, and mark every
fact in the generated review.jsonl.review.jsonl file as accept, refuse, or
contested. The printed restore command refuses unresolved decisions and promotes a
checksum-sealed snapshot containing accepted facts only. Searches return current facts
by default; kg ask --history is the explicit historical view.
kg-ingest also accepts a Markdown/text file or a directory tree directly. Large
documents split at stable text boundaries. Transient writes retry with one stable
episode id; ingest-receipts.jsonl and ingest-failures.jsonl in the workspace show
exactly what landed and what still needs attention.
Multiple users on Ladybug
Give each user a group, and each group its own Ladybug file:
Each file is named by the SHA-256 of its group, so no group id can point outside the
directory. Reads, kg ask and the drain open only the file of the group they address;
a token granted alice never opens Bob's file. A read names one group, or the token's
single group is used. For a tenant boundary inside one database server, use FalkorDB
or Neo4j.
Is it a fit?
Use it for local agent memory with explicit human review. Skip it if you need agents to write through MCP or want a hosted service without local setup. FalkorDB and Neo4j are also supported.
- Setup and MCP configuration
- Commands, ingestion, backups, and deployment
- Privacy · Security · Container discovery
- Report a successful or blocked setup
If this helps your workflow, star the repository and share your setup result.
Maintained by René Zander, who builds context layers for AI agents on temporal knowledge graphs.
Independent community project built on Graphiti, not affiliated with or endorsed by Zep. Apache-2.0.