Source-grounded web research: search, extraction, verification, and browser automation.
Quick Install
Automated & IDE SetupCopy the AI prompt to install this server into Claude Code, Cursor, or another agent — or use 1-click editor setup below.
Not yet automatically verified
We haven't yet run this listing's install command through our automated sandbox check. This isn't a red flag — we're steadily working through the catalog.
Manual Client & Custom JSON ConfigExpand JSON ▾
Client Config & Setup
Choose your client or environment
Target File:
💡 Paste the JSON block into your client's configuration file under mcpServers, then restart the application.
Capabilities & Tool Schemas (35)
Inspect callable tools, capabilities, and parameters exposed to AI agents by Footnote MCP.
web_searchConfigured providers plus zero-key Bing, DuckDuckGo, Brave, and Wiby; Marginalia is explicit-only. Snippets are discovery only.
web_search_recentSearch restricted to a recency window (day/week/month/year).
web_deep_searchIteratively close evidence gaps across web/papers/encyclopedia/GitHub/archive sources; extracts tables/files, verifies individual facts, and returns an evidence ledger plus diagnostic funnel.
web_readFetch one URL, extract text, classify source quality, persist cache metadata.
papers_searchSearch Crossref and arXiv through one normalized, zero-key paper contract.
encyclopedia_searchSearch Wikipedia/Wikidata entities or run read-only Wikidata SPARQL.
Documentation Overview
footnote-mcp — web research MCP server with claim verification
Search, extract data, and verify every claim against the source page.
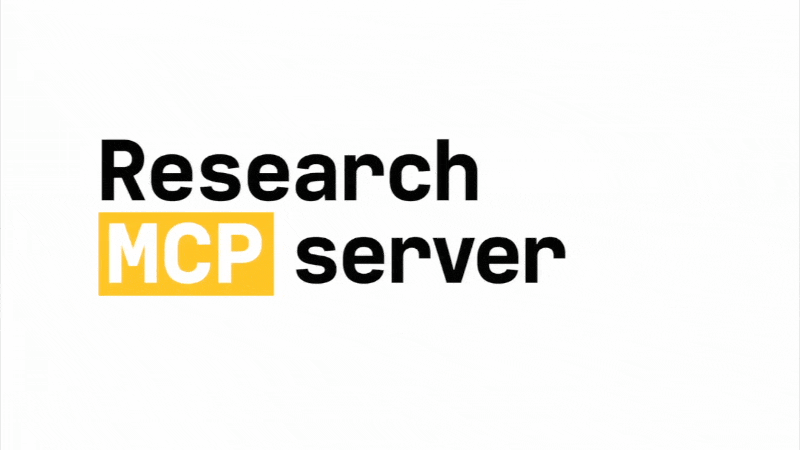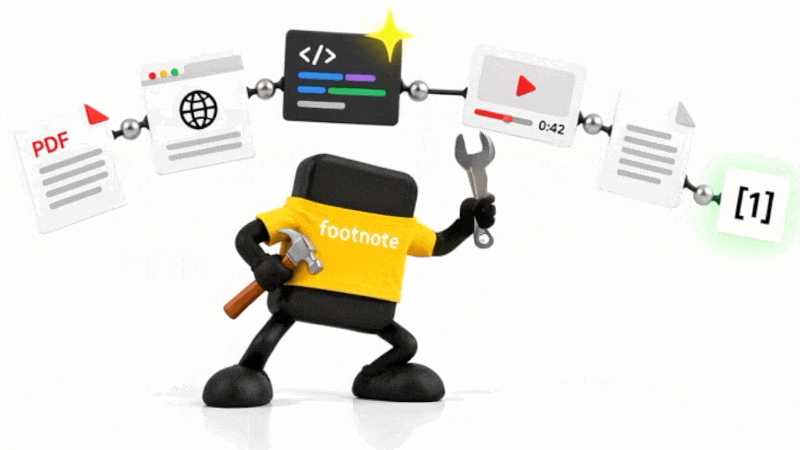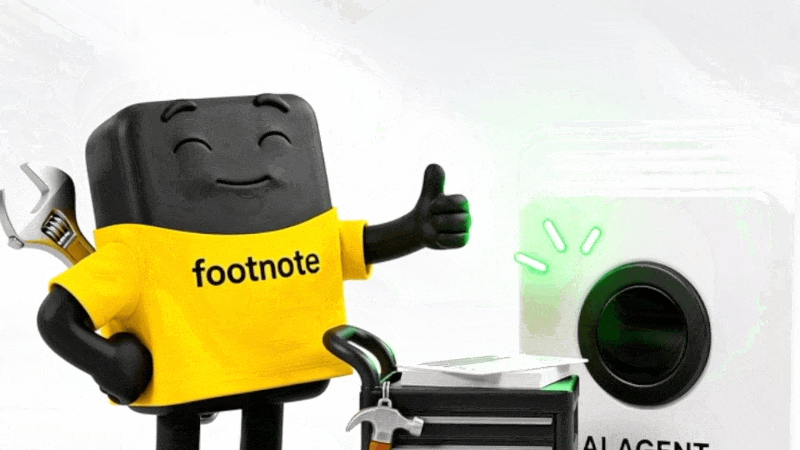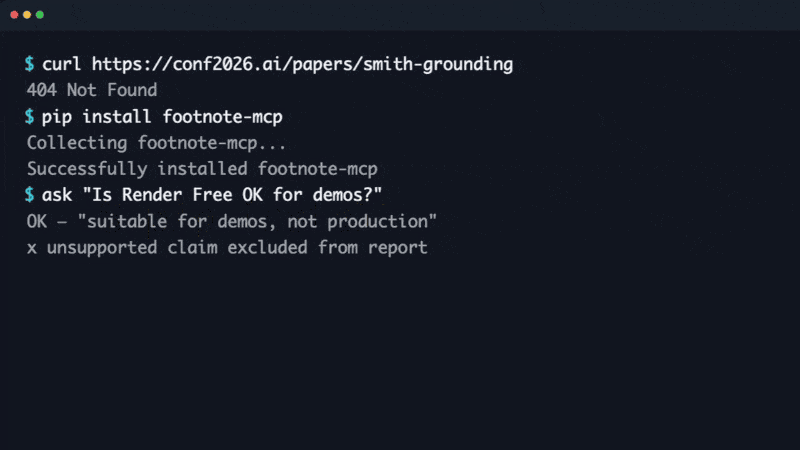
Unlike search APIs (Tavily, Exa) or scrapers (Firecrawl) that return raw text or markdown, footnote-mcp is built for verification: every claim is checked against the raw source text with sentence-level citations and character offsets, with zero required API keys.
Add to Cursor · Claude Desktop setup
Runs without API keys · 45 tools · MIT licensed
Quick start
footnote-mcp speaks MCP over stdio. Point a client at it — Claude Desktop's
claude_desktop_config.json, or Cursor's ~/.cursor/mcp.json:
No API keys are needed to start. Restart the client and ask it to run startup_health_check:
it reports, one line each, whether the extractors, the PDF and spreadsheet parsers, the
browser, OCR and the cache directory are usable on this machine — so a missing optional piece
shows up now rather than halfway through a research task.
Search the web without configuring an API key
Ask the assistant to look something up and web_search queries the zero-key providers — Bing,
DuckDuckGo, Brave, Wiby — alongside any keyed provider you configured, then deduplicates and
merges them into one ranking.
Every result carries the engines that returned it, so a page two independent indexes agree on is distinguishable from one only a single engine found, and a relevance score. Snippets count as discovery only: nothing at this stage is evidence yet, which is what the next two sections are for.
Provider routing, keys, and semantic reranking: docs/search-backends.md.
Extract tables and files from a page into structured rows
web_extract_tables turns a page's HTML tables into named columns and rows, each set tagged
with the URL it came from and with the true total, so a truncated answer says so instead of
looking complete. Point it at a Wikipedia revenue table and you get Rank, Name,
Industry, Revenue, Employees as fields you can sort and compare, not a wall of text to
re-read.
Data a page links rather than renders is covered too: web_detect_downloads finds the
CSV/TSV/XLS/XLSX/PDF/JSON attached to it, web_parse_file parses them, and web_fetch_json
takes an API endpoint directly.
Verify that a source actually supports a claim
The part a plain search tool does not do. evidence_entailment compares a claim to the source
text and returns a verdict; corroborate_claim triangulates across excerpts, and
locate_claim_span returns the supporting sentence with character offsets.
Given the claim "Norway's battery-electric share of new passenger cars was 82.4% in 2023" and a source reading "In 2023, battery-electric vehicles accounted for 82.4% of all new passenger cars registered in Norway", the verdict comes back as a value your agent can act on rather than a paragraph it has to interpret:
The default backend is deterministic and offline, and it never quietly hands the decision to
another model: where it is not confident it returns needs_review with the spans it matched,
for you — or the assistant that called it, which already has both texts — to read. A local
LLM judge (backend="ollama") and a local NLI model (backend="local_nli") are there when you
want them. Measured accuracy of the deterministic path, which is the default:
benchmarks/REPORT.md.
How it works
Search snippets are discovery, never evidence. Discovery merges several independent indexes;
fetching escalates through a ladder — plain HTTP, optional proxy, headless Chromium, optional
hosted scrape API — and stops at the cheapest tier returning real content. Extraction pulls
text, tables, and linked files, each cached with its source URL. Only then does verification
run, checking the claim against the fetched text before it counts. web_deep_search wraps the
whole loop: it decomposes requirements, re-searches unresolved gaps, and returns an evidence
ledger with a funnel showing where candidates were lost.
All 45 tools by category
Search (8)
web_search— Multi-engine search across zero-key providers (Bing, DuckDuckGo, Brave, Wiby) and optional metered APIsweb_search_recent— Search restricted to a recency window (day, week, month, year)web_deep_search— Iterative multi-step research loop with evidence ledger and funnel diagnosticspapers_search— Academic paper search via Crossref and arXivencyclopedia_search— Wikipedia and Wikidata entity lookup plus read-only SPARQLgithub_search— Search public repositories, code, issues, and commitsarchive_search— Historical snapshots via Wayback Machine and Common Crawlgenerate_search_queries— Generate targeted operator queries (site:,filetype:csv)
Fetch (4)
web_read— Fetch URL, extract text, evaluate source quality, and cache snapshotweb_fetch_authenticated— Fetch pages requiring custom cookies or session headersweb_archive_fetch— Retrieve the nearest Wayback Machine snapshot for dead or changed URLsweb_crawl— Breadth-first crawl following links from a starting URL
Extract (15)
web_extract_tables— Parse HTML tables into typed columns and rows with source URLsweb_detect_downloads— Discover linked data files (CSV, TSV, XLS, XLSX, PDF, JSON, XML)web_parse_file— Download and parse tabular data and PDF documentsweb_fetch_json— Fetch direct REST API endpoints into parsed JSONcheck_date_completeness— Validate time series date continuity across calendar and market schedulesresolve_units— Normalize currencies, units, and currency pairsvalidate_unit_rows— Detect and reject rows with conflicting units or currenciesreconcile_time_series— Align series by key, compute deltas, and flag missing entries or outliersexport_dataset— Save consolidated rows to CSV, XLSX, or JSON filestool_spec_propose— Propose task-specific extraction recipe specificationstool_code_generate— Generate starter Python extraction recipestool_code_validate— Validate recipe code against an AST safety allowlisttool_code_run_sandboxed— Execute extraction code inside a restricted subprocesstool_promote— Persist validated recipes to local memoryrecipe_registry— List, inspect, run, and delete registered extraction recipes
Verify (8)
evidence_entailment— Evaluate whether source text entails a claim (heuristic, Ollama, or NLI)corroborate_claim— Triangulate claim consensus or conflict across multiple excerptslocate_claim_span— Locate supporting sentences with character offsets and containment scoresclassify_source— Classify domains (official, aggregator, blog, forum, interactive, blocked)source_cache_get— Retrieve cached page snapshots and provenance metadatasource_cache_put— Store page contents and metadata into persistent cachebuild_research_debug_report— Compact diagnostic report of queries, sources, and verification gapsstartup_health_check— Inspect availability of parsers, browser runtime, OCR, and cache directories
Browser (10)
web_navigate— Open URL in Chromium session (headless or--headed)web_snapshot— Inspect interactive DOM accessibility tree with stable element referencesweb_click— Click interactive page elements by reference ID or CSS selectorweb_type— Enter text into form fields and input elementsweb_scroll— Scroll viewports or containers to reveal dynamic contentweb_extract— Extract targeted HTML elements or attributesweb_screenshot— Capture page screenshots with optional Tesseract OCRbrowser_set_date_range— Manipulate dynamic web date-picker controlsbrowser_extract_tables— Extract client-side rendered tables after DOM hydrationbrowser_extract_tables_for_date_range— Automate date selection and table extraction cycles
Full parameters and schemas: docs/tools.md.
Requirements
- Python 3.10 or newer, on macOS, Linux or Windows — CI runs all six combinations
- Chromium via
python -m playwright install chromium, for the browser tier and browser tools - Any MCP client speaking stdio; config is documented for Claude Desktop and Cursor
- Optional, for
semantic: true: an Ollama daemon, orrequirements-embed.txtto run the same bge-m3 weights in-process — the only option where no daemon exists, such as Docker - Optional: the system
tesseractbinary for OCR inweb_screenshotand scanned PDFs - No API keys, no account, no hosted service
Limitations
Related MCP Servers
Adoption & maintenance
Factual signals from GitHub, npm, and our automated checks — not a rating.
GitHub stars
2
Stargazers on the source repository.
Last commit
18d ago
Most recent push to the default branch.
Tools exposed
35
Callable tools this server registers over MCP.
Reviews
No reviews yet — be the first to share how this listing worked for you.
Frequently Asked Questions about Footnote MCP
AllMCPs Directory Badge
Showcase your server listing on GitHub or your project documentation. Embed this dynamic SVG badge to highlight official listing status and live engagement.
Badge Style:
Live Dynamic SVG Preview
Markdown (GitHub README)
[](https://allmcps.com/mcp/footnote-mcp)HTML Embed
<a href="https://allmcps.com/mcp/footnote-mcp"><img src="https://allmcps.com/api/badge/footnote-mcp?style=directory" alt="Footnote MCP on AllMCPs" /></a>Technical Specs & Signals
CategorySearch & Data Extraction
10/14 checks healthy over the last 46d
53Quality signal: Good · 53/100How this signal is calculated ▾
Server availabilityNot measured
Not scored for repo-hosted servers — we can't reach the running server, only its GitHub page. Hosted MCP endpoints are health-checked live.
Verified ownership10/20
Documentation & tools25/30
Adoption & activity5/15
Community engagement0/10
A guidance signal from public completeness & health data — not a user rating. New listings start lower and rise as they add docs, get verified, and grow adoption. Signals we can't observe for a listing are skipped, not counted against it.
Supply-chain signal
No high-severity advisories surfaced by our automated scan.
Critical 0High 0Medium 0Low 0
Scanned 2d ago via OSV.dev · footnote-mcp (PyPI)
Own this project?
This directory is pre-filled from public sources. Claim via GitHub README, site badge, or DNS TXT to unlock edit access and the Official badge — proof is checked automatically, then reviewed by our team.
Free dofollow backlink: add your website and place the AllMCPs badge on it — no claim needed. We detect it automatically and keep it verified as long as the badge stays live.
Claim & get free dofollowShare & Embed
Add our SVG badge (dark/light directory styles) or embeddable widget to your site.