Fedit README
The full upstream README, mirrored here for reference. Install config, tool schemas, adoption signals, and an original overview live on the Fedit listing page.
fedit — Fast File Editor for the Terminal

A zero-dependency CLI tool for surgical file edits from the command line. No interactive editors. No sed/awk gymnastics. Just simple, predictable operations with built-in verification.
Built for sysadmins, DevOps engineers, and anyone who scripts config changes.
Why fedit?
- One binary, zero dependencies — pure Go, runs everywhere
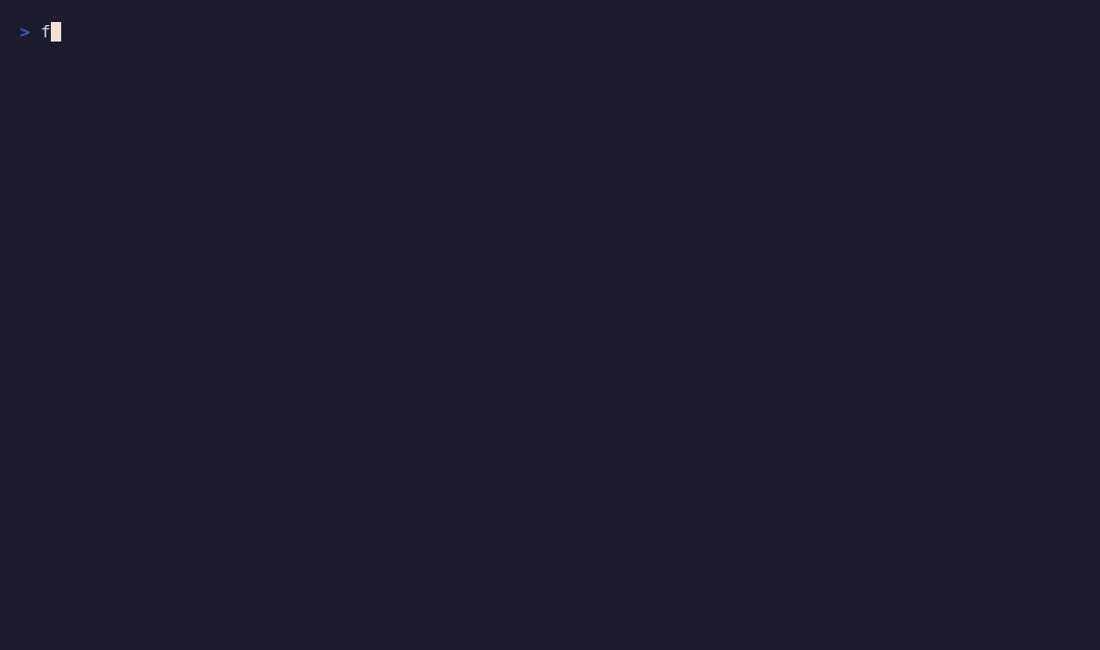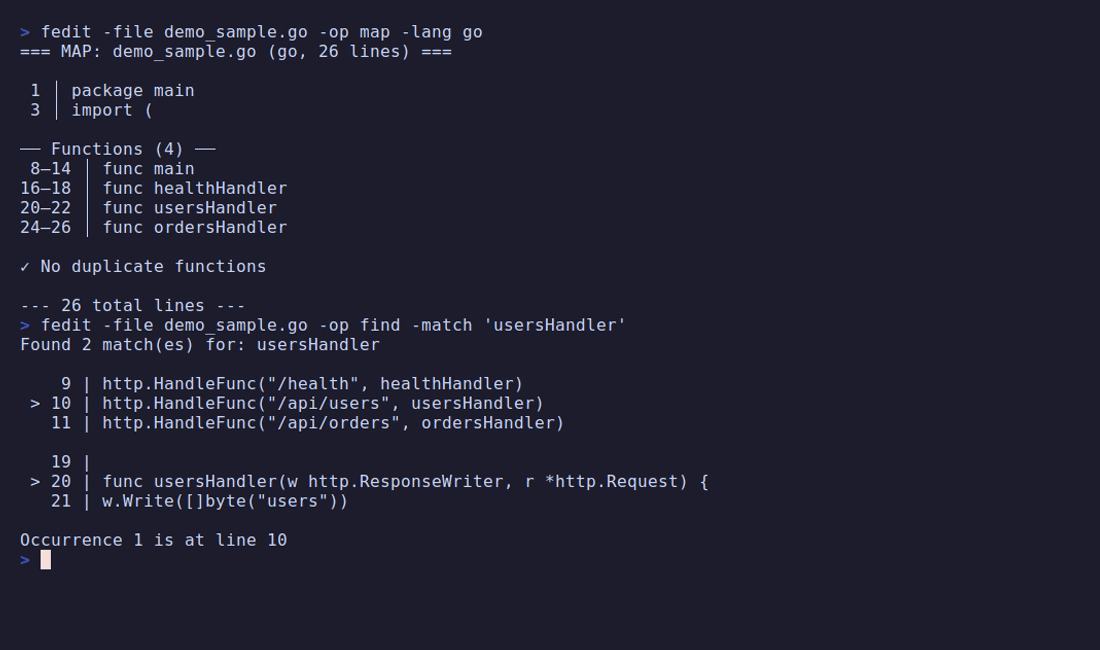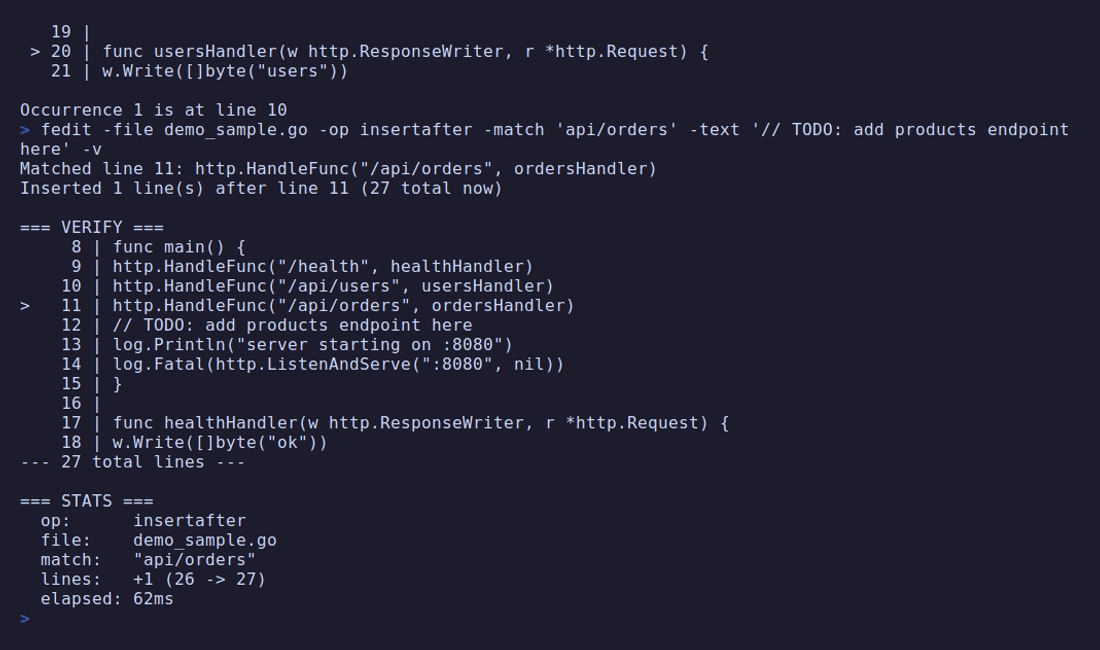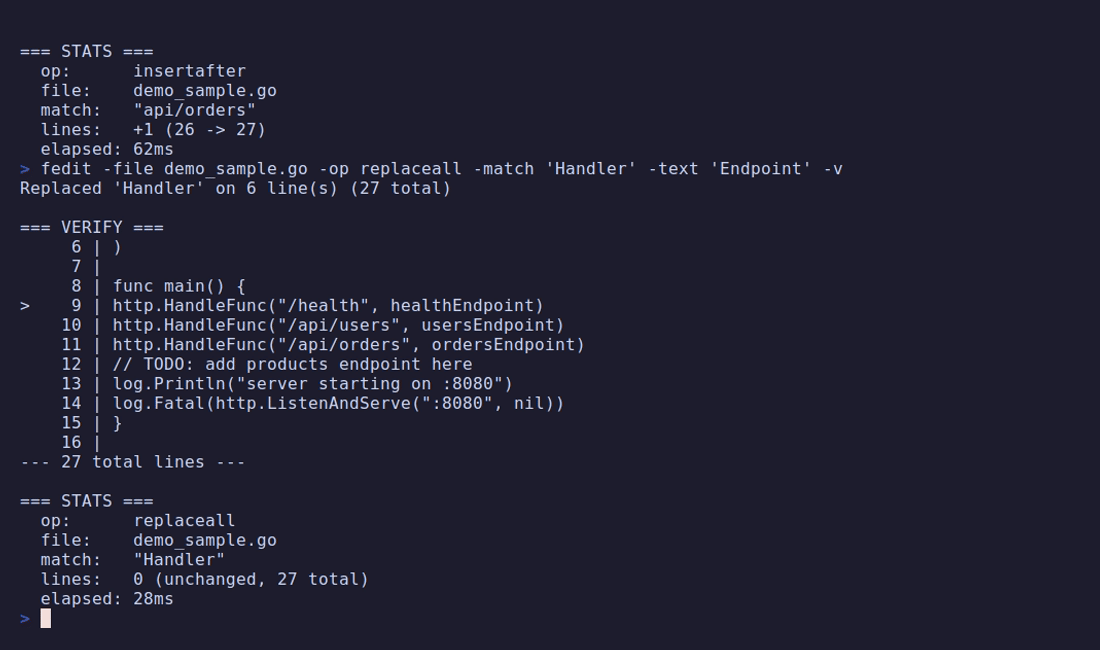
- 17 language mappers — see the structure of any file before editing
- -v flag — verify every mutation before moving on
- Line-aware — no regex surprises, no "which match did it hit?"
- Stream engine — process multi-GB files line-by-line with atomic integrity
- Field extraction — pull CSV/TSV column N without awk
- Safe — no in-place unless you say so, never touches files you did not name
Install
Go install (recommended):
Or download the binary from GitHub Releases and put it in your PATH.
Verify:
Quick Start
All Operations
show — Display file contents
find — Search for lines matching a substring
Pro tip: Run find first to get line numbers, then use replace or delete with exact lines.
insert — Insert content after a line number
insertafter — Insert after a matching line (RECOMMENDED)
insertbefore — Insert before a matching line (RECOMMENDED)
replace — Replace a line range with new content
replaceall — Global find-and-replace
Output goes to stdout for piping. Lines shorter than -col are skipped silently.
Always streaming -- no memory limit regardless of file size.
-stream -- Large-file streaming mode (v1.4.0)
Add -stream to replaceall or find to process files line-by-line without
loading them into memory. 10 MB per-line buffer handles JSON blobs and minified files.
Atomic integrity: writes to a temp file then renames -- original is untouched on interruption.
Supported with -stream: replaceall (literal and regex), find.
Not supported: move, copy, map (these require full file structure in memory).
writeraw — Write without escape expansion
Unlike write, writeraw treats \n as two characters (backslash + n), not a newline.
writelines — Write lines interactively from stdin
-texthex — Hex-encoded input (v1.6.0)
Encode text to hex first (e.g. with fwencode), then pass the hex string as -text.
Eliminates all shell-quoting issues with special characters.
-matchhex / -endmatchhex — Hex-encoded anchors (v1.8.1)
Same idea as -texthex, but for the search anchors. PowerShell mangles a double quote
inside -match before fedit sees it, so case "replace": silently becomes case replace:
and matches nothing. Pass the anchor as hex instead; fedit decodes it into -match
(or -endmatch) once, so every op that takes an anchor works unchanged.
Invalid hex exits 1 with matchhex: invalid hex string: ... (or endmatchhex: ...).
Multiple files -- comma list or glob (v1.8.1)
-file accepts a comma-separated list, a glob, or both, for the read-only ops show, find and map. Each file gets a ==> path <== header, and a real file with that exact name wins over glob expansion.
- find skips files with no hits (grep-style) and exits 1 only if nothing matched in any file.
- map skips unrecognized extensions with a SKIP line.
- A summary line reports how many files had results.
- Mutating ops and -stream are rejected with exit 1 before any file is read. For a global rename across files, use -files GLOB with replaceall.
- CLI only: the MCP tools still take a single file.
-cleanfirst — Truncate before writing (v1.6.0)
-x — Machine-readable output (v1.6.0)
v1.5.0: HCL/Terraform block mapper (-lang hcl)
Move, copy, and refactor Terraform blocks by name — no line numbers needed.
Accepts -lang hcl, -lang tf, or -lang terraform (all equivalent).
Supported block types: resource, data, module, provider, variable,
output, locals, terraform, moved, import, check.
Nested blocks (e.g. ingress {} inside a resource) are correctly ignored —
only top-level blocks are matched.
v1.5.0: Nix block mapper (-lang nix)
Move and copy top-level attribute bindings in Nix expression files.
Handles attribute sets (name = { }), lists (name = [ ]), and
dotted attributes (programs.git = { }).
move — Move a line range to a new position
Rules:
- Destination may not overlap the source range — fedit reports a precise error with line numbers.
-times N: cut once, paste N times. Net delta = blockSize × (N−1). Default times=1 = zero delta.
copy — Copy a line range to a new position
Rules:
- Snapshot semantics: source range is read once before any writes. All N copies are identical clones of the original, even when destination overlaps source.
- Net delta = blockSize × times.
write — Create or overwrite a file
map — Structural overview of a file
Supported Map Languages (17)
| Language | Key Structures Detected |
|---|---|
| go | package, imports, types, interfaces, functions |
| python | imports, classes, functions, decorators |
| javascript | imports, exports, classes, functions, arrows |
| typescript | (same as javascript) |
| css | imports, custom properties, selectors, @media, @keyframes |
| rust | use, mod, struct, enum, trait, impl, fn, macro_rules! |
| java | package, imports, classes, interfaces, enums, methods |
| csharp | using, namespace, classes, interfaces, records, properties |
| html | doctype, head/body, headings, scripts, links, forms, ids |
| sql | CREATE, ALTER, DROP, INSERT, SELECT, indexes, triggers |
| yaml | document separators, top-level keys |
| toml | tables, array tables, top-level keys |
| markdown | headings, code blocks, links |
| ruby | requires, modules, classes, methods, attributes |
| php | namespace, use, classes, interfaces, traits, functions |
| dockerfile | FROM stages, all instructions |
| makefile | includes, variables, .PHONY, targets |
All mappers detect duplicates and flag them with warnings.
Flags Reference
| Flag | Description |
|---|---|
| -file PATH | Target file (required); comma list or glob for show/find/map (v1.8.1) |
| -op OP | Operation to perform (required) |
| -line N | Starting line number (1-based); N:+M=range, -N=from end, -N:=last N lines, :=EOF |
| -end N | Ending line (for ranges); -N counts from end of file |
| -text "s" | Inline text content |
| -textfile F | Read content from a file |
| -match "s" | Substring to search for |
| -nth N | Which occurrence (default 1, -1 = last) |
| -lang LANG | Language for map operation |
| -v | Verify: show affected lines after edit |
| -endmatch "s" | Content-anchor end of range (show/replace/delete/move/copy) |
| -quiet | Suppress stdout on success; exit code signals result |
Real-World Examples
Patch an Nginx config in a deploy script
Add a cron job to crontab
Bulk update version in multiple files
Inspect a Dockerfile before editing
Remove a block from a config
PowerShell workflow (Windows sysadmins)
Tips
- Always use -v on mutations — it costs nothing and saves you from blind edits
- Use find before replace — get the exact line numbers first
- Prefer insertafter/insertbefore over insert — matching is more resilient than hardcoded line numbers
- Use -nth -1 to target the last occurrence of a match
- Use -textfile for multi-line inserts — avoids shell quoting headaches
- map before editing unfamiliar files — see the structure first
LLM Benchmark
How well do current LLMs use fedit vs. rewriting whole files?
We tested Claude (Sonnet 4.6), ChatGPT (GPT-4o), and Gemini (2.5 Pro) on 7 realistic editing tasks across files of 565-1206 lines. Each model was tested twice per task: once asked to output the whole file ("raw"), once asked to output fedit commands only ("fedit").
Results
Legend: PASS+ = optimal one-line solution | PASS = correct | PASS* = correct content, formatting artifact | PARTIAL = correct intent, off-by-one or fragile | FAIL = wrong output
| Test | File | Task | Claude raw | Claude fedit | GPT raw | GPT fedit | Gemini raw | Gemini fedit |
|---|---|---|---|---|---|---|---|---|
| T1 | processor_600.go (575 L) | Insert method after specific struct method | PASS | PARTIAL | FAIL | PARTIAL | PASS | FAIL |
| T2 | config_800.yaml (1059 L) | Replace 24-line deployment block | PASS | PASS | FAIL | FAIL | PASS | FAIL |
| T3 | styles_500.css (565 L) | Find & delete CSS rule block | PASS | PASS | PASS* | FAIL | PASS* | FAIL |
| T4 | system_1000.go (980 L) | Global rename (36 occurrences) | PASS | PASS+ | FAIL | PASS+ | PASS* | PASS+ |
| T5 | analytics_700.py (682 L) | 3-step chain (insert + delete + replace) | PASS | PARTIAL | FAIL | FAIL | PASS | FAIL |
| T6 | dashboard_900.html (891 L) | Insert before 3rd matching button (-nth) | PASS | PARTIAL | FAIL | PASS+ | PASS | FAIL |
| T7 | engine_1200.go (1196 L) | Map + targeted insert after method | PASS | PASS | FAIL | FAIL | PASS | FAIL |
Top-line numbers
| Model | Raw mode | Fedit mode |
|---|---|---|
| Claude | 7/7 PASS | 4 PASS, 3 PARTIAL |
| ChatGPT | 1/7 PASS* | 2 PASS+, 1 PARTIAL, 4 FAIL |
| Gemini | 7/7 PASS* | 1 PASS+, 6 FAIL |
Key findings
1. ChatGPT cannot output large files reliably.
6 of 7 raw tests truncated. The most striking failure was T6, where it inserted
the literal placeholder line [... TRUNCATED FOR BREVITY ...] into otherwise
valid HTML — a uniquely dangerous failure mode where output looks structurally
complete but contains placeholder strings. T7 truncated 1206 lines down to 166.
2. LLMs hallucinate line numbers — and it gets worse with chain length. Gemini's line-number errors grew across the suite: off by 36-56 lines on T2 (single replace), 45 lines on T3, then 73 lines on T5 (3-step chain). ChatGPT showed similar drift on T5. Claude was the only model that produced runnable line-numbered commands consistently.
3. Content-matching ops are immune to the hallucination class.
Gemini failed every fedit test that required line numbers (T1, T2, T3, T5, T6,
T7), but PASSED T4 — which used replaceall with a content match. Same model,
same task complexity, dramatically different reliability. The bottleneck is
counting, not understanding.
4. insertafter on a function declaration matches the OPENING line.
Models repeatedly tried insertafter -match "func MyFunc()" to insert content
AFTER the function ended. This is correct fedit behavior (it inserts after the
matched line) but inserts the new code INSIDE the function body. Workaround:
insertbefore the NEXT structural element. Confirmed in T1 and T7.
5. Even Claude flubs line-number direction.
T6: Claude used insert -line 30 to add a banner before the 3rd button at line
30. But insert -line N adds content AFTER line N. The correct command was
insertbefore -match "View Details" -nth 3. Even the strongest model gets
direction wrong about 1 in 6 single-step ops when reaching for line numbers.
6. -match is single-line only — and that's a feature.
ChatGPT (T3 fedit) tried to pass a multi-line CSS block as -match with literal
\n escapes. fedit doesn't interpret escapes in -match and matches only
single lines. This kept the operation safe (zero matches → no edit) rather than
allowing a fragile multi-line pattern that could easily mismatch.
7. Markdown rendering is a hidden adversary.
ChatGPT and Gemini outputs lost __name__ → name, __init__ → **init**,
and stripped CSS/Python indentation when rendered in chat UIs. The underlying
files (when downloaded directly) were correct. This affects copy-paste workflows
but not API integrations. For best results, use the model's "copy code"
button or download links — never select-and-copy from rendered output.
8. Three different models converged on the same one-liner for T4.
Claude, ChatGPT, and Gemini all independently produced
fedit -op replaceall -match "FetchUser" -text "GetAccount".
When the right tool is obvious, models reach for it. fedit's design surface
makes the right tool obvious for content-driven edits.
Recommendations for LLM-driven workflows
Based on these results, prefer content-matching operations over line-number operations when generating fedit commands from an LLM:
- Use
insertbefore -match "next anchor"instead ofinsert -line N - Use
replaceall -match "old" -text "new"instead ofreplace -line N -end M - Use
find -matchandshowto confirm line numbers before any line-numbered op - Reserve line-numbered ops for cases where an MCP-connected LLM has just run
fedit_findorfedit_showand has verified the line in context
For best results, give the LLM an MCP connection to fedit (see
MCP Server Mode) so it can fedit_find and fedit_show
before mutating. This eliminates the line-number hallucination class entirely
and was the path Claude consistently took when it had recon available.
Methodology
- Each test run in a fresh chat with the original file uploaded
- Prompts identical across models; only "raw" vs "fedit" framing differed
- Output saved verbatim, then diffed against ground truth via
Compare-Object - Ground truth verified by running fedit commands locally and re-reading output
- All 7 raw outputs that PASSED Compare-Object empty (byte-identical to ground truth): Claude T2, T3, T4, T5, T6, T7 + Gemini T5, T6, T7
PASS*indicates byte-difference from indentation-stripping in chat UI render, with content structurally correct (verified by re-running fedit ops on the saved file)
Test corpus
7 synthetic files (565-1206 lines) covering Go, YAML, CSS, Python, and HTML.
All test files, prompts, and ground-truth outputs are available in the bench/
directory of this repository.
MCP Server Mode
fedit includes a built-in Model Context Protocol (MCP) server, so AI coding assistants can use fedit as a tool for precise file edits.
This starts a JSON-RPC 2.0 server on stdin/stdout. The server exposes all 14 editing operations as MCP tools:
| Tool | Description |
|---|---|
fedit_show | Display file contents (full or line range) |
fedit_insert | Insert content after a line number |
fedit_delete | Delete one or more lines |
fedit_replace | Replace a line range with new content |
fedit_replaceall | Global find-and-replace; regex capture groups; multi-file glob; -stream for large files |
fedit_write | Create or overwrite a file |
fedit_writeraw | Create or overwrite a file with no escape expansion (backslashes literal) |
fedit_map | Structural overview (17 languages) |
fedit_find | Find lines matching a substring |
fedit_insertafter | Insert after a matching line |
fedit_insertbefore | Insert before a matching line |
fedit_move | Move a line range to a new position; destination-overlap rejected |
fedit_copy | Copy a line range; snapshot semantics, overlap allowed, -times N |
fedit_fields | Extract column N from CSV/TSV/delimited file (-col N -delim CHAR); always streaming |
Configuring with Claude Desktop
Add to your claude_desktop_config.json:
For a full setup guide (Windows paths, troubleshooting, Cursor/Cline/Windsurf snippets): CLAUDE_DESKTOP.md
Configuring with Cursor
Add to .cursor/mcp.json in your project root:
Why MCP?
Without fedit, LLMs rewrite entire files — burning tokens and introducing drift. With fedit as an MCP tool, the model calls fedit_map to see structure, fedit_find to locate targets, and fedit_replace or fedit_insertafter to make surgical edits. Every mutation returns stats (line delta, elapsed time) so the model can verify its work.
FAQ
Do I need fedit if my team has a solid PR review process?
Probably not for human-driven edits where you review every diff. fedit shines in two specific cases:
-
Whole-file rewrites in long configs. When an LLM regenerates a 600-line
values.yamlto change one key, the diff is technically reviewable but practically nobody scrolls to line 412 to confirm nothing else moved. fedit makes the diff exactly N lines for an N-line change. -
Agent loops without a human in the middle. If you run agents semi-autonomously (issue → branch → PR opened, you review at the end), giving the agent surgical tools (
fedit_replace,fedit_insertafter) instead of "rewrite the whole file" measurably reduces review surface area.
If your workflow already catches these, the CLI is overkill. The MCP server may still be useful as an agent primitive.
Does fedit support streaming for all operations?
Currently replaceall and find support -stream mode. move and copy require the full file in memory because they need to read both source and destination ranges. map requires structure analysis. fields is always streaming.
What is the maximum file size fedit can handle?
In default (in-memory) mode: limited by available RAM, typically fine up to a few hundred MB. With -stream: unlimited -- fedit processes one line at a time with a 10 MB per-line buffer.
Does fedit support Terraform / HCL?
Yes, as of v1.5.0. Use -lang hcl (or -lang tf/terraform) with -block, -beforeblock, -afterblock to move and copy Terraform blocks by name. All 11 top-level block types are supported. The map op supports HCL/Terraform and Nix as of v1.5.0 -- fedit_map -lang hcl returns all top-level block names and line ranges.
Does fedit preserve comments and formatting?
Yes, by design. fedit does not parse-and-reformat — it operates on raw text bytes at line granularity.
If you replace -line 47 -end 49, lines 1–46 and 50–EOF are untouched byte-for-byte: comments, trailing whitespace, mixed indentation, BOM markers, all preserved exactly. This is the main reason fedit is line-addressable instead of AST-based: AST round-trips lose too much (trailing commas, comment positioning, key ordering, blank-line spacing).
This matters most for nginx configs (inline comments documenting why a directive exists), Ansible playbooks (YAML anchors and merge keys), and any file where a human formatting choice carries semantic weight.
Is the MCP server Claude-specific or Cursor-specific?
Neither — it targets the open MCP spec. Plain JSON-RPC 2.0 over stdin/stdout against the public Model Context Protocol schema. No vendor-specific bits.
Tested with Claude Desktop; should work with any compliant MCP client (Cursor, Continue, Cline, custom integrations). Tool definitions and JSON Schema live in mcp.go if you want to inspect the surface area before wiring it up.
What if the target string appears multiple times in the file?
Use the -nth N flag:
-nth 1(default) — first match-nth 2— second match-nth -1— last match- Any positive integer picks that occurrence
Example targeting the third http.Redirect call:
If you are not sure how many matches exist, run find first — it lists every match with context so you can disambiguate before mutating:
Does chaining commands cause line-number drift?
No. Each fedit invocation reads the file fresh, so line numbers always reflect the current state on disk. You can chain operations safely with ; (PowerShell) or && (bash):
The tradeoff is one disk read per operation, which is negligible for editing workflows.
If you want drift-immunity by design, prefer content-based targeting (insertafter / insertbefore / replaceall with -match) over line numbers — those resolve the target on each invocation regardless of what previous ops did.
LLM Benchmark
fedit is the missing layer between LLMs and your codebase. LLMs excel at generating correct code — but applying that code to the right line of a 900-line file, across a 3-step chain, without hallucinating line numbers? That is a different problem.
We tested Claude Sonnet 4.6, ChatGPT GPT-4o, and Gemini 2.5 Pro on 7 realistic editing tasks against files of 565–1206 lines. Each task ran twice: once asking the model to output the whole rewritten file ("raw"), once asking it to output fedit commands only ("fedit"). All outputs were diffed byte-for-byte against ground truth.
Top-line results
| Model | Raw | fedit |
|---|---|---|
| Claude Sonnet 4.6 | 7/7 PASS | 4/7 PASS · 3 PARTIAL |
| ChatGPT GPT-4o | 1/7 PASS (6 truncated) | 2/7 PASS · 1 PARTIAL · 4 FAIL |
| Gemini 2.5 Pro | 7/7 PASS* | 1/7 PASS · 6 FAIL |
*PASS* = correct content, formatting artifact from chat UI render.
Per-test results
| Test | File | Task | CL raw | CL fedit | GPT raw | GPT fedit | GM raw | GM fedit |
|---|---|---|---|---|---|---|---|---|
| T1 | processor.go (575 L) | Insert method after struct method | PASS | PARTIAL | FAIL | PARTIAL | PASS | FAIL |
| T2 | config.yaml (1059 L) | Replace 24-line deployment block | PASS | PASS | FAIL | FAIL | PASS | FAIL |
| T3 | styles.css (565 L) | Find and delete CSS rule | PASS | PASS | PASS* | FAIL | PASS* | FAIL |
| T4 | system.go (980 L) | Global rename (36 occurrences) | PASS | PASS+ | FAIL | PASS+ | PASS* | PASS+ |
| T5 | analytics.py (682 L) | 3-step chain (insert + delete + replace) | PASS | PARTIAL | FAIL | FAIL | PASS | FAIL |
| T6 | dashboard.html (891 L) | Insert before 3rd match (-nth) | PASS | PARTIAL | FAIL | PASS+ | PASS | FAIL |
| T7 | engine.go (1196 L) | Map + targeted insert after method | PASS | PASS | FAIL | FAIL | PASS | FAIL |
PASS+ = optimal one-liner · PASS = correct · PARTIAL = correct intent, fragile execution · FAIL = wrong output
Key findings
1. ChatGPT cannot reliably output large files. 6 of 7 raw tests were truncated. T6 inserted the literal placeholder [... TRUNCATED FOR BREVITY ...] into otherwise valid HTML. T7 compressed 1196 lines down to 166.
2. LLMs hallucinate line numbers — and it compounds with chain length. Gemini drifted by 36–56 lines on T2, 45 on T3, then 73 lines on a 3-step chain (T5). Only Claude produced correct line-numbered commands consistently.
3. Content-matching ops are immune to the drift problem. Gemini failed every fedit test that required line numbers — but PASSED T4 with replaceall -match. Same model, same task complexity, dramatically different reliability. The bottleneck is counting, not understanding.
4. All three models converged on the same one-liner for T4. Claude, ChatGPT, and Gemini independently produced fedit -op replaceall -match "FetchUser" -text "GetAccount". When the right tool is obvious, models reach for it.
Recommendations
Prefer content-matching operations over line-number operations when generating fedit commands from an LLM:
- Use
insertbefore -match "next anchor"instead ofinsert -line N - Use
replaceall -match "old" -text "new"instead ofreplace -line N -end M - Use
find -matchandshowto confirm position before any line-numbered op - Use
-block/-langto target named functions and structs without any line numbers
For best results, give the LLM an MCP connection to fedit (fedit mcp). This eliminates the line-number hallucination class entirely — the path Claude consistently took when recon was available.
Full results, ground truth files, test prompts, and the 7-file corpus: amalexhandler.com/fedit#benchmark
License
MIT — see LICENSE
Built by Amalex — makers of Amalex Handler, the universal file transporter.