

Build & Unit Tests, E2E, and MCP Conformance all run on stock GitHub-hosted runners (cloud CI) — no docker image, no self-hosted runner. E2E and Conformance run against EDT 2026.2 (build 2026.2, Eclipse 4.38 / Java 25): the setup step installs a headless EDT of that version on the runner via
p2 director. E2E additionally imports the test fixtures into an empty workspace via the plugin's headless bootstrap (EDT_MCP_IMPORT_PROJECTS) and skips the live-infobase tools, so no 1C platform is needed. Each badge reflects its latest run.
EDT MCP Server
MCP (Model Context Protocol) server plugin for 1C:EDT, enabling AI assistants (Claude, GitHub Copilot, Cursor, etc.) to interact with EDT workspace.
[!TIP] Contributing / making changes? Read CLAUDE.md first — it's the code-conduct "minefield map": hard don'ts and the stop-and-think-twice zones for this codebase (BM transactions, the bilingual ru/en model, cascading rename, etc.). Detailed how-to lives in the skills under
.claude/skills/.
[!TIP] Using EDT-MCP on a 1C business project? The client-neutral business-project skills pack routes common project tasks to compact workflows. The rules pack provides standing, detailed project policy; the two business-project layers are complementary. Both are separate from the plugin-contributor skills above.
[!IMPORTANT] EDT version compatibility: Supports 1C:EDT 2026.1 and 2026.2 (Ruby) from a single build. The plugin is COMPILED against the 2026.2 target platform but to Java 17 (
release 17plusBundle-RequiredExecutionEnvironment: JavaSE-17), so one artifact resolves on both — 2026.1 is Eclipse 4.30 / Java 17, 2026.2 is Eclipse 4.38 / Java 25. Building it needs a JDK 25 (Tycho 5 reads the platform's Java 25 class files); that is the JDK that runs the build, not the level it emits. The e2e + protocol-conformance gates run it on 2026.2.
Features
- 🔧 MCP Protocol 2025-11-25 - Streamable HTTP transport with SSE support
- 📊 Project Information - List workspace projects and configuration properties
- 🔴 Error Reporting - Get errors, warnings, problem summaries with filters
- 📝 Check Descriptions - Get check documentation from markdown files
- 🔄 Project Revalidation - Trigger revalidation when validation gets stuck
- 🔖 Bookmarks & Tasks - Access bookmarks and TODO/FIXME markers
- 💡 Content Assist - Get type info, method hints and platform documentation at any code position
- 🧪 Query Validation - Validate 1C query text in project context (syntax + semantic errors, optional DCS mode)
- 🧩 BSL Code Analysis - Browse modules, inspect structure, read/write methods, search code, and analyze call hierarchy
- 🖼️ Form Inspection - Get PNG screenshots and YAML layout snapshots from the form WYSIWYG editor
- 🚀 Application Management - Get applications, update database, launch in debug mode, terminate EDT-launched 1C clients
- 🎯 Status Bar - Real-time server status with tool name, execution time, and interactive controls
- ⚡ Interruptible Operations - Cancel long-running operations and send signals to AI agent
- 🏷️ Metadata Tags - Organize objects with custom tags, filter Navigator, keyboard shortcuts (Ctrl+Alt+1-0), multiselect support
- 📁 Metadata Groups - Create custom folder hierarchy in Navigator tree per metadata collection, with a toolbar toggle to hide groups temporarily
- ✏️ Metadata Refactoring - Create top-level objects with EDT default content; rename/delete metadata objects, their members and managed-form elements with full cascading updates across BSL code, forms and metadata; add new attributes to existing objects
- 🧭 Command Interface - Read and edit a subsystem section's (or the main section's) command interface: command visibility, common and per role, placement into panel groups, and order within a group
- 🛠️ Tool Management - Enable/disable tools by group, presets (Analysis Only, Code Review, Development), per-tool parameter defaults
Installation
From Update Site
- In EDT: Help → Install New Software...
- Add update site URL:
https://ditrixnew.github.io/EDT-MCP/ - Select EDT MCP Server Feature
- Restart EDT
From Windows command line - "one shot" very fast install
Close your EDT (!) and run:
rem Here  "%VER_EDT% = 2025.2.3+30"  just for example - please, set YOUR actual version !
set VER_EDT=2025.2.3+30

"\your\path\to\EDT\components\1c-edt-%VER_EDT%-x86_64\1cedt.exe" -nosplash ^
    -application org.eclipse.equinox.p2.director ^
    -repository https://ditrixnew.github.io/EDT-MCP/ ^
	-installIU com.ditrix.edt.mcp.server.feature.feature.group ^
	-profileProperties org.eclipse.update.reconcile=true
Installation Result
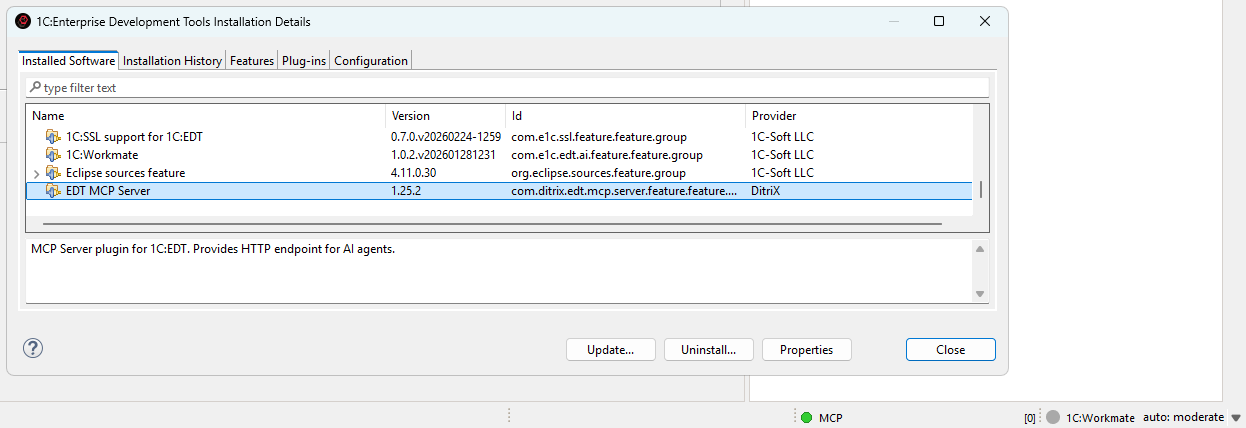
After that, EDT will automatically monitor the update site and install available updates when detected.
As well, we can also manually check via Help → About → Installation Details → Select MCP → Update
Required JVM flag for form screenshots
On Windows, get_form_screenshot needs EDT launched with:
-DnativeFormBufferedLayoutRender=true
get_form_layout_snapshot does not need this flag. Linux and macOS already use buffered native rendering, so the flag changes nothing there.
On Windows, enabling it switches the human form designer to offscreen-image mode. EDT builds the buffer path as <java.io.tmpdir>dtgraphics-form.bin, without inserting a separator. If EDT cannot create that file, the designer turns gray and screenshots fail. Even with a usable buffer path, this mode can distort the designer on a scaled display: elements are drawn larger, and a click in the designer selects a different element in the element tree. Add the flag only while you need form screenshots, and remove it for everyday designer work.
How to add it:
-
Close EDT.
-
Open
1cedt.ini(next to1cedt.exe, e.g.C:\Program Files\1C\1CE\components\1c-edt-2025.2.6+4-x86_64\1cedt.ini). -
After the
-vmargsline, add:-DnativeFormBufferedLayoutRender=true -
Start EDT.
How to add it (one-shot, no install changes):
"<path-to-EDT>\1cedt.exe" -data "<workspace>" -vmargs -DnativeFormBufferedLayoutRender=true
If the designer or screenshot is blank or gray, check the EDT log for AccessDeniedException on dtgraphics-form.bin. A typical cause is -Djava.io.tmpdir=C:\edt_tmp without a trailing separator: EDT tries C:\edt_tmpdtgraphics-form.bin. Change the line to -Djava.io.tmpdir=C:\edt_tmp\ and fully restart EDT. Also verify that -vmargs precedes the JVM options. If nothing helps, remove the buffered-render flag and restart EDT.
Configuration
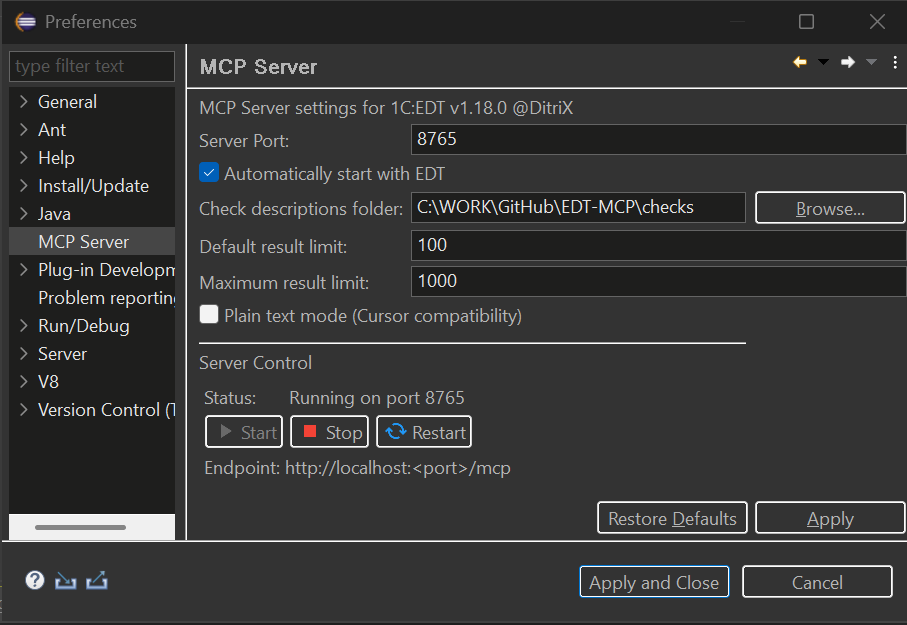
Go to Window → Preferences → MCP Server. The settings page has two tabs:
[!NOTE] Display language. The settings page and the tag dialogs are bilingual (Russian / English) and follow the Eclipse/EDT display language — the same
-nllaunch argument (or OS locale) that localizes the rest of EDT. Launch EDT with-nl rufor Russian or-nl enfor English; any other locale falls back to English. The MCP tool surface itself (tool names, descriptions and errors) stays English regardless, as it is the AI wire contract.
General Tab
- Server Port: HTTP port (default: 8765)
- Check descriptions folder: Optional override for the check descriptions that ship with the plugin. Leave it empty to use the bundled ones; point it at a folder to replace or translate individual checks (a file found there wins, per check)
- Auto-start: Start server on EDT launch
- Plain text mode (Cursor compatibility): Returns results as plain text instead of embedded resources (for AI clients that don't support MCP resources)
- Enhance Navigator: Controls this plugin’s contributions to the Navigator tree (groups and their filter). Turn it off to resolve conflicts with another plugin that patches the same panel
- Show tags in Navigator: Display tags as decorations in the Navigator tree
- Tag decoration style: How tags are displayed — all tags as suffix, first tag only, or tag count
- Server control: Start, stop, and restart the MCP server directly from preferences. The endpoint line shows the real URL for the port the server is actually serving, with Copy URL and Copy config (type/url) buttons — the latter puts a ready
mcpServersJSON entry on the clipboard for agents that are configured only by editing a file. That entry is thetype/urlform (Cursor, VS Code, Claude Code); Cline, Antigravity and OpenCode need the different shapes shown in their sections below. If an auth token is saved, the entry carries it as anAuthorizationheader (it would get a 401 otherwise), so treat the copied text as a secret
Tools Tab
Manage which tools are available to AI assistants. Tools are organized into groups that can be enabled or disabled together. See Tool Management for details.
Status Bar Controls
The MCP server status bar shows real-time execution status with interactive controls.
Status Indicator:
- 🟢 Green - Server running, idle
- 🟡 Yellow blinking - Tool is executing
- ⚪ Grey - Server stopped
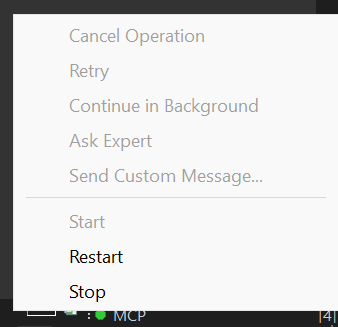
User Signal Controls - Send signals to AI agent during tool execution
During Tool Execution:
- Shows tool name (e.g.,
MCP: update_database) - Shows elapsed time in MM:SS format
- Click to access control menu
When a tool is executing, you can send signals to the AI agent to interrupt the MCP call:
| Button | Description | When to Use |
|---|---|---|
| Cancel Operation | Stops the MCP call and notifies agent | When you want to cancel a long-running operation |
| Retry | Tells agent to retry the operation | When an EDT error occurred and you want to try again |
| Continue in Background | Notifies agent the operation is long-running | When you want agent to check status periodically |
| Ask Expert | Stops and asks agent to consult with you | When you need to provide guidance |
| Send Custom Message... | Send a custom message to agent | For any custom instruction |
How it works:
- When you click a button, a dialog appears showing the message that will be sent to the agent
- You can edit the message before sending
- The MCP call is immediately interrupted and returns control to the agent
- The EDT operation continues running in the background
- Agent receives a response like:
USER SIGNAL: Your message here

Signal Type: CANCEL
Tool: update_database
Elapsed: 20s

Note: The EDT operation may still be running in background.
Use cases:
- Long-running operations (full database update, project validation) blocking the agent
- Need to give the agent additional instructions
- EDT showed an error dialog and you want agent to retry
- Want to switch agent's focus to a different task
Tool Management
Control which MCP tools are exposed to AI assistants. This lets you reduce context window usage and restrict AI to read-only operations when needed.
Tool Groups
All tools are organized into 11 semantic groups:
| Group | Description | Tools |
|---|---|---|
| Core / Project | Essential server, project, configuration, history, and XML export/import tools | get_edt_version, get_server_status, get_tool_guide, list_toolsets, enable_toolset, list_projects, get_configuration_properties, clean_project, revalidate_objects, resync_to_disk, get_check_description, export_configuration_to_xml, import_configuration_from_xml, import_project_from_file, delete_project, create_project, get_event_log, get_mcp_history |
| Errors & Problems | Error reporting, validation, and workspace markers (bookmarks, tasks) | get_problem_summary, get_project_errors, get_markers, apply_quick_fix, validate_xdto_package |
| Code Intelligence | Content assist, documentation, metadata and common-picture browsing, and references | get_content_assist, get_platform_documentation, get_metadata_objects, get_metadata_details, list_subsystems, get_subsystem_content, find_references, list_common_pictures, export_common_picture, search_in_dcs |
| Tags | Metadata tag management | get_tags, get_objects_by_tags |
| Applications & Testing | Application and infobase management, external-object builds, launch, testing, background jobs, and Workmate | get_applications, infobase_sessions, list_configurations, create_launch_config, delete_launch_config, create_infobase, delete_infobase, update_database, launch, terminate_launch, run_yaxunit_tests, ask_workmate, get_job_status, , , , |
Enable or disable entire groups or individual tools from the Tools tab in Window → Preferences → MCP Server. Disabled tools are filtered out of tools/list responses. If a client calls a disabled tool directly through tools/call, the server returns a message explaining that the tool is disabled.
Presets
Quickly switch between common tool configurations using presets:
| Preset | Description |
|---|---|
| All Tools | All tools enabled (default) |
| Analysis Only | Read-only analysis — Core except delete_project, plus Errors, Code Intelligence, Tags |
| Code Review | Analysis + BSL code reading (excludes write_module_source) |
| Development | Full development without debugging tools |
Select a preset from the dropdown in the Tools tab. The dropdown shows the preset you last chose and keeps it when you tick or untick individual tools, so later preset-owed updates (for example a new mutating tool disabled in the read-only presets) still reach your edited profile. Choose "Custom", "Disable all" or "Restore Defaults" to opt out. Profiles saved by older versions are recognised once, on upgrade.
Per-Tool Parameter Defaults
Some tools have configurable default values for parameters like result limits. These defaults are used when the AI client doesn't specify the parameter explicitly:
| Tool | Parameter | Default | Range |
|---|---|---|---|
get_project_errors | Result limit | 100 | 1–1000 |
get_markers | Result limit | 100 | 1–1000 |
get_metadata_objects | Result limit | 100 | 1–1000 |
get_content_assist | Result limit | 100 | 1–1000 |
search_in_code | Max results | 100 | 1–500 |
search_in_code | Context lines | 2 | 0–5 |
read_module_source | Max lines | 500 | 100–50000 |
terminate_launch | Termination timeout (sec) | 10 | 1–120 |
Configure these in the Tools tab by selecting a tool that has configurable parameters — the parameter editors appear in the details panel below the tool tree.
Progressive Tool Disclosure (dynamic toolsets)
For clients that work better with a small initial tool surface, the server can expose
only a core toolset up front and reveal the rest on demand — shrinking the
always-loaded tools/list. This is off by default (the full list is exposed,
unchanged); turn it on with the Progressive disclosure preference (or the
EDT_MCP_PROGRESSIVE_DISCLOSURE=true environment variable for headless/CI runs).
When on, only the core toolset (navigation, source read, metadata discovery, and the
two management tools) appears in tools/list. To use more tools:
- Call
list_toolsetsto see the groups (core,metadata,code,debug,testing,profiling,forms,tags,translation,project,git) and their tools. - Call
enable_toolsetwithtoolsets=[ids](e.g.["code","debug"]). - Re-request
tools/list— the revealed tools now appear.
The server pushes notifications/tools/list_changed whenever that surface changes —
after enable_toolset reveals a toolset, and after the Tools tab enables or
disables tools — but only to a client holding an open SSE stream. A client without one
must re-list after enabling (the enable_toolset response says so). A hidden tool is
only hidden from tools/list; it remains callable by name. These progressive-disclosure
toolsets are distinct from the Tool Groups above (which the Tools tab uses to
enable/disable tools persistently).
Connecting AI Assistants
VS Code / GitHub Copilot
Create .vscode/mcp.json:
{
  "servers": {
    "EDT MCP Server": {
      "type": "sse",
      "url": "http://localhost:8765/mcp"
    }
  }
}
Other AI Assistants - Cursor, Claude Code, Claude Desktop
Cursor IDE
Note: Cursor doesn't support MCP embedded resources. Enable "Plain text mode (Cursor compatibility)" in EDT preferences: Window → Preferences → MCP Server. It moves a result into
content[0].text; a JSON tool still returns itsstructuredContentas well, so a client that enforces the declaredoutputSchemais satisfied too.
Create .cursor/mcp.json:
{
  "mcpServers": {
    "EDT MCP Server": {
      "url": "http://localhost:8765/mcp"
    }
  }
}
Claude Code
Note: By editing the file
.claude.jsoncan be added to the MCP either to a specific project or to any project (at the root). If there is no mcpServers section, add it.
Add to .claude.json (in Windows %USERPROFILE%\.claude.json):
"mcpServers": {
  "EDT MCP Server": {
    "type": "http",
    "url": "http://localhost:8765/mcp"
  }
}
Claude Desktop
claude_desktop_config.json accepts only stdio servers (a command), not a direct url, so bridge the HTTP endpoint with mcp-remote (requires Node.js):
{
  "mcpServers": {
    "EDT MCP Server": {
      "command": "npx",
      "args": ["-y", "mcp-remote", "http://localhost:8765/mcp"]
    }
  }
}
The Settings → Connectors ("custom connector") route needs an HTTPS server reachable from Anthropic's cloud, so a plain-HTTP
localhostendpoint must go through themcp-remotestdio bridge above. You could expose it over an HTTPS tunnel (ngrok / Cloudflare Tunnel) to use a connector — but this server can write code into your configuration and start a debugger, so putting it on the public internet is a serious security risk and is not recommended.
Cline - extension for VSCode.
{
  "mcpServers": {
    "EDTMCPServer": {
      "type": "streamableHttp",
      "url": "http://localhost:8765/mcp"
    }
  }
}
Antigravity
{
    "mcpServers": {
        "EDTMCPServer": {
            "serverUrl": "http://localhost:8765/mcp"
        }
    }
}
1C:Workmate in-process bridge
When 1C:Workmate (com.e1c.edt.ai* 1.0.5 or 1.0.7) runs in the same EDT JVM,
integration works in both directions. The two builds differ in the conversation
API — 1.0.5 wraps the project in ProjectId, 1.0.7 takes the Eclipse IProject
and adds a progress-listener argument — and the adapter picks the layout by
probing the installed classes, so no version has to be configured. One behaviour
follows from that difference: on 1.0.7 a conversation is bound to a project, so
projectName is required there and omitting it is refused before the question is
sent.
ask_workmatestarts Workmate's full conversation/tool loop in a bounded background job and returns a pollablejobId, so the MCP transport request does not stay open for the full cloud round-trip. Poll that id with the sharedget_job_statustool;cancel_jobfirst previews and only acts withconfirm=true, and it never claims that a request already handed to Workmate was cancelled. The Workmate bundles remain optional and are loaded only at runtime through OSGi/reflection; they are not part of this project's target platform. The tool ships disabled — it sends the question to an external cloud service and Workmate may change the configuration with its own tools — so enable it under Preferences → EDT MCP Server → Tools first.- The OSGi service
com.ditrix.edt.mcp.server.bridge.IEdtMcpBridgelets Workmate/JShell list and call EDT-MCP tools without importing EDT-MCP packages.callToolgoes through the same dispatcher as MCPtools/calland returns its JSON-RPC response.
Two details decide whether this actually works, both measured against Workmate 1.0.5:
- The skill.
ConversationFacadedefaults toraw, under which the cloud answers from the model alone — one assistant message, no tool call, no look at the project.ask_workmatetherefore sendscustom(the skill Workmate's own autopilot uses), which runs the full tool loop. Override withskillNameonly if you know the name is accepted; the cloud refuses most others outright. - The question carries the bridge. Workmate's chat reads a project's
.workmaterules, but this Java path does not, soask_workmateprefixes the question with the bridge instructions and the list of tool NAMES (full descriptions stay behindget_tool_guide, which it calls when it needs one). PassshareMcpTools=falseto send the question verbatim instead.
The same instance is published under the JDK types BiFunction<String,String,String>
(callTool) and Supplier<String> (listTools), both carrying the service property
edt.mcp.bridge=v1. Prefer that alias: it needs no reflection and no access to the
bridge package, which matters for callers whose rules forbid unproven Java API - such
as Workmate's JShell tool.
// Take the context from an ALWAYS-ACTIVE bundle, not from EDT-MCP's own: this bundle
// uses lazy activation, so `Platform.getBundle("com.ditrix.edt.mcp.server")
// .getBundleContext()` can hand back null and the next line then fails with
// "because ctx is null". OSGi services are global, so any live context finds this one.
var bundleContext = org.osgi.framework.FrameworkUtil
    .getBundle(org.eclipse.core.runtime.Platform.class).getBundleContext();
var references = bundleContext.getServiceReferences(
    java.util.function.BiFunction.class, "(edt.mcp.bridge=v1)");
if (references.isEmpty()) {
    throw new IllegalStateException("EDT-MCP bridge service is not registered");
}
var mcp = bundleContext.getService(references.iterator().next());
System.out.println(mcp.apply("get_edt_version", "{}"));
A consumer that prefers the named contract can still resolve it by string name and invoke it reflectively:
var serviceReference = bundleContext.getServiceReference(
    "com.ditrix.edt.mcp.server.bridge.IEdtMcpBridge");
var bridgeService = bundleContext.getService(serviceReference);
try {
    var callTool = bridgeService.getClass().getMethod(
        "callTool", String.class, String.class);
    System.out.println((String) callTool.invoke(
        bridgeService, "get_edt_version", "{}"));
} finally {
    bundleContext.ungetService(serviceReference);
}
Letting Workmate's chat use the bridge
Workmate's agentic chat holds its JShell tool but not JShellSession, and
JShell rejects every call whose repl_session_id it cannot resolve. The chat can
therefore execute code but cannot obtain the one value executing code requires.
EDT-MCP breaks that deadlock: shortly after startup it registers a JShell session
under the constant id edt-mcp (retried in the background while Workmate comes
up, and again if Workmate ever evicts it). Together with jshell_edt_canonical_imports
— a fixed entry in Workmate's own scenario catalogue — both values JShell demands are
constants, so a project's rules can name them literally and nothing has to be passed
around at runtime:
repl_session_id = "edt-mcp"
manual_ids      = ["jshell_edt_canonical_imports"]
tests/TestConfiguration/.workmate/WORKMATE.md
is a working example of such a rules file; copy it into <project>/.workmate/ to give
the chat the same access in your own configuration. Note that the chat cannot reach the
HTTP endpoint at all — java.net.URL, java.net.Socket and ProcessBuilder are on
Workmate's restricted-types list — so the in-process bridge is its only route.
Multi-EDT Proxy
Running more than one EDT instance at once? edt-mcp-proxy is a standalone router that exposes a single, stable MCP endpoint on :8764 and forwards each call to the right EDT-MCP instance by projectName, discovering live instances in the background. It ships as edt-mcp-proxy-<version>.jar alongside the plugin archive in every release. See proxy/README.md for setup, CLI options and configuration.
Available Tools
The full per-tool reference lives in docs/tools/ — one page per
tool (what it does, every parameter, and how it works), generated from the live MCP
server (get_tool_guide) so it never drifts from the code. Index below; re-generate
with python docs/generate_tool_docs.py.
100 tools, grouped by toolset. Full per-tool pages under docs/tools/.
Core
Always-on essentials: project/module navigation, source read, metadata discovery, and the toolset-management tools (list_toolsets / enable_toolset).
| Tool | Description |
|---|---|
enable_toolset | Make additional MCP tool groups visible or hide them. Parameters and examples: get_tool_guide('enable_toolset'). |
get_edt_version | Identify the installed 1C:EDT version. Parameters and examples: get_tool_guide('get_edt_version'). |
get_metadata_details | Inspect metadata objects and members, including managed-form root properties and structure, and a section's command interface. Parameters and examples: get_t… |
get_metadata_objects | Discover metadata objects available in a 1C configuration. Parameters and examples: get_tool_guide('get_metadata_objects'). |
get_module_structure | Discover procedures, functions, regions, and execution contexts in a BSL module. Parameters and examples: get_tool_guide('get_module_structure'). |
get_server_status | Diagnose the EDT MCP server and its feature configuration. Parameters and examples: get_tool_guide('get_server_status'). |
get_tool_guide | Retrieve detailed instructions for an MCP tool. mode=summary lists sections; section=<heading|#anchor>; query=. |
Metadata
Metadata objects: discovery, create/modify/delete/rename/adopt, subsystems, configuration.
| Tool | Description |
|---|---|
adopt_metadata_object | Add a base-configuration object or member to an extension for customization. Parameters and examples: get_tool_guide('adopt_metadata_object'). |
create_launch_config | Configure an EDT runtime client for launching a 1C application. Parameters and examples: get_tool_guide('create_launch_config'). |
create_metadata | Add a new metadata object or member to a configuration. Parameters and examples: get_tool_guide('create_metadata'). |
dcs | Read, author, and losslessly XML-round-trip 1C DCS schemas, settings variants, form conditional appearance, and form dynamic lists. Call action='get' first;… |
delete_launch_config | Remove an unused EDT runtime or attach launch configuration. Two-phase: call once WITHOUT confirm to preview, then again with confirm=true to apply. Paramete… |
delete_metadata | Delete a metadata object or member (FQN-addressed). DESTRUCTIVE and CASCADING: on the md-refactoring path EDT cleans the REFERENCES to the deleted object acr… |
export_common_picture | Inspect or extract the image data of a 1C common picture. Parameters and examples: get_tool_guide('export_common_picture'). |
Code
BSL code: write/read methods, call hierarchy, go-to-definition, references, content assist, queries.
| Tool | Description |
|---|---|
find_references | Discover where a metadata object is used throughout the configuration and BSL code. Parameters and examples: get_tool_guide('find_references'). |
get_content_assist | Find valid BSL completion suggestions at a source-code position. Parameters and examples: get_tool_guide('get_content_assist'). |
get_method_call_hierarchy | Trace which BSL methods call a method or are called by it; optional depth walks the chain transitively for impact analysis (callers only, max 5). Finds STATI… |
get_outgoing_structures | Discover the fields passed to outgoing or qualified BSL method calls. BEST-EFFORT and incomplete by design: only top-level LITERAL keys of the first argument… |
get_symbol_info | Inspect the type and documentation of a BSL symbol at its source location. Parameters and examples: get_tool_guide('get_symbol_info'). |
go_to_definition | Locate the source definition of a BSL symbol or metadata object. Parameters and examples: get_tool_guide('go_to_definition'). |
read_method_source |
Debug
Runtime debugging: launch/attach, breakpoints, step/resume/pause, variables, expression evaluation.
| Tool | Description |
|---|---|
debug_pause | Pause a running 1C debug session now and return where it is executing (thread and stack frames); unlike wait_for_break, it requests the suspend itself. Param… |
debug_status | Check which EDT debug sessions are running or paused. Parameters and examples: get_tool_guide('debug_status'). |
evaluate_expression | Evaluate a BSL expression in a paused debug frame and return the value. WARNING: this executes arbitrary code in the running application - it can change stat… |
get_applications | Discover infobases connected to an EDT project. Parameters and examples: get_tool_guide('get_applications'). |
get_variables | Inspect runtime variables in a paused debug frame. Parameters and examples: get_tool_guide('get_variables'). |
launch | Start a 1C application in EDT debug (default) or run mode. An already-running session is NOT relaunched - the call short-circuits with alreadyRunning:true; r… |
list_breakpoints | Review configured BSL line breakpoints and workspace-wide break-on-error state. Full parameters and examples: call get_tool_guide('list_breakpoints'). |
Testing
YAXUnit unit testing, 1C:Workmate assistance, and shared background-job polling.
| Tool | Description |
|---|---|
ask_workmate | Start a background question to the 1C:Workmate plugin and return its jobId. Hands the question to an EXTERNAL agent: by default (shareMcpTools) Workmate may… (not enabled by default) |
cancel_job | Cancel a background job by jobId. DESTRUCTIVE. Two-phase: call once WITHOUT confirm to see the owning tool, state and progress, then again with confirm=true… |
debug_yaxunit_tests | DEPRECATED alias of run_yaxunit_tests(debug=true) - prefer that instead; the implementation is shared. DEBUG mode, so breakpoints fire: a short start returns… |
get_job_status | Poll any background job by the jobId its owning tool returned: state, progress journal and terminal result. Parameters and examples: get_tool_guide('get_job_… |
run_yaxunit_tests | Run YAXUnit tests as a named background job and return a JUnit Markdown report. The start call waits up to timeout (default and maximum 45s): a short run r… |
Profiling
Performance profiling: start/stop a measurement and read the results.
| Tool | Description |
|---|---|
get_profiling_results | Identify performance hotspots in executed BSL code. Returns the MOST RECENT measurement session GLOBALLY - applicationId only changes the reported active-sta… |
start_profiling | Measure execution time and coverage of BSL code in a debug session. Parameters and examples: get_tool_guide('start_profiling'). |
stop_profiling | Finish measuring BSL performance in a debug session. Parameters and examples: get_tool_guide('stop_profiling'). |
Forms
Forms: layout snapshot, form screenshot, template screenshot, and structural validation of a form model.
| Tool | Description |
|---|---|
get_form_layout_snapshot | Inspect the calculated visual layout of an EDT form. Parameters and examples: get_tool_guide('get_form_layout_snapshot'). |
get_form_screenshot | Visually inspect an EDT form as rendered by the designer. Requires EDT launched with -DnativeFormBufferedLayoutRender=true on Windows; a blank or gray image… |
get_template_screenshot | Visually inspect how a spreadsheet print template renders. Parameters and examples: get_tool_guide('get_template_screenshot'). |
validate_form_model | Check ONE managed form for structural defects: duplicate names or ids, a data path that names no attribute, a button with no command, a handler with no proce… |
Tags
Tag-based organization: list tags and find objects by tag.
| Tool | Description |
|---|---|
get_objects_by_tags | Find metadata objects organized under selected tags. Parameters and examples: get_tool_guide('get_objects_by_tags'). |
get_tags | Discover user-defined tags used to organize project metadata. Parameters and examples: get_tool_guide('get_tags'). |
Translation
Configuration translation via LanguageTool: extract, translate, project info.
| Tool | Description |
|---|---|
generate_translation_strings | Collect translatable strings of a configuration and WRITE the generated keys into the project's translation storage (.lstr/.trans/.dict; storageId, default '… |
get_translation_project_info | Inspect the translation setup of an EDT project. Parameters and examples: get_tool_guide('get_translation_project_info'). |
translate_configuration | SYNCHRONIZE a 1C configuration's translated artifacts with the target languages. Does NOT translate anything itself: it regenerates the artifacts from transl… |
Project
Project operations: clean/revalidate, inspect infobase sessions/update DB, export/import XML, problems and markers, docs.
| Tool | Description |
|---|---|
apply_quick_fix | Apply an EDT quick fix to a validation problem. Parameters and examples: get_tool_guide('apply_quick_fix'). |
build_external_objects | Compile external 1C data processors and reports into deployable files. NOT self-contained: the project needs an associated infobase AND a resolvable 1C runti… |
clean_project | Rebuild an EDT project from the on-disk src/ files and revalidate everything. Direction DISK -> MODEL; slow, and it DISCARDS unsaved in-memory model edits -… |
create_git_branch | Start isolated work on a new Git branch for an EDT project. Parameters and examples: get_tool_guide('create_git_branch'). |
create_infobase | Create a file infobase or register an existing file/cluster infobase and bind it to an EDT project. EDT may open a Designer connection during binding when a… |
create_project | Start a new EDT configuration, extension, or external-objects project. Parameters and examples: get_tool_guide('create_project'). |
delete_infobase | Remove a project's infobase or its standalone-server registration, optionally deleting the database files. DESTRUCTIVE and IRREVERSIBLE. Two-phase: call once… |
Comparison
Read a three-way configuration comparison: start one against two git revisions, expand a node's differences, and read or author the merge-rules file EDT re-applies. Nothing is ever merged - running a merge stays a human action in EDT's comparison window.
| Tool | Description |
|---|---|
compare_configurations | Compare a project's working tree against two git revisions (three-way) and report which top objects differ. Read-only: it never merges and never writes the p… |
get_comparison_node | Expand one node of a comparison started by compare_configurations: three-way property table, form structure, module sections, support state and potential pro… |
merge_rules | Read or author EDT's merge-rules file - the per-node decisions a configuration comparison saves and re-applies when it is launched. Which container to write… |
Git
Run raw git commands (status/diff/commit/push/pull/...) in a project's repository via the 'git' tool. Powerful (it can push, checkout, stash); DISABLED by default - check it in the MCP Server Tools preference tab to enable.
| Tool | Description |
|---|---|
git | Run a git command in a project's repository through the real git CLI, sent as a shell-style string. Only a whitelisted set of subcommands runs, and the write… (not enabled by default) |
Infobase sessions and database updates
Before applying update_database to a standalone-server application, call
infobase_sessions(action='list', projectName='...', applicationId='...'). A readable empty
sessions array proves no sessions exist; reachable=false instead names why inspection was
impossible and must never be read as an empty list. Any non-agent session blocks the default
update preflight. Clear blockers with
infobase_sessions(action='terminate', projectName='...', applicationId='...', all=true, confirm=true), then retry the update. A Designer session may be EDT's update agent OR a
human Configurator, and EDT exposes no discriminator. It is therefore not treated as a
blocker — EDT's own agent is present during every normal update — and all=true always
skips it. Terminating one is possible only by its exact full session UUID.
Three-way configuration comparison
A configuration can be compared against two git revisions and read node by node through MCP. The family is read-only about your project: it never merges and never writes the project — the plugin holds no merge starter at all, so running a merge stays a human action in EDT's comparison window.
compare_configurationsstarts the comparison and returns ajobId; poll it withget_job_status. The sides aremain— the project's WORKING TREE as EDT currently has it, uncommitted edits included —other(otherRevision) andancestor(ancestorRevision), each anything git resolves in that repository: a branch, a tag,HEAD~1, a commit id. BeyondprojectName/otherRevision/ancestorRevisionit takesscope(qualified names such asCatalog.Products, Russian type tokens accepted; omitting it compares the WHOLE configuration),mergeRulesFile(decisions applied BEFORE the comparison starts — the file is read, never written),waitSeconds(0 to 25, default 5 — how long THIS call waits for its job snapshot, never the job's own budget),limit(how many top objects the report lists; the counters above the table always describe the whole comparison) andchangedOnly(defaulttrue; a node that has not been compared yet is listed anyway, because "not answered yet" is not "equal").get_comparison_nodeexpands ONE node of that comparison: a three-way property table, the per-side form structure, the module section list, the vendor-support state, the child outline and the engine's POTENTIAL problems. Address the node byobjectFqn(Russian or English type tokens both work) or bynodeIdfrom the report, never both;side(mainby default,other,ancestor) says which side the FQN is written in;depth(1 to 5),limit(1 to 500) andwaitSeconds(0 to 25) size the answer. The comparison tree is built lazily, so a subtree the engine has not reached is reported as unfinished — never as "no differences".merge_rulesreads and authors the sparse XML merge-rules file the comparison saves and re-applies when it is launched with it.modeisreadorwrite;filePathis absolute, and for a WRITE its extension must be spelled in LOWER CASE, because EDT's own reader compares it case-sensitively —mode: "read"andbasedOnare lenient about case, since those files are opened by this server and never by the platform (read takes the.xmlor the a comparison saves; write takes , which every supported EDT reads, or , which EDT 2026.1 reads and EDT 2026.2 refuses outright; a carries ONE entry, named by the exact string over the three project names, so a later comparison over the same three projects re-applies it even with other revisions — and since is legal inside a project name that string is not unique to one triple, so a comparison finds nothing here only when its OWN three names spell something else; and an existing file is replaced only when names that SAME file — any other write over an existing file is refused); carries an existing file's decisions forward; is , where is the key chain below the root ( = the whole configuration, = a collection, and = one object, keyed by its main:other:ancestor names with for a side that has no such object) and is one of , , , ; and complete the list. Authoring the DOCUMENT needs no running comparison; naming a 's entry does, so a is refused without one. The report names the container it wrote and which EDT reads it, and it says which of THREE validation outcomes happened: a comparison whose tree has FINISHED checks every rule against what its own node allows; a comparison that answers while its tree cannot be read names the zip's entry but checks nothing — reported , or refused outright if you passed ; with no comparison at all the file is authored from names and also reported .
One comparison at a time, and it stays open when it finishes. EDT runs exactly one
comparison per workbench, so a second compare_configurations while one is live is refused
naming the live comparison — it is never queued, and a refusal means nothing was started. A
comparison that has FINISHED still holds that single slot, because its session is what
get_comparison_node reads. cancel_job cannot end it then: once the comparison
finishes its background job is terminal, and a terminal job is answered without this tool's
cancellation handler ever running. Give the slot back by calling compare_configurations
with releaseComparisonId alone; cancel_job is the right call only while the comparison
is still RUNNING. A comparison nobody comes back to is reclaimed by an idle TTL of 30
minutes as part of answering the next launch, so a forgotten one delays the next comparison
rather than blocking it until EDT restarts.
XDTO Packages
1C XDTO packages (XDTOPackage) can be authored end-to-end through MCP, down to their
package-local structure, without hand-editing XML:
-
create_metadata/modify_metadata/delete_metadataaddress XDTO package members by FQN, layered on top of the existing top-levelXDTOPackage.<Name>create/delete:XDTOPackage.<Package>.ObjectType.<Type>— an ObjectType in the package (optional flags:open,abstract,mixed,ordered,sequenced).XDTOPackage.<Package>.Property.<Name>— a package-global Property.XDTOPackage.<Package>.ObjectType.<Type>.Property.<Name>— a Property nested in an ObjectType.
A Property's
typeaccepts a built-in XSD type name (e.g.string), the exact name of another ObjectType already in the same package (a same-package reference), or an explicit{nsUri, name}pair; optionallowerBound/upperBound,nillable,fixed+defaultround out the vocabulary. Seeget_tool_guide('create_metadata')for the full parameter list. -
validate_xdto_packageruns EDT's own configuration validation scoped to one package and returns a one-line verdict — valid, problems found, or undecided when nothing matched but a marker's location could not be resolved — plus any problems found (e.g. a Property left referencing an ObjectType that was since deleted) — a thin, read-only wrapper overget_project_errors, handy right after authoring or editing package members.
Output Formats
Each tool declares a response type (IMcpTool.getResponseType()). The default — and the most common type — is Markdown: any tool that does not override getResponseType() returns Markdown as an EmbeddedResource with mimeType: text/markdown. The non-default types are enumerated exhaustively below; everything not listed here is Markdown.
Response format policy (Markdown vs JSON)
structuredContent/JSON exists for clients to consume, not for the agent to read: it is justified only by verbatim round-trip of identifiers, machine-structured positions, a declared outputSchema, or UI-rendered data. Markdown is the default because it is more token-efficient and directly readable.
A tool returns JSON only when its result carries at least one of:
- (a) round-trip IDs another tool consumes (e.g. a created object's FQN, a launch/application ID, a breakpoint ID);
- (b) machine-structured positions (e.g. an error line/column);
- (c) a declared
outputSchema; - (d) UI-rendered data.
An action/confirmation/status result with none of these returns Markdown. write_module_source is the reference Markdown action tool; revalidate_objects, export_configuration_to_xml, and import_configuration_from_xml follow it (status + paths/counts, no round-trip data).
Which tool families stay JSON, and why:
- metadata-writes (
create_metadata,modify_metadata,delete_metadata, viaAbstractMetadataWriteTool) — return the edited object's round-trip FQN (a); - debug / profiling tools — return launch / application / breakpoint IDs and live session state consumed by follow-up calls (a);
validate_query— returns the error line/column (b);list_configurations— returns config identities consumed by other tools (a);clean_project/update_database/infobase_sessions— return machine-readable status whose JSON shape is asserted by e2e (d-like contract).
Errors are reported the same way regardless of a tool's normal format — see the Error contract below.
- Markdown tools (the default): every tool that is not listed under another type below, returned as an EmbeddedResource with
mimeType: text/markdown. This includes all read/list/search/navigation tools that emit human-readable reports — for examplelist_projects(which switches to JSON when called withformat='json'),list_modules,list_subsystems,list_configurations,get_project_errors,validate_xdto_package,get_markers,get_problem_summary,get_check_description,get_metadata_objects,get_metadata_details,get_module_structure,get_subsystem_content,get_symbol_info,get_method_call_hierarchy,get_objects_by_tags,get_tags,get_platform_documentation,find_references,go_to_definition,search_in_code,search_in_dcs,read_module_source,read_method_source,write_module_source,rename_metadata_object,run_yaxunit_tests,debug_yaxunit_tests,terminate_launch,revalidate_objects,export_configuration_to_xml,export_configuration_to_file,import_configuration_from_xml,import_project_from_file, and all three LanguageTool tools (generate_translation_strings,translate_configuration,get_translation_project_info). (list_configurationsis the exception among thelist_*tools — it returns JSON; see below.) - YAML tools:
get_configuration_properties— returns a human-readable YAML body as an EmbeddedResource (resource named*.yaml,mimeType: text/yaml). - JSON tools (return JSON with
structuredContent):get_server_status,get_applications,infobase_sessions,create_infobase,delete_infobase,get_content_assist,get_variables,get_profiling_results,list_configurations,list_breakpoints, , , , , , , , , , , , , , , , , , when called with , plus the metadata-write tools that inherit JSON from (, , ).
DCS XML transfers
dcs with action="get", type="schema", and format="xml" returns
{success,totalChars,offset,hasMore,nextOffset?,hash,xml}. Begin at offset=0, append
xml, and while hasMore is true repeat with the numeric nextOffset; require the
20-character hash to stay the same on every page so a mid-transfer schema change is
detected. The server measures each escaped JSON envelope and shrinks its XML chunk before
returning if necessary, so the 100000-character content guard never truncates XML. Each
page request re-serializes the whole schema, making transfer cost O(pages × schema size);
raise limit when the client tolerates larger results to reduce the page count. Concatenate
all chunks, then send the WHOLE document in ONE replace as body.xml; writes are not chunked. See
dcs for the paging loop and replacement example.
Error contract
Whatever a tool's normal output format above, it reports a failure the same way: a JSON payload {"success": false, "error": "<message>"} that the server delivers as a structured tool error (isError: true) regardless of the declared response type. The error field is always present (a null exception message is coalesced to Unknown error) and the message carries no redundant Error: prefix. A client detects failure via isError / success: false and reads error for the reason — no markdown parsing required. Success and purely informational results (for example "No references found", or a not-found accompanied by a list of valid alternatives) stay in the tool's natural format.
Tool annotations
Every tool in the tools/list response carries an annotations object with the standard MCP behavioral hints, so a client can reason about a tool's effect before calling it. The hints are derived centrally from the tool name (a tool may override them):
| Hint | Meaning | When set |
|---|---|---|
readOnlyHint | The tool does not modify the workspace | true for get_* / list_* / read_* / search_* / find_* / validate_* and for go_to_definition, debug_status, wait_for_break; false for write and destructive tools |
idempotentHint | Repeating the call has no additional effect | true for the read-only tools above |
destructiveHint | The tool may perform a destructive or irreversible update | true for tools such as delete_metadata, update_database, infobase_sessions, rename_metadata_object, delete_project, and cancel_job |
openWorldHint | The tool interacts with an external/open world | false for every tool but git, which sets it true: push / pull / fetch reach a remote |
Only hints that apply are emitted; unset hints are omitted from the JSON. Tools that write but are not destructive (for example write_module_source, create_metadata) carry readOnlyHint: false and destructiveHint: false.
API Endpoints
| Endpoint | Method | Description |
|---|---|---|
/mcp | POST | MCP JSON-RPC (initialize, tools/list, tools/call) |
/mcp | GET | Server info |
/health | GET | Health check |
Security & trust model
The MCP server is a local developer tool and is secured for that model:
- Loopback bind by default. The server listens on
127.0.0.1only. To expose it on all interfaces, enable Allow remote (non-loopback) access in MCP preferences — which requires an auth token: with remote access on and the token empty the server refuses to start rather than listening unauthenticated on every interface. - Optional shared-token auth. Set an Auth token in MCP preferences to require
Authorization: Bearer <token>(scheme case-insensitive, or the raw token) on every/mcprequest. An empty token disables authentication — the default, and allowed only for the loopback bind./healthis always unauthenticated (liveness only). Prefer printable ASCII for the token. A header value is bytes: a code point above U+00FF has none, so no client can send it — preferences warn about such a token (a Cyrillic one, say) rather than leaving you a run of unexplained 401s. Latin-1 characters are deliverable but not portable: they work with clients that serialise header values as ISO-8859-1 (fetch, Pythonrequests) and not with one that writes the string UTF-8. Control characters are likewise accepted by some clients and rejected by others. Neither is warned about, because both can be made to work; ASCII is simply the choice that works everywhere. - Clearing the token does not reopen a remote listener. Saving preferences does not rebind the running server, so a listener that was opened on all interfaces stays open. Rather than serve the network unauthenticated, it then refuses every request until a token is set again or the server is restarted onto loopback. The endpoint line in preferences says so while that is the case, so the URL it shows is never one it knows to be unusable.
- Bounded request bodies. A
/mcprequest body larger than 4 MiB is refused with413instead of being buffered, matching the cap the proxy already applies. - Loopback origins only. A browser request whose
Originis notlocalhost/127.0.0.1/[::1](http or https, any port) is refused with403before anything runs — this is the whole browser-CSRF defence, since a default install has no token. The literalnull(what a sandboxed iframe, adata:URL and a cross-origin redirect all send),file://andvscode-webview://are not accepted: each is producible by a hostile page, and a VS Code extension reaches the server from its extension host, which sends no at all. A request with no is a non-browser client and is admitted; access control for those is the loopback bind plus the optional token.
Destructive-operation consent
Before a destructive operation, the server can ask you (the human at the EDT
workbench) to confirm — so the AI cannot silently delete data or terminate live sessions.
The gated tools are delete_metadata, rename_metadata_object, delete_project,
delete_infobase, update_database, infobase_sessions, evaluate_expression (arbitrary BSL in the running 1C app —
its effect cannot be classified from the call, so it always asks), git for its write-capable
subcommands, dcs only for a destructive retype, modify_metadata only when it changes
an object's or attribute's data type (a benign property edit is never gated), and merge_rules
only when a write replaces the file basedOn names (a write to a path that holds no file is
never gated).
Configure it in Window → Preferences → MCP Server:
- Consent level (General tab), one of:
- Ask always (default) — every gated operation shows a confirmation dialog with a compact preview (the tool, what will be affected, a count and the top few names) and Allow / Reject / Allow for this session buttons (the last remembers that one tool until EDT is restarted).
- Allow all — never ask; every destructive write proceeds. Use this for unattended/automated runs.
- Ask, except allowed tools — ask, except for the tools you tick in the Tools tab.
- Per-tool checkbox (Tools tab) — active only at the Ask, except allowed tools level: tick a tool to let it run destructively without a prompt.
Automation / CI bypass. Because the confirmation dialog would block a headless or automated run,
set the environment variable EDT_MCP_DESTRUCTIVE_CONSENT=allow on the EDT process before launch —
it overrides the preference and lets every gated operation proceed without a dialog (the same knob the
e2e suite uses). Every such allow is logged with the tool name and its preview, so an unattended run
leaves an audit trail in the EDT log — with one deliberate omission. Where a preview's content is the
caller's OWN text it can hold a password or a token, so the audit records its length and never any
part of it: evaluate_expression's BSL always, and git for the subcommands that carry caller text
— a message (commit, tag, stash, merge, pull) or a transmitted server option (push,
fetch). The rest is recorded in full — restore <path> and branch -D <name> destroy something and
leave no commit or reflog behind, so that line is the only record of what they hit. The human at the
dialog always sees the whole command, redacted or not. The dialog only ever appears on a live UI
session at the Ask level.
A headless EDT REFUSES a gated operation (it still never blocks): with no workbench window there is nobody to ask, and the gate's job is to stop a destructive write that no human agreed to — so consent for an unattended run has to come from the operator at launch, via the environment variable above. The error names it. Previously the absence of a display granted consent instead, which meant an agent could remove the gate simply by starting EDT headless.
The prompt is time-bounded. A confirmation dialog waits at most 120 seconds for a human to
answer (below common MCP client request budgets, so a caller gets an actionable error instead of its
own transport timing out first). If nobody answers in time, the operation auto-rejects — nothing is
changed — with an error naming the tool, the 120 s budget, and the three ways to proceed: allow the
tool via Preferences (Allow all or per-tool), set EDT_MCP_DESTRUCTIVE_CONSENT=allow for unattended
runs, or re-run the call and answer the dialog promptly.
Vendor support
A configuration taken on vendor support can lock objects (its support rule does not allow
changes). The writing tools respect that lock the way EDT's own editors do: create_metadata,
modify_metadata, delete_metadata, rename_metadata_object, write_module_source and dcs
refuse a write to a locked object with an error naming it, and change nothing;
translate_configuration refuses an in-place run when the configuration or any object in it is
locked, naming the first one; the orphaned role-rights sweep of resync_to_disk skips a locked
role and says so, and its cleanDanglingReferences cleanup leaves a locked configuration's
entries in place, reports them and says why. delete_metadata marks a
support-derived platform prohibition supportLock=true, and force=true does not override it.
When EDT's support check cannot be answered, the write is refused (fail closed). A configuration
extension and an external data processor/report project are never locked. The way out is an
extension (adopt_metadata_object) or the user allowing changes in EDT's support settings; the
server never changes support settings itself. A change to the configuration root itself
(modify_metadata on Configuration) is judged on the root, and for a locked root only the support
settings help: an extension's root is its own and describes the extension, not the configuration it
extends. get_metadata_details shows one
Vendor support: line for a locked object.
Infobase authentication dialog
When a target infobase has a user list, connecting to it during update_database or launch
can raise 1C's blocking "Configure Infobase access Settings" login dialog. To keep unattended MCP
calls from hanging on it, the server auto-cancels that dialog while a tool is running — the
MCP-triggered connect fails fast with a hint to set_infobase_credentials instead of blocking forever
(issue #194). Store the credentials once with set_infobase_credentials and the connect no longer
needs the dialog.
The auto-cancel is activity-scoped: it fires only while an MCP tool is in flight (plus a short grace window for the asynchronous read-back that follows a tool). So when the MCP server is idle, you can open EDT's "Configure Infobase access" dialog by hand in the GUI and use it normally — the credentials you enter are stored into EDT's encrypted Secure Storage (the leak-free path), exactly as the configurator does it. Only dialogs raised by MCP activity are cancelled; a human configuring credentials between agent runs is never interrupted. (The Secure-Storage password-hint dialog stays suppressed unconditionally — it is internal and never human-configured.)
Automation / CI bypass. The auto-cancel is on by default. To turn it off — e.g. to debug the
login flow interactively, or on a stand where you want the prompt to appear even during MCP calls — set
the environment variable EDT_MCP_SUPPRESS_AUTH_DIALOG=false (also 0 / no) on the EDT process
before launch. Any other value — or leaving it unset — keeps auto-cancel enabled, so an unattended run
never regresses into a hang.
Metadata Tags
Organize your metadata objects with custom tags for easier navigation and filtering.
Why Use Tags?
Tags help you:
- Group related objects across different metadata types (e.g., all objects for a specific feature)
- Quickly find objects in large configurations
- Filter the Navigator to focus on specific areas of the project
- Share object organization with your team via version control
Getting Started
Assigning Tags to Objects:
- Right-click on any metadata object in the Navigator
- Select Tags from the context menu
- Check the tags you want to assign, or select Manage Tags... to create new ones
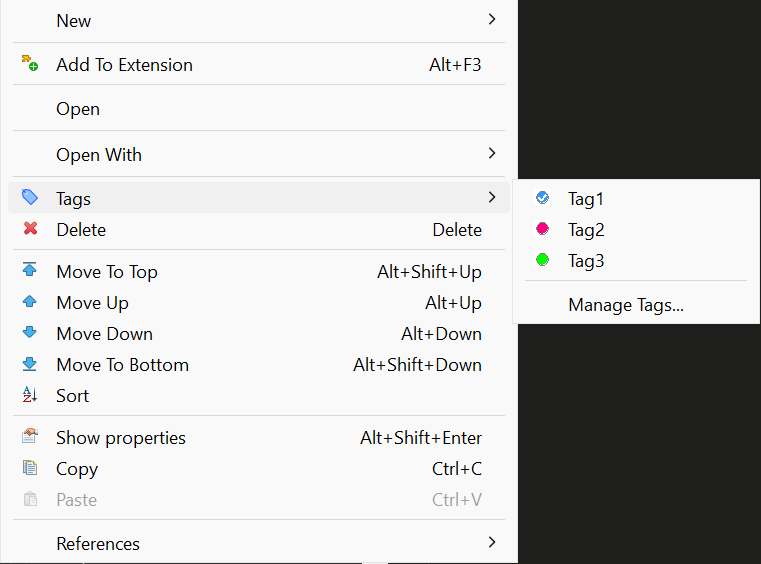
Managing Tags:
In the Manage Tags dialog you can:
- Create new tags with custom names, colors, and descriptions
- Edit existing tags (name, color, description)
- Delete tags
- See all available tags for the project
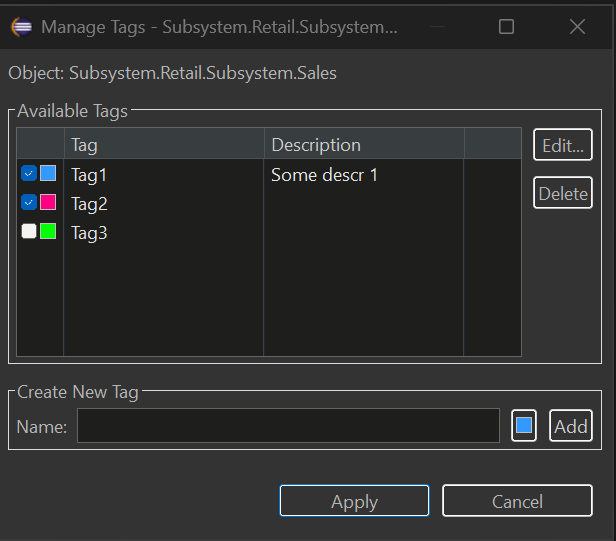
Viewing Tags in Navigator
Tagged objects show their tags as a suffix in the Navigator tree:
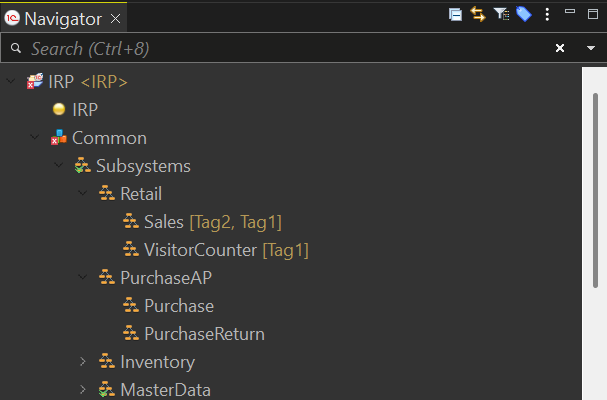
To enable/disable tag display:
- Window → Preferences → General → Appearance → Label Decorations
- Toggle "Metadata Tags Decorator"
Filtering Navigator by Tags
Filter the entire Navigator to show only objects with specific tags:
- Click the tag filter button in the Navigator toolbar (or right-click → Tags → Filter by Tag...)
- Select one or more tags
- Click Set to apply the filter
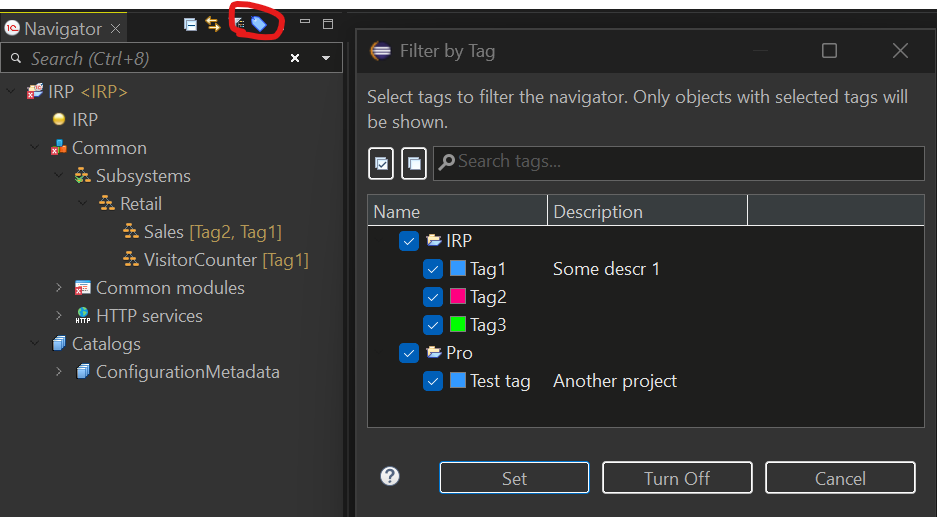
The Navigator will show only:
- Objects that have ANY of the selected tags
- Parent folders containing matching objects
To clear the filter: Click Turn Off in the dialog or use the toolbar button again.
Keyboard Shortcuts for Tags
Quickly toggle tags on selected objects using keyboard shortcuts:
| Shortcut | Action |
|---|---|
| Ctrl+Alt+1 | Toggle 1st tag |
| Ctrl+Alt+2 | Toggle 2nd tag |
| ... | ... |
| Ctrl+Alt+9 | Toggle 9th tag |
| Ctrl+Alt+0 | Toggle 10th tag |
Features:
- Works with multiple selected objects
- Supports cross-project selection (each object uses tags from its own project)
- Pressing the same shortcut again removes the tag (toggle behavior)
- Tag order is configurable in the Manage Tags dialog (Move Up/Move Down buttons)
To customize shortcuts: Window → Preferences → General → Keys → search for "Toggle Tag"
Filtering Untagged Objects
Find metadata objects that haven't been tagged yet:
- Open Filter by Tag dialog (toolbar button or Tags → Filter by Tag...)
- Check the "Show untagged objects only" checkbox
- Click Set
The Navigator will show only objects that have no tags assigned, making it easy to identify objects that need categorization.
Multi-Select Tag Assignment
Assign or remove tags from multiple objects at once:
- Select multiple objects in the Navigator (Ctrl+Click or Shift+Click)
- Right-click → Tags
- Select a tag to toggle it on/off for ALL selected objects
Behavior:
- ✓ Checked = all selected objects have this tag
- ☐ Unchecked = none of the selected objects have this tag
- When objects are from different projects, only objects from projects that have the tag will be affected
Tag Filter View
For advanced filtering across multiple projects, use the Tag Filter View:
Window → Show View → Other → MCP Server → Tag Filter
This view provides:
- Left panel: Select tags from all projects in your workspace
- Right panel: See all matching objects with search and navigation
- Search: Filter results by object name using regex
- Double-click: Navigate directly to the object
Where Tags Are Stored
Tags are stored in .settings/metadata-tags.yaml file in each project. This file:
- Can be committed to version control (VCS friendly)
- Is automatically updated when you rename or delete objects
- Uses YAML format for easy readability
Example:
assignments:
  CommonModule.Utils:
    - Utils
  Document.SalesOrder:
    - Important
    - Sales
tags:
  - color: '#FF0000'
    description: Critical business logic
    name: Important
  - color: '#00FF00'
    description: ''
    name: Utils
  - color: '#0066FF'
    description: Sales department documents
    name: Sales
Metadata Groups
Organize your Navigator tree with custom groups to create a logical folder structure for metadata objects.
Why Use Groups?
Groups help you:
- Create custom folder hierarchy in the Navigator tree
- Organize objects by business area, feature, or any logical structure
- Navigate large configurations faster with nested groups
- Separate grouped objects from ungrouped ones
Getting Started
Creating a Group:
- Right-click on any metadata folder (e.g., Catalogs, Common modules) in the Navigator
- Select New Group... from the context menu
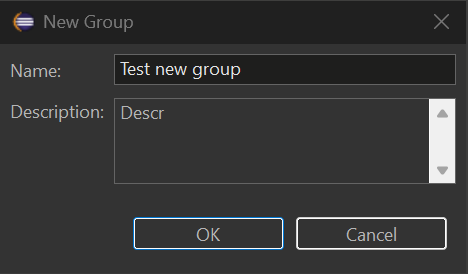
- Enter the group name and optional description
- Click OK to create the group
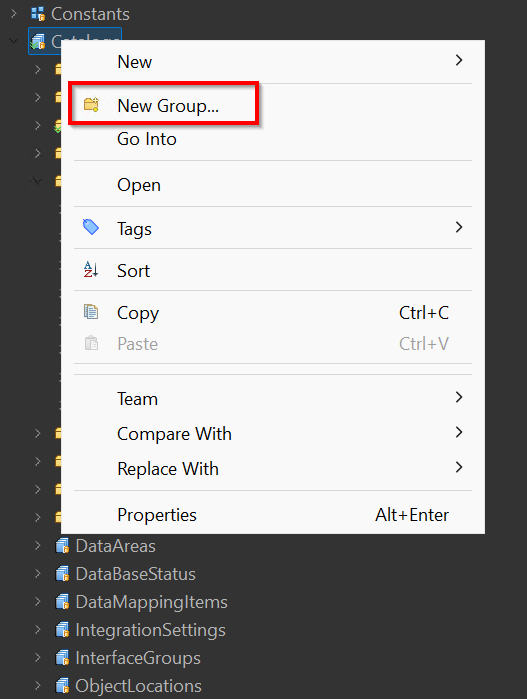
Create Group Dialog:
Adding Objects to a Group:
- Right-click on any metadata object in the Navigator
- Select Add to Group...
- Choose the target group from the list
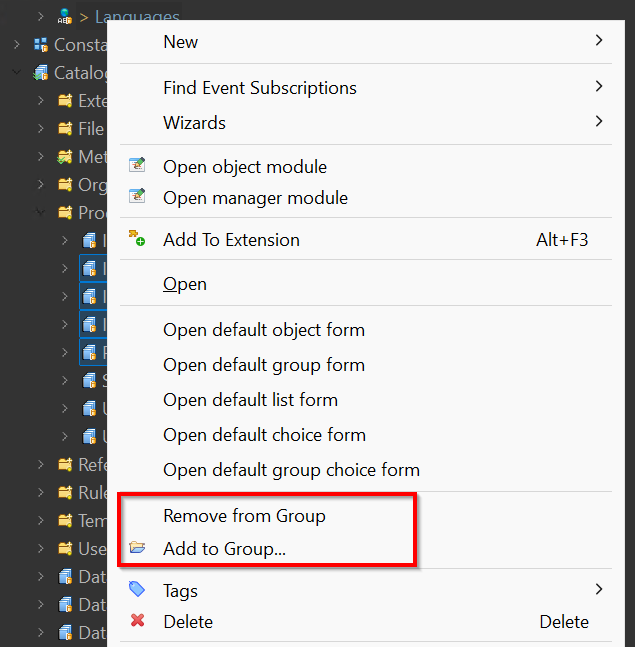
Removing Objects from a Group:
- Right-click on an object inside a group
- Select Remove from Group
Viewing Groups in Navigator
Grouped objects appear inside their group folders in the Navigator tree:
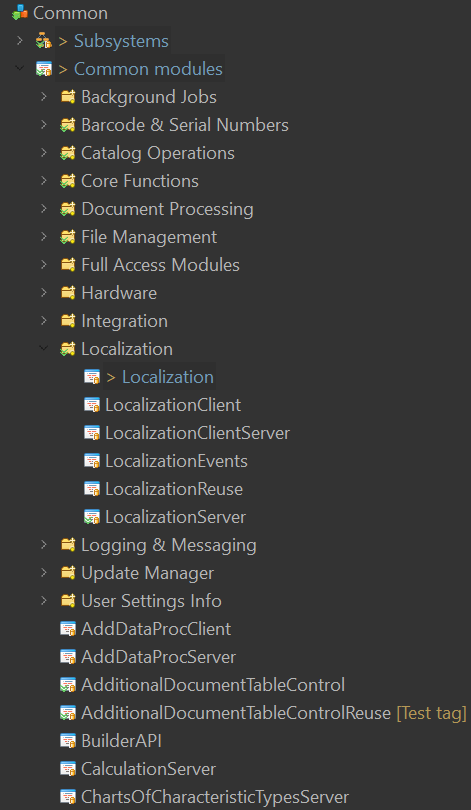
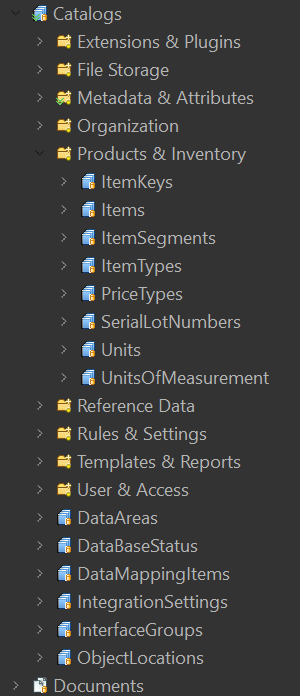
Key Features:
- Groups are created per metadata collection (Catalogs, Common modules, Documents, etc.)
- Objects inside groups are still accessible via standard EDT navigation
- Ungrouped objects appear at the end of the list
- Use the Hide Groups toggle button in the Navigator toolbar to temporarily hide virtual group folders and show grouped objects in their original collections again
Group Operations
| Action | How to Do It |
|---|---|
| Create group | Right-click folder → New Group... |
| Add object to group | Right-click object → Add to Group... |
| Remove from group | Right-click object in group → Remove from Group |
| Copy group name | Select group → Ctrl+C |
| Delete group | Right-click group → Delete |
| Rename group | Right-click group → Rename... |
| Hide/show groups | Click Hide Groups in the Navigator toolbar |
Where Groups Are Stored
Groups are stored in .settings/groups.yaml file in each project. This file:
- Can be committed to version control (VCS friendly)
- Uses YAML format for easy readability
- Is automatically updated when you rename or delete objects
Example:
groups:
- name: "Products & Inventory"
  description: "Product and inventory catalogs"
  path: Catalog
  order: 0
  children:
    - Catalog.ItemKeys
    - Catalog.Items
    - Catalog.ItemSegments
    - Catalog.Units
    - Catalog.UnitsOfMeasurement
- name: "Organization"
  description: "Organization structure catalogs"
  path: Catalog
  order: 1
  children:
    - Catalog.Companies
    - Catalog.Stores
- name: "Core Functions"
  description: "Core shared functions used across the application"
  path: CommonModule
  order: 0
  children:
    - CommonModule.CommonFunctionsClient
    - CommonModule.CommonFunctionsServer
    - CommonModule.CommonFunctionsClientServer
- name: "Localization"
  description: "Multi-language support modules"
  path: CommonModule
  order: 1
  children:
    - CommonModule.Localization
    - CommonModule.LocalizationClient
    - CommonModule.LocalizationServer
    - CommonModule.LocalizationReuse
Building from source
The plugin is a Maven/Tycho project under mcp/. CI builds it via .github/workflows/build.yml; the same flow can be run locally with source/compile.sh.
Prerequisites
- JDK 25 (e.g. Temurin) - Tycho 5 needs JDK 21+ to run and reads the platform's Java 25 class files; the plugin itself is still compiled to Java 17
- Apache Maven 3.9+ (no
mvnwwrapper is committed — install Maven manually or via a package manager:winget, Homebrew,apt, SDKMAN, etc.) bash(Git Bash on Windows works) and eitherzipor thejarbinary that ships with the JDK- Network access to
https://edt.1c.ru/,https://download.eclipse.org/and Maven Central — Tycho downloads the EDT p2 repository and Eclipse SDK on the first run (hundreds of MB, cached afterwards under~/.m2/)
Quick start
# from the repo root
bash source/compile.sh --skip-tests
Output:
source/dist/MCP-EDT.v<VERSION>.zip
This is a valid p2 update site — install via EDT → Help → Install New Software → Add → Archive….
Script options
source/compile.sh accepts every path as a flag (with matching environment-variable fallback) so it can be driven from CI or run against an out-of-tree checkout:
| Flag | ENV fallback | Default | Meaning |
|---|---|---|---|
--skip-tests | — | off | Skip Maven Surefire tests |
--version X.Y.Z | — | parsed from README.md, falls back to dev | Version label used in the output zip name |
--archive-prefix PREFIX | — | MCP-EDT.v | Archive name prefix (final name: <prefix><version>.zip) |
--project-root PATH | EDT_MCP_PROJECT_ROOT | parent of script dir | Repo root containing mcp/ |
--mcp-dir PATH | — | <project-root>/mcp | Maven project directory |
--repo-dir PATH | — | <project-root>/mcp/repositories/com.ditrix.edt.mcp.server.repository/target/repository | Tycho p2 output to repackage |
--output-dir PATH | EDT_MCP_OUTPUT_DIR | <script-dir>/dist | Where the final zip lands |
--java-home PATH | JAVA_HOME | — | JDK 25 home; if set, prepended to PATH for Maven |
--maven-home PATH | MAVEN_HOME / M2_HOME | — | Maven home (uses <maven-home>/bin/mvn); otherwise falls back to mvn on PATH |
-h, --help | — | — | Show help |
Examples
# Self-contained invocation, no env tweaks required
bash source/compile.sh \
    --java-home "/c/Program Files/Java/jdk-25" \
    --maven-home /d/Soft/maven \
    --skip-tests \
    --version 1.27.1

# Drop the artifact somewhere else
bash source/compile.sh --output-dir /tmp/edt-mcp-builds

# Same, configured via environment
JAVA_HOME="/c/Program Files/Java/jdk-25" \
MAVEN_HOME=/d/Soft/maven \
EDT_MCP_OUTPUT_DIR=/tmp/edt-mcp-builds \
bash source/compile.sh
Notes
- A full first build pulls the EDT 2026.2 p2 repository (
mcp/targets/default/default.target) and the Eclipse 2025-12 release — expect several minutes. Subsequent builds run in ~1 minute thanks to the local p2 cache. bash source/verify-oldest-platform.sh <edt-install-dir>compiles the same sources against an installed older EDT instead, which is what keeps the single-build claim honest: the manifest cannot express "references no API that only the newest release has", but a compile against the older one proves it. Run it when the target platform or a call into an EDT API changes. It needs a local EDT installation, because 1C publishes only the current service release of each major online and deletes the previous one. Two installations are worth keeping:- 2026.1 — the oldest supported major:
bash source/verify-oldest-platform.sh <2026.1-install-dir>(the defaults). - 2026.2.0 — the previous service release of the current major:
bash source/verify-oldest-platform.sh <2026.2.0-install-dir> --ee JavaSE-25 --keep-svg(its bundles require Java 25, so without the flags platform resolution fails before any API is tested). CI cannot cover it: theruby/2026.2/channel now serves 2026.2.1 and 2026.2.0's jars are gone from it, so a local install is the only place it still exists. Re-pinning CI forward (.github/scripts/edt-pin.sh) is a one-way door, which is why this check is the thing that keeps the claim "still loads on 2026.2.0" honest.
- 2026.1 — the oldest supported major:
- The output zip uses forward-slash entries (produced by
jarwhenzipis unavailable) so it installs cleanly on both Windows and Linux EDT instances. source/dist/is gitignored; only the script itself is tracked.
AI-assisted development: the edt-mcp-autopilot skill
This repository ships a Claude Code project skill at .claude/skills/edt-mcp-autopilot/ that takes a whole task or issue end-to-end with minimal human input, using a multi-agent, Spec-Driven (SDD) pipeline. The code-conduct it follows lives in CLAUDE.md and the sibling skills under .claude/skills/.
Pipeline (phases): study the task → documentation researchers → several waves of code researchers (loop-until-dry) → adversarial critics (refuted findings dropped, "rework" bounced back) → an architect that synthesises a spec and a file-disjoint developer partition → N parallel developers → a 3–4 reviewer loop until clean → build + unit tests → live-stand scenarios → a Russian issue comment and a pull request.
How to run (Claude Code): the skill is auto-discovered from .claude/skills/. Invoke it with
/edt-mcp-autopilot <issue number or task description>
It runs unattended: the only mandatory human touchpoint is confirming the live-stand result before shipping; principal design questions are posted to the issue and polled until answered. The heavy fan-out runs through the Claude Code Workflow tool (the two scripts under references/), orchestrated by the main session as a "conductor". Scale the fan-out with the size argument (small / medium / large).
⚠️ This skill consumes a LOT of tokens
It deliberately spawns many subagents — documentation and code researchers in waves, a critic panel, parallel developers, and a cyclic reviewer pool. Measured cost per real task in this repository (subagent tokens only — the conductor, the Maven build and the live-stand verification add more on top):
| Phase | Subagents | Subagent tokens | Wall time |
|---|---|---|---|
| Discover (research → critics → architect) | ~8–9 | ~0.6–0.9 M | ~15 min |
| Build (parallel developers → reviewer loop) | ~11–15 | ~0.7–0.8 M | ~15 min |
So a single task's discover + build phases alone are roughly 20–25 subagents and ~1.3–1.8 M subagent tokens; a full end-to-end task (with the conductor, the builds, golden regeneration and live-stand checks) typically runs several million tokens and 30–60+ minutes. A misconfigured run can be far worse — an early, pre-hardened version once burned ~9.8 M tokens / ~210 agents on a no-op before the guard rails were added.
Use it for substantial whole-task work — a feature, a non-trivial bug, or a new tool — not for small edits or quick questions, where working directly is far cheaper.
Requirements
- 1C:EDT 2026.1 or 2026.2 (Ruby)
- Java 17+ (EDT 2026.2 itself runs on Java 25 — it ships its own JRE)