SearxNcrawl
Web search via your own SearXNG instance and/or You.com, plus page and site crawling to deduplicated Markdown with Crawl4AI and Playwright, including pages behind a login.
Install SearxNcrawl
Pick your client, then add it in one click or paste the config.
~/Library/Application Support/Claude/claude_desktop_config.json{
"mcpServers": {
"dasdigitalemomentum-searxncrawl": {
"command": "uvx",
"args": [
"searxncrawl"
]
}
}
}
Settings → Developer → Edit Config, merge this into mcpServers, then fully quit and reopen Claude Desktop.
Automated check passed— started and listed 3 tools correctly (16d ago).
Overview
Tools3
What SearxNcrawl lets your agent do. Expand a tool for its parameters.
Security & health
What it can reach and how reliably it runs — from our own checks, not the maintainer’s claims.
Recent health check succeeded.
What it can do
From the 3 tools this server returned when we ran it.
Observed 2026-10-24 in an isolated sandbox. A description of reach, not a security audit.
Supply-chain signal
No high-severity advisories surfaced by our automated scan.
Scanned 2d ago via OSV.dev · searxncrawl (PyPI)
Adoption & maintenance
Factual signals from GitHub, npm, and our automated checks — not a rating.
From the project README


Website · Quick start · Docs · Developers · Changelog
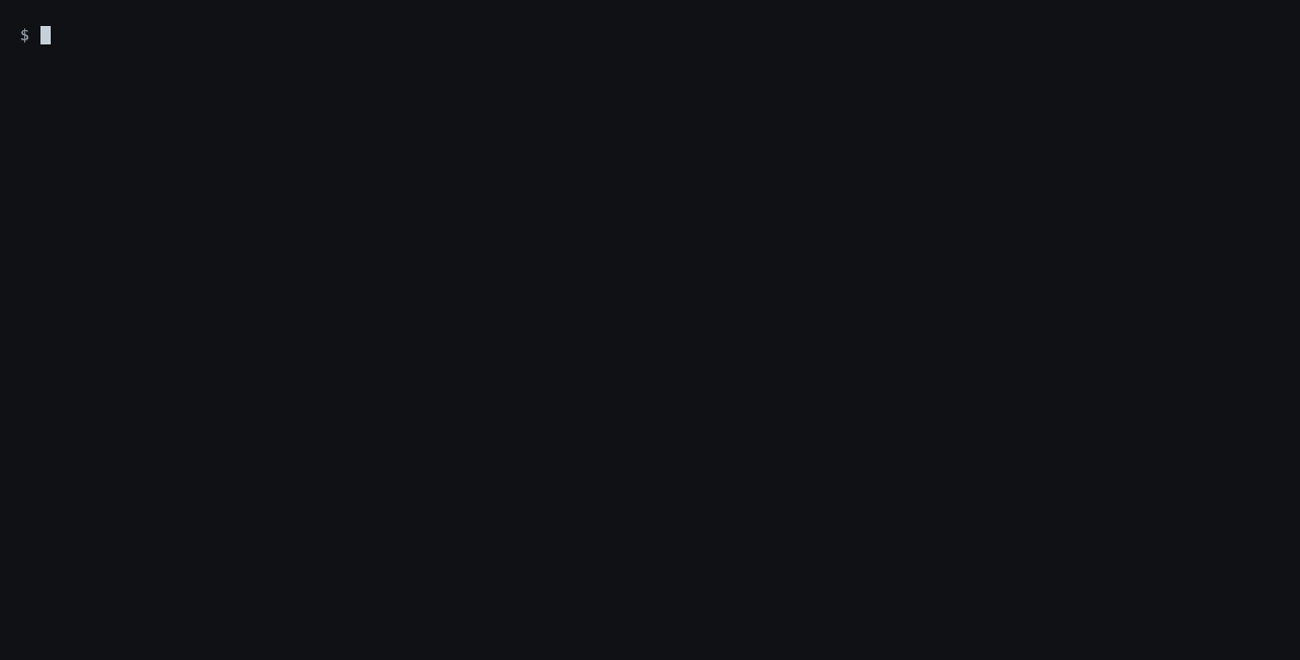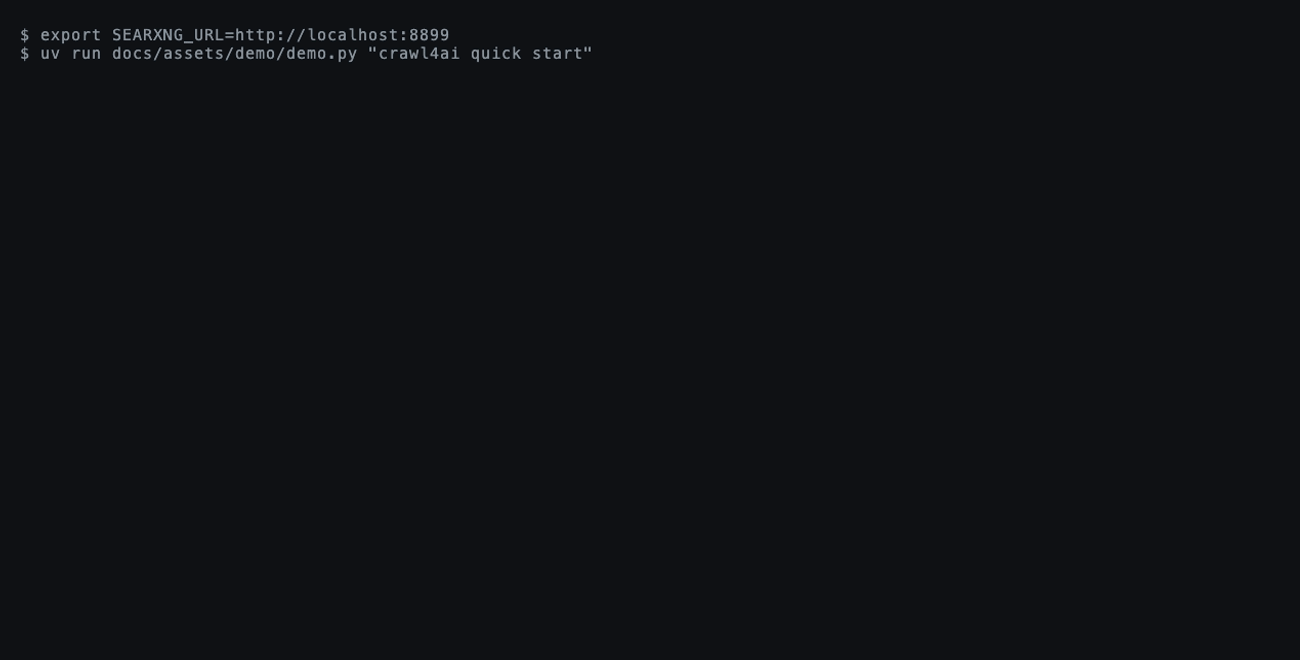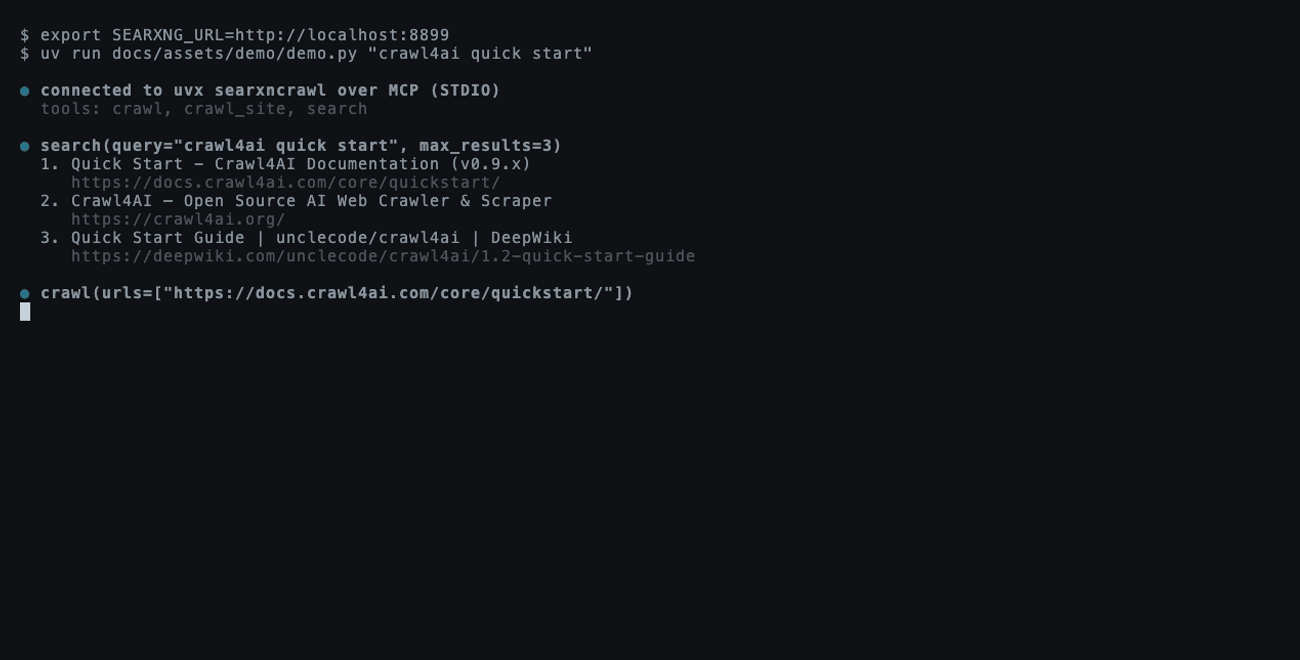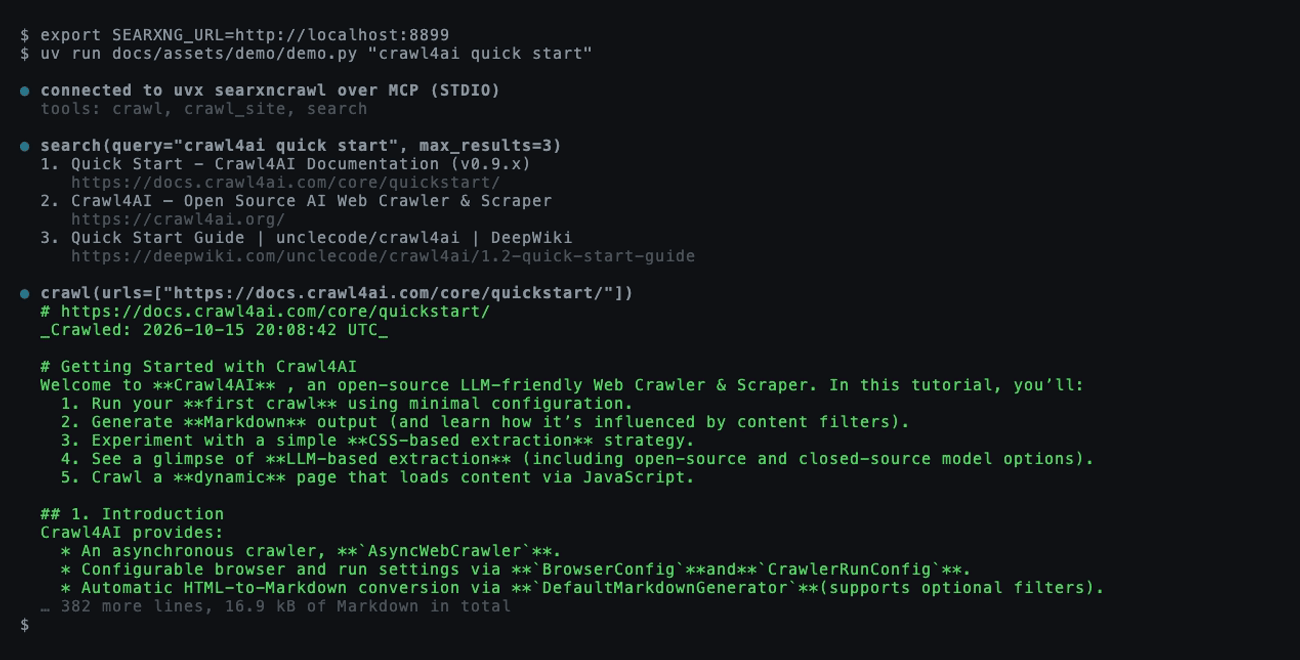
A real MCP client session (fastmcp) against uvx searxncrawl 0.31.0 and a local SearXNG: search, then crawl the top hit into Markdown. Output is shortened for display. Reproduce it with docs/assets/demo/.
searxNcrawl is an open-source MCP server and CLI toolkit that gives AI agents web search and clean Markdown crawling, built on Crawl4AI. Search queries the configured providers, SearXNG and/or You.com, in parallel and merges the results. It runs on your own hardware, needs no API key with SearXNG and succeeds searxng-mcp.
| Web search Your own SearXNG instance and/or the You.com API, queried in parallel; results are merged and attributed to their providers, filtered by language and time range. | Page crawl One or many URLs to Markdown or JSON, with repeated blocks removed and links optionally stripped. | Site crawl Whole sites with depth and page limits, tuned for documentation. |
| Authenticated crawls Capture a login session once with crawl-capture, then crawl behind the login. | STDIO and HTTP Plug into local MCP clients, or run an HTTP endpoint with opt-in Host/Origin checks and configurable CORS. | CLI and Python APIcrawl, search and crawl-capture on the command line, or import it in Python. |
SEARXNG_URL=http://your-searxng:8888 uvx searxncrawl
Quick start
Connect your MCP client directly to searxNcrawl over STDIO or its HTTP endpoint.
You need uv and, for the search tool, at least one search provider: a SearXNG instance with JSON output enabled and/or a You.com API key (YDC_API_KEY). No SearXNG yet? Start one with Docker. Crawling works without either.
Add it to your agent
One step for every agent on your machine
uvx searxncrawl setup
setup detects Claude Code, Codex, Gemini CLI, Cursor, VS Code and Claude Desktop, asks for your SearXNG URL and, optionally, a You.com API key (hidden input, never printed), shows each config change and applies it only after you confirm. Every file it touches is backed up first, and setup --remove undoes it. More options are in MCP server.
Or per agent

The buttons and commands below assume SearXNG at http://localhost:8888; change SEARXNG_URL if yours runs elsewhere, or add YDC_API_KEY for You.com.
Claude Code
claude mcp add searxncrawl --env SEARXNG_URL=http://localhost:8888 -- uvx searxncrawl
Codex
codex mcp add searxncrawl --env SEARXNG_URL=http://localhost:8888 -- uvx searxncrawl
VS Code
code --add-mcp '{"name":"searxncrawl","command":"uvx","args":["searxncrawl"],"env":{"SEARXNG_URL":"http://localhost:8888"}}'
Cursor (~/.cursor/mcp.json), Claude Desktop and other clients that use the mcpServers format
{
  "mcpServers": {
    "searxncrawl": {
      "command": "uvx",
      "args": ["searxncrawl"],
      "env": { "SEARXNG_URL": "http://localhost:8888" }
    }
  }
}
The first crawl downloads Playwright's Chromium once (about 550 MB). For Docker, HTTP transport and other setups see Installation and MCP server.
- Claude Desktop bundle: download
searxncrawl-<version>.mcpbfrom GitHub Releases and open it in Claude Desktop. - Smithery users: use the direct installation above or the native bundle; see the Smithery transition.
Ask your agent
Search for the Crawl4AI quick start, crawl the official page and summarise
how to run a first crawl.
Your agent calls search, picks a result and calls crawl. It gets back clean Markdown instead of raw HTML.
Use the terminal
uvx --from searxncrawl crawl https://modelcontextprotocol.io/docs/getting-started/intro
SEARXNG_URL=http://localhost:8888 uvx --from searxncrawl search "model context protocol" --max-results 5
SEARXNG_URL=http://localhost:8888 uvx --from searxncrawl search "Python documentation" --max-results 3 --include-content
Choose how to connect
| Mode | Setup | Hosting |
|---|---|---|
| Native MCP over STDIO (default) | uvx searxncrawl or uvx searxncrawl setup | Runs alongside your MCP client |
| Native MCP over HTTP | uvx searxncrawl --transport http or Docker Compose | You operate the server; see HTTP configuration |
| Arcade gateway (optional) | Separate Arcade adapter | Requires your own Playwright-compatible worker host and authenticated connection to Arcade |
- Standard installations and releases do not require Arcade.
- For shared HTTP access, use an authenticated TLS proxy. Enable Host/Origin checks with
FASTMCP_HTTP_HOST_ORIGIN_PROTECTION=truebefore startup; allowlists alone do not enable checks or authenticate callers.
How it works
flowchart LR
    agent["AI agent<br/>Claude Code · Codex<br/>Cursor · VS Code"]
    server["searxNcrawl<br/>MCP server"]
    searxng["SearXNG (your instance)<br/>and/or You.com API"]
    browser["Crawl4AI +<br/>Playwright Chromium"]
    results["Merged results<br/>attributed per provider"]
    markdown["Deduplicated<br/>Markdown or JSON"]

    agent -- "MCP · STDIO or HTTP" --> server
    server -- "search" --> searxng --> results
    server -- "crawl · crawl_site" --> browser --> markdown
Results return to the agent as the tool response. Search and crawling are also available as the search and crawl CLI commands, crawling also as a Python API.
searxNcrawl exposes three MCP tools:
| Tool | What it does |
|---|---|
search | Queries the configured providers (SearXNG, You.com) in parallel and returns one merged, deduplicated list with the source of each result. Filters: language, time range, safe search, paging; categories and engines for SearXNG. With include_content, also returns the Markdown of each result page in the same call. |
crawl | Renders one or many URLs in Chromium and returns Markdown or JSON with metadata and references. |
crawl_site | Follows links from a seed URL within depth, page and timeout limits, tuned for documentation sites. |
Both crawl tools drop sections that repeat within a page's Markdown (dedup_mode="exact"), can strip links for a smaller context (remove_links), and accept a Playwright storage_state for pages behind a login. Full parameters are in the MCP tools reference.
Private SearXNG instances
Reviews
No reviews yet — be the first to share how it worked for you.
Frequently Asked Questions about SearxNcrawl
Related MCP servers
Add a badge to your READMEShow it’s listed — live SVG, Markdown or HTML.
AllMCPs Directory Badge
Showcase your server listing on GitHub or your project documentation. Embed this dynamic SVG badge to highlight official listing status and live engagement.
[](https://allmcps.com/mcp/dasdigitalemomentum-searxncrawl)<a href="https://allmcps.com/mcp/dasdigitalemomentum-searxncrawl"><img src="https://allmcps.com/api/badge/dasdigitalemomentum-searxncrawl?style=directory" alt="SearxNcrawl on AllMCPs" /></a>