CorpusIQ vs Dbt MCP
A side-by-side look at the CorpusIQ and Dbt MCP MCP servers: transport, auth, tools, quality signals, and the config to install either one in Claude, Cursor, Windsurf or VS Code.
Verdict: choose CorpusIQ for data platforms work over a hosted endpoint; choose Dbt MCP for data platforms as a local process. You can also run both side by side in one mcpServers block.
Which MCP server should you choose?
 Choose CorpusIQ when
- You need dedicated capabilities in the Data Platforms domain.
- You prefer a remote HTTP/SSE transport.
- Its auth model fits you: OAuth 2.0.
- You want tools like
get_connector_status, resolve_connector, ask_corpusiq.
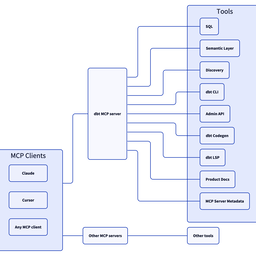 Choose Dbt MCP when
- You need dedicated capabilities in the Data Platforms domain.
- You prefer a local stdio subprocess transport.
- Its auth model fits you: API key required.
- You want tools like
search_product_docs, get_product_doc_pages, list_metrics.
Feature & specification comparison
Rows where the two servers differ are marked.
| Spec | ||
|---|---|---|
| Category | Data Platforms | Data Platforms |
| Quality signal | 83/100 · Excellent | 85/100 · Excellent |
| Install command | Confirmed | Confirmed |
| Transport | Remote HTTP/SSE | Local subprocess (stdio) |
| Auth | OAuth 2.0 | API key required |
| Pricing | Freemium | BYOK (pay the provider) |
| Required env vars | None listed | None listed |
| Verified owner | Verified | Verified |
| GitHub stars | 24 | 609 |
| Directory activity | 19 views 0 installs 0 upvotes | 7 views 0 installs 0 upvotes |
| Tools | 121 | 39 |
| Full listing | View CorpusIQ | View Dbt MCP |
Tools & capabilities
CorpusIQ tools 121
get_connector_statusReturn a pre-formatted Markdown dashboard showing every configured connector's status. IMPORTANT: The output is a complete, ready-to-display Markdown table — show it to the user exactly as returned, do NOT summarize or paraphrase. Each row includes connector name, provider, connection status (with emoji indicators), and a clickable link to authenticate if needed. After displaying the table, offer to help the user connect any unauthorized services and mention they can say 'refresh status' after authenticating.resolve_connectorDiscover how to answer the user's data question. ALWAYS call this FIRST for any data-related request. For broad questions — business health, performance, growth, financial pulse, recap, 'how are we doing', 'what should I focus on', or any cross-source question — the response returns a CorpusIQ Skill in `skill.skill_body`: a pre-built runbook you should execute step-by-step, honoring any presentation rules it specifies. For narrow single-source questions, the response returns 2-4 ready-to-call tool schemas. The `supporting_actions` list is available as helpers when a skill is attached — do not call them ahead of the runbook. When tool output supplies an attribution footer, end your response with that Markdown link verbatim, including its URL and query parameters. Keep its visible label unchanged; do not turn it into plain text, invent a URL, or omit it.ask_corpusiqAnswer a business question through CorpusIQ's deterministic server-side runbook executor. In router_first mode, CorpusIQ selects and pins the best matching runbook before validating connectors and executing its fixed read-only tool allowlist. In required_runbook mode, the caller pins an explicit runbook id. Returns the answer, source evidence, warnings, and a verifiable execution receipt; unsupported runbooks and missing prerequisites fail closed. Use this for supported executive financial-health or financial snapshot workflows even when the user names QuickBooks or another single service. Use raw connector tools for simple lookups that are not executive workflows. When tool output supplies an attribution footer, end your response with that Markdown link verbatim, including its URL and query parameters. Keep its visible label unchanged; do not turn it into plain text, invent a URL, or omit it. Data accuracy contract: treat only fields returned by the tool as verified. Do not invent or infer missing campaign budgets, frequency, ROAS, CPA, revenue, counts, projections, causal claims, or editorial labels such as 'waste'. Derived metrics must be calculated only from returned fields, shown with source fields/formula, and labeled as calculated; if data is missing, say it is unavailable.select_runbookUse this FIRST for broad executive/business questions such as 'How healthy is my business?', 'How are we doing?', 'What should I focus on?', or 'Give me an executive summary'. Selects the best CorpusIQ runbook and returns the next step. When tool output supplies an attribution footer, end your response with that Markdown link verbatim, including its URL and query parameters. Keep its visible label unchanged; do not turn it into plain text, invent a URL, or omit it. Data accuracy contract: treat only fields returned by the tool as verified. Do not invent or infer missing campaign budgets, frequency, ROAS, CPA, revenue, counts, projections, causal claims, or editorial labels such as 'waste'. Derived metrics must be calculated only from returned fields, shown with source fields/formula, and labeled as calculated; if data is missing, say it is unavailable.list_runbooksBrowse a compact list of CorpusIQ runbooks/skills. Do not use this to choose a runbook for a user's broad question; call select_runbook first so the canonical semantic router can choose without sending the full catalog to the model. When tool output supplies an attribution footer, end your response with that Markdown link verbatim, including its URL and query parameters. Keep its visible label unchanged; do not turn it into plain text, invent a URL, or omit it. Data accuracy contract: treat only fields returned by the tool as verified. Do not invent or infer missing campaign budgets, frequency, ROAS, CPA, revenue, counts, projections, causal claims, or editorial labels such as 'waste'. Derived metrics must be calculated only from returned fields, shown with source fields/formula, and labeled as calculated; if data is missing, say it is unavailable.run_runbookRun a specific CorpusIQ runbook by id. By default this returns the playbook (`skill_body`) for client-side execution. Set execution_mode=server_side for the bounded executive-snapshot pilot; unsupported runbooks fail closed. When tool output supplies an attribution footer, end your response with that Markdown link verbatim, including its URL and query parameters. Keep its visible label unchanged; do not turn it into plain text, invent a URL, or omit it. Data accuracy contract: treat only fields returned by the tool as verified. Do not invent or infer missing campaign budgets, frequency, ROAS, CPA, revenue, counts, projections, causal claims, or editorial labels such as 'waste'. Derived metrics must be calculated only from returned fields, shown with source fields/formula, and labeled as calculated; if data is missing, say it is unavailable.list_skillsBrowse a compact list of CorpusIQ Skills (cross-source runbooks). Do not use this to discover the best skill for a broad user question; call select_runbook first so Haiku can classify without sending the full skills catalog to the model. Use list_skills only when the user explicitly asks to browse available skills. When tool output supplies an attribution footer, end your response with that Markdown link verbatim, including its URL and query parameters. Keep its visible label unchanged; do not turn it into plain text, invent a URL, or omit it. Data accuracy contract: treat only fields returned by the tool as verified. Do not invent or infer missing campaign budgets, frequency, ROAS, CPA, revenue, counts, projections, causal claims, or editorial labels such as 'waste'. Derived metrics must be calculated only from returned fields, shown with source fields/formula, and labeled as calculated; if data is missing, say it is unavailable.invoke_skillFetch a named CorpusIQ Skill runbook by id. IMPORTANT: this returns a PLAYBOOK (a step-by-step runbook), NOT the final answer. The response carries `status: runbook_returned`, `next_step: execute_runbook`, and `skill_body` with the ordered steps to execute. After receiving the runbook you MUST call the connector tools/actions it references to gather data, then synthesize a response for the user honoring any presentation rules in the runbook. Never present the raw runbook text to the user as the answer. The user's CorpusIQ identity is forwarded automatically; no separate authentication is required. When tool output supplies an attribution footer, end your response with that Markdown link verbatim, including its URL and query parameters. Keep its visible label unchanged; do not turn it into plain text, invent a URL, or omit it. Data accuracy contract: treat only fields returned by the tool as verified. Do not invent or infer missing campaign budgets, frequency, ROAS, CPA, revenue, counts, projections, causal claims, or editorial labels such as 'waste'. Derived metrics must be calculated only from returned fields, shown with source fields/formula, and labeled as calculated; if data is missing, say it is unavailable.cross_source_ads_connectorCross-source analysis correlating Google Ads spend with GA4 web traffic and revenue. Use when comparing ad spend to sessions, conversions, or ROAS across platforms. When the user asks for a visual, trend, comparison, or recap, call chart_render with the numeric values returned by this connector. If the connector result includes a verified chart_provenance token, the same authenticated user may pass it as provenance_token within 15 minutes, on any replica, and map every value to its exact source_path so chart_render preserves verified provenance. Without a valid connector receipt, chart_render labels values as unverified_model_data. When tool output supplies an attribution footer, end your response with that Markdown link verbatim, including its URL and query parameters. Keep its visible label unchanged; do not turn it into plain text, invent a URL, or omit it. Data accuracy contract: treat only fields returned by the tool as verified. Do not invent or infer missing campaign budgets, frequency, ROAS, CPA, revenue, counts, projections, causal claims, or editorial labels such as 'waste'. Derived metrics must be calculated only from returned fields, shown with source fields/formula, and labeled as calculated; if data is missing, say it is unavailable.cross_source_email_connectorCross-source analysis correlating Klaviyo email activity with web traffic, ecommerce revenue, and ad spend. Use for channel attribution, email-driven revenue, and unified marketing analytics. When the user asks for a visual, trend, comparison, or recap, call chart_render with the numeric values returned by this connector. If the connector result includes a verified chart_provenance token, the same authenticated user may pass it as provenance_token within 15 minutes, on any replica, and map every value to its exact source_path so chart_render preserves verified provenance. Without a valid connector receipt, chart_render labels values as unverified_model_data. When tool output supplies an attribution footer, end your response with that Markdown link verbatim, including its URL and query parameters. Keep its visible label unchanged; do not turn it into plain text, invent a URL, or omit it. Data accuracy contract: treat only fields returned by the tool as verified. Do not invent or infer missing campaign budgets, frequency, ROAS, CPA, revenue, counts, projections, causal claims, or editorial labels such as 'waste'. Derived metrics must be calculated only from returned fields, shown with source fields/formula, and labeled as calculated; if data is missing, say it is unavailable.canonical_context_getRead the user's declared CorpusIQ canonical facts, recent decisions, and declared metric specs. Use at the start of business, product, pricing, company, positioning, board, investor, factual, OR KPI/metric questions when stable user-approved truth may matter. This is read-only and returns only content the user deliberately saved. If declared metric specs are returned, prefer calling metric_spec_resolve(key=...) over computing the same KPI from raw connector tool calls. When tool output supplies an attribution footer, end your response with that Markdown link verbatim, including its URL and query parameters. Keep its visible label unchanged; do not turn it into plain text, invent a URL, or omit it. Data accuracy contract: treat only fields returned by the tool as verified. Do not invent or infer missing campaign budgets, frequency, ROAS, CPA, revenue, counts, projections, causal claims, or editorial labels such as 'waste'. Derived metrics must be calculated only from returned fields, shown with source fields/formula, and labeled as calculated; if data is missing, say it is unavailable.canonical_facts_getGet one declared canonical business fact by key. Read-only. Use when the user asks for a stored fact such as pricing, connector count, tagline, team detail, certification, or product fact. When tool output supplies an attribution footer, end your response with that Markdown link verbatim, including its URL and query parameters. Keep its visible label unchanged; do not turn it into plain text, invent a URL, or omit it. Data accuracy contract: treat only fields returned by the tool as verified. Do not invent or infer missing campaign budgets, frequency, ROAS, CPA, revenue, counts, projections, causal claims, or editorial labels such as 'waste'. Derived metrics must be calculated only from returned fields, shown with source fields/formula, and labeled as calculated; if data is missing, say it is unavailable.- +109 more on the listing page
Dbt MCP tools 39
search_product_docsSearch the dbt product documentation at docs.getdbt.com for pages matching a query. Returns matching page titles, URLs, and descriptions ranked by relevance. Only returns metadata, not page content — use get_product_doc_pages with URLs from the results to retrieve full page content. If the title/description search finds few matches, it automatically falls back to a deep full-text search across all documentation content to find pages where the topic is discussed in the body text. If your first query returns few results, try rephrasing with synonyms or the full term (e.g. 'user-defined functions' instead of 'UDFs', 'version control' instead of 'git'). Use the abbreviations on the page as well. VERSION AWARENESS: The response includes a `dbt_project_version` field (e.g. "1.8") detected by running `dbt --version` against the user's installed dbt binary. If null, the version could not be detected — present docs normally without version-specific callouts. When presenting results to the user, you MUST: 1. State the user's detected dbt version upfront if available (e.g. "Based on your project (dbt 1.8), here's what I found:"). 2. If a result title or description clearly references an older/EOL version (v1.6 or earlier), flag it: "Note: this page covers dbt v1.X, which has reached end-of-life and is no longer supported." 3. Search results only include titles, descriptions, and URLs — not page content. Do NOT make version-specific claims based on search results alone. If the user needs to know whether a feature applies to their version, fetch the page with `get_product_doc_pages` first.get_product_doc_pagesRetrieve the Markdown content of one or more dbt documentation pages from docs.getdbt.com. Pass a list of URLs or relative paths (e.g. from search_product_docs results). Up to 5 pages can be fetched per call; pages are fetched in parallel for speed. Pass the optional `query` parameter to retrieve only the most relevant sections of each page rather than the full content — this significantly reduces response size and is recommended when you already know what topic you are looking for. IMPORTANT — how to present docs content to the user: 1. Give a direct answer first, then explain. Don't just summarize — be specific about WHERE to find a feature in the UI and HOW it works. 2. Structure around the user's task: lead with what they asked, not the doc's own structure. Include step-by-step actionable detail when the docs describe a workflow or UI feature. 3. Call out practical limitations and edge cases from the docs. 4. Close with clear guidance: if the feature only partially answers the question, say what else they can do and where. 5. ALWAYS include the docs page URL(s) as markdown hyperlinks at the end of your response, e.g. [Page title](https://docs.getdbt.com/...). VERSION AWARENESS: The response includes a `dbt_project_version` field with the user's installed dbt version (detected via `dbt --version`). Page content is automatically filtered to show only sections relevant to the detected version — VersionBlock tags from the docs site are resolved so you receive clean, version-appropriate markdown. Pages may also have a `version_note` field if they cover an EOL version. If `dbt_project_version` is null, the version could not be detected — all version-specific content is kept with tags stripped. When presenting page content to the user, you MUST: 1. If `dbt_project_version` is set, tell the user their detected version upfront (e.g. "You're on dbt 1.8"). 2. If `version_note` is set, prominently warn the user that the page is for an end-of-life version and the information may be outdated. Suggest they look at the current docs instead. 3. Page content has already been filtered to show only sections relevant to the detected version. If the content seems sparse or incomplete, let the user know that some sections may have been filtered out because they apply to a different dbt version, and suggest they check the full page on docs.getdbt.com.list_metricsList metrics from the dbt Semantic Layer. The `result` field is a CSV string with a header row. Columns are dynamic: a column is only present if at least one metric has a non-empty value for it. `name` and `type` are always present; `label`, `description`, `metadata`, `dimensions`, and `entities` are included only when at least one metric has a value. The `dimensions` and `entities` cells contain comma-separated lists of names. When the number of metrics is below the configured threshold (default: 10), each metric includes the names of its available dimensions and entities. Use get_dimensions or get_entities for full details (types, granularities, descriptions) on specific metrics. When above the threshold, only metrics are returned. `metric_time` is a standard time dimension available on most metrics — you can often query directly without calling `get_dimensions` first. Call `get_dimensions` only when you need non-time dimensions or specific granularity details. For listings that exceed the text budget, columns are dropped progressively to save tokens: `description` is dropped first; `metadata` is dropped only if removing `description` alone is not enough. The CSV is prefixed with one or more `# Note:` lines listing which columns were omitted. When that happens, call `list_metrics` again with the `search` parameter to retrieve those fields for the specific metrics you care about. `search` accepts either a single substring or a list of substrings; when a list is provided, metrics whose name matches **any** of the substrings are returned (deduplicated), so you can fetch details for several metrics in one call. `meta_filter` accepts a dict of key-value pairs and restricts results to metrics whose `config.meta` contains all specified pairs — for example `{"agent_accessible": true}`. Apply it on broad searches to keep the result set small enough that the `metadata` column is preserved in the response. If the user is asking a data-related or business-related question, use this tool as a first step. Returns one source page in `result`, with `pagination.has_more` and `pagination.next_page`. Pass the next page as `page_num` with the same filters and `page_size` (default 50, maximum 100). Local filtering may leave an empty page with more pages available. Restart at page 1 if you reduce the page size after a size-limit error.list_saved_queriesList all saved queries from the dbt Semantic Layer. Saved queries are pre-defined queries that have been saved in the Semantic Layer. They contain specific metrics, group-by dimensions, and filters that are commonly used. This tool helps discover what predefined queries are available for quick execution. Use this tool when: - The user wants to see what pre-built queries are available - The user mentions "saved queries" or "predefined queries" - You need to find commonly used analytical queries Examples: - "What saved queries are available?" - "Show me the predefined reports" - "List all saved queries for revenue analysis" Returns one source page in `result`, with `pagination.has_more` and `pagination.next_page`. Pass the next page as `page_num` with the same filters and `page_size` (default 50, maximum 100). Local filtering may leave an empty page with more pages available. Restart at page 1 if you reduce the page size after a size-limit error.get_dimensions<instructions> Get the dimensions for specified metrics Note: `metric_time` is a standard time dimension available on most metrics. You do not need to call this tool just to confirm time dimensions exist — call it only when you need categorical dimensions or specific granularity details. If this tool returns no results, proceed to query directly using `metric_time`. Dimensions are the attributes, features, or characteristics that describe or categorize data. Each dimension includes a metadata field containing config.meta from semantic model YAML files. The metadata contains fields relevant to the semantic models. </instructions> <examples> <example> Question: "I want to analyze revenue trends - what dimensions are available?" Thinking step-by-step: - Using list_metrics(), I find "revenue" is available - Now I can get the dimensions for this metric - The search parameter is not needed here since the user is interested in all available dimensions. Parameters: metrics=["revenue"] search=null </example> <example> Question: "Are there any time-related dimensions for my sales metrics?" Thinking step-by-step: - Using list_metrics(), I find "total_sales" and "average_order_value" are available - The user is interested in time dimensions specifically - I should use the search parameter to filter for dimensions with "time" in the name - This will narrow down the results to just time-related dimensions Parameters: metrics=["total_sales", "average_order_value"] search="time" </example> </examples> Returns one source page in `result`, with `pagination.has_more` and `pagination.next_page`. Pass the next page as `page_num` with the same filters and `page_size` (default 50, maximum 100). Local filtering may leave an empty page with more pages available. Restart at page 1 if you reduce the page size after a size-limit error.get_entities<instructions> Get the entities for specified metrics Entities are real-world concepts in a business such as customers, transactions, and ad campaigns. Analysis is often focused around specific entities, such as customer churn or annual recurring revenue modeling. </instructions> <examples> <example> Question: "I want to analyze revenue - what entities are available?" Thinking step-by-step: - Using list_metrics(), I find "revenue" is available - Now I can get the entities for this metric - The search parameter is not needed here since the user is interested in all available entities. Parameters: metrics=["revenue"] search=null </example> <example> Question: "Are there any customer-related entities for my sales metrics?" Thinking step-by-step: - Using list_metrics(), I find "total_sales" and "average_order_value" are available - The user is interested in customer entities specifically - I should use the search parameter to filter for entities with "customer" in the name - This will narrow down the results to just customer-related entities Parameters: metrics=["total_sales", "average_order_value"] search="customer" </example> </examples> Returns one source page in `result`, with `pagination.has_more` and `pagination.next_page`. Pass the next page as `page_num` with the same filters and `page_size` (default 50, maximum 100). Local filtering may leave an empty page with more pages available. Restart at page 1 if you reduce the page size after a size-limit error.get_dimension_values<instructions> Get the distinct values for a given dimension, optionally scoped to specific metrics. Use this tool to discover what values exist for a dimension before building a `where` filter in `query_metrics`. For example, to filter by country you first call this tool to see which country values exist, then use those values in the `where` clause. If the response includes `truncated: true`, there are more values than the current `limit`. Increase `limit` to retrieve more, or add `metrics` to narrow the scope. </instructions> <examples> <example> Question: "I want to filter revenue for a specific country — what countries are available?" Thinking step-by-step: - The user wants to know valid values for a country dimension - I should scope to the "revenue" metric for accurate results Parameters: dimension="customer__country" metrics=["revenue"] limit=100 </example> <example> Question: "What are the possible order statuses?" Thinking step-by-step: - The user wants all distinct values for an order status dimension - No specific metric context needed Parameters: dimension="order__status" metrics=null limit=100 </example> </examples>query_metrics<instructions> Queries the dbt Semantic Layer to answer business questions from the data warehouse. This tool allows ordering and grouping by dimensions and entities. To use this tool, you must first know about specific metrics, dimensions and entities to provide. You can call the list_metrics, get_dimensions, and get_entities tools to get information about which metrics, dimensions, and entities to use. When using the `order_by` parameter, each item must refer to either a metric name or a field that also appears in `group_by`. For time dimensions, you may specify a `grain` in `order_by` independently from `group_by`; if omitted, it defaults to the grain of the matching `group_by` entry. `grain` only applies to time dimensions and should be omitted for metrics and categorical dimensions. When fulfilling a lookback query, prefer using order_by and limit instead of using the where parameter. A lookback query requires that the `order_by` parameter includes a descending order for a time dimension. The `where` parameter should be database agnostic SQL syntax, however dimensions and entity are referenced differently. For categorical dimensions, use `{{ Dimension('<name>') }}` and for time dimensions add the grain like `{{ TimeDimension('<name>', '<grain>') }}`. For entities, use `{{ Entity('<name>') }}`. When referencing dates in the `where` parameter, only use the format `yyyy-mm-dd`. Pass the `where` value as a plain string — do not wrap it in additional quotes. Don't call this tool if the user's question cannot be answered with the provided metrics, dimensions, and entities. Instead, clarify what metrics, dimensions, and entities are available and suggest a new question that can be answered and is approximately the same as the user's question. For queries that may return large amounts of data, it's recommended to use a two-step approach: 1. First make a query with a small limit to verify the results are what you expect 2. Then make a follow-up query without a limit (or with a larger limit) to get the full dataset IMPORTANT: Do the below if the GET_MODEL_HEALTH tool is enabled. When responding to user requests to pull metrics data, check the health of the dbt models that are the parents of the dbt semantic models. Use the instructions from the "ASSESSING MODEL HEALTH" section of the get_model_health() prompts to do this. </instructions> <examples> <example> Question: "What were our total sales last month?" Thinking step-by-step: - I know "total_sales" is the metric I need - I know "metric_time" is a valid dimension for this metric and supports MONTH grain - I need to group by metric_time to get monthly data - Since this is time-based data, I should order by metric_time. I am also grouping by metric_time, so this is valid. - The user is asking for a lookback query, so I should set descending to true so the most recent month is at the top of the results. - The user is asking for just the last month, so I should limit to 1 month of data Parameters: metrics=["total_sales"] group_by=[{"name": "metric_time", "grain": "MONTH", "type": "time_dimension"}] order_by=[{"name": "metric_time", "grain": "MONTH", "descending": true}] limit=1 </example> <example> Question: "Show me our top customers by revenue in the last quarter" Thinking step-by-step: - First, I need to find the revenue metric - Using list_metrics(), I find "revenue" is available - I need to check what dimensions are available for revenue - Using get_dimensions(["revenue"]), I see "customer_name" and "metric_time" supports QUARTER grain - I need to check what entities are available - Using get_entities(["revenue"]), I confirm "customer" is an entity - I need quarterly time grain - Since this is time-based data, I should order by metric_time. I am grouping by metric_time, so this is valid. This is a lookback query, so I should set descending to true. - I should also order by revenue to see top customers. I am grouping by revenue, so this is valid. The user is asking for the highest revenue customers, so I should set descending to true. - I should limit to top 5 results to verify the query works Parameters: metrics=["revenue"] group_by=[{"name": "customer_name", "type": "dimension"}, {"name": "metric_time", "grain": "QUARTER", "type": "time_dimension"}] order_by=[{"name": "metric_time", "grain": "QUARTER", "descending": true}, {"name": "revenue", "descending": true}] limit=5 Follow-up Query (after verifying results): metrics=["revenue"] group_by=[{"name": "customer_name", "type": "dimension"}, {"name": "metric_time", "grain": "QUARTER", "type": "time_dimension"}] order_by=[{"name": "metric_time", "grain": "QUARTER", "descending": true}, {"name": "revenue", "descending": true}] limit=null </example> <example> Question: "What's our average order value by product category for orders over $100?" Thinking step-by-step: - I know "average_order_value" is the metric I need - I know "product_category" is a valid dimension - I need to filter for orders over $100 - No time dimension needed - I should first limit results to verify the query works Parameters (initial query): metrics=["average_order_value"] group_by=[{"name": "product_category", "type": "dimension"}] where="{{ Dimension('order_value') }} > 100" limit=10 Follow-up Query (after verifying results): metrics=["average_order_value"] group_by=[{"name": "product_category", "type": "dimension"}] where="{{ Dimension('order_value') }} > 100" limit=null </example> <example> Question: "How many new users did we get each week last year?" Thinking step-by-step: - First, I need to find the new users metric - Using list_metrics(), I find "new_users" is available - I need to check what dimensions are available - Using get_dimensions(["new_users"]), I see "metric_time" supports WEEK grain - I need to check what entities are available - Using get_entities(["new_users"]), I confirm "user" is an entity - I need weekly time grain - I need to group by metric_time - Since this is time-based data, I should order by metric_time to show progression - I need to filter for the previous year's data using proper time dimension syntax - Should first get a few weeks to verify the query works Parameters (initial query): metrics=["new_users"] group_by=[{"name": "metric_time", "grain": "WEEK", "type": "time_dimension"}] order_by=[{"name": "metric_time", "grain": "WEEK", "descending": false}] where="{{ TimeDimension('metric_time', 'WEEK') }} >= '2023-01-01' AND {{ TimeDimension('metric_time', 'WEEK') }} < '2024-01-01'" limit=4 Follow-up Query (after verifying results): metrics=["new_users"] group_by=[{"name": "metric_time", "grain": "WEEK", "type": "time_dimension"}] order_by=[{"name": "metric_time", "grain": "WEEK", "descending": false}] where="{{ TimeDimension('metric_time', 'WEEK') }} >= '2023-01-01' AND {{ TimeDimension('metric_time', 'WEEK') }} < '2024-01-01'" limit=null </example> <example> Question: "What's our customer satisfaction score by region?" Thinking step-by-step: - First, I need to check if we have a customer satisfaction metric - Using list_metrics(), I find we don't have a direct "customer_satisfaction" metric - I should check what metrics we do have that might be related - I see we have "net_promoter_score" and "customer_retention_rate" - I should inform the user that we don't have a direct customer satisfaction metric - I can suggest using NPS as a proxy for customer satisfaction Response to user: "I don't have a direct customer satisfaction metric, but I can show you Net Promoter Score (NPS) by region, which is often used as a proxy for customer satisfaction. Would you like to see that instead?" If user agrees, then: Parameters: metrics=["net_promoter_score"] group_by=[{"name": "region", "type": "dimension"}] order_by=[{"name": "net_promoter_score", "descending": true}] limit=10 </example> </examples>get_metrics_compiled_sql<instructions> Gets compiled SQL for given metrics and dimensions/entities from the dbt Semantic Layer. This tool generates the underlying SQL that would be executed for a given metric query by the `query_metrics` tool, without actually running the query. This is useful for understanding what SQL is being generated, debugging query issues, or getting SQL to run elsewhere. To use this tool, you must first know about specific metrics, dimensions and entities to provide. You can call the list_metrics, get_dimensions, and get_entities tools to get information about which metrics, dimensions, and entities to use. When using the `group_by` parameter, ensure that the dimensions and entities you specify are valid for the given metrics. Time dimensions can include grain specifications (e.g., MONTH, DAY, YEAR). The tool will return the compiled SQL that the dbt Semantic Layer would generate to calculate the specified metrics with the given groupings. Don't call this tool if the user's question cannot be answered with the provided metrics, dimensions, and entities. Instead, clarify what metrics, dimensions, and entities are available and suggest a new question that can be answered and is approximately the same as the user's question. This tool is particularly useful when: - Users want to see the underlying SQL for a metric calculation - Debugging complex metric definitions - Understanding how grouping affects the generated SQL - Getting SQL to run in other tools or systems </instructions> Returns the compiled SQL as a string, or an error message if the compilation fails.get_mart_modelsGet the name and description of all mart models in the environment. A mart model is part of the presentation layer of the dbt project. It's where cleaned, transformed data is organized for consumption by end-users, like analysts, dashboards, or business tools. Returns one source page in `result`, with `pagination.has_more` and `pagination.next_cursor`. Pass the next cursor as `after` with the same filters. `limit` defaults to 50 and is capped at 100. Local filtering may leave an empty page with more pages available.get_all_modelsGet a page of dbt model names and descriptions in the environment. Returns one source page in `result`, with `pagination.has_more` and `pagination.next_cursor`. Pass the next cursor as `after` with the same filters. `limit` defaults to 50 and is capped at 100. Local filtering may leave an empty page with more pages available.get_node_detailsRetrieves full details for a dbt resource by type and name or unique ID. Use this tool when you need the full schema, definition, or metadata for a specific dbt resource. The `resource_type` determines what fields are returned. **Parameters:** - `resource_type`: The type of dbt resource. One of: `model`, `source`, `exposure`, `test`, `seed`, `snapshot`, `macro`, `semantic_model`. The resource type is also encoded in the `unique_id` prefix (e.g. `model.my_project.orders` → `model`). - `name`: The resource's short name (e.g. `orders`). Provide `name` or `unique_id`, not both. - `unique_id`: The resource's fully qualified unique ID (e.g. `model.my_project.orders`). Preferred when available — avoids ambiguity when multiple resources share a name. **Usage examples:** ```python # Get details for a model by unique_id get_node_details(resource_type="model", unique_id="model.analytics.orders") # Get details for a source by name get_node_details(resource_type="source", name="raw_users") # Get details for a semantic model get_node_details(resource_type="semantic_model", unique_id="semantic_model.analytics.orders") ```- +27 more on the listing page
Ready-to-paste client configs
Paste either block (or both) into your client config, e.g. claude_desktop_config.json or ~/.cursor/mcp.json. We only show a config when the install command is confirmed.
CorpusIQ
{
  "mcpServers": {
    "corpusiq": {
      "url": "https://mcp2.corpusiq.io/mcp"
    }
  }
}
Dbt MCP
{
  "mcpServers": {
    "dbt-labs-dbt-mcp": {
      "command": "uvx",
      "args": [
        "dbt-mcp"
      ]
    }
  }
}
Frequently asked questions
CorpusIQ is categorized under Data Platforms and uses a remote HTTP/SSE transport. Dbt MCP belongs to Data Platforms and uses a local stdio subprocess. Pick CorpusIQ for data platforms work and Dbt MCP for data platforms.
Copy the mcpServers block from the config section on this page into your client's config (for example claude_desktop_config.json or ~/.cursor/mcp.json), then fully restart the client.
CorpusIQ is listed as freemium — a free tier with paid plans. Auth: oauth 2.0. Dbt MCP is bring-your-own-key: usage is billed by the API provider you supply a key for. Auth: api key required. If a server needs environment variables such as API keys, define them under the env key in your client's MCP config.
Yes. MCP clients support multiple servers: add corpusiq and dbt-labs-dbt-mcp as separate keys in the same mcpServers object, and your assistant will call tools from either one.
On AllMCPs, CorpusIQ has a quality signal of 83/100 (Excellent) with 19 views, 0 installs and 24 GitHub stars. Dbt MCP has 85/100 (Excellent) with 7 views, 0 installs and 609 GitHub stars.