Boson Video README
The full upstream README, mirrored here for reference. Install config, tool schemas, adoption signals, and an original overview live on the Boson Video listing page.
Boson-Video
Get the point of any video without watching all of it. Paste a YouTube link or drop a video file. Every line of the summary, the transcript and the screen text carries the second it came from, and questions are answered from the video and checked against it.
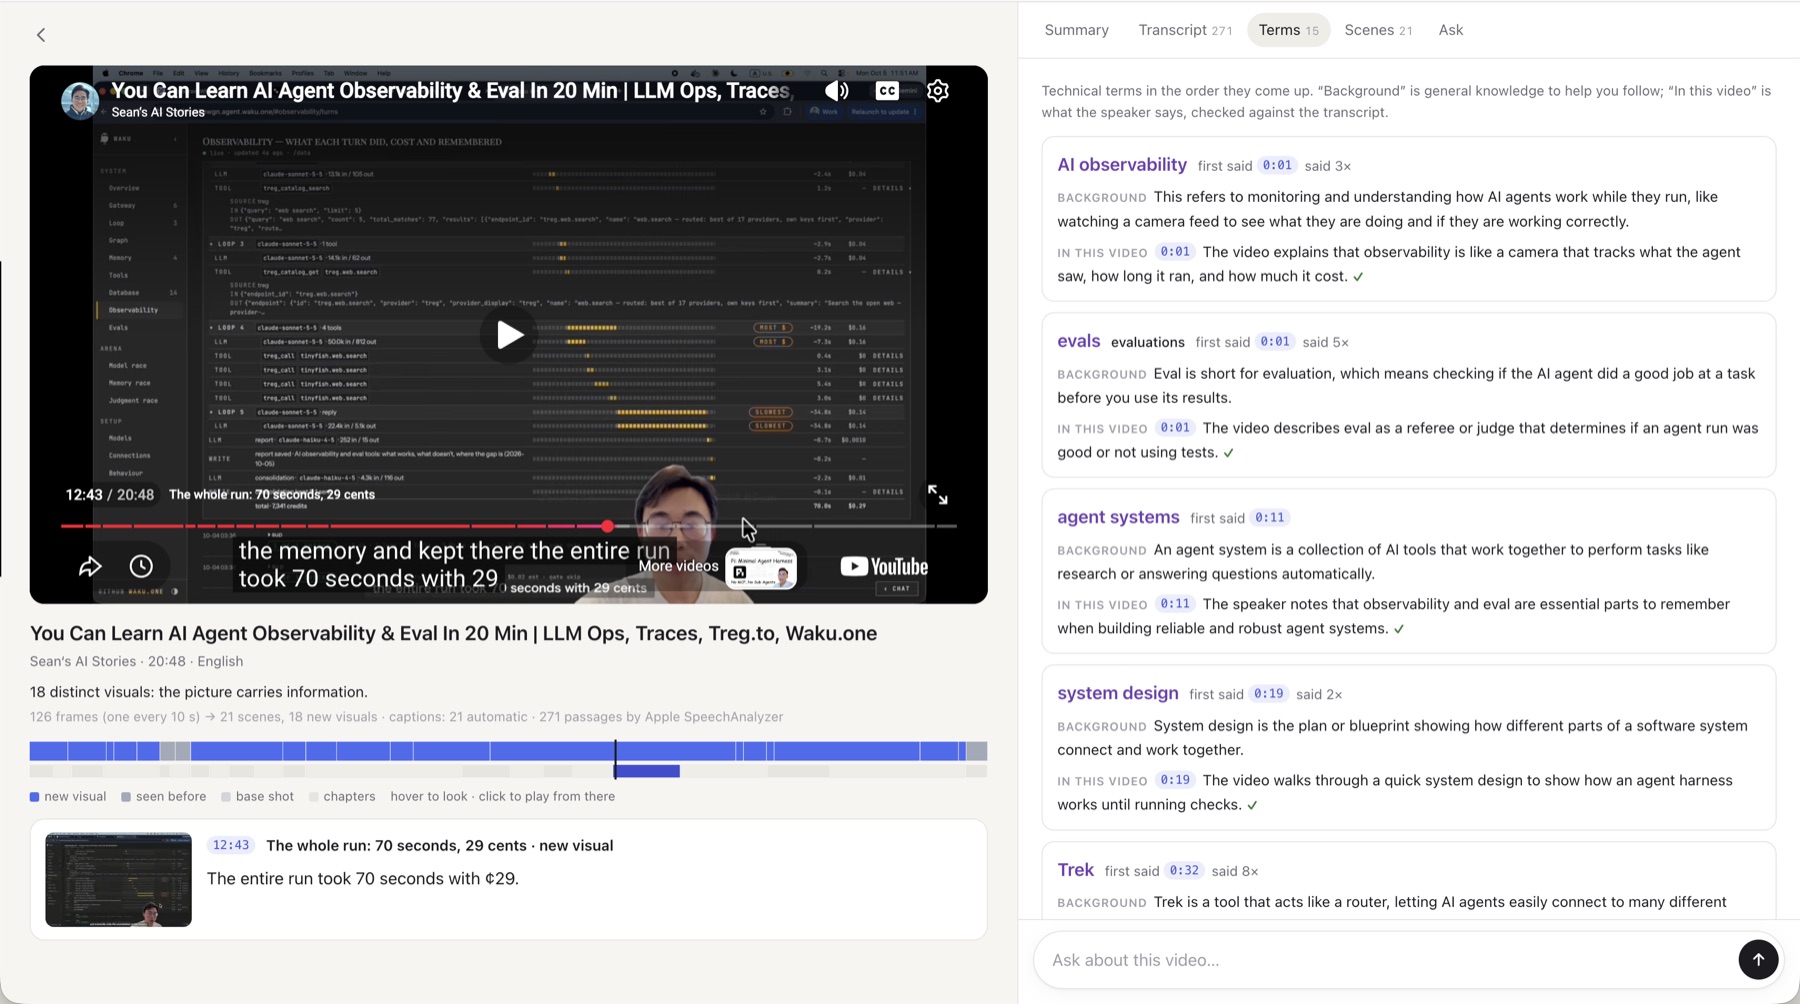
- The ribbon: the whole video on one strip (scenes, chapters, most replayed). Hover to see any second's frame and words.
- Summary: sections with their frames; every sentence timed and checked (✓ ? ✗).
- Transcript: the original with English beneath, technical terms explained, on-screen text read in.
- Ask: answers that cite their moments and show the frames; anything the video doesn't say is marked as background.
- Your own AI: the same document as an MCP plugin for Claude, Cursor, Codex and more.
Built for long talks, lectures and finance videos in a language you half know (Chinese and English today).
In your own AI
In Claude Code, one line (uv runs it; nothing else to install):
Claude Desktop, Cursor and Codex take the same command, uvx boson-video mcp, in their MCP settings;
claude.ai and ChatGPT need a web address instead: setup for each app.
Then paste a YouTube link and ask. Your AI opens the video, reads the transcript, looks at the frames that matter at full resolution, and checks its claims, citing every moment. No keys needed, and everything runs on your computer. In apps that show interactive pages (Claude Desktop, claude.ai, ChatGPT, Cursor), the video's page opens right in the chat, and questions you ask there go to your AI.
Run the page
Two optional models make it fuller. Without their keys you still get the scenes, the transcript and search.
- A writer writes the summary, the English and the terms: Mercury from
Inception by default (
INCEPTION_API_KEY), or any OpenAI-compatible model (BOSON_WRITER_BASE_URL,BOSON_WRITER_MODEL,BOSON_WRITER_API_KEY). - A checker checks every sentence against what was said and finds the moments that answer a
question: Jev from TypeSafe (
TYPESAFE_API_KEY).
Put the keys in a .env file in the folder you start from, or in ~/.boson-video/.env; the server says
at start which one is missing. Off by default: with OPENAI_API_KEY and BOSON_SCREEN_CHECK=1, a sentence
the words can't confirm is also checked against the frames on screen (OpenAI's Decisions API, about a
cent a video).
Tested videos
Measured, one run each unless a range is shown. Mac: M5 MacBook with Apple's transcriber. Windows: a 12-thread laptop with SenseVoice or Parakeet on the CPU. Full tables: docs/measured.md.
| Video | Length | Scene map | Words | Transcript errors¹ | Screen text | Summary ✓ |
|---|---|---|---|---|---|---|
| Money or Life 美股频道, Meta and AI (zh, talking head) | 24:53 | 1.3 s | 13.8 s (Mac) | no human captions | — | 13 / 13 |
| Money or Life 美股频道, AI drug discovery (zh, slides) | 28:24 | 1.1 s | 18.5 s (Mac) | not scored | 36 moments read | 15 / 16 |
| 程序员老王, LLM abliteration (zh, animated diagrams) | 11:35 | — | 10.0 s (Windows) | not scored | 88 moments; burned-in subtitles told apart at 85 | 21 of 22 to 22 of 23 (several runs) |
| 陳永儀, TEDxTaipei (zh, talk) | 14:29 | — | 7.1 s (Mac) | 5.3% chars (Mac), 4.8% (SenseVoice) | — | 14 / 14 |
| Ken Robinson, TED (en, talk) | 20:06 | — | 9.9 s (Mac) | 10.0% words (Mac), 10.5% (Parakeet) | — | 22 / 25 |
| Sean's AI Stories, agent observability (en, screen recording) | 20:48 | 1.5 s | 13.2 s (Mac) | not scored | none: YouTube refused full resolution | 23 / 26 |
| Andrej Karpathy, Intro to LLMs (en, slides) | 59:48 | 1.6 s | 30.5 s (Mac) | only automatic captions | 19 of 20 slides right | 22 / 23 |
| Rick Astley, Never Gonna Give You Up (fast cuts) | 3:33 | 0.7 s | — | — | — | — |
¹ Against human captions (scripts/accuracy.py); about half the English errors are filler words the captions leave out.
Summary ✓: summary sentences the checker confirmed against what was said (Jev, with numbers compared in code).
Command line
From a clone: uv sync, then uv run boson-video …; uv run pytest runs the tests (offline).
More
- docs/workflow.md: how the workflow is designed: stages, the document, the ways in
- docs/how-it-works.md: the pipeline, what YouTube allows, limits
- docs/DIRECTION.md: what we're building, milestones, decisions
- docs/timeline-format.md: the document format, for other tools
- CONTRIBUTING.md: how to set up, test and propose a change
- AGENTS.md: the guide for coding agents
MIT licensed. YouTube's terms don't allow automated access for products, so everything that touches YouTube runs on your own computer.