Anymd README
The full upstream README, mirrored here for reference. Install config, tool schemas, adoption signals, and an original overview live on the Anymd listing page.
anymd
PDF, Word, PowerPoint, Excel, EPUB, HTML and web pages, images (OCR), audio and video (metadata, subtitles, transcripts). A fast Rust MCP server and CLI that runs on your machine. No API key.

Install · Benchmarks · Tools · CLI · Formats · Docs
Formerly pdf-reader-mcp. Migrating from pdf-reader-mcp
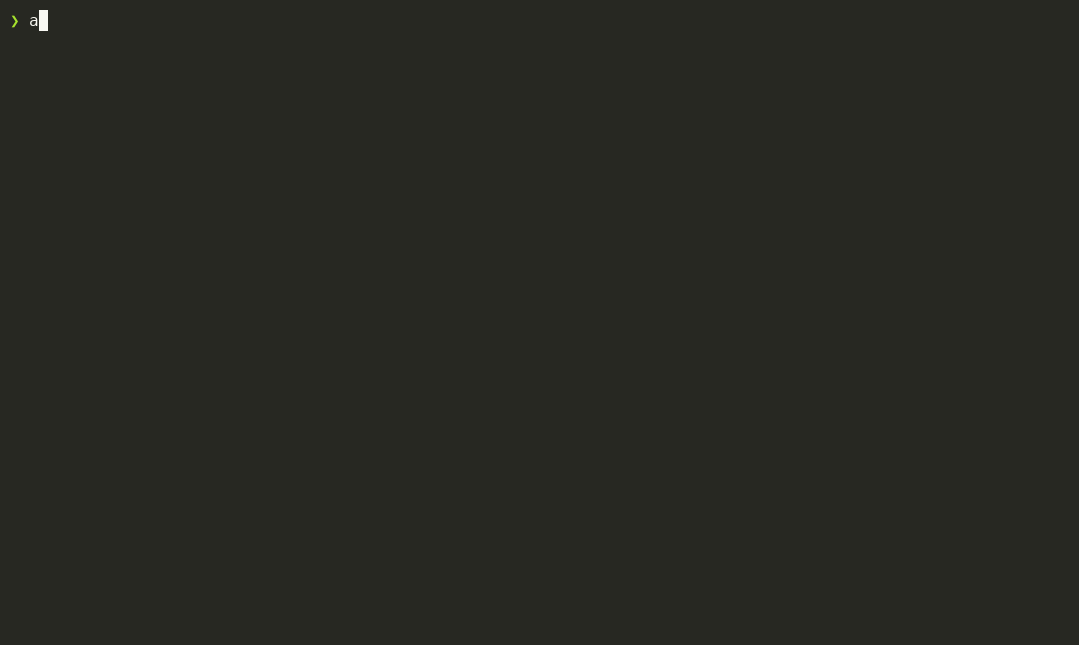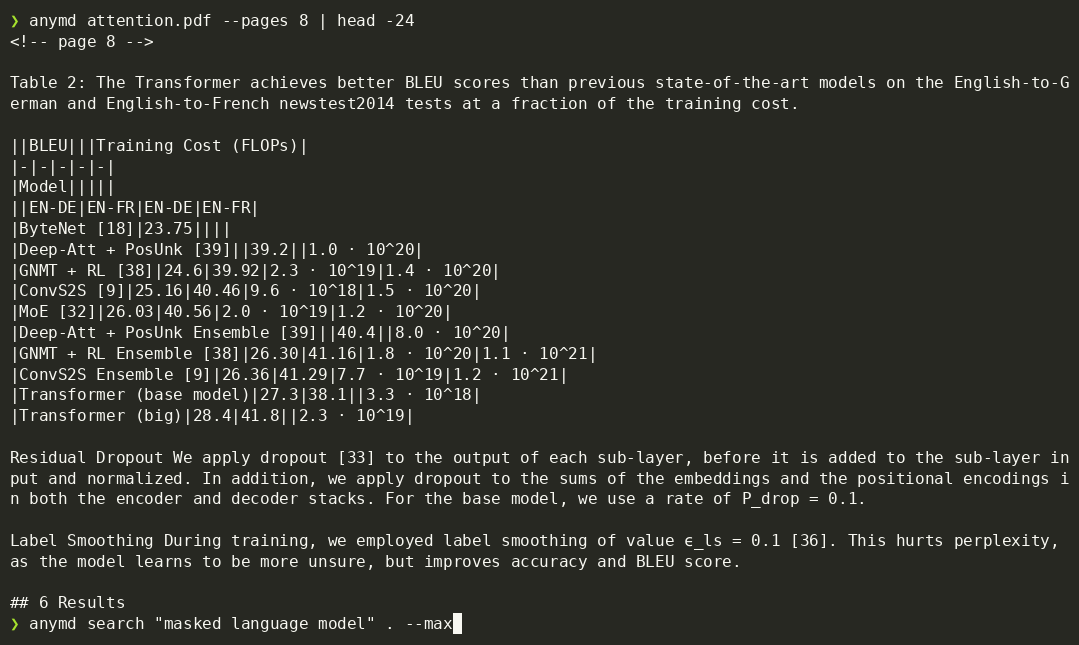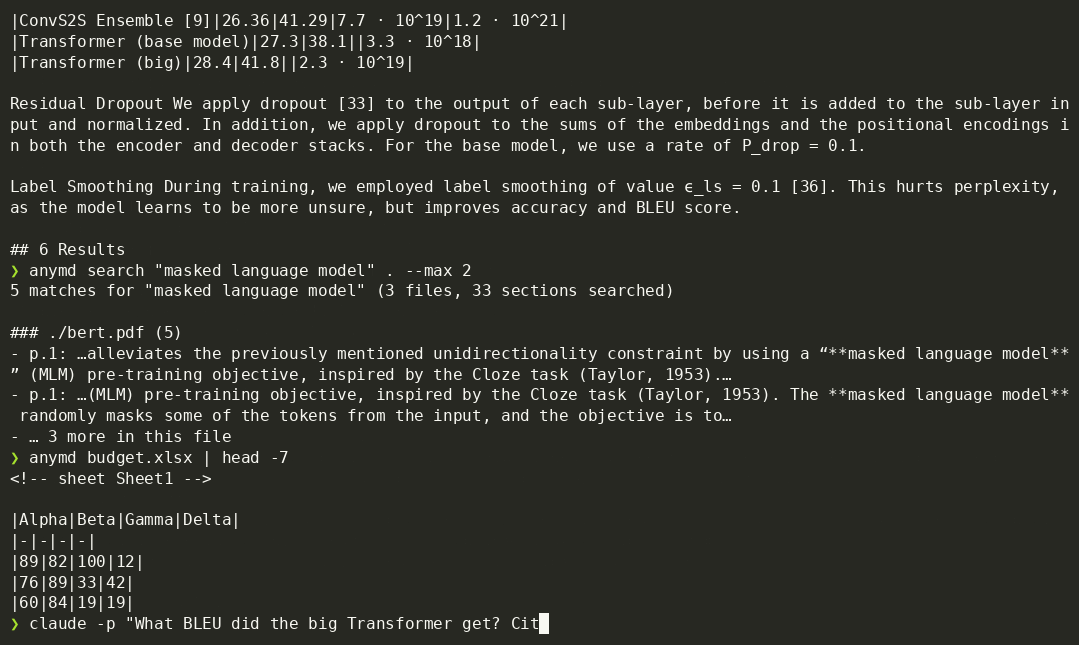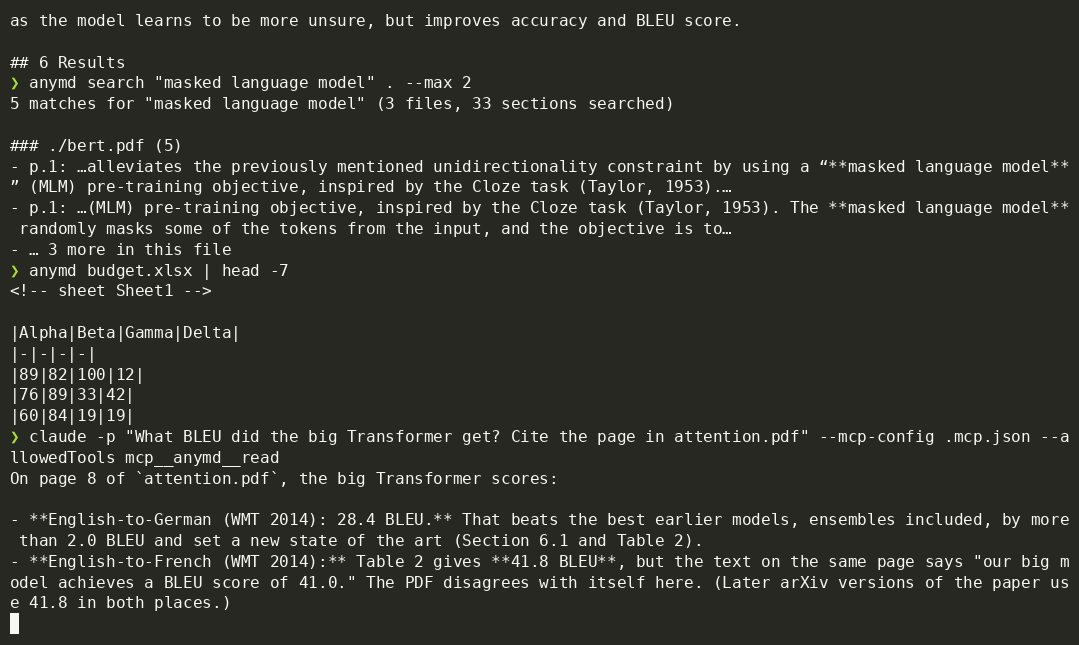
A real, unedited terminal recording (asciinema + agg, script). The last command is Claude Code answering from the PDF through the anymd MCP server.
Why anymd
- Fast. Native Rust converts in parallel, page by page. On the 19 benchmark documents every tool converted, anymd takes 12.1 s in total; docling 1,723.3 s (143×), markitdown 45.4 s (4×), marker 5,256.3 s (435×).
- Accurate. A layout engine rebuilds words from glyph gaps, puts two-column papers in reading order, and recovers tables, including borderless ones. The text stays exactly as printed, with no glued words and no scrambled columns.
- Lean on tokens. Pages come back as Markdown with
<!-- page 3 -->citation anchors, a small front-matter header, and compact tables. A token budget and a cursor keep large documents within your agent's context. - Every format, one call. One tool reads every format listed below. It also accepts web URLs and whole directories, and
searchlooks across all of them. - Local and private. Nothing is uploaded. OCR and transcripts use local tools you already have (tesseract, ffmpeg, whisper.cpp), and only when they are installed.
Install
Add anymd to every MCP client on your machine (Claude Code, Codex, Cursor, VS Code, Claude Desktop, Windsurf, Gemini CLI) with one command:
Or add it by hand: every MCP client runs the same command, npx -y @sylphx/anymd. Node 18+ is the only requirement; npm installs the native binary for your platform.
Claude Code
Or as a plugin, with the anymd skill: /plugin marketplace add SylphxAI/anymd, then /plugin install anymd@anymd.
Codex
or in ~/.codex/config.toml:
Cursor

or in .cursor/mcp.json:
VS Code
or in .vscode/mcp.json:
Claude Desktop
Add to claude_desktop_config.json (Settings → Developer → Edit Config):
Windsurf, Zed, Cline, and other clients
Any client that speaks MCP over stdio: command npx, args ["-y", "@sylphx/anymd"]. To keep the server inside one folder, add --allow-dir=/path/to/docs.
CLI only
Benchmarks
AgentDocBench is an open benchmark for document → Markdown conversion for agents: license-clean documents in 12 categories (math papers, two-column papers, financial tables, forms, scans, CJK, slides, spreadsheets, Word, EPUB, HTML), scored on verbatim sentences, text F1, reading order, and table cells, with time and output tokens. Every tool runs on the same kind of GitHub-hosted runner (4 CPUs):
| anymd | docling | kreuzberg | unstructured | markitdown | marker | pdftotext | |
|---|---|---|---|---|---|---|---|
| Overall score | 96.3 | 93.0 | 81.7 | 81.2 | 76.8 | 71.0 | 42.2 |
| Table cells F1 | 92.2 | 89.9 | 38.4 | 38.4 | 57.2 | 60.9 | 0.0 |
| Reading order | 98.8 | 94.4 | 96.8 | 93.9 | 85.5 | 76.8 | 52.0 |
| Docs converted | 38/38 | 38/38 | 38/38 | 38/38 | 38/38 | 30/38 | 23/38 |
| Time, all docs | 22.9 s | 2,432.4 s | 16.0 s | 346.5 s | 75.6 s | 7,104.5 s | 0.90 s |
The generated leaderboard, per-category scores (including where anymd loses), and method are in the benchmark guide. The corpus, ground truth, adapters, and raw results are in bench/, and the Benchmark workflow reruns everything; new tools can join with a single adapter file.
MCP tools
anymd exposes three tools.
| Tool | Use it to | Key arguments |
|---|---|---|
read | Turn a file, URL, or folder into Markdown | source, pages ("1-5,8"), max_tokens (default 20000), cursor, ocr, transcript, download_whisper_model |
search | Find text across files, folders, and URLs | query, sources, mode (auto · literal · ranked), glob, max_results |
inspect | Go deeper on a PDF | operation: render_page, extract_regions, ocr_pages, structure (JSON with geometry), compare, inspect |
A read answer looks like this:
search answers with one line per hit:
If nothing matches exactly, search falls back to BM25-ranked passages, so a question like "how does bidirectional pretraining work" still finds the right page.
CLI
The same binary is a command-line converter, like MarkItDown but much faster:
Run with no arguments from an MCP client (piped stdin), or as anymd mcp, and it serves MCP over stdio.
Formats
| Input | What you get |
|---|---|
Reading-order Markdown: headings, paragraphs, lists, tables, sub/superscripts, <!-- page N --> markers, bookmarks as an outline. Running headers and page numbers are removed. Image-only pages are OCR'd when tesseract is installed. | |
Word .docx | Headings, bold/italic, links, nested lists, tables with merged cells, footnotes, equations as LaTeX |
PowerPoint .pptx | One section per slide in deck order, titles, bullets, tables, chart data, speaker notes |
Excel .xlsx .xls .ods · CSV/TSV | One table per sheet, dates as ISO strings, capped at 2,000 rows per sheet |
| EPUB | One section per chapter in spine order, plus title and author |
| HTML and URLs | The main article only: navigation, cookie banners, and sidebars are dropped. Relative links are resolved, and code keeps its language. |
| Markdown, text, JSON | Returned unchanged, with pagination |
| Images | Dimensions and EXIF (camera, date, GPS), plus OCR text when tesseract is installed |
| Audio / video | Duration, streams, chapters, embedded and sidecar subtitles (via ffprobe/ffmpeg). Local whisper.cpp transcript with transcript: true; download_whisper_model: true fetches a verified model on first use. |
How it works
For PDFs, anymd reads glyph positions rather than text runs. Glyphs are grouped into lines by baseline, which tolerates super- and subscripts. Word spaces come from the gaps between glyphs, measured against the font size and adjusted for letter tracking. A column-aware XY cut finds gutters between running text. Tables come from drawn lines where a table has them (a missing line between two cells makes a merged cell) and from aligned columns of whitespace where it does not. Wrapped cell text stays in its cell, stacked header lines become one header, and a header over several columns is kept with each of them. Text a reader cannot see (invisible text, or text in the colour of the box behind it) is left out. Pages are processed in parallel and isolated from each other, so one malformed page never fails the whole document. The other formats are parsed natively in Rust (zip/XML, calamine, html5ever); no Python, LibreOffice, or cloud service is involved.
Security
- Local-first: documents never leave your machine unless you pass a URL, and even then only that URL is fetched.
- URL fetches block private and loopback addresses, and every redirect hop is checked again, pinned to its resolved address.
--allow-dir=<path>(repeatable) orMCP_PDF_ALLOWED_DIRSconfines the server to the directories you list.- External tools (tesseract, ffprobe, whisper.cpp) are optional. anymd runs them without a shell, with a timeout and an output cap.
See SECURITY.md to report a vulnerability.
Also from Sylphx
- repomap: A map of your codebase for AI agents: code graph, search, call paths and change impact — with an interactive graph UI. Rust MCP server + CLI. Local, no API key, MIT.
- lockdocs: Exact-version library docs from your lockfile — local, offline, no rate limits.
- readme-mark: Beautiful README images from one URL — animated banners, shields-compatible badges, typing text, 3000+ tech icons, GitHub stats cards. Free, no token, drop-in for shields / capsule-render / skill-icons / readme-typing-svg / github-readme-stats.
Star history
License
MIT © Sylphx